Command Palette
Search for a command to run...
Generating Predictive Mass Spectra for Over 100 Million Small Molecules With Cornell University's AIMe, Integrating Chemical Rules, Fragmentation Pathway Reasoning, and Neural Network Learning
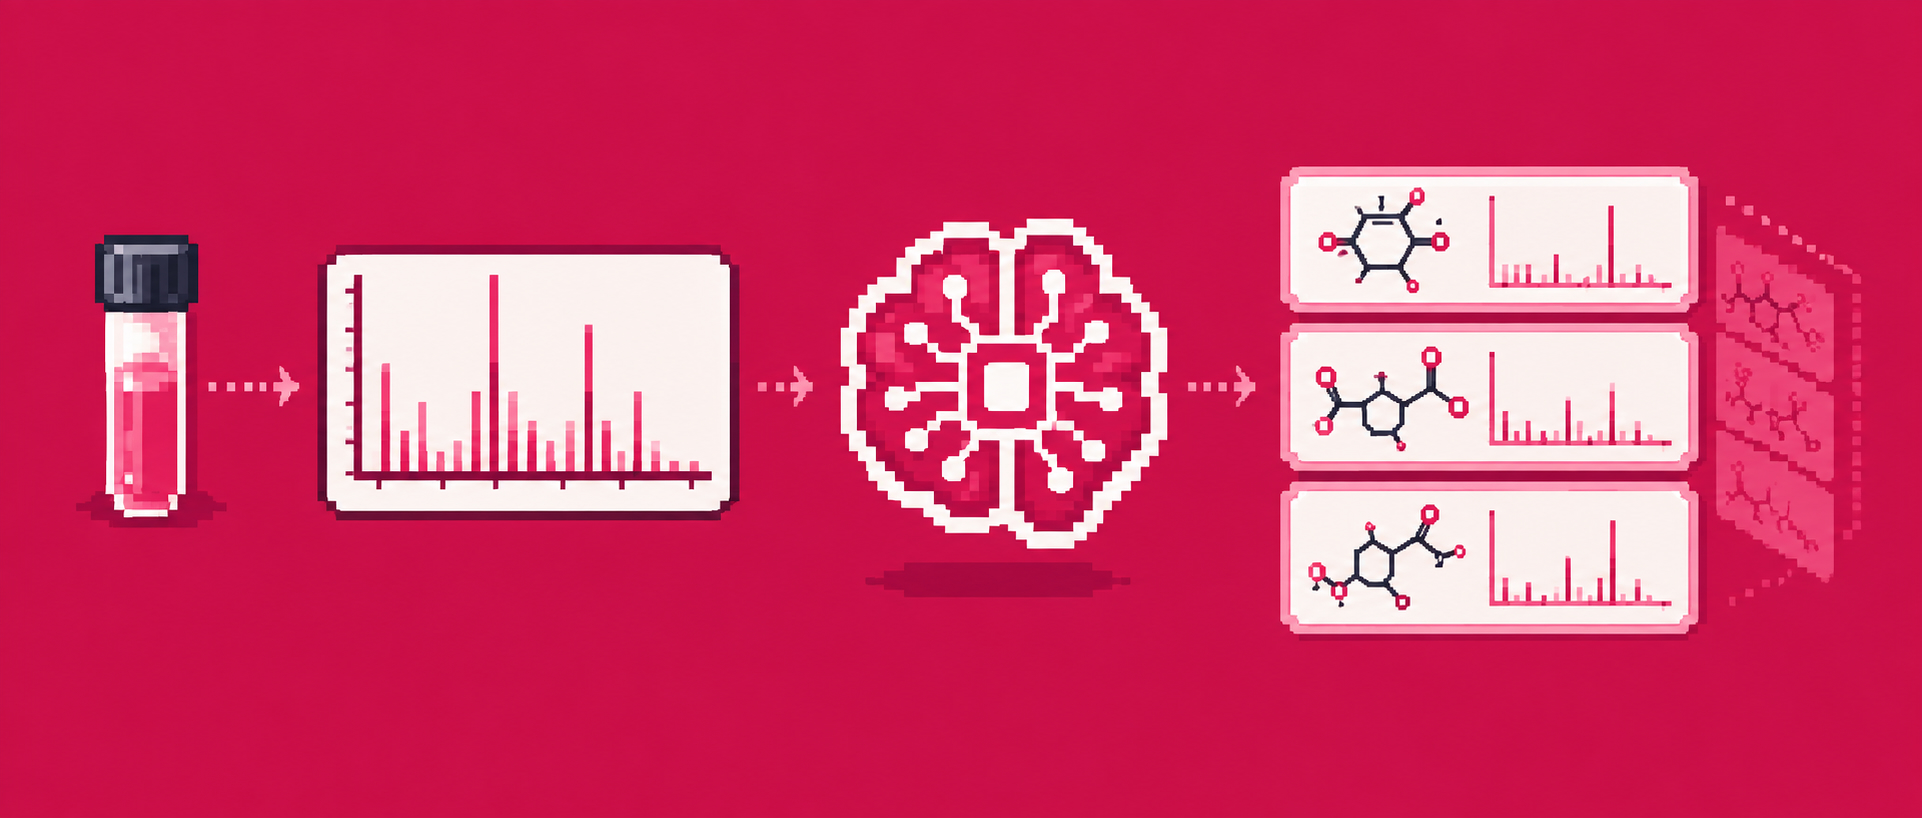
In metabolomics research, mass spectrometry can capture numerous signals of small molecules from complex biological samples; however, detecting these signals is merely the first step—the true challenge lies in identifying what specific molecules correspond to those signals. Currently, experimental reference spectral libraries available for comparison cover less than 1% of known compounds, meaning that over 80% of metabolites in typical complex biological samples remain unidentified. Meanwhile, the structural space of small molecules is far more complex than that of DNA and proteins. A single molecular formula may correspond to a vast number of different structures, making it difficult to cover this enormous chemical space solely by continuously expanding standards and reference spectral libraries.
To address this issue, a research team at Cornell University developed AI Molecule Explorer (AIMe), a multi-agent neural symbolic AI framework designed for the interpretation of small molecule mass spectra. Its core model, DeepMS²Reasoner, integrates chemical rules, fragmentation pathway reasoning, and neural network learning. Starting from molecular structures, it simulates fragmentation processes such as bond cleavage and hydrogen transfer, predicting corresponding MS² spectra. Consequently, AIMe moves beyond traditional direct matching between "experimental mass spectrum–reference library," placing unknown mass spectra within a broader molecular structural space to identify relevant candidates.
To extend this capability into the space of known small molecules, the research team further constructed MS²KOSMOS, generating over 800 million predicted MS² spectra for more than 100 million small molecules in PubChem, thereby expanding the searchable mass spectral space by approximately three orders of magnitude compared to existing experimental libraries. For an unknown mass spectrum, AIMe not only returns candidate molecules but also provides their associated fragmentation pathways, linking specific mass spectral peaks to possible fragment formulas and structures. The research team subsequently validated its ability to interpret unknown small molecules and perform database-level annotation using mouse gut microbiota-related metabolites and large-scale mass spectrometry data from GNPS.
The related research findings have been published on the preprint server bioRxiv under the title "Charting the small-molecule universe from mass spectra with neuro-symbolic AI."
View Paper:
https://www.biorxiv.org/content/10.64898/2026.08.05.743095v1
From Experimental Mass Spectra to Billion-Scale Small Molecule Space
The data involved in AIMe primarily serves three tasks:** training the mass spectral prediction model, constructing a retrievable small molecule space, and evaluating interpretation capabilities in real-world samples.**
The training data for DeepMS²Reasoner comes from the NIST 2020 tandem mass spectrometry database. The research team retained MS² spectra for protonated ions [M+H]⁺ and deprotonated ions [M−H]⁻, excluded metal-containing compounds and samples with incomplete structural information, and standardized processing of mass spectral peaks and molecular structures. Data were divided into an 80% training set, 10% validation set, and 10% test set based on complete InChIKeys. To mitigate the impact of structural redundancy, test molecules with a Morgan fingerprint Tanimoto similarity of 1.0 relative to training molecules were excluded during final evaluation.
The external generalization capability of the model was tested using two independent datasets, CASMI 2022 and MassSpecGym, neither of which participated in the training process. Structural retrieval experiments added another layer of difficulty: for each experimental mass spectrum, up to 49 interfering items consisting of PubChem molecules with similar masses and structures, besides the ground truth structure, were included. Regarding CASMI, the researchers designed even stricter all-isomer tests, incorporating all PubChem isomers sharing the same molecular formula into the candidates, involving nearly 2.5 million candidate mass spectra in total.
After completing model training, the scope expanded to include known small molecules in PubChem. For over 105 million organic compounds with m/z < 1000, AIMe predicted MS² spectra across positive and negative ion modes and four collision energies, generating over 800 million predicted mass spectra. These were organized into MS²KOSMOS, providing a foundation for subsequent searches of unknown mass spectra.
Real-world applications mainly involve two sets of data. One dataset consists of fecal metabolomes from germ-free (GF) mice and specific pathogen-free (SPF) mice with intact intestinal microbiotas. From this group, 111 microbial-community-dependent signals exhibiting high abundance yet unable to be identified through current standards and spectral libraries were selected. Another dataset came from the public GNPS mass spectrometry database. After filtering conditions such as charge state and molecular weight, a total of 7,144,480 consensus MS² spectra entered large-scale search operations.
Teaching Models How Molecules Fragment
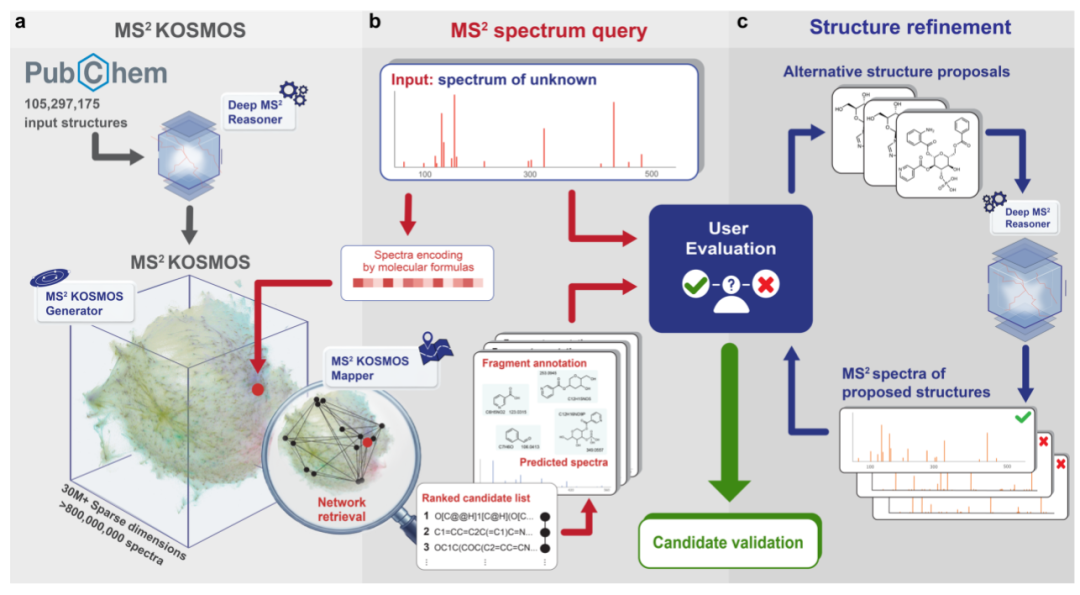
AIMe comprises three interconnected modules: DeepMS²Reasoner predicts MS² spectra and fragmentation paths from molecular structures; MS²KOSMOSGenerator calls upon this model to predict outcomes for massive chemical structures and constructs the searchable MS²KOSMOS; finally, MS²KOSMOSMapper handles unknown experimental mass spectra, searching within MS²KOSMOS for potentially related molecules and structural neighborhoods. With large-scale predictions completed beforehand, actual queries require only finer computational analysis of filtered candidate structures.
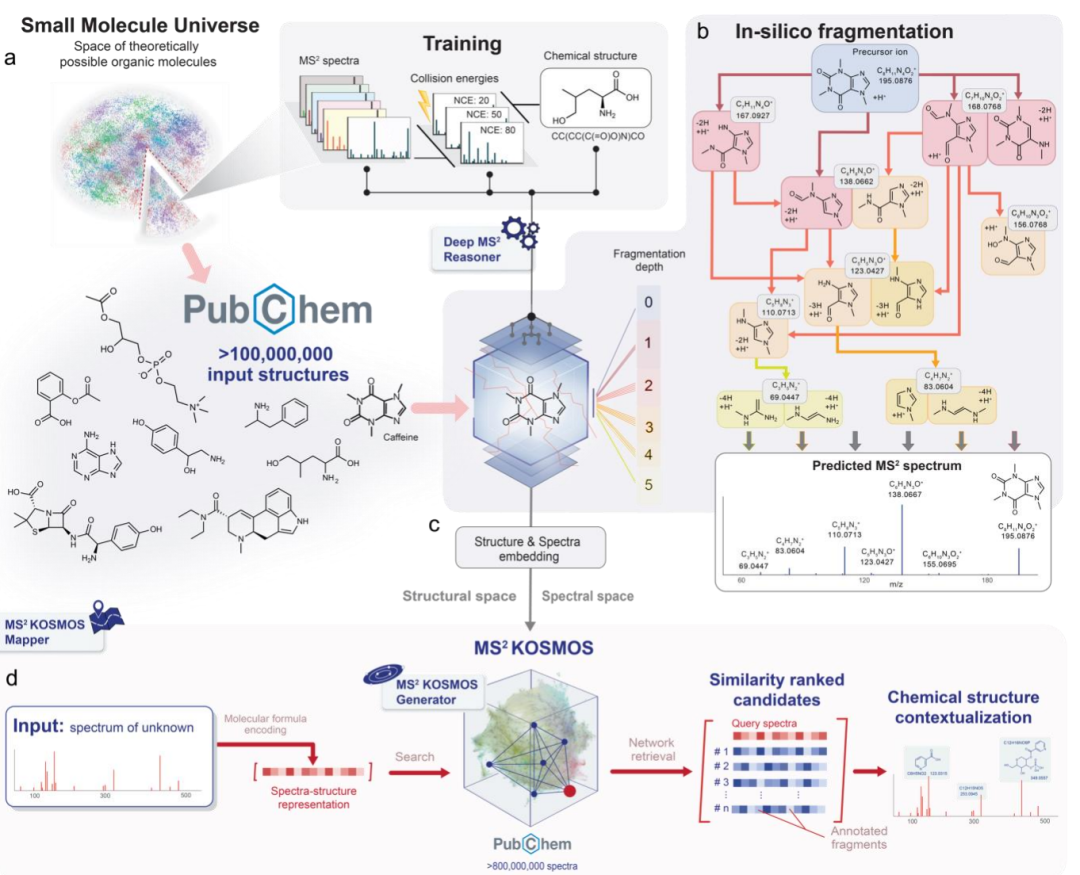
Among these components, the DeepMS² Reasoner determines the mass spectrometry prediction capability of the entire system. Rather than directly learning “which peaks correspond to which molecule and their intensities,” it starts from the precursor ion and step-by-step simulates the fragmentation process while dynamically constructing a directed acyclic graph (DAG). In this DAG, nodes represent different fragment ions, and edges correspond to specific fragmentation events. The model considers three types of mechanisms—linear bond cleavage, ring bond cleavage, and neutral loss—while also tracking charge changes and hydrogen transfers. Since there is no predefined limit on fragmentation depth, the framework can accurately depict complex fragments that require multiple steps involving bond breaking, ring opening, or rearrangement.
The selection of fragmentation pathways is determined by an neural network component called ALEA (Action Likelihood Estimator Advisor). Leveraging the Graphormer architecture, ALEA assigns probabilities to various fragmentation actions as well as a “stop fragmentation” action based on current atomic configurations, chemical bonds, ring structures, protonation states, along with experimental conditions such as collision energy, instrument type, and adduct ions. These probability distributions are then propagated through the fragmentation paths in the DeepMS² Reasoner; finally, the accumulated stop-probability at each fragment yields its corresponding peak intensity in the predicted spectrum.
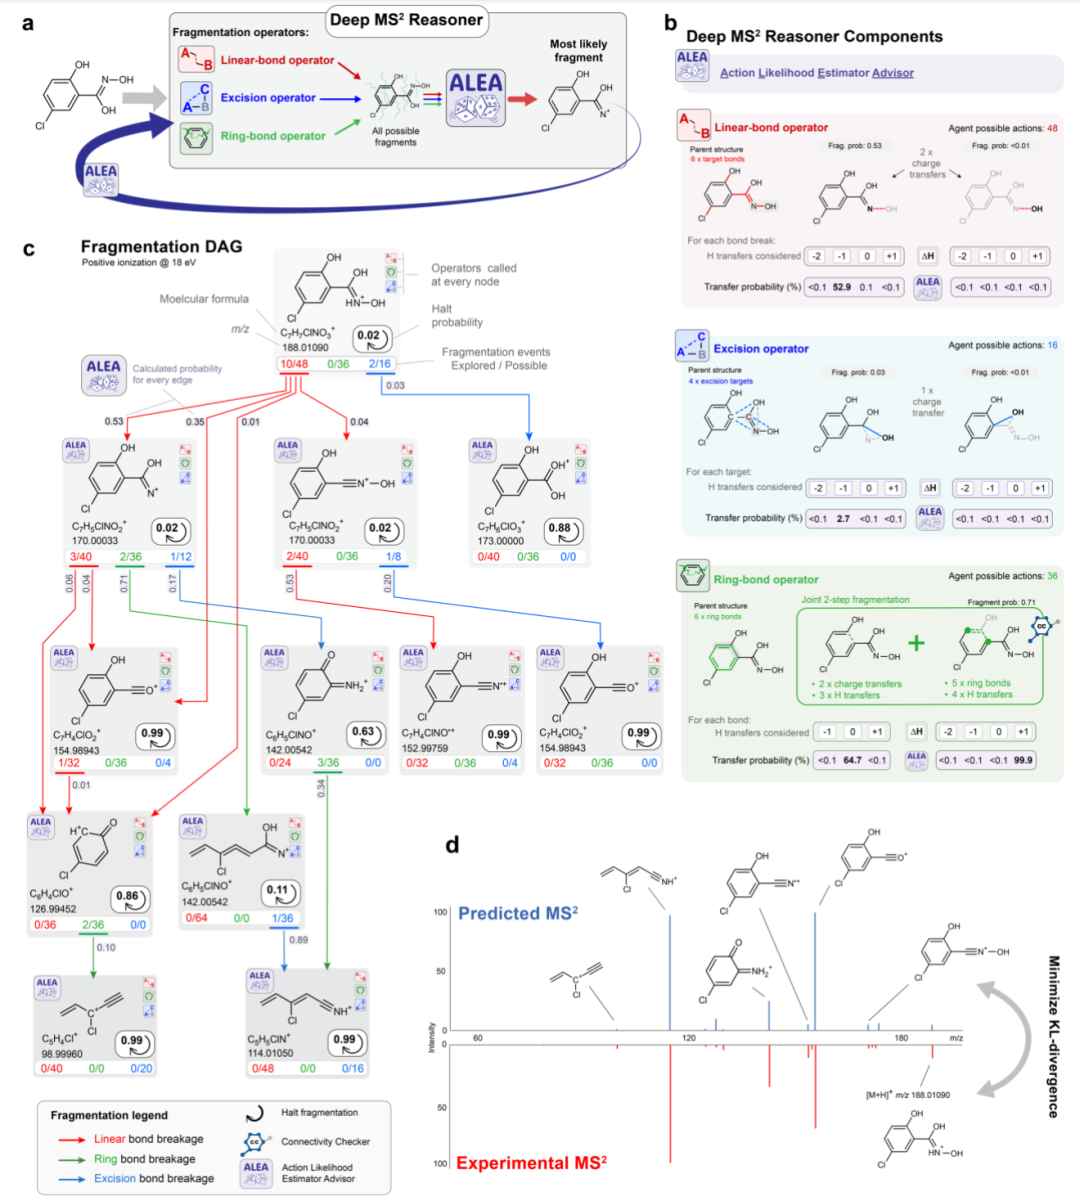
The neural network is responsible for determining which paths are more likely to occur, while chemical rules constrain which paths can actually take place. After each fragmentation step, the system checks molecular connectivity, hydrogen balance, and other chemical constraints; unreasonable fragmentations are excluded from subsequent calculations. Fragments with identical structures and chemical states are merged to reduce redundant searches. For branches with very low probabilities, the model does not continue expanding them, thereby avoiding an exhaustive enumeration of all possible fragmentation pathways that grow rapidly in number as molecular complexity increases.
During training, the primary component requiring parameter learning is ALEA; all other fragmentation operations and assessments of chemical feasibility are handled by deterministic rules. The model uses Kullback-Leibler (KL) divergence to measure the difference between predicted and experimental mass spectra, incorporating regularization constraints so that when multiple mechanisms could explain the same spectral peak, simpler linear bond cleavages are appropriately prioritized. Curriculum learning is also employed: starting with smaller molecules having fewer and simpler fragmentation paths, then gradually introducing larger and more complex compounds, enabling the model to first master transferable local fragmentation patterns.
DeepMS²Reasoner addresses “predicting mass spectra from structures,” whereas MS²KOSMOS further tackles “how to search across hundreds of millions of molecules.” The MS²KOSMOS Generator represents each predicted spectrum as a sparse vector composed of fragment formulas and builds an inverted index. When faced with an unknown mass spectrum, the system avoids comparing against every one of the hundred million candidate molecules individually; instead, it first identifies candidates sharing fragment formula matches with the query spectrum. It then re-predicts the mass spectra for these candidates using actual collision energy and other experimental conditions via MS²KOSMOS Mapper, ranks them accordingly, and returns the corresponding fragmentation directed acyclic graphs (DAGs).
From Predicted Mass Spectra to Elucidating Unknown Molecules
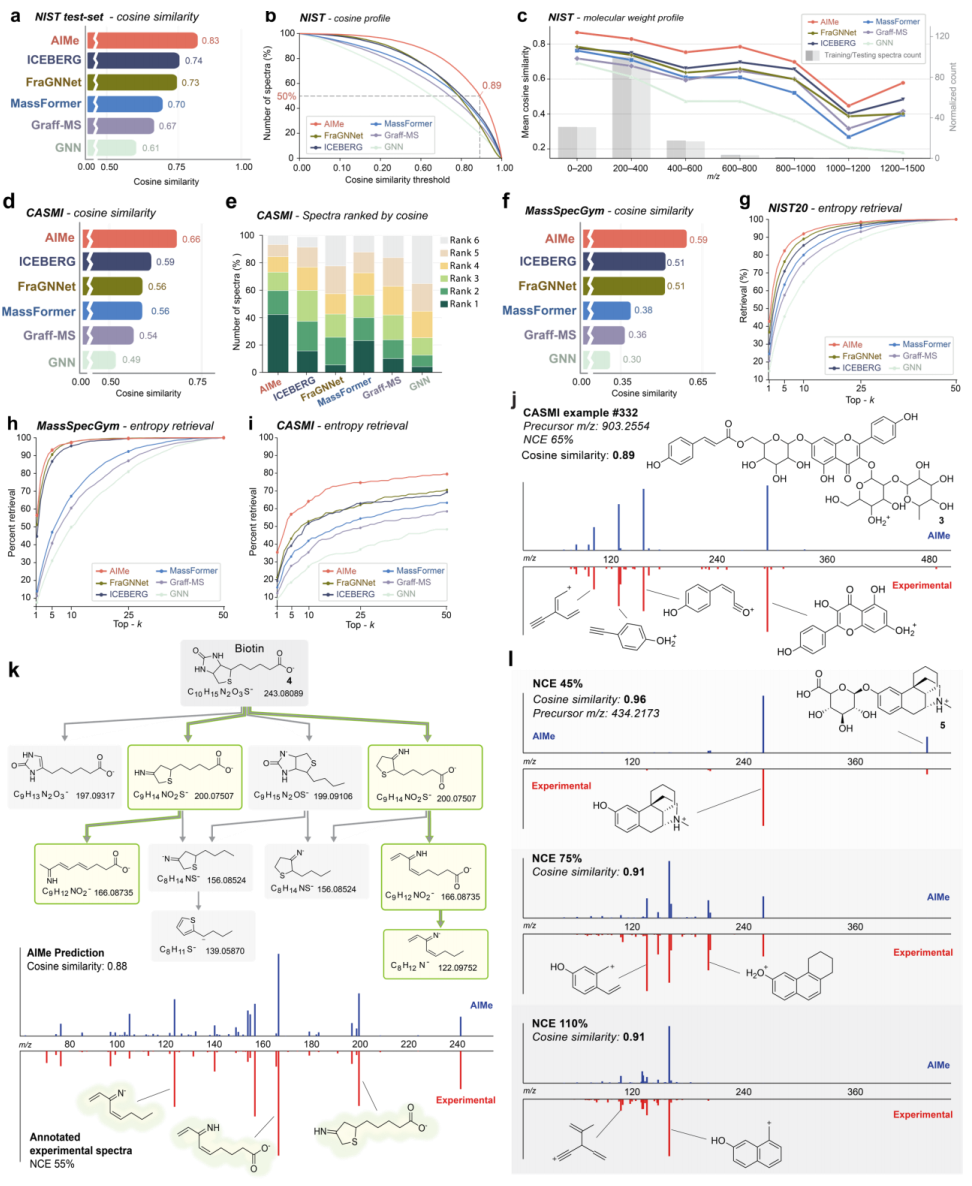
The study first evaluated DeepMS²Reasoner on fundamental mass spectrometry prediction tasks. On the independent NIST 2020 test set, the average cosine similarity between predicted and experimental spectra reached 0.83, with a median of 0.89; other comparative models showed averages ranging from 0.61 to 0.75. In fully independent datasets such as CASMI 2022 and MassSpecGym, DeepMS²Reasoner achieved mean cosine similarities of 0.67 and 0.59, respectively, both representing the highest scores among all participating models. Taking CASMI as an example, in over 40% of samples, DeepMS²Reasoner produced the most experimentally accurate predictions compared to all baseline models.
Compared to merely predicting mass spectra, a more challenging task is reverse-engineering correct molecular structures based on experimental spectra. The research placed true structures alongside numerous candidates with similar masses or structural features for retrieval. In the full-isomer tests of CASMI, DeepMS²Reasoner attained top-1, top-10, and top-50 accuracies of 35.6%, 64.4%, and 79.8%, respectively—with its top-1 and top-10 performances exceeding those of second-place FraGNNet by more than ten percentage points each.
The model's capability to handle multi-step fragmentation was also validated using specific molecules. For biotin, the cosine similarity between DeepMS²Reasoner’s predicted spectrum and the experimental one reached 0.88. Some major fragments cannot form through single bond cleavage but require sequential processes including group elimination, ring-opening, and further fragmentation. The model successfully identified these multi-step pathways corresponding to observed fragments while accounting for varying degrees of dissociation under different collision energies.
Mass Spectrometry Prediction Performance of DeepMS²Reasoner
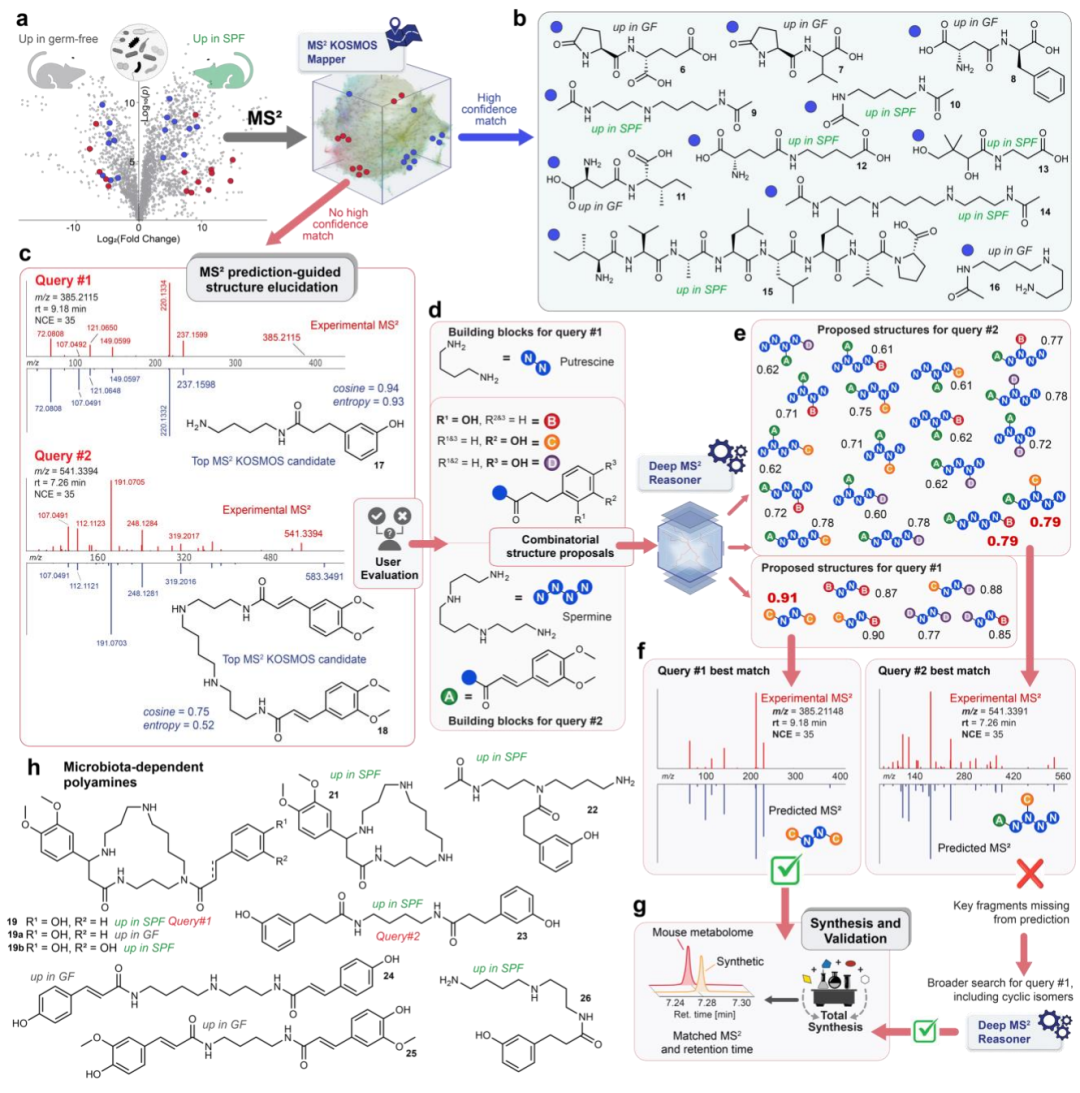
Following this, the study applied AIMe to the structural elucidation of truly unknown metabolites. Among 111 unidentified microbiome-dependent signals in the mouse metabolome, approximately one-third could be matched with known compounds exhibiting high similarity via MS²KOSMOS, while the remaining ones were more likely to correspond to yet-to-be-described structures.
Researchers further selected two unknown compounds for structural elucidation. Based on the fragment structures provided by AIMe, they combined various candidate molecules and predicted their MS² spectra for comparison with experimental results. For one of the unknowns, the best initial candidate achieved a cosine similarity of 0.79 but still lacked several key fragments observed experimentally. Consequently, the research team continued to consider cyclized structures and identified a rare macrolide polyamine derivative. Both candidate structures were ultimately validated through chemical synthesis and comparisons of retention times and MS² spectra; this included a polyamine structure previously unreported in mice or humans. Further searches revealed that multiple related metabolites also exist in human samples.
Finally, the study extended AIMe to over 7.14 million consensus mass spectra in the GNPS database. Using a cosine similarity threshold of 0.7, approximately 2.69 million spectra received candidate annotations, representing about one-third of the total queries; raising the threshold to 0.8 yielded an additional ~1.27 million high-similarity annotations corresponding to more than 26 million originally unannotated raw mass spectra in GNPS. Thus, the application scope of AIMe expanded further from predicting individual molecular masses to annotating unknowns at a database scale.
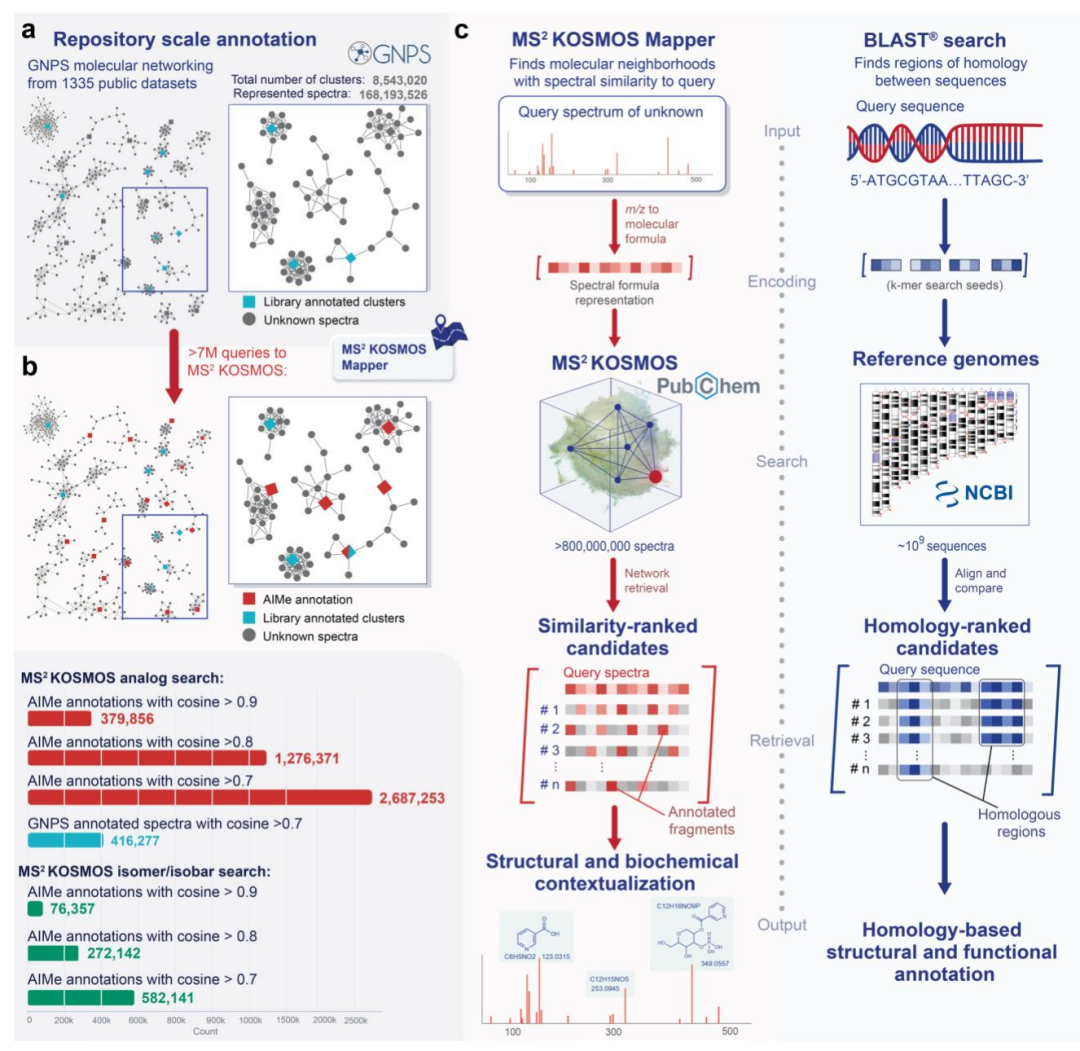 *LARGE-SCALE ANNOTATION RESULTS OF AIME ON THE GNPS DATABASE*
These findings do not imply that small-molecule structural identification has been fully automated. As molecular weight increases, possible fragmentation pathways multiply significantly, while coverage of large molecules in training data remains relatively insufficient, causing DeepMS²Reasoner’s predictive performance to decline. More importantly, MS² alone is typically insufficient for definitive structural confirmation. According to metabolomics standards, when independent evidence such as retention time, NMR, or authentic standards is lacking, results provided by AIMe primarily constitute Level 3 annotation; its role lies closer to narrowing down candidates, proposing structural hypotheses, explaining fragmentation rationale, whereas final confirmation requires experimental validation.
Conclusion
The significance of AIMe extends beyond merely improving spectral prediction accuracy—it aims to transform how we approach resolving unknown small molecules. Previously, researchers faced limited options when confronted with an unknown spectrum, often relying solely on direct matches within finite experimental libraries; AIMe first converts known small molecule spaces into searchable predicted spectral domains using models before gradually reducing candidate ranges via fragment structures and fragmentation paths. While it currently cannot replace standard references, NMR, or other forms of experimental verification, it enables tracking signals once deemed difficult due to "lack of reference spectra."
For metabolomics, perhaps what matters most isn’t simply adding entries to existing library catalogs—instead enabling new possibilities where unresolved questions become starting points rather than dead ends! Unknown spectra now have opportunities instead being restricted just matching/unmatching outcomes becoming tools suggesting/testing hypothetical frameworks leading towards discoveries ahead...