Command Palette
Search for a command to run...
تصميم الآليات لنماذج اللغة الكبيرة
تصميم الآليات لنماذج اللغة الكبيرة
Paul Dütting Vahab Mirrokni Renato Paes Leme Haifeng Xu Song Zuo
الملخص
نبحث في آليات المزاد للمحتوى المُولَّد بالذكاء الاصطناعي، مع التركيز على تطبيقات مثل إنشاء الإبداعات الإعلانية. في نموذجنا، تُشفَّر تفضيلات الوكلاء تجاه المحتوى المُولَّد احتماليًّا بوصفها نماذج لغة كبيرة (LLMs). نقترح صيغة مزاد تعمل على مستوى الرمز اللغوي (token)، وتُتيح لوكلاء نماذج اللغة الكبيرة التأثير في إنشاء المحتوى من خلال عروض أسعار أحادية البُعد. نصوغ خاصيتين مرغوبتين للحوافز ونُثبت تكافؤهما مع شرط الرتابة على تجميع المخرجات. يُتيح هذا التكافؤ تصميم قاعدة السعر الثاني، حتى في غياب دوال تقييم صريحة للوكلاء. ندعم تصميمنا بعروض توضيحية على نموذج لغة كبير مُتاح للعموم.
One-sentence Summary
Google Research and University of Pennsylvania propose a token-by-token auction mechanism for AI-generated content such as ad creatives, where agent preferences are encoded as LLMs, prove that two incentive properties are equivalent to a monotonicity condition on output aggregation, and enable a second-price rule design without explicit agent valuation functions, supported by demonstrations on a publicly available LLM.
Key Contributions
- A token-by-token auction framework is introduced for aggregating outputs from multiple LLM-based agents, allowing them to shape stochastically generated content through single-dimensional bids in settings such as ad creative generation.
- A robust mechanism-design characterization shows that two incentive properties are equivalent to monotone output aggregation, enabling second-price payment rules without explicit agent valuation functions, with aggregation functions inspired by KL-divergence and PPO-style training losses.
- Demonstrations on a publicly available state-of-the-art LLM using prompt tuning show that the proposed aggregation mechanisms can produce promising content-generation outcomes in practice.
Introduction
In today’s web ecosystem, auctions decide which ads and commercial content users see, and as AI generated content becomes more common, advertisers may want to bid for influence over LLM generated outputs rather than fixed ad slots. This matters because LLMs can create dynamic, context aware commercial content for chatbots, webpages, videos, and games, but auction theory has not yet adapted to the way these models represent preferences.
Prior work does not directly address this setting, and simple auctions where the highest bidder chooses the content waste the flexibility of LLMs to combine advertisers’ concepts into joint outputs. LLMs also complicate mechanism design because they encode preferences through token level probability distributions, rely on random sampling, require technical compatibility with existing model APIs, and are expensive to query.
The authors introduce a token auction model that aggregates multiple advertiser LLMs one token at a time, using bids to weight each model’s influence over the output distribution. They develop robust incentive properties, including payment monotonicity and consistent aggregation, and show how second price style payments can be adapted to this setting. They also design aggregation rules inspired by LLM training losses, such as KL divergence, and demonstrate that these mechanisms can produce interpretable joint ads that smoothly favor different advertisers.
Method
Token Auction Mechanism for LLM Output Aggregation
The proposed method models each LLM as an algorithmic agent that expresses preferences through its next-token distribution. Rather than designing an auction over complete generated texts, the authors place the mechanism at the token-generation layer, which keeps the system aligned with modern autoregressive LLM inference pipelines. Each agent receives a prompt, produces a probability distribution over the next token, and participates in a token auction that combines these distributions into a single aggregated distribution used to generate the next token.
The overall mechanism is denoted as
M=⟨q,z⟩,where q is a distribution aggregation function and z is a payment rule. The aggregation function determines which token distribution is used at each generation step, while the payment rule determines what each agent pays for influencing the sampled token.
Consider n LLM agents with token-generation functions
fi:T∗→Δ(T),where T is the vocabulary and Δ(T) is the set of probability distributions over tokens. At step k, starting from the current prompt sk−1, agent i produces the preferred token distribution
pi=fi(sk−1).The agents submit bids
b=(b1,…,bn)∈Q+n,where each bi is a nonnegative scalar representing the agent’s desired influence on aggregation. The aggregation function maps bids and token distributions to a new distribution:
q:Q+n×Δ(T)n→Δ(T).For fixed bids, the aggregated distribution at step k is
qk=q((b1,…,bn),(f1(sk−1),…,fn(sk−1))).The next token is sampled as
τk∼qk,and the generated text is extended by
sk=sk−1⊕τk.Because each LLM already produces fi(sk−1), the auction operates directly on the token-level outputs already required by inference, avoiding additional LLM calls merely to compute the aggregated distribution.
Robust Preference Modeling
A central challenge is defining when one aggregated distribution is better than another for an LLM agent. The authors argue that it is difficult to impose a complete ordering over all possible output distributions. For example, if an LLM’s preferred distribution over two tokens is p=(0.6,0.4), then it is not always clear whether a generated distribution (0.5,0.5) or (0.8,0.2) is more preferable, because one may reduce deviation on some tokens while increasing probability on the agent’s favored token.
To address this, the method uses a partial order based on robust preferences. For an agent i with preferred distribution pi, an aggregated distribution q is weakly robustly preferred to q′, written
q⪰iq′,if for every token t∈T,
∣q(t)−pi(t)∣≤∣q′(t)−pi(t)∣and
(q(t)−pi(t))(q′(t)−pi(t))≥0.The first condition requires that q deviates from pi no more than q′ does for each token. The second condition requires that the deviations have the same sign, meaning the two distributions move in the same direction relative to the preferred distribution for every token. Thus, q is preferred when it is closer to the agent’s preferred distribution in a coordinate-wise, same-direction sense. This avoids assuming a full utility function over all possible output distributions while retaining a meaningful partial comparison.
Aggregation and Payment Modules
The auction separates output aggregation from payments. The aggregation module produces the next-token distribution, while the payment module assigns a per-token charge to each agent.
For each agent i, the system defines a per-token pricing function
ζi:Q+n×Δ(T)n×T→R.If bids are b, token distributions are p=(p1,…,pn), and token t is sampled from q(b,p), then agent i pays
ζi(b,p,t).The expected payment for agent i is
zi(b,p)=Et∼q(b,p)[ζi(b,p,t)].This token-level decomposition is important because it mirrors the stage-independent structure of autoregressive generation. The payment does not require comparing complete generated sequences; instead, it operates on the sampled token at each step.
Incentive-Oriented Aggregation Design
The authors focus on mechanisms with simple and robust incentive properties. They introduce payment monotonicity, which requires that an agent’s payment increases only when its aggregated outcome becomes weakly more preferred. Formally, for agent i,
zi(bi,b−i,p)≥zi(bi′,b−i,p)if and only if
q(bi,b−i,p)⪰iq(bi′,b−i,p).This condition prevents a common manipulation incentive: an agent should not be able to lower its bid, or otherwise strategically misreport, to obtain a better output distribution at a lower payment.
They also define consistency of aggregation. If two bids of agent i induce a strict preference ordering for some opponents’ bids, then that ordering should not reverse for other opponents’ bids. Formally, if for some b−i,
q(bi,b−i,p)≻iq(bi′,b−i,p),then for all alternative opposing bids b−i′,
q(bi,b−i′,p)⪰iq(bi′,b−i′,p).This requirement stabilizes an agent’s view of its own bids, so the agent does not face ambiguity about whether its bid is better simply because of the bids chosen by others.
From these conditions, the method derives a design principle focused on monotone aggregation functions. A distribution aggregation function is monotone if a higher bid from agent i always leads to a weakly more preferred aggregated distribution for i:
q(bi,b−i,p)⪰iq(bi′,b−i,p)wheneverbi≥bi′.The authors show that, under payment monotonicity, any mechanism with a consistent aggregation function can be strategically converted into one with a monotone aggregation function. This gives a design reduction: one can focus on monotone aggregation rules without losing the main incentive structure.
Two simple aggregation rules illustrate the distinction. The linear aggregation function is
qKL(b,p)=∑ibi∑ibipi.This rule is monotone under robust preferences: increasing bi increases the weight of pi in the mixture. In contrast, a log-linear rule such as
lnqˉKL(t)=C+∑ibi1i∑bilnpi(t),where C is a normalization constant, is not monotone under robust preferences in general. Although it corresponds naturally to certain RLHF-style aggregation, monotonicity can fail for particular pairs of agents and preferred distributions.
Second-Price Payments via Stable Sampling
Once a monotone aggregation rule is chosen, the method constructs a token-level second-price payment rule inspired by the Vickrey auction idea of paying the minimum bid needed to improve the outcome.
To define the payment, the authors represent the random sampling induced by the aggregation function as an implementation. Fix all bids and distributions except agent i’s bid. Let
qt(bi)=qt(bi,b−i,p)be the probability of token t. An implementation is a deterministic mapping
σ(bi,r)∈T,where r is an exogenous random variable. It is valid if for each token t,
r∼RPr[σ(bi,r)=t]=qt(bi).Thus, randomness enters through r, and for a fixed random draw r, the sampled token is a deterministic function of the bid.
The key idea is to partition the token set into undersampled and oversampled tokens relative to agent i’s preferred distribution. Using qt(0) as the baseline probability when the agent’s bid is zero, define
T+={t∈T:qt(0)≤pi(t)}and
T−={t∈T:qt(0)>pi(t)}.Tokens in T+ are tokens that agent i would like to increase, while tokens in T− are tokens that are overly frequent relative to its preference. Monotonicity of the aggregation function corresponds to probabilities on T+ weakly increasing with bi and probabilities on T− weakly decreasing with bi.
A stable sampling implementation has a particularly simple counterfactual structure. For each random draw r, there exist one undersampled token ur∈T+, one oversampled token or∈T−, and a critical bid threshold θr such that
σ(bi,r)=orifbi<θr,and
σ(bi,r)=urifbi≥θr.Intuitively, as the agent raises its bid, the sampled token can transition from an oversampled token to an undersampled token. The payment rule follows directly from this transition. If the sampled token is oversampled, the agent pays zero because the same token would have appeared under the zero-bid baseline for that random draw. If the sampled token is undersampled, meaning the agent’s bid crossed the threshold needed to improve the outcome, the agent pays the critical bid
θr.This gives a token-level second-price rule: agents pay the minimal amount required to replace a less preferred token with a more preferred one under the realized random draw.
The expected payment can be expressed in terms of the reduction in total variation distance toward the agent’s preferred distribution. Specifically,
zi(bi)=21∫0bi[∥q(bi)−pi∥1−∥q(b′)−pi∥1]db′.This formula shows that payment is proportional to how much the agent’s bid moves the aggregated distribution closer to its preferred distribution. It also provides a Myerson-style characterization: the allocation probability in classical auctions is replaced here by the change in total variation distance.
This stable sampling design makes payments independent of the particular sampling algorithm, as long as the algorithm is stable. It also simplifies counterfactual reasoning for agents. For any fixed random draw r, an agent can compare only two possible outcomes: the oversampled token below the threshold and the undersampled token at or above the threshold.
Aggregation Rules Inspired by LLM Training
The authors then propose aggregation functions whose structure mirrors standard LLM training objectives. Their guiding principle is to define an aggregated loss over agents:
Loss(p,b,q)=i∑biρ(pi,q),where ρ(pi,q) measures how far the aggregated distribution q is from agent i’s preferred distribution pi. The function ρ is chosen to reflect losses used in LLM training.
KL-Inspired Aggregation
For KL-inspired aggregation, the authors consider agents whose models were trained by minimizing KL divergence to labeled data. They define the aggregated loss as
LOSSKL(p,b,q)=i∑bit∈T∑pi(t)lnq(t)pi(t).This is the bid-weighted sum of
DKL(pi∥q).Minimizing this loss yields the linear aggregation rule
qKL(t)=∑ibi∑ibipi(t).This aggregation is monotone under robust preferences. It also has a practical sampling interpretation: instead of explicitly evaluating the full mixture, one can choose an agent i with probability proportional to bi, then sample a token from pi. This reduces the computation needed for token generation, although payment calculations may still require access to all agents’ distributions.
RLHF-Inspired Aggregation
For RLHF-inspired aggregation, the authors consider a setting where agents share the same supervised fine-tuned base model but differ in reward functions. Weighting reward functions by bids leads to an aggregated loss with the opposite KL direction:
LossKL(p,b,q)=i∑bit∈T∑q(t)lnpi(t)q(t).This corresponds to bid-weighted
DKL(q∥pi).The minimizer is the log-linear aggregation rule
lnqˉKL(t)=C+∑ibi1i∑bilnpi(t),where C normalizes the probabilities over T. This rule is natural for aggregating models that have been tuned with different reward signals, but it is not generally monotone under robust preferences. Thus, the method exposes a design tradeoff: KL-inspired linear aggregation supports monotonicity and simpler second-price incentives, while RLHF-inspired log-linear aggregation better reflects certain reward-based tuning processes but may require weaker or adapted incentive guarantees.
Experiment
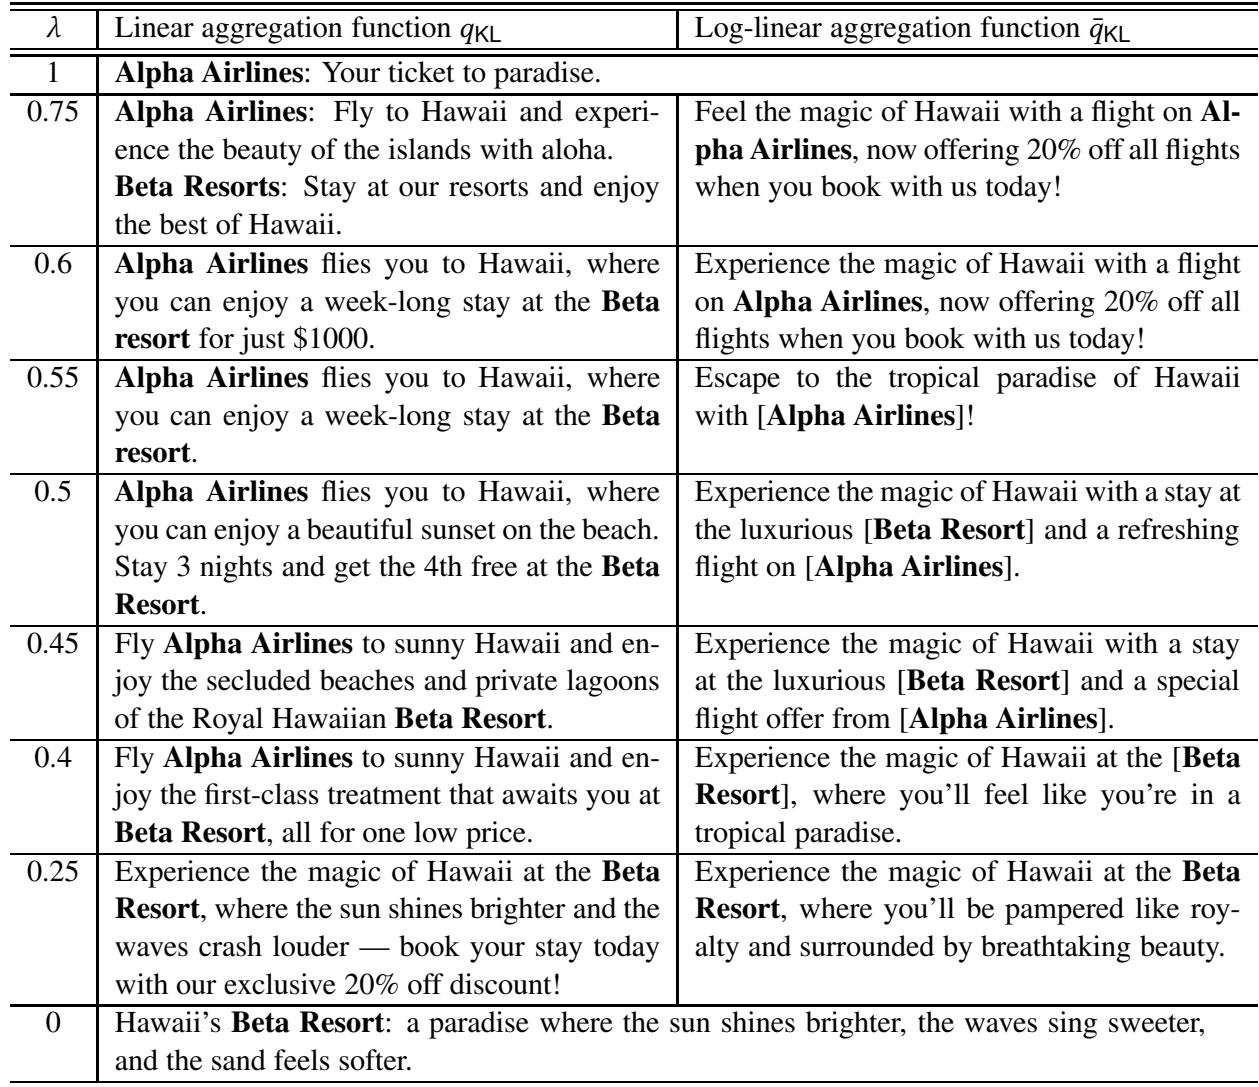
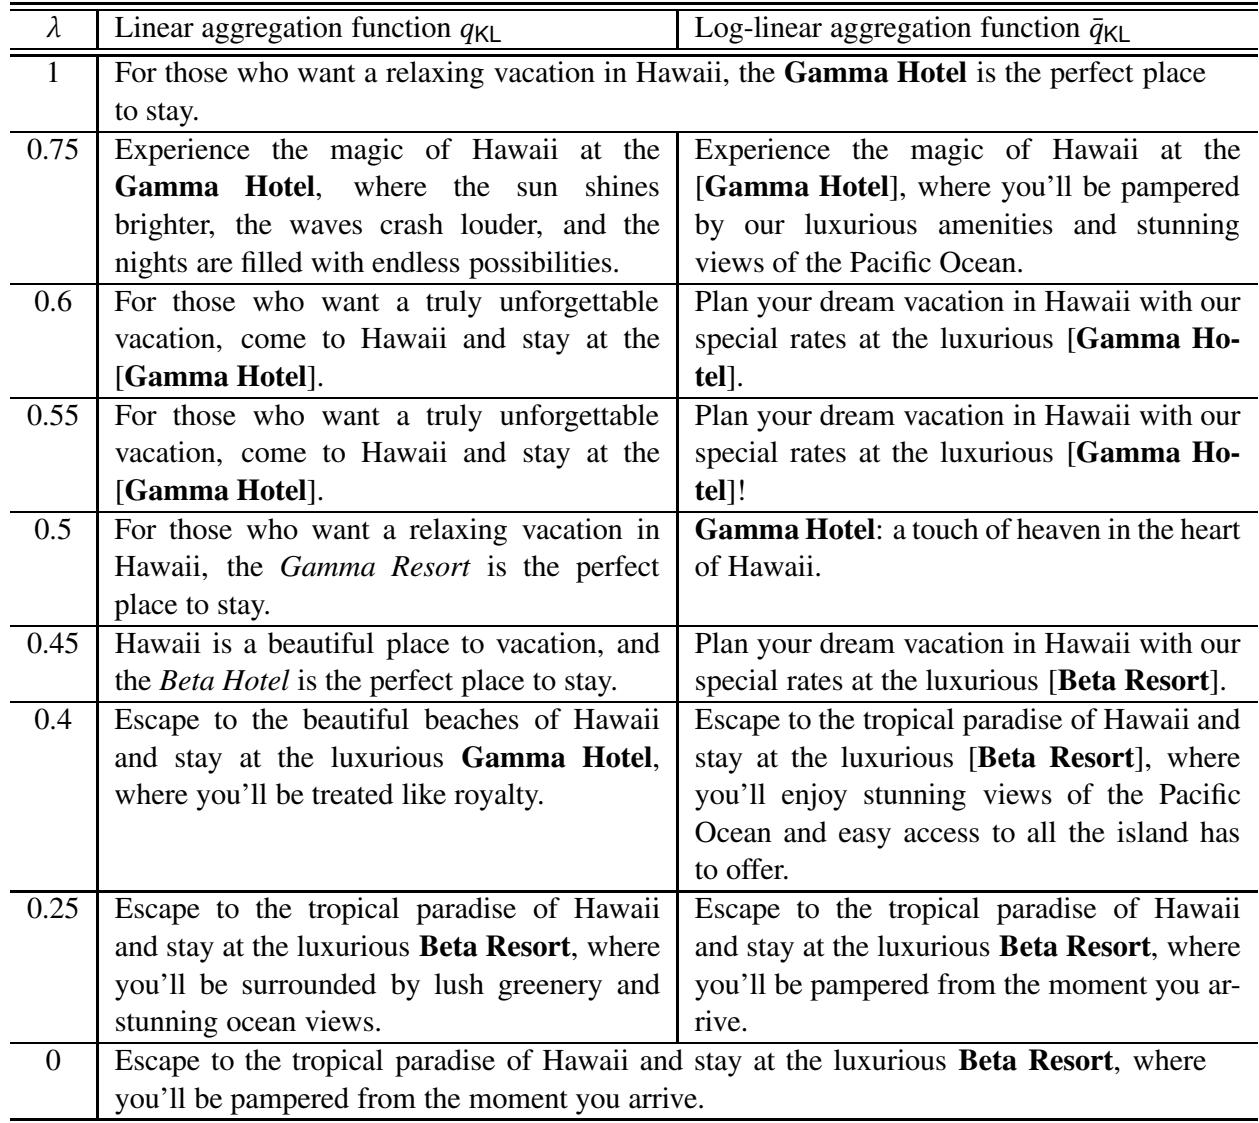
The authors implement the proposed aggregation functions with a modified LLM that exposes token distributions and simulates different agents through prompt tuning. Experiments on co-marketing and competing fictitious brands show that the generated advertisements qualitatively follow the intended preference weighting, shifting toward one brand, both brands, or the other brand in cooperative cases and toward a single brand in competitive cases. Occasional confusion among brand names near intermediate preference levels suggests that task-specific fine-tuning could improve reliability.
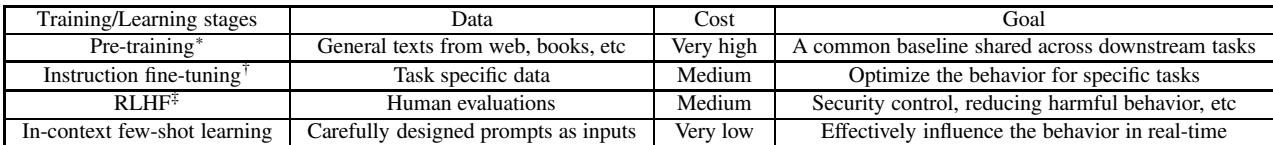
These training stages range from broad model development to lighter ways of adapting model behavior. Pre-training on general text is costly and creates a shared baseline for many tasks, while instruction fine-tuning and RLHF use more targeted data or human feedback to improve specific behavior and reduce harmful outputs. Prompt-based learning is the least expensive because it changes model behavior in real time without additional training. Pre-training uses broad web, books, and similar text, has very high cost, and establishes a common baseline. Instruction fine-tuning and RLHF have medium cost and aim to optimize specific task behavior or improve safety. In-context few-shot learning uses carefully designed prompts, has very low cost, and can influence behavior in real time.
In the co-marketing demonstration, decreasing the aggregation weight gradually shifts generated advertisements from emphasizing Alpha Airlines to mentioning both Alpha Airlines and Beta Resort and finally emphasizing Beta Resort. This trend appears for both linear and log-linear aggregation, though the log-linear rule changes the emphasis over a narrower intermediate range and tends to retain the initially favored brand longer. The outputs suggest the aggregation rule can guide brand prominence, with potential improvement from task-specific fine-tuning. Generations move from one brand to both brands to the other brand as the aggregation weight shifts toward the second brand. Log-linear aggregation preserves the Alpha Airlines emphasis longer than linear aggregation before producing combined ads.
When the weighting moves from favoring the first brand to favoring the second brand, the generated text shifts from mentioning Gamma Hotel alone to mentioning Beta Resort alone for both aggregation functions. The competing setup produces single-brand outputs rather than jointly naming both brands. The linear method sometimes blends the brand names incorrectly near the transition, suggesting task-specific training could help enforce exact terms. Both aggregation methods show a shift from Gamma Hotel emphasis to Beta Resort emphasis. The competing setup avoids combining both brands in the same creative. Linear aggregation can confuse brand suffixes near the switching region.
Experiments compare broad training and adaptation strategies for controlling generated advertisements, then demonstrate how aggregation weight and rule influence brand prominence. Co-marketing outputs gradually shift from first brand through combined mention to second brand, with log-linear preserving first brand longer than linear. Competing outputs mostly isolate brands as weighting changes, indicating the aggregation mechanism guides emphasis, though fine-tuning may improve term accuracy and blending.