Command Palette
Search for a command to run...
هل يحفّز التعلم المعزز حقًا قدرات الاستدلال في النماذج اللغوية الكبيرة بما يتجاوز النموذج الأساسي؟
هل يحفّز التعلم المعزز حقًا قدرات الاستدلال في النماذج اللغوية الكبيرة بما يتجاوز النموذج الأساسي؟
Yang Yue Zhiqi Chen Rui Lu Andrew Zhao Zhaokai Wang Shiji Song Gao Huang
الملخص
أظهر التعلم المعزز بمكافآت قابلة للتحقق (RLVR) مؤخرًا نجاحًا لافتًا في تعزيز أداء الاستدلال لدى النماذج اللغوية الكبيرة (LLMs)، لا سيما في مهام الرياضيات والبرمجة. ويُعتقد على نطاق واسع أنه، على غرار مساعدة التعلم المعزز التقليدي للوكلاء على استكشاف واستيعاب استراتيجيات جديدة، يمكّن RLVR النماذج اللغوية الكبيرة من التحسين الذاتي المستمر، مما يُمكّنها من اكتساب قدرات استدلال جديدة تتجاوز حدود النموذج الأساسي المقابل. في هذه الدراسة، نتناول نظرة نقدية للوضع الراهن لمنهجية RLVR من خلال فحص منهجي لحدود قدرة الاستدلال لدى النماذج اللغوية الكبيرة المُدرَّبة بـ RLVR عبر عائلات نماذج وخوارزميات تعلم معزز ومعايير تقييم متنوعة في الاستدلال الرياضي والتشفيري والبصري، باستخدام مقياس pass@k عند قيم k كبيرة كمعيار تقييم. ورغم أن RLVR يحسّن كفاءة العينات نحو المسارات الصحيحة، فقد وجدنا بشكل مفاجئ أن التدريب الحالي لا يُنشئ أنماط استدلال جديدة جوهريًا. نلاحظ أنه بينما تتفوق نماذج RLVR على نماذجها الأساسية عند قيم k الصغيرة (مثل k=1)، يحقق النموذج الأساسي درجة pass@k أعلى عندما تكون k كبيرة. علاوة على ذلك، نلاحظ أن حدود قدرة الاستدلال لدى النماذج اللغوية الكبيرة غالبًا ما تتقلص مع تقدّم تدريب RLVR. وتُظهر تحليلات التغطية والحيرة (perplexity) أن مسارات الاستدلال التي تولّدها نماذج RLVR مُضمَّنة بالفعل ضمن توزيع العينات للنموذج الأساسي، مما يشير إلى أن قدراتها الاستدلالية تنبع من النموذج الأساسي وتخضع لحدوده. ومن هذا المنظور، وباعتبار النموذج الأساسي حدًا علويًا، يُظهر تحليلنا الكمي أن ست خوارزميات RLVR شائعة أداءً متقاربًا وتبقى بعيدة عن الأداء الأمثل في استغلال الإمكانات الكاملة للنموذج الأساسي. في المقابل، وجدنا أن التقطير يمكن أن يُدخل أنماط استدلال جديدة من المُعلّم ويوسّع فعليًا قدرات النموذج الاستدلالية. وبمجمل نتائجنا، تُشير إلى أن منهجيات RLVR الحالية لم تُحقق بالكامل إمكانات التعلم المعزز في استخلاص قدرات استدلال جديدة حقًا لدى النماذج اللغوية الكبيرة. وهذا يؤكد الحاجة إلى نماذج تعلم معزز محسّنة — مثل التوسع المستمر والتفاعل متعدد الجولات بين الوكيل والبيئة — لإطلاق العنان لهذه الإمكانات.
One-sentence Summary
Researchers from LeapLab at Tsinghua University and Shanghai Jiao Tong University use pass@k at large k to systematically probe RLVR-trained LLMs and find that RLVR narrows rather than expands reasoning capability boundaries, with all tested reasoning paths originating from the base model's sampling distribution, whereas distillation genuinely introduces novel reasoning patterns.
Key Contributions
-
This paper provides a systematic framework for evaluating reasoning capability boundaries of RLVR-trained large language models across model families, reinforcement learning algorithms, and math, coding, and visual reasoning benchmarks, using pass@k at large k values.
-
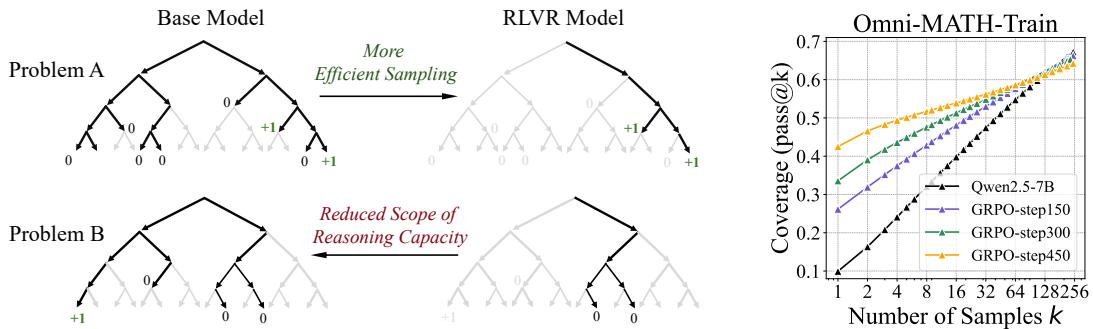
Empirical results indicate that current RLVR training improves sampling efficiency toward correct paths already present in base models, while base models can achieve higher pass@k scores at large k and RLVR-trained models often show narrowed reasoning boundaries.
-
A comparison of six popular RLVR algorithms against distillation shows that the RLVR algorithms perform similarly and remain far from fully leveraging the base model, whereas distillation introduces new reasoning patterns and expands reasoning capability.
Introduction
The authors study reinforcement learning with verifiable rewards, or RLVR, which has become important for improving large language models on reasoning-heavy tasks such as math and coding. In this setting, models are optimized using automatically verifiable feedback, such as final-answer correctness or passing unit tests, without relying on costly human annotations. Prior work has shown strong empirical gains, but it remained unclear whether RLVR genuinely teaches new reasoning strategies or merely makes better use of the base model’s existing capabilities. Previous analyses were often limited in scope and typically evaluated average-case performance, which can obscure a model’s true reasoning potential. The authors contribute a rigorous boundary evaluation using pass@k across multiple model families, sizes, tasks, and RLVR algorithms. They show that current RLVR improves sampling efficiency but does not fundamentally expand reasoning capacity, and that the successful reasoning paths found by RLVR models largely already exist in the base model.
Dataset
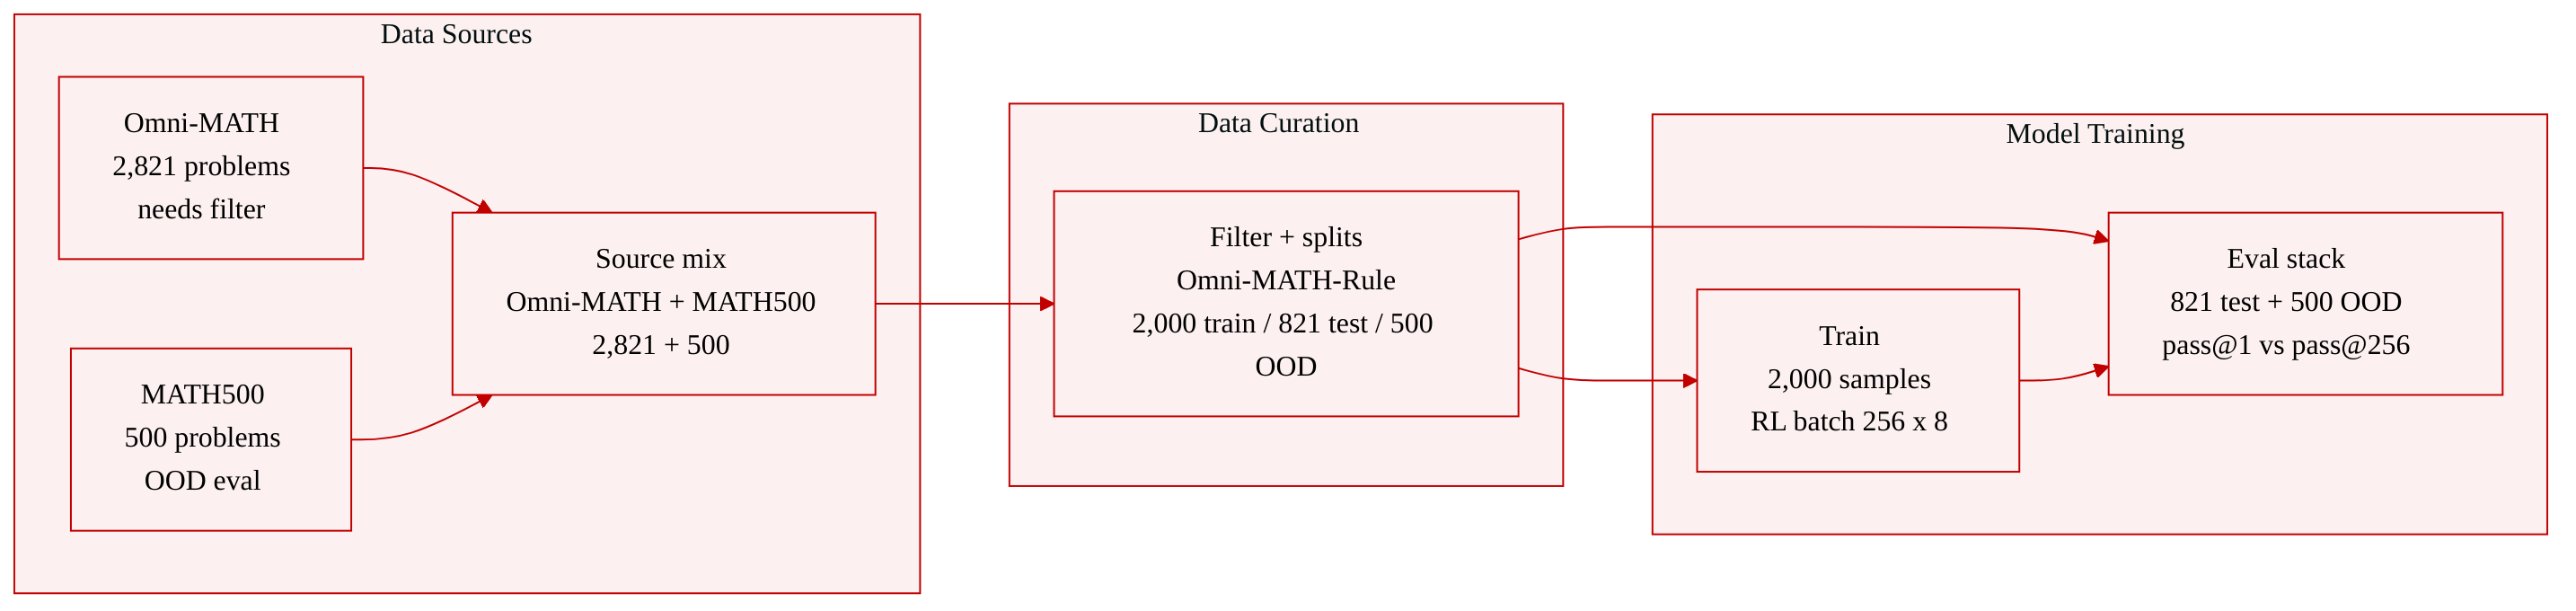
- The dataset is Omni-MATH-Rule, a subset of Omni-MATH selected to include math problems with verifiable answers.
- The authors split Omni-MATH-Rule into a 2,000-sample training set and an 821-sample in-domain test set.
- They use MATH500 as a separate out-of-domain benchmark for evaluating generalization.
- The data is used to study how different RL algorithms affect sampling efficiency, especially by comparing pass@1 with base-model pass@256.
- During evaluation, prompts are handled in batches of 256, with 8 candidate responses generated per prompt, under a maximum generation length of 8,192 tokens.
Method
The authors formulate reinforcement learning with verifiable rewards as an optimization problem over an LLM policy. Let πθ denote a language model with parameters θ that generates a token sequence y=(y1,…,yT) conditioned on a prompt x. A deterministic verifier V evaluates the generated output and returns a binary reward
r=V(x,y)∈{0,1},where r=1 if and only if the model’s final answer is exactly correct. In some settings, an additional format reward is used to encourage the model to separate its reasoning process from the final answer. The training objective is to maximize the expected reward over the prompt distribution D:
J(θ)=Ex∼D[Ey∼πθ(⋅∣x)[r]].The overall RLVR workflow, including prompt sampling, model generation, verifier scoring, and policy optimization, is summarized in the accompanying figure.
For policy optimization, the paper adopts Proximal Policy Optimization and its variants. PPO maximizes a clipped surrogate objective:
LCLIP=E[min(rt(θ)At,clip(rt(θ),1−ϵ,1+ϵ)At)],where
rt(θ)=πθold(yt∣x,y<t)πθ(yt∣x,y<t),and At is the advantage estimated by a value network Vϕ. The probability ratio rt(θ) measures how much the updated policy deviates from the old policy at each token position. The clipping operation limits the magnitude of this deviation, improving training stability compared with unbounded policy updates. An optional KL divergence term can also be added to constrain the optimized policy from drifting too far from the initial model.
PPO belongs to the broader policy gradient family of RL methods. These algorithms learn from on-policy samples, meaning the training data are generated by the current policy or an older version of it. In the verifiable-reward setting, the training signal is especially clean: samples whose final answers are correct receive positive feedback, while incorrect samples receive negative or zero feedback. Consequently, the policy gradient process increases the log likelihood of successful continuations and decreases the likelihood of unsuccessful ones.
The training protocol distinguishes between math tasks and coding or visual reasoning tasks. For math, the authors follow a zero RL setting, where RL is applied directly to a pretrained base model without prior supervised fine tuning. This setting is useful for isolating the effect of RLVR itself. For coding and visual reasoning, instruction-tuned models are typically used as starting points because zero RL from a pure pretrained model can be less stable. In those cases, the paper compares a supervised fine tuned model against its RLVR-trained counterpart to examine the incremental impact of reinforcement learning with verifiable rewards.
Experiment
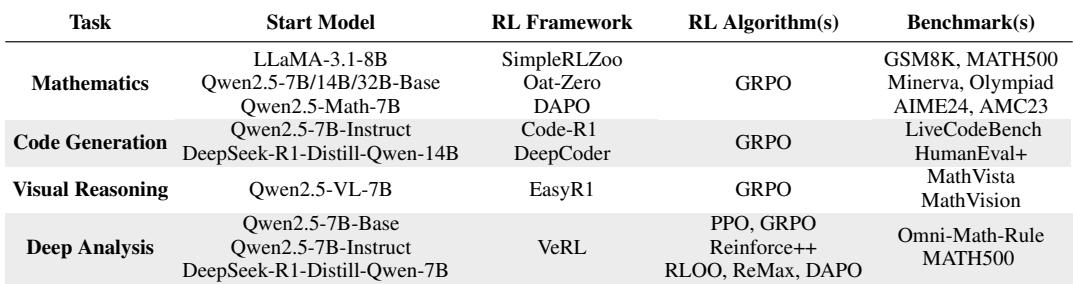
The experiments evaluate reasoning capacity boundaries across mathematical, coding, and visual reasoning benchmarks using pass@k with extensive sampling and consistent zero-shot prompts, comparing base, RLVR-trained, and distilled models. The results show that RLVR mainly improves sampling efficiency at small k, while base models often cover more solvable problems at larger k, indicating a narrower reasoning boundary after RL training. Analyses of coverage, perplexity, training settings, entropy, algorithm choice, and a near-frontier model suggest that current RLVR sharpens existing base-model reasoning paths rather than expanding them, whereas distillation can introduce new reasoning capabilities.
The experiments compare base and RLVR models across mathematics, code generation, and visual reasoning using matched zero-shot sampling settings. RLVR consistently improves low-budget pass performance, but its advantage narrows as the sampling budget increases, and larger near-frontier models show a similar boundary-limited pattern. The evaluation spans multiple model families, RL frameworks, and task domains, including mathematics, coding, and visual reasoning. Base and RLVR models use the same zero-shot prompt style to avoid confounding from few-shot examples. RLVR provides clear gains at low pass budgets, while base models catch up or outperform RLVR at higher pass budgets. KL regularization and entropy-matched generation do not remove the apparent narrowing of the RLVR reasoning boundary.
The base model and RLVR-trained model mostly solve the same problems, but the base model still solves many problems that the RLVR-trained model misses. The reverse case is rare, especially on AIME24, so the RLVR model's gains mainly reflect more reliable sampling on problems the base model can already solve. Both models fail on a notable fraction of AIME24 problems, while shared failures are much less common on MATH500. Most problems solved by the RLVR-trained model are also solvable by the base model. The base model covers a broader set of solvable problems than the RLVR-trained model. RLVR-trained models rarely solve problems that the base model cannot.
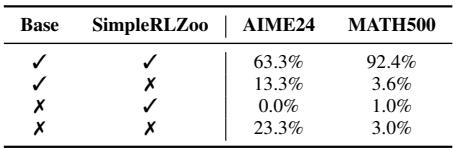
The experiments compare base and RLVR-trained models on mathematics, coding, and visual reasoning under matched zero-shot sampling across multiple model families and RL frameworks. They show that RLVR mainly increases reliability on problems the base model can already solve, yielding larger gains at low sampling budgets that narrow as budgets grow. The base model generally covers a broader set of solvable problems, while RLVR models rarely solve tasks beyond the base model's reach, suggesting reasoning boundary limitations rather than expanded capability.