Command Palette
Search for a command to run...
تعلم تحويل التسلسلات إلى تسلسلات باستخدام الشبكات العصبية
تعلم تحويل التسلسلات إلى تسلسلات باستخدام الشبكات العصبية
Ilya Sutskever Oriol Vinyals Quoc V. Le
الملخص
الشبكات العصبية العميقة (DNNs) نماذج قوية حققت أداءً ممتازًا في مهام التعلم الصعبة. وعلى الرغم من أن الشبكات العصبية العميقة تعمل بشكل جيد عندما تكون مجموعات بيانات التدريب الموسومة الكبيرة متاحة، إلا أنها لا يمكن استخدامها لتعيين التسلسلات إلى تسلسلات. في هذه الورقة، نقدم نهجًا عامًا شاملًا من البداية إلى النهاية لتعلم التسلسلات، لا يفترض إلا افتراضات ضئيلة حول بنية التسلسل. تستخدم طريقتنا ذاكرة المدى الطويل القصيرة متعددة الطبقات (LSTM) لتعيين تسلسل الإدخال إلى متجه ذي بُعد ثابت، ثم تستخدم شبكة LSTM عميقة أخرى لفك تشفير تسلسل الهدف من المتجه. نتيجتنا الرئيسية هي أنه في مهمة الترجمة من الإنجليزية إلى الفرنسية باستخدام مجموعة بيانات WMT-14، حققت الترجمات التي أنتجتها LSTM درجة BLEU تبلغ 34.8 على مجموعة الاختبار بأكملها، حيث كانت درجة BLEU الخاصة بـ LSTM مُعاقَبة على الكلمات خارج المفردات. إضافة إلى ذلك، لم تواجه LSTM صعوبة مع الجمل الطويلة. للمقارنة، حققت نظام الترجمة الآلية الإحصائية (SMT) القائم على العبارات درجة BLEU تبلغ 33.3 على نفس مجموعة البيانات. عندما استخدمنا LSTM لإعادة ترتيب الـ 1000 فرضية التي أنتجها نظام SMT المذكور آنفًا، ارتفعت درجته في BLEU إلى 36.5، وهو ما يقترب من أحدث التقنيات السابقة. تعلمت LSTM أيضًا تمثيلات معقولة للعبارات والجمل حساسة لترتيب الكلمات وثابتة نسبيًا تجاه المبني للمعلوم والمبني للمجهول. وأخيرًا، وجدنا أن عكس ترتيب الكلمات في جميع جمل المصدر (وليس جمل الهدف) حسّن أداء LSTM بشكل ملحوظ، لأن ذلك أدخل العديد من التبعيات قصيرة المدى بين جملة المصدر وجملة الهدف مما جعل مشكلة التحسين أسهل.
One-sentence Summary
Researchers at Google propose a general end-to-end sequence-to-sequence model that uses a deep LSTM encoder-decoder to map input sequences through a fixed-dimensionality vector to target sequences, achieving a BLEU score of 34.8 on English-to-French translation that surpasses phrase-based SMT, with the finding that reversing source word order introduces short-term dependencies that ease optimization.
Key Contributions
- The paper presents an end-to-end encoder-decoder method for sequence learning that uses a multilayered Long Short-Term Memory network to map an input sequence to a fixed-dimensional vector and a deep LSTM to decode the target sequence, while making minimal assumptions about sequence structure.
- On the WMT-14 English-to-French translation task, the LSTM system achieves BLEU 34.8 on the full test set with penalization for out-of-vocabulary words, surpassing a phrase-based statistical machine translation baseline at BLEU 33.3. It also raises BLEU to 36.5 by reranking 1000 hypotheses from that baseline.
- Reversing word order in source sentences, while leaving target sentences unchanged, markedly improves LSTM performance by introducing short-term dependencies between source and target sentences. Qualitative evaluation shows the learned representations are sensitive to word order, relatively invariant to active and passive voice, and capable of translating long sentences.
Introduction
Deep neural networks excel at tasks such as speech and vision because they can learn complex fixed-size mappings, yet many important problems, including machine translation and question answering, involve input and output sequences with unknown lengths. This length variability makes standard DNN application difficult, and earlier neural approaches often struggled with long sequences, relied on specialized alignment assumptions, or needed to assist an existing statistical translation system rather than translate directly. The authors leverage a long short-term memory encoder and decoder: one LSTM reads the source sequence into a fixed vector, while a second LSTM generates the target sequence from that vector. They also show that reversing the source word order introduces stronger short-term dependencies, making training easier and improving performance on long sentences. This simple sequence to sequence approach enables a large LSTM model to achieve strong direct English to French translation results and outperform a mature phrase based statistical machine translation baseline.
Dataset
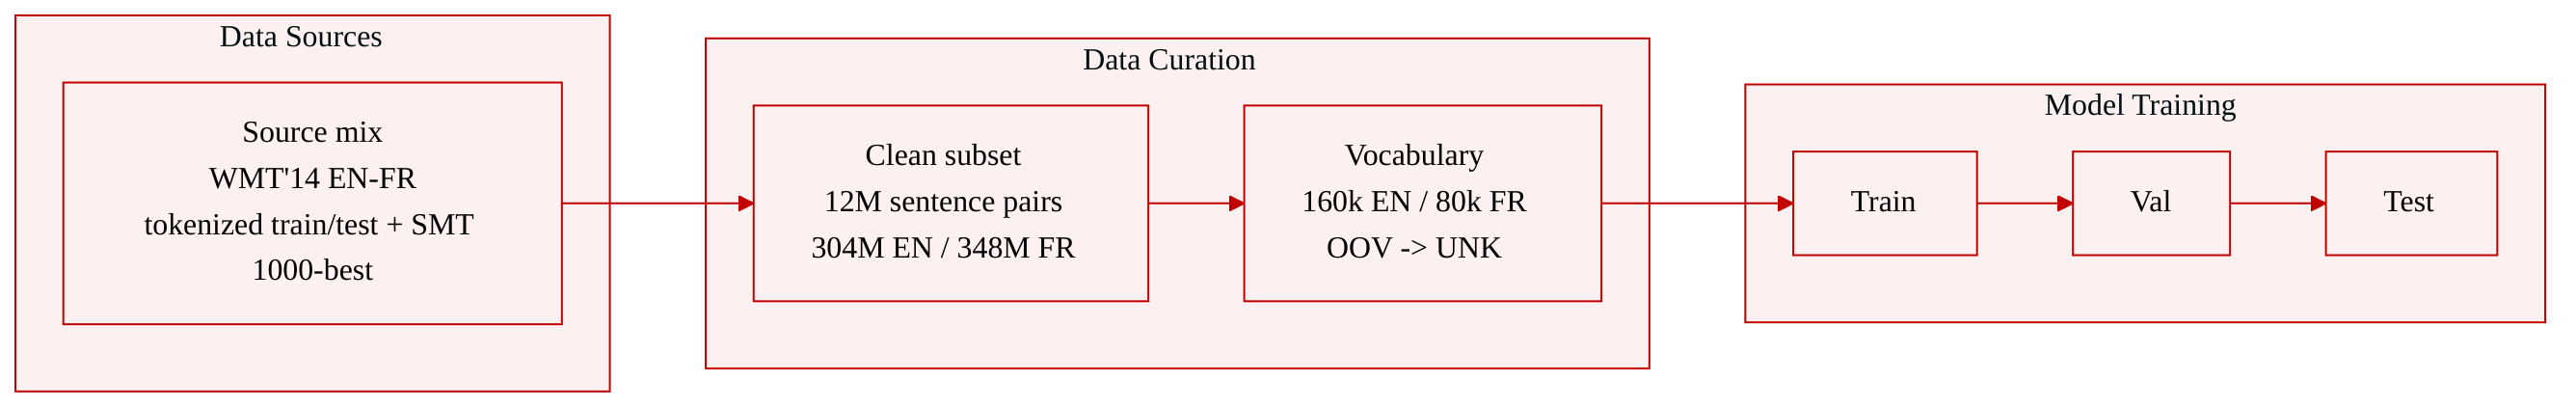
- The authors use the WMT’14 English-to-French machine translation dataset.
- They train on a clean “selected” subset containing 12 million sentence pairs.
- The training subset includes 348 million French words and 304 million English words.
- This subset was chosen because tokenized training and test sets are publicly available, along with 1000-best lists from a baseline SMT system.
- For processing, they use fixed vocabularies for both languages.
- The source English vocabulary includes the 160,000 most frequent words.
- The target French vocabulary includes the 80,000 most frequent words.
- All out-of-vocabulary words are replaced with a special “UNK” token.
Method
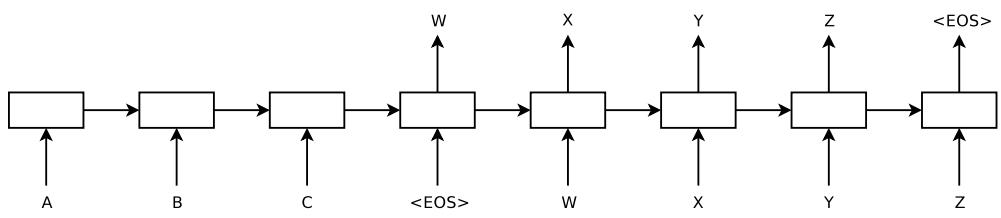
The authors leverage a sequence to sequence encoder decoder architecture built from Long Short Term Memory networks. The model receives an input sequence x1,…,xT and produces an output sequence y1,…,yT′, where the two sequences can have different lengths and the mapping between them is not monotonic. Instead of requiring a pre aligned input output correspondence, the architecture first compresses the source sequence into a fixed size vector, then uses that vector to condition a language model that generates the target sequence word by word.
The encoder processes the input sequence one time step at a time and outputs a hidden state that serves as the summary representation. The decoder is initialized with this representation and predicts the target sequence autoregressively. In this work, the authors separate the encoder and decoder into two distinct LSTM stacks, which increases model capacity at little extra computational cost and makes it natural to train on multiple language pairs. Each output distribution is modeled with a softmax over the target vocabulary, and the model can generate variable length sequences by using a special end of sequence token.
The conditional probability modeled by the system is written as
p(y1,…,yT′∣x1,…,xT)=t=1∏T′p(yt∣v,y1,…,yt−1),where v is the fixed dimensional representation of the input sequence produced by the encoder. The framework diagram below shows the overall flow from source words to target words and the final stopping token.
A key design choice is the reversal of the source sequence during training and inference. Rather than mapping a source sentence directly to its target, the model maps a reversed source sentence to the target sentence. This reduces the minimal time lag between related source and target words, because the first words of the reversed source are closer to the first words of the target sequence. The authors argue that this introduces many short term dependencies, which makes optimization easier and helps backpropagation establish communication between the encoder and decoder.
The deployed model uses deep LSTM stacks. The encoder and decoder are both multi layer LSTMs, with four layers in the final configuration. Each layer contains 1000 cells, and the input word embeddings are 1000 dimensional. The authors use different vocabularies for the source and target languages, and the decoder produces predictions with a naive softmax over the output vocabulary. The large parameter count is mainly due to recurrent connections inside the two LSTM stacks.
Training maximizes the log probability of a correct target sequence given its source sequence. The objective is
∣S∣1(T,S)∈S∑logp(T∣S),where S is the training set and p(T∣S) is computed with the factorization shown above. The parameters are initialized from a uniform distribution. The authors use stochastic gradient descent without momentum, with a fixed initial learning rate. The learning rate is reduced periodically during later epochs, and training runs for a limited number of epochs. Mini batches contain 128 sequences, and the computed gradient is divided by the batch size. To avoid exploding gradients, the gradient norm is clipped when it exceeds a threshold. Sentences within a mini batch are also grouped by similar length, which reduces wasted computation caused by large differences in sentence duration.
For efficient training, the system is parallelized across multiple GPUs. Each LSTM layer can be placed on a separate GPU, with activations passed to the next layer as soon as they are computed. The softmax computation is distributed across additional GPUs, allowing the large output projection to be handled more efficiently. This design makes it possible to train a very large deep LSTM on large sentence pairs using batch training.
At inference time, translations are produced by searching for the most likely target sequence:
T^=argTmaxp(T∣S).The authors implement a simple left to right beam search decoder. The beam maintains B partial hypotheses, each representing a prefix of a possible translation. At every decoding step, each hypothesis is extended with candidate target words, and only the B most likely hypotheses are kept according to the model log probability. When the end of sequence token is generated, the hypothesis is removed from the beam and stored as a complete translation. The authors find that even small beam sizes can work well, and they also use the LSTM to rescore baseline n best lists by averaging the baseline hypothesis score with the LSTM log probability.
Experiment
The experiments evaluate a deep LSTM translation system on the WMT’14 English-to-French task using both direct beam-search translation and rescoring of SMT n-best lists. They validate that reversing source sentences, increasing model depth, and using LSTM ensembles substantially improve translation quality, while multi-GPU training makes the large models tractable. Overall, the results show that a pure neural system can outperform an SMT baseline and approach strong systems, remains effective on long sentences, and learns representations sensitive to word order and semantics.
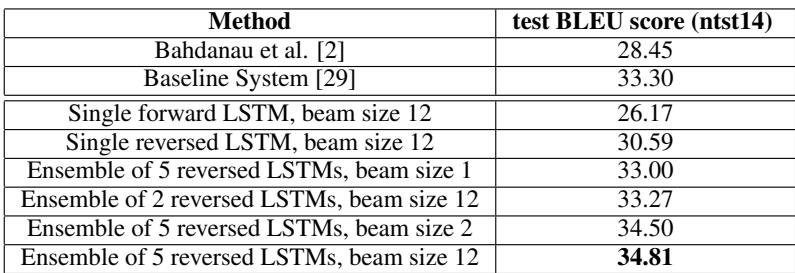
The results compare LSTM models for English-to-French translation on the ntst14 test set using cased BLEU score. Reversed LSTMs perform better than the single forward LSTM, and ensembles of reversed LSTMs give the strongest pure LSTM scores. A small beam ensemble is reported as cheaper than a single model decoded with a much larger beam. Reversed LSTMs outperform the single forward LSTM. An ensemble of five reversed LSTMs with a small beam reaches the best reported pure LSTM score. The ensemble system approaches the phrase-based baseline score.
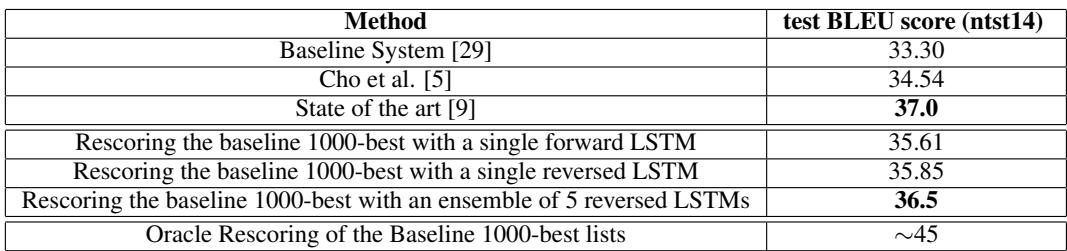
The results show that LSTM-based methods improve over the phrase-based SMT baseline on the English to French test set, with the strongest gains coming from rescoring baseline 1000-best translations. A five-model reversed LSTM ensemble reaches the closest performance to the prior state of the art, while oracle rescoring indicates substantial remaining potential in the baseline candidate lists. LSTM models using neural networks together with an SMT system outperform the baseline by a clear margin. Rescoring the baseline 1000-best list with a reversed LSTM ensemble gets very close to the prior state of the art. Oracle rescoring suggests that many of the best translations were already present in the baseline candidate lists.
The examples show that the LSTM can produce broadly sensible translations for long sentences while preserving the main ideas. The outputs sometimes reorder clauses and paraphrase details, and they may replace unknown words or names with an unknown token. The translations remain close to the ground truth in overall meaning, with differences mainly in wording and structure. The long example translations generally convey the intended meaning of the source sentences. Some outputs use an unknown token for proper names or unusual terms. The translations preserve overall topics while differing from the ground truth in clause order and wording.
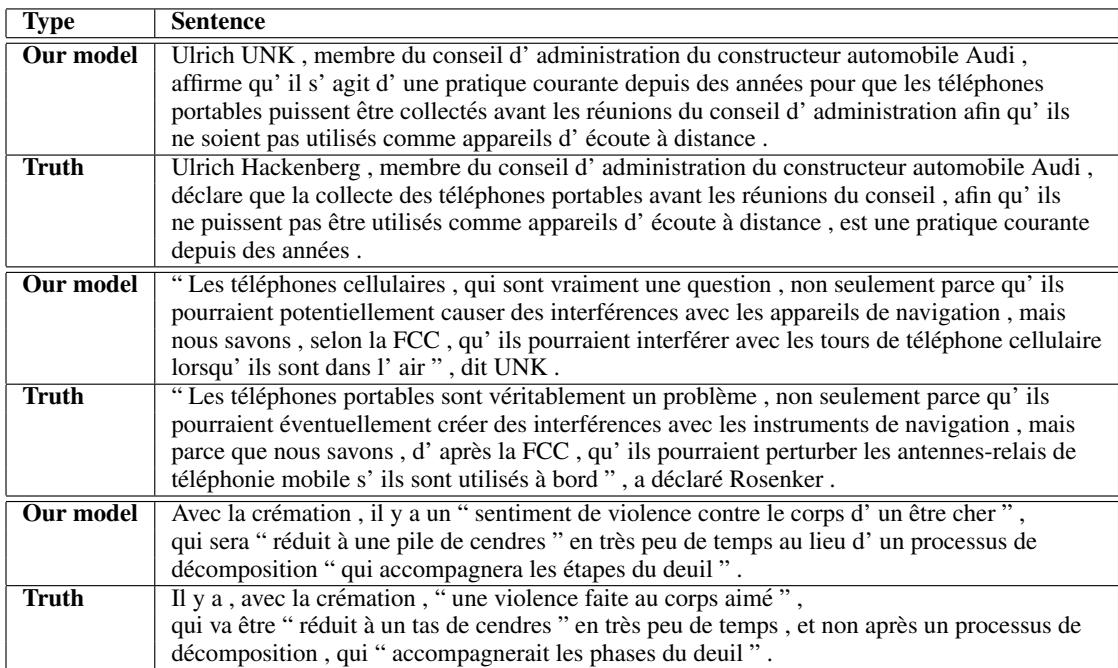
The experiments evaluate English-to-French translation on the ntst14 test set, showing that reversed LSTM architectures and ensembles improve over a single forward LSTM and approach phrase-based baselines. Hybrid LSTM rescoring of phrase-based 1000-best lists further exceeds the baseline and nears prior state-of-the-art performance, with oracle rescoring indicating substantial remaining potential. Qualitative examples indicate that long-sentence translations preserve the main content and overall meaning, despite differences in clause order, wording, and use of unknown tokens for rare names or terms.