Command Palette
Search for a command to run...
R-Tuning: تعليم النماذج اللغوية الكبيرة على قول "لا أعرف"
R-Tuning: تعليم النماذج اللغوية الكبيرة على قول "لا أعرف"
Hanning Zhang Shizhe Diao Yong Lin Yi R. Fung Qing Lian Xingyao Wang Yangyi Chen Heng Ji Tong Zhang
الملخص
أحدثت النماذج اللغوية الكبيرة (LLMs) ثورةً في مجالاتٍ متعددة بفضل أدائها المذهل، لكنها لا تزال تواجه تحدياتٍ جوهرية. من أبرز هذه التحديات ميلُ هذه النماذج إلى توليد حقائقَ وهمية، وهي إشكاليةٌ تُعرف بالهلوسة (Hallucination). تنبع دوافع بحثنا من ملاحظةٍ مفادها أن أساليب الضبط بالتعليمات (Instruction Tuning) السابقة تُجبر النموذج على إكمال جملة بغض النظر عن امتلاكه المعرفة المطلوبة من عدمه. فعندما يكون السؤال خارج المعرفة البارامترية (Parametric Knowledge) التي اختُزنت في النموذج، يميل إلى تلفيق إجابة وفشله في الإشارة إلى افتقاره للمعرفة. في هذا-paper، نقدّم نهجاً جديداً نسمّيه الضبط بالتعليمات الواعي بالرفض (Refusal-Aware Instruction Tuning)، أو ما نختصره بـ R-Tuning. نُصِيغ هذا النهج عبر تحديد الفجوة المعرفية بين ما تغطيهِ المعايير الأولية المُدرَّبة مسبقاً وما تتضمنه بيانات الضبط بالتعليمات. بعد ذلك، نبني بيانات واعيّة بالرفض اعتماداً على تقاطع المعرفة، لضبط النماذج اللغوية الكبيرة على امتناعها عن الإجابة عن الأسئلة التي تتجاوز معرفتها البارامترية. تُظهر النتائج التجريبية أن R-Tuning يعزّز بفاعلية قدرةَ النموذج على الإجابة عن الأسئلة المعروفة والامتناع عن الإجابة عن المجهولة منها. وعلاوةً على ذلك، عند اختبار النموذج على مجموعات بيانات خارج النطاق (Out-of-Domain)، تبيّن أن قدرة الرفض مهارةٌ فوقية (Meta-Skill) قابلةٌ للتعميم على مهامٍ أخرى. كما كشف تحليلٌ أعمق نتيجةً مفاجئةً وهي أن تعلّم حالة عدم اليقين يؤدي إلى معايرةٍ (Calibration) أفضل وقدرةٍ أدقّ على تقدير عدم اليقين مقارنةً بطرق الاختبار القائمة على عدم اليقين.
One-sentence Summary
Researchers from The Hong Kong University of Science and Technology and the University of Illinois Urbana-Champaign propose R-Tuning, a refusal-aware instruction tuning method that identifies knowledge disparities between pre-trained parameters and instruction tuning data to construct training examples enabling LLMs to refrain from answering questions beyond their parametric knowledge, a refusal ability shown to generalize as a meta-skill across out-of-domain tasks while improving uncertainty calibration.
Key Contributions
- R-Tuning is introduced as a refusal-aware instruction-tuning method that identifies the gap between pre-trained parametric knowledge and instruction tuning data, then constructs training examples with uncertainty expressions to make LLMs answer known questions while refusing unknown ones.
- Experiments show that R-Tuning improves answering known questions, avoids answering unknown questions, outperforms a traditional fine-tuning baseline on the AP score, and extends refusal to out-of-domain tasks as a meta-skill.
- Uncertainty analysis shows that training with explicit uncertainty expressions improves calibration and uncertainty estimation compared with uncertainty-based testing.
Introduction
Large language models are powerful general-purpose systems, but their tendency to hallucinate non-existent facts remains a major obstacle for reliable applications such as question answering, summarization, and knowledge-intensive generation. Prior work has addressed hallucination through retrieval, verification, confidence estimation, and uncertainty-based filtering, yet these approaches often treat the symptom rather than the underlying issue: models are typically forced to produce complete answers even when the requested knowledge is absent from their parametric memory.
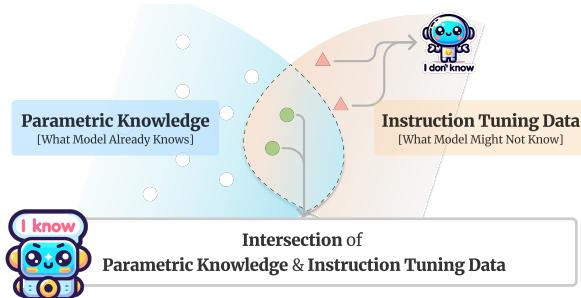
The authors attribute much of this behavior to a mismatch between parametric knowledge learned during pre-training and instruction-tuning datasets that may contain information the model does not reliably know. Under standard fine-tuning, a model trained only to complete correct answers may learn to guess instead of admitting uncertainty, leaving it poorly equipped to refuse questions beyond its knowledge boundary.
To address this, the authors introduce Refusal-Aware Instruction Tuning (R-Tuning). Their method estimates the knowledge gap between the model and its instruction data, separates certain from uncertain examples, and then trains on refusal-aware data that appends uncertainty or refusal expressions to answers for uncertain inputs. This teaches the model to recognize what it knows and what it does not, improving the reliability of willingly answered questions and enabling refusal behavior that generalizes across tasks.
Dataset
-
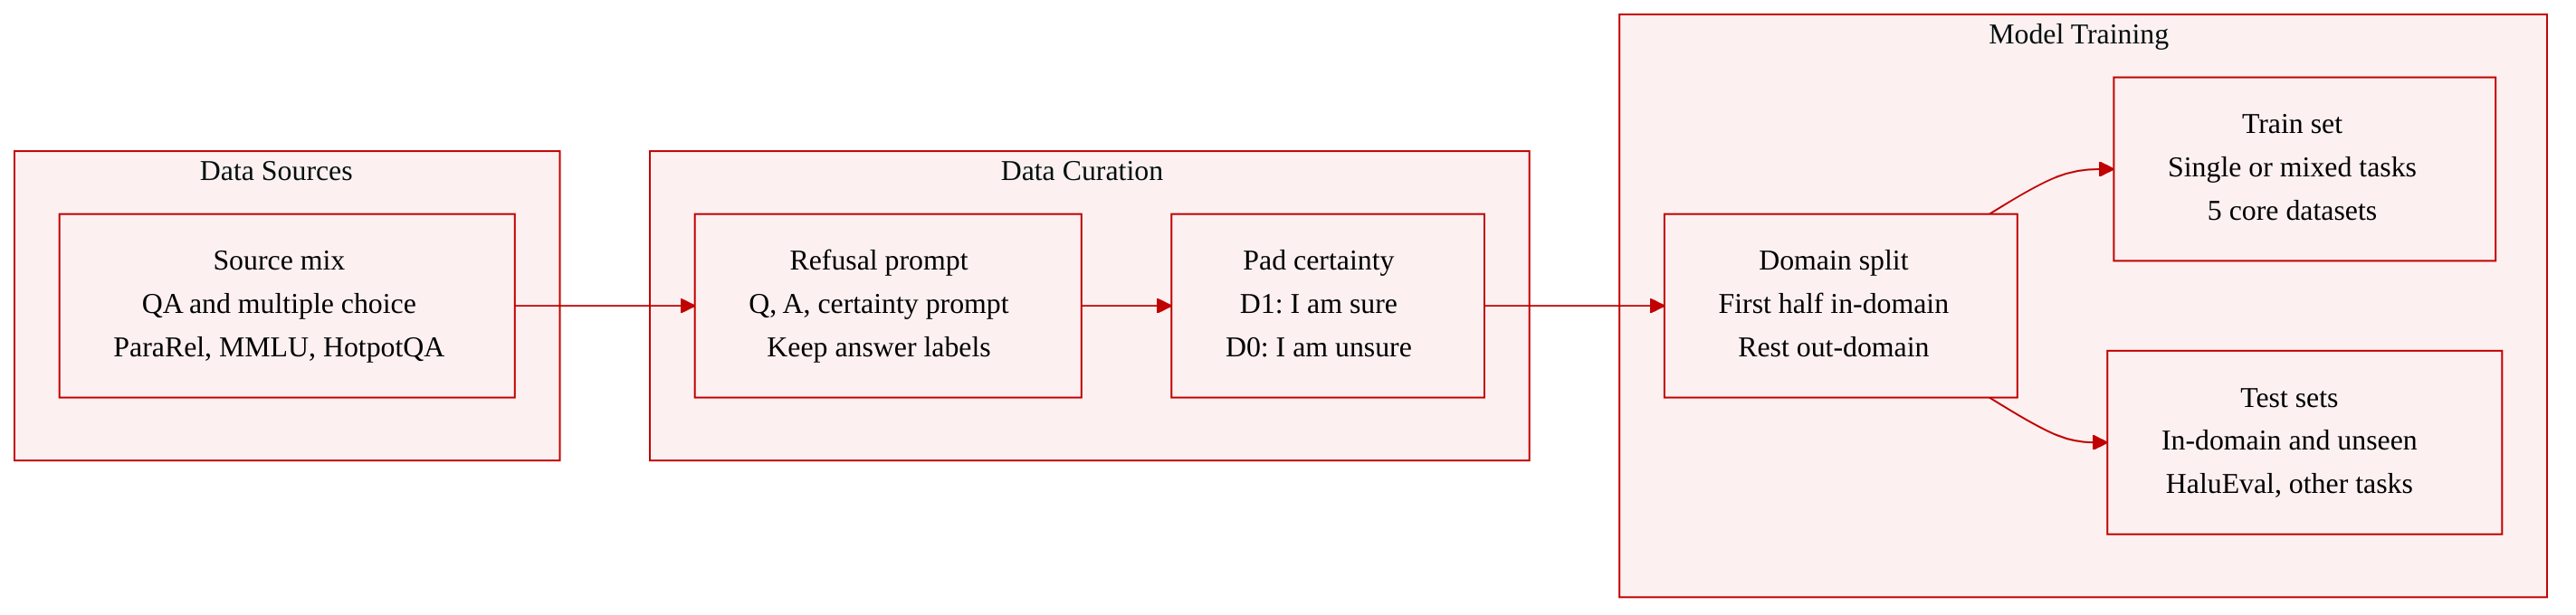
The authors build refusal-aware instruction data from downstream question-answering examples. Each example is formatted as
Q: {Question}, A: {Answer}. {Prompt}., where the prompt is “Are you sure you accurately answered the question based on your internal knowledge?”. -
They use a padding strategy to add uncertainty signals while preserving the original answer labels. The certainty dataset, called D1, appends “I am sure” after the template, and the uncertainty dataset, called D0, appends “I am unsure”. This lets the model learn to express uncertainty without losing the original label information.
-
The paper also mentions an alternative replacement method, where label words are directly replaced with uncertainty expressions, but the main construction described is the padding method above.
-
The downstream evaluation data are organized into two task formats. The Question-Answering format includes ParaRel, HotpotQA, SelfAware, HaluEval, FalseQA, and NEC. The Multiple-Choice format includes MMLU, WiCE, and FEVER.
-
For single-task experiments, the authors use ParaRel and MMLU separately. Each dataset is manually split into a training set, an in-domain test set, and an out-of-domain test set using available domain annotations. Questions from the first half of the domains are used as in-domain data, while questions from the remaining domains are used as out-of-domain data.
-
For multi-task experiments, the authors mix training data from ParaRel, MMLU, WiCE, HotpotQA, and FEVER to form a combined training set. Evaluation is performed on the corresponding in-domain test sets and on an unseen out-of-domain test set, HaluEval.
-
The provided text does not report explicit subset sizes, detailed filtering rules, cropping strategies, or additional metadata beyond these formats, splits, task definitions, and prompt-based construction details.
Method
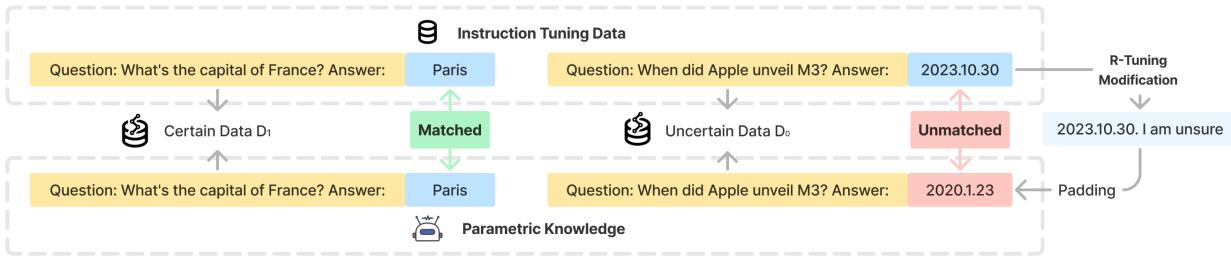
The authors leverage Refusal-Aware Instruction Tuning, or R-Tuning, to adapt a language model so that it can separate questions it can answer from questions that exceed its parametric knowledge. The method treats the original instruction tuning dataset as a source of both certain and uncertain examples. It first asks the pre-trained model to answer each training question, then compares the prediction with the reference label. If the prediction matches the label, the example is placed in the certain set D1. If the prediction mismatches the label, the example is placed in the uncertain set D0. This step identifies where the model’s internal knowledge is aligned with the supervision signal and where it is not. As shown in the figure below:
After this identification step, the authors construct refusal-aware training targets with a prompt template. The template keeps the original question and answer, then appends a certainty or uncertainty expression. Conceptually, the constructed sample takes the form:
Q:{Question},A:{Answer}.{Prompt}.
The prompt asks whether the model accurately answered the question based on internal knowledge. For instances in D1, the model is trained to append “I am sure” after the answer. For instances in D0, the model is trained to append “I am unsure”. This padding design preserves the ground-truth answer while teaching the model to express confidence or uncertainty toward its own response. In other words, the model still sees the full label information, but it also learns a behavioral signal about whether that label corresponds to reliable parametric knowledge.
The resulting dataset is used with standard instruction-tuning training. Given a token sequence t1,t2,…,tT that contains the question, answer, and uncertainty expression, the model predicts the next token conditioned on previous tokens. The objective is a standard cross-entropy loss:
L=−T1i=1∑TlogP(ti∣t1,t2,…,ti−1).Importantly, the loss is applied only to the answer portion and the uncertainty portion, while the question portion is masked out. This focuses training on answer generation and self-assessment rather than memorizing the input prompt.
During inference, the input question is first placed into the same template so that the model can generate an answer. Then the prompt “Are you sure you accurately answered the question based on your internal knowledge? I am” is appended after the generated context. The model continues by producing a certainty or uncertainty expression. The probability mass assigned to “I am sure” versus “I am unsure” can then be combined with the answer probability to form a confidence estimate. This makes the model’s self-reported uncertainty useful for evaluating whether it should answer or avoid a question.
The authors also describe an unsupervised variant for identifying uncertain examples without relying on direct gold-label comparison. In this approach, the model samples k answers for each question and estimates uncertainty through entropy:
u=−j=1∑kp(aj∣q)logp(aj∣q),where p(aj∣q) is the frequency of predicted answer aj for question q. Questions with higher entropy are considered less reliably answered by the model. The most uncertain questions are routed into the uncertain training set and paired with uncertainty expressions, while the remaining questions are routed into the certain set and paired with certainty expressions. This provides a label-free way to expose the model to knowledge-gap-aware training signals.
Experiment
The experiments evaluate refusal-aware answering on ParaRel and MMLU using OpenLLaMA and LLaMA models, comparing pre-trained and vanilla instruction-tuned baselines with R-Tuning through accuracy on willingly answered questions and average precision. They show that selectively answering questions consistent with the model’s parametric knowledge produces more reliable predictions, better confidence calibration, and stronger refusal behavior than answering all inputs. Additional analyses using uncertainty-based data selection, unanswerable-question benchmarks, perplexity, and entropy further support that uncertainty can help identify knowledge boundaries and improve model trustworthiness.
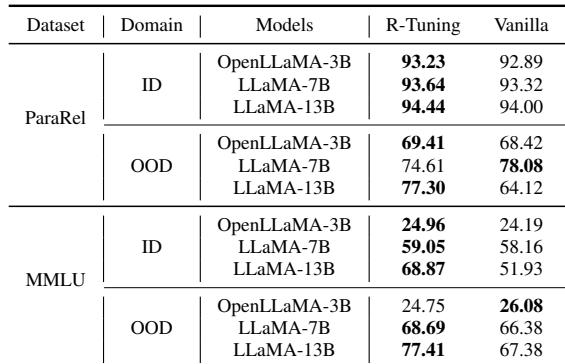
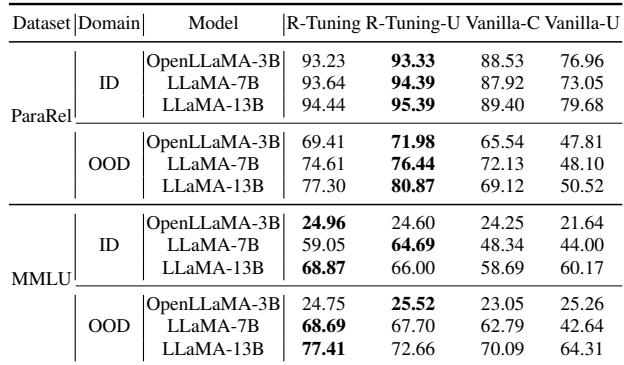
Across the single task results, R Tuning generally achieves higher AP scores than Vanilla, especially on in-domain ParaRel and MMLU and on the largest out of domain ParaRel setting. The gains are not uniform, because the smaller out of domain comparisons are mixed and the 7B model shows a reversal on ParaRel OOD. The pattern supports the idea that answering only confidently supported questions can improve performance, while outcomes depend on model size and domain. R Tuning outperforms Vanilla in most reported settings, with consistent small gains on ParaRel ID and an advantage on MMLU ID. The out of domain results are mixed, showing a strong R Tuning gain for the largest model but a Vanilla advantage for the 7B model.
Across the reported ParaRel and MMLU comparisons, R-Tuning-U generally attains the strongest or near strongest AP performance, supporting the idea that uncertainty based data selection can create effective refusal-aware training data. R-Tuning-U consistently outperforms Vanilla-C and Vanilla-U, especially on ParaRel, while the unsupervised variant is also close to or slightly ahead of supervised R-Tuning. The larger gaps for Vanilla-U, particularly in out-of-domain ParaRel, suggest that simply applying confidence scoring to Vanilla-C answers is less reliable than learning uncertainty during training. R-Tuning-U gives higher AP than supervised R-Tuning in the reported ParaRel in-domain and out-of-domain rows. Uncertainty learning during training outperforms test-time uncertainty filtering represented by Vanilla-C across the listed ParaRel models. Vanilla-U is the weakest method overall, with especially pronounced drops on out-of-domain ParaRel. ParaRel scores are much higher than the reported MMLU score, and both R-Tuning methods remain stronger than Vanilla-C and Vanilla-U on MMLU.
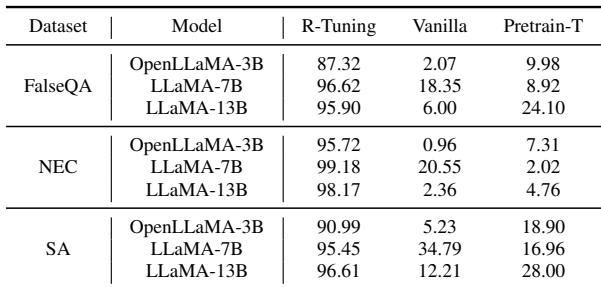
R-Tuning achieves substantially higher refusal rates than the Vanilla and Pretrain baselines on benchmarks containing unanswerable questions. It refuses nearly all such questions across model sizes, while other fine-tuned and pretrained models often answer even when allowed to refuse. This shows stronger conservation when questions contradict common sense or exceed parametric knowledge. R-Tuning shows very high refusal rates on unanswerable question benchmarks. Vanilla and Pretrain baselines have low refusal rates and often answer invalid questions.
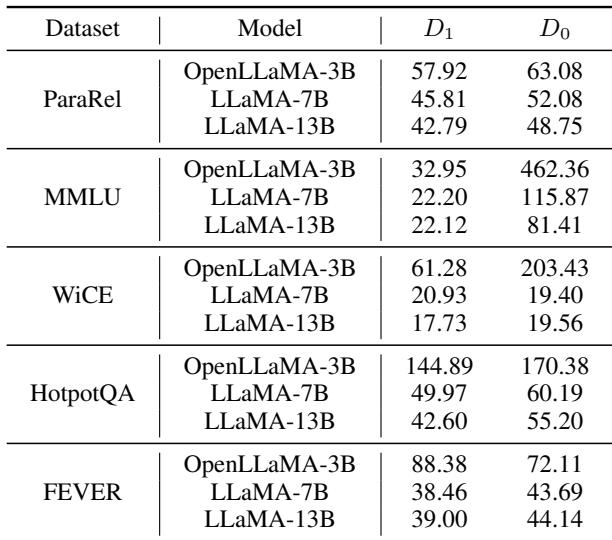
Across the reported datasets, the pre-trained models assign lower perplexity to certain data than to uncertain data, indicating that the models find certain questions more familiar and less difficult. Larger models generally show lower perplexity, suggesting that model scale improves the ability to process training questions and may reduce uncertainty. Certain questions consistently have lower perplexity than uncertain questions across model sizes. Uncertain questions are associated with much higher perplexity, especially for smaller models. Larger models generally produce lower perplexity than smaller models.
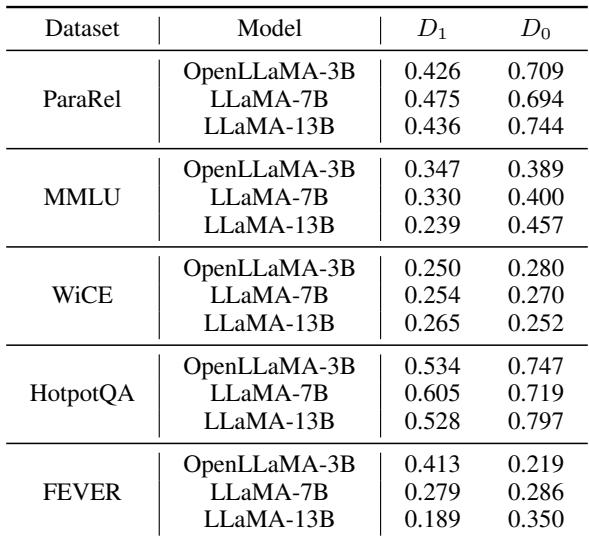
Across the reported datasets, the certain data split D1 shows lower answer entropy than the uncertain split D0, meaning predictions on D1 are more concentrated and less variable. The uncertainty gap is visible for each model configuration where both splits are reported, and it is especially large on ParaRel and MMLU. These results support a division of training data into answerable and harder, more uncertain subsets. Predicted answers on D1 are more consistent than on D0 across the reported settings. Uncertain data D0 has markedly higher entropy than certain data D1 on ParaRel and MMLU. The higher entropy of D0 aligns with greater uncertainty or multiple possible predicted answers for difficult data.
The experiments evaluate R-Tuning on ParaRel and MMLU with single-task, ablation, refusal, and uncertainty analyses. R-Tuning, especially its uncertainty-based variant, generally outperforms Vanilla baselines by improving answer selection, yielding the strongest or near strongest accuracy on in-domain settings and showing model-size dependent gains out of domain, while its main advantage is refusing nearly all unanswerable questions. Perplexity and entropy analyses further show that uncertain data are less familiar and more variable than certain data, supporting the use of uncertainty-based training data for answerability-aware behavior.