Command Palette
Search for a command to run...
إدراك الغروكينغ: إثبات وجود الغروكينغ في انحدار Ridge
إدراك الغروكينغ: إثبات وجود الغروكينغ في انحدار Ridge
Mingyue Xu Gal Vardi Itay Safran
الملخص
ندرس ظاهرة الغروكينغ — أي onset التعميم طويلًا بعد الإفراط في التخصيص — في إطار الانحدار Ridge الكلاسيكي. نثبت نتائج شاملة للغروكينغ عند تعلّم نماذج الانحدار الخطي الفائضة المعلمات باستخدام نزول التدرج مع إضمحلال الأوزان. على وجه التحديد، نُثبت حدوث المراحل التالية: (أ) يُفرط النموذج في تخصيص بيانات التدريب في المراحل المبكرة من التدريب؛ (ب) يستمر ضعف التعميم طويلًا بعد ظهور الإفراط في التخصيص؛ (ج) يصبح خطأ التعميم صغيرًا اعتباطيًا في النهاية. علاوة على ذلك، نُظهر نظريًا وتجريبيًا أنه يمكن تضخيم الغروكينغ أو_elimination_ منه بأسلوب مبدئي من خلال الضبط المناسب للمعلمات الفائقة. وبحسب علمنا، فإن هذه أولى الحدود الكمية الصارمة على تأخير التعميم (الذي نُطلق عليه «زمن الغروكينغ») بدلالة المعلمات الفائقة للتدريب. وأخيرًا، نتجاوز الإطار الخطي فنُظهر تجريبيًا أن حدودنا الكمية تلتقط أيضًا سلوك الغروكينغ في الشبكات العصبية غير الخطية. تُشير نتائجنا إلى أن الغروكينغ ليس حالة فشل متأصلة في التعلّم العميق، بل هو نتيجة لظروف تدريب محددة، ومن ثمّ لا يتطلب تفاديَه تغييرات جوهرية في بنية النموذج أو خوارزمية التعلّم.
One-sentence Summary
This work proves the first rigorous quantitative bounds on grokking time in over-parameterized ridge regression trained with gradient descent and weight decay, demonstrating that grokking unfolds through overfitting, prolonged poor generalization, and eventual convergence, with the delay controllable through hyperparameter tuning rather than architectural changes and empirically validated on non-linear neural networks.
Key Contributions
-
The paper proves end-to-end grokking in over-parameterized linear ridge regression trained with gradient descent and weight decay, including early overfitting, sustained poor generalization, and eventual arbitrarily small generalization error.
-
The paper establishes quantitative bounds on the generalization delay, termed grokking time, in terms of training hyperparameters, and shows theoretically and empirically that proper hyperparameter tuning can amplify or eliminate grokking.
-
The paper empirically shows that the derived bounds also capture grokking on nonlinear neural networks, and that a threshold-based accuracy metric recovers the familiar test error plateau in regression.
Introduction
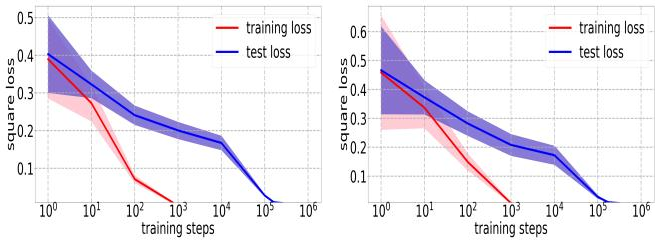
In deep learning and related ML systems, grokking is a counterintuitive overfitting phenomenon where training accuracy becomes perfect early, while test generalization improves only much later. This matters because it challenges standard regularization intuition and reveals hidden dynamics in how models converge during optimization. Prior theory often links grokking to regime changes in training, such as lazy-to-rich dynamics or weight-decay effects, but earlier analyses generally lack rigorous end-to-end guarantees, fail to prove that poor generalization persists long after overfitting, or study overly narrow settings. The authors leverage an over-parameterized linear ridge regression framework to provide the first provable end-to-end grokking result, showing that gradient descent can quickly fit the training data, maintain worse generalization for a quantifiable delay, and later converge to a well-generalizing global optimum, while also giving explicit hyperparameter bounds and demonstrating that weight decay can control the grokking time.
Method
The authors leverage a teacher-student regression pipeline to isolate the mechanism behind grokking. Each input xi∈Rd is sampled from a marginal distribution Dx, and its label is given exactly by a fixed teacher function N∗(x). The student model is linear in a feature representation:
N(x;θ)=⟨θ,ϕ(x)⟩,where ϕ(x):Rd↦Rm is a fixed feature map and θ∈Rm is trainable. The realizable assumption means that there exists some θ∗ such that N∗(x)=⟨θ∗,ϕ(x)⟩.
Training is performed with ridge regression, which combines the empirical squared loss with an ℓ2 regularization term:
Ln(θ;λ)=2n1i=1∑n(⟨θ−θ∗,ϕ(xi)⟩)2+2λ∥θ∥22.The parameter is optimized using vanilla gradient descent:
θ(t+1)=θ(t)−nηi=1∑n⟨θ(t)−θ∗,ϕ(xi)⟩ϕ(xi)−ηλθ(t),where η is the learning rate and λ is the weight decay strength. The method studies training from a random initialization θ(0)∼N(0,ν2Im), which makes the early dynamics and the eventual decay of unused directions analytically tractable.
The central mechanism behind grokking is a subspace decomposition of the learned weights. Let V=span{ϕ(x1),…,ϕ(xn)} denote the feature subspace spanned by the training examples. In the overparameterized regime m≫n, the optimization can be understood by splitting θ into a component θ∥ inside V and a component θ⊥ in the complementary subspace. The empirical gradient primarily updates θ∥, allowing the model to fit the training data quickly. However, θ⊥ is invisible to the empirical loss and is mainly reduced by weight decay. Therefore, when λ is very small, training loss can decrease rapidly while the component responsible for poor population performance decays slowly.
This gives rise to two relevant time points. The first is
t1=max({t∈N:Ln(θ(t))≥ϵ}),which marks the end of rapid training loss reduction. The second is
t2=min({t∈N:L(θ(t))≤c}),which marks the point where population loss becomes small. The authors show that, under sufficient sample size, large feature dimension, sufficiently small weight decay, and a compatible learning rate, t1 can be small while t2 can be arbitrarily large. Their bounds imply
t1≤2ηλmin+(Φ⊤Φ)nln(ϵ6b2∥θ(0)∥22),and
t2≥4ηλln(2(m−n)ν2(λmin(Σ)c+∥θ∗∥2)−2),where Φ is the empirical feature matrix, Σ=E[ϕ(x)ϕ(x)⊤] is the feature covariance matrix, and b bounds the feature norm. These expressions make clear why a small λ can delay generalization without preventing fast training convergence.
To connect the theoretical bounds with observable hyperparameter behavior, the authors evaluate how λ, sample size n, feature dimension m, and initialization scale ν2 change t1 and t2. As shown in the figure below:
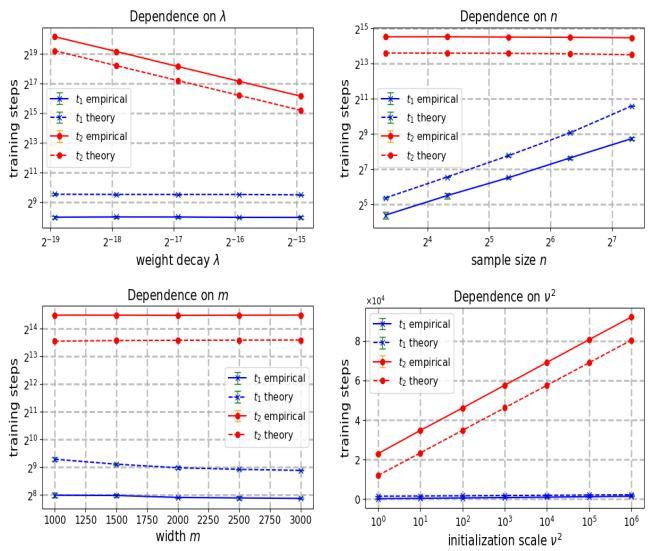
The plots indicate that decreasing λ primarily increases t2, because the orthogonal component θ⊥ decays more slowly under weak weight decay. Reducing n can shorten t1 by making the training set easier to fit, thereby widening the interval t2−t1. Increasing m has a comparatively muted effect in the plotted regime, while increasing ν2 shifts both t1 and t2 upward at logarithmic rates, with t2 growing faster, which amplifies the grokking gap.
The empirical ridge regression pipeline uses the identity feature map in some experiments, so that the student predicts ⟨θ,x⟩. Samples are generated under distributional assumptions on the features, often i.i.d. spherical Gaussian vectors, so that the covariance structure and the positive eigenvalue of the empirical Gram matrix can be estimated. The learning rate is fixed, and the model is trained by gradient descent with weight decay until both training and generalization behavior are observed.
The authors also extend the training protocol to a two-layer ReLU network. The network takes an input x∈Rd, applies a first-layer weight matrix W, passes the resulting hidden units through ReLU, and combines them with a second-layer vector a. The output has the form
N(x;W,a)=j=1∑majReLU(⟨wj,x⟩).Both W and a are trained jointly with gradient descent and weight decay. The zero teacher is used as a simplified target, and the initialization scale ν2 controls the initial norm of the first-layer weights. This nonlinear setup serves to check whether the same hyperparameter trends predicted by the ridge regression analysis appear beyond the linear feature model.
Experiment
The experiments use ridge regression and gradient descent with weight decay to empirically test the theoretical grokking behavior, comparing training and generalization error timelines under controlled hyperparameters. The results confirm that small weight decay can produce the predicted separation between early overfitting and later generalization, closely matching the theoretical bounds. Extensions to random-feature networks and fully trained nonlinear ReLU networks exhibit qualitatively similar grokking behavior, suggesting that the observed phenomenon is not limited to the idealized linear setting.