Command Palette
Search for a command to run...
كولاب إل إل إم: من مستجيبين سلبيين إلى متعاونين نشطين
كولاب إل إل إم: من مستجيبين سلبيين إلى متعاونين نشطين
Shirley Wu Michel Galley Baolin Peng Hao Cheng Gavin Li Yao Dou Weixin Cai James Zou Jure Leskovec Jianfeng Gao
الملخص
عادةً ما تُدرَّب نماذج اللغة الكبيرة باستخدام مكافآت تعتمد على الاستجابة التالية فقط، مما يحد من قدرتها على تحسين التفاعل طويل الأمد. ونتيجةً لذلك، فإنها غالبًا ما تستجيب بشكل سلبي لطلبات المستخدمين الغامضة أو مفتوحة النهاية، وتفشل في مساعدتهم على تحقيق أهدافهم النهائية، مما يؤدي إلى محادثات غير فعّالة. لمعالجة هذه القيود، نقدم إطار عمل جديدًا وعامًا للتدريب يُسمى كولاب إل إل إم، يعزز التعاون البشري-النموذجي متعدد الجولات. يتمثل ابتكاره الأساسي في محاكاة تعاونية تُقدّر المساهمة طويلة الأمد للاستجابات باستخدام مكافآت تدرك تعدد الجولات. من خلال الضبط الدقيق القائم على التعزيز لهذه المكافآت، يتجاوز كولاب إل إل إم مجرد الاستجابة لطلبات المستخدمين، ليكشف بنشاط عن نوايا المستخدم، ويقدم اقتراحات ثاقبة—وهي خطوة أساسية نحو الذكاء الاصطناعي الأكثر تركيزًا على الإنسان. كما نطوّر معيارًا للتفاعل متعدد الجولات يتضمن ثلاث مهام صعبة مثل إنشاء المستندات. يتفوق كولاب إل إل إم بشكل ملحوظ على خطوط الأساس لدينا بمتوسط أداء أعلى بنسبة 18.5% في المهام، وتحسين التفاعلية بنسبة 46.3% وفقًا لتقييم نماذج اللغة الكبيرة. أخيرًا، نجري دراسة مستخدمين واسعة النطاق بمشاركة 201 مُقيّمًا، حيث يزيد كولاب إل إل إم من رضا المستخدمين بنسبة 17.6% ويقلل من الوقت الذي يقضيه المستخدمون بنسبة 10.4%.
One-sentence Summary
Microsoft Research and Stanford introduce COLLABLLM, a training framework that leverages collaborative simulation with multiturn-aware rewards to optimize long-term human-LLM interaction, enabling proactive intent discovery and suggestions, and it outperforms baselines by 18.5% in task performance, 46.3% in interactivity, and increases user satisfaction by 17.6% while reducing user time by 10.4%.
Key Contributions
-
The paper introduces COLLABLLM, a training framework that estimates the long-term contribution of each response via collaborative simulation with Multiturn-aware Rewards, then applies reinforcement fine-tuning on these rewards. This allows the model to actively uncover user intent and offer suggestions, explicitly modeling the causal impact of responses on task success through forward sampling.
-
A multiturn interaction benchmark is devised with three challenging tasks, including document creation, to evaluate long-term human-LLM collaboration. It covers open-ended scenarios with highly diverse user input and limited user capacity to review lengthy outputs.
-
COLLABLLM outperforms baselines by 18.5% higher task performance and 46.3% improved interactivity as judged by LLMs. A user study with 201 judges reports a 17.6% increase in user satisfaction and a 10.4% reduction in time spent.
Introduction
Modern Large Language Models generate strong single-turn responses, but real users often begin with vague or incomplete intents and refine their requests through iterative corrections. That dynamic increases frustration, reduces conversational efficiency, and makes it harder to complete complex, open-ended tasks. An open problem, therefore, is training models that actively guide users to clarify and refine their intents rather than passively answering each turn.
A central limitation of established fine-tuning techniques such as Reinforcement Learning from Human Feedback (RLHF) is that they reward immediate, single-turn responses. This gives models little incentive to seek clarification or help users sharpen their preferences, so deployed LLMs tend to answer directly even when asking follow-up questions would improve task outcomes and satisfaction.
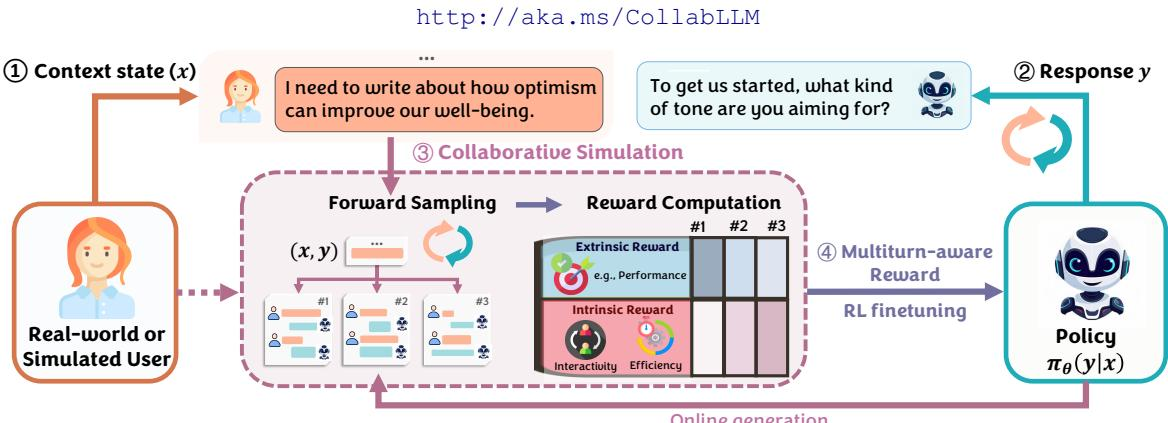
The authors introduce COLLABLLM, a general training framework that improves LLM collaboration in multiturn scenarios. Its key innovation is promoting forward-looking behavior through a collaborative simulation module that samples future conversations to estimate the long-term impact of each response, quantified as a Multiturn-aware Reward (MR). The MR combines extrinsic metrics such as task-specific success with intrinsic metrics such as efficiency. By fine-tuning with RL on MRs, COLLABLLM learns responses that yield better task completion and efficiency in later conversation stages. The authors also release three challenging multiturn benchmarks, MediumDocEdit-Chat, BigCodeBench-Chat, and MATH-Chat, covering document creation, code generation, and multiturn question answering. On these tests, COLLABLLM improves task accuracy by 18.5% and interactivity by 46.3% on average over strong baselines, generalizes to unseen data domains, and in a large-scale user study with 201 Amazon Mechanical Turkers, it raises user satisfaction by 17.6% and saves 10.4% of user time on average.
Dataset
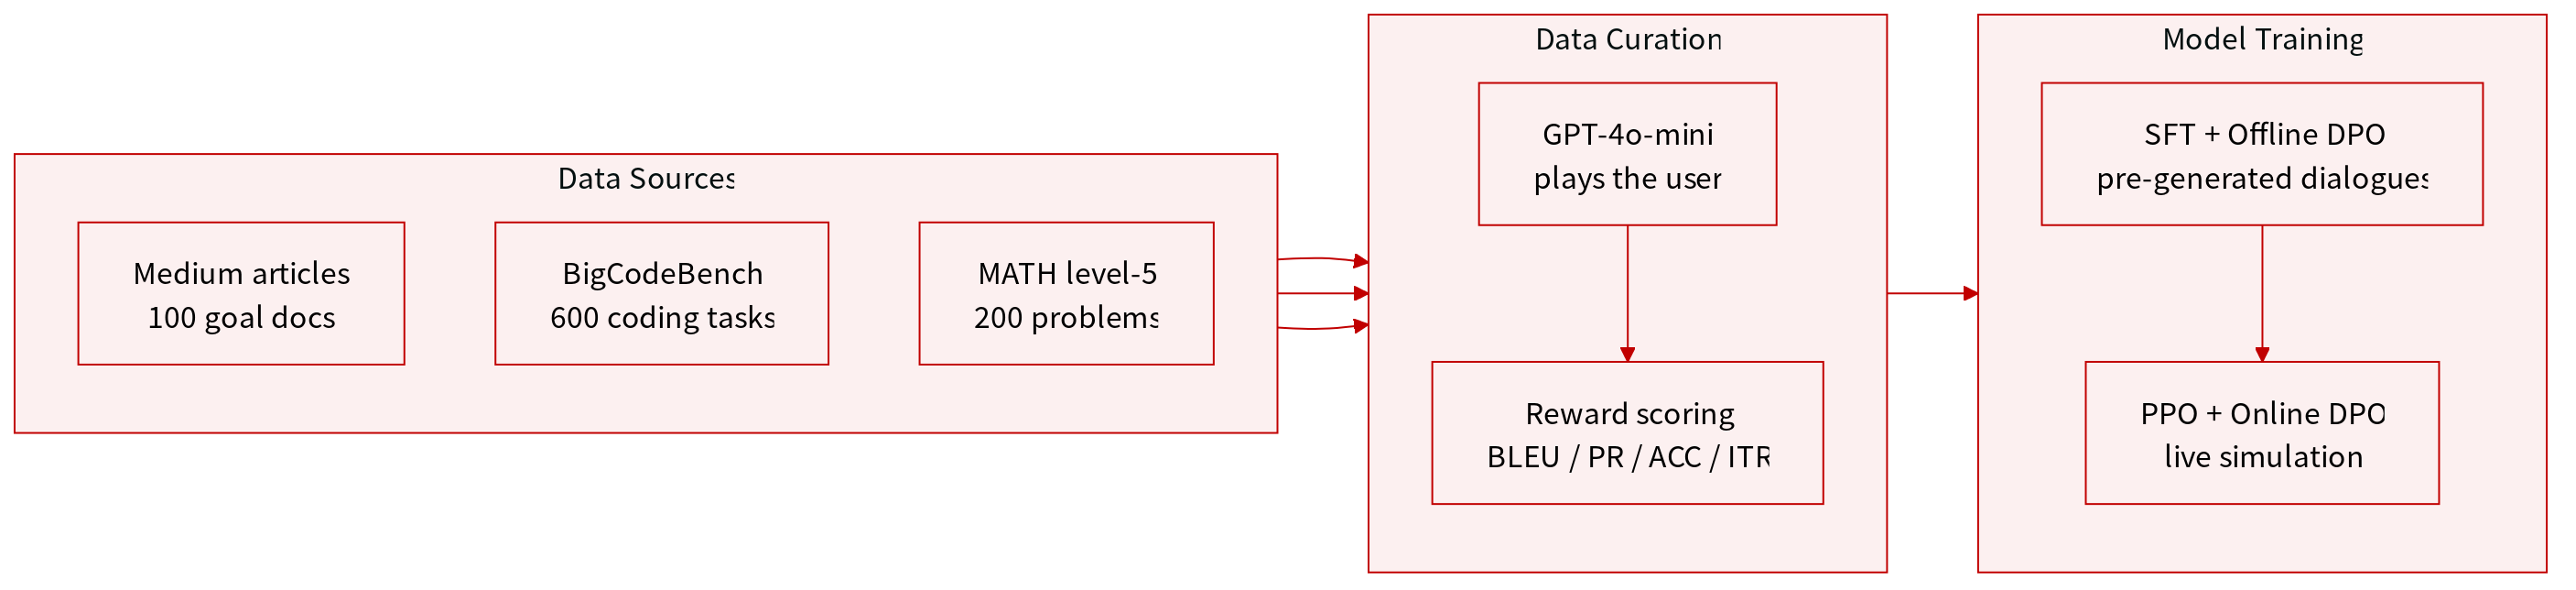
The authors construct three multiturn datasets for fine-tuning and evaluation, using large language models to simulate realistic user behavior. All datasets are designed for dynamic, goal-oriented interactions rather than a single prompt-response exchange.
- Multiturn Environment: To create this environment, the authors use GPT-4o-mini as a user simulator LLM. The simulator role-plays realistic user behaviors based on the target problem and conversation history, enabling interactions that closely mimic real-world scenarios.
- Subset Composition:
- MediumDocEdit-Chat: Includes 100 sampled Medium articles as goal documents. These articles are summarized into target problems to guide the user simulator. Task performance is measured using the BLEU score, comparing the extracted document to the original article.
- BigCodeBench-Chat: Includes 600 coding problems sampled from BigCodeBench, provided directly as target problems. Task success is measured by the average Pass Rate (PR) of the code at the end of the interaction.
- MATH-Chat: Includes 200 level-5 math problems from the MATH dataset, used to prompt the user simulator. The accuracy (ACC) of the final solution, judged by an LLM, determines task success.
- Common Evaluation Metrics: Beyond task-specific metrics, all datasets use two task-agnostic scores. Average Token Count measures the number of tokens generated per conversation to reflect efficiency. Interactivity (ITR) measures user engagement, scored by an LLM judge and rescaled to a maximum of 1.
- Usage in Fine-tuning: The authors fine-tune LLMs based on Llama-3.1-8B using LoRA. They train four model variants:
- Offline Models: Trained via SFT and Offline DPO on pre-generated conversational datasets, which are guided by Multiturn-aware Rewards (MR).
- Online Models: Trained via PPO and Online DPO, starting from the SFT and Offline DPO models. During this stage, the model participates in the simulation to compute MRs, allowing its preferences to be dynamically adjusted.
- Baselines: The authors compare their models against the pretrained Llama-3.1-8B base model and a "Proactive Base" variant, which uses prompt engineering to encourage follow-up and clarification questions.
Method
The authors introduce a unified collaborative LLM training framework designed to optimize for long-term conversational goals rather than immediate single-turn rewards. Refer to the framework diagram.
The core of this approach is the Multiturn-aware Reward (MR), which evaluates a model response by estimating its impact on the entire conversation trajectory. Formally, the MR for a response mj at turn j, given the conversation history tjh and goal g, is defined as:
MR(mj∣tjh,g)=Etjf∼P(tj+1:K∣tjh∪{mj})R∗(tjh∪{mj}∪tjf∣g)where tjf represents the forward trajectory of turns following the current turn, and R∗ is a conversation-level reward function. To compute this expectation, the framework employs a collaborative simulation module that forward-samples potential future conversations. This sampling is facilitated by a user simulator U, which generates probabilistic user responses conditioned on the conversation history, effectively emulating realistic user behavior and evolving needs. To maintain computational efficiency, the simulation is constrained by a window size w, limiting the number of forward turns considered.
The conversation-level reward function R∗ is approximated as a combination of extrinsic and intrinsic metrics:
R∗(t∣g)≃Rext(t,g)+Rint(t)The extrinsic reward Rext(t,g) measures task success by comparing the extracted final solution from the conversation against a reference solution yg. The intrinsic reward Rint(t) prioritizes user experience, defined as:
Rint(t)=−min[λ⋅TokenCount(t),1]+RLLM(t)This formulation penalizes excessive token usage to encourage efficiency, while an LLM-based judge evaluates engagement and interactivity.
By optimizing for higher MR scores, the model learns to generate responses that enhance overall effectiveness and efficiency. The framework supports reinforcement learning methods such as PPO and DPO for online finetuning. Additionally, the MR metric facilitates the generation of high-quality synthetic datasets. For supervised fine-tuning, the system iteratively selects top-ranked responses to build realistic conversation histories. For direct preference optimization, it constructs pairwise comparisons by ranking responses at each turn, distinguishing chosen and rejected pairs based on their MR scores.
Experiment
The experiments evaluate COLLABLLM, fine-tuned from Llama-3.1-8B with multiturn-aware rewards, using simulated multiturn environments across document editing, coding, and math tasks, plus a real-world user study with human participants. Results show that prompt engineering alone yields limited gains, while COLLABLLM improves task performance, interaction efficiency, and user engagement by clarifying intent and adapting dynamically to user needs. Ablations confirm that forward sampling in rewards captures long-term conversational impact better than immediate rewards, and a generalization test shows collaborative behaviors transfer to new question-answering domains. Real-world user ratings consistently favor COLLABLLM for document quality, sustained engagement, and reduced task time, though users note room for more personalization and creativity.
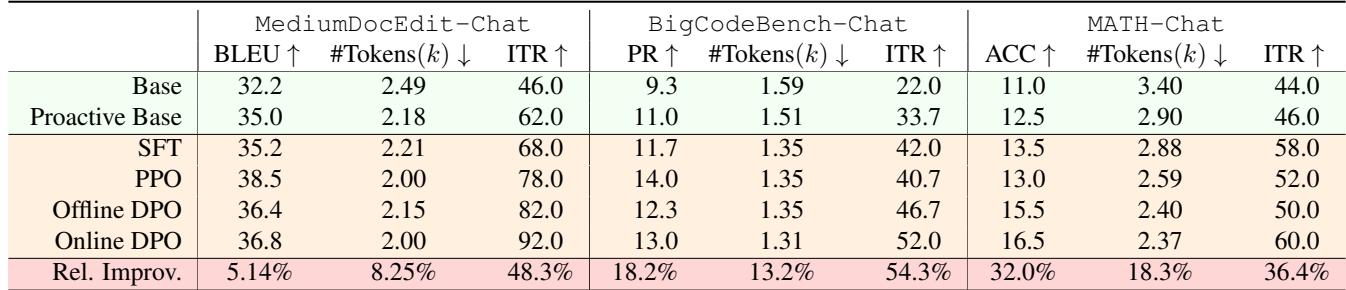
The evaluation shows that prompt engineering yields modest gains, while COLLABLLM variants, especially with Online DPO, significantly improve task performance, efficiency, and interactivity across all multiturn datasets. Online DPO consistently reduces token usage and boosts interaction ratings compared to the base model, though variants like PPO and Offline DPO also show improvements in specific metrics. Proactive Base improves over Base on all datasets, but gains are limited compared to trained COLLABLLM variants. Online DPO achieves the highest interaction ratings on all three datasets, with notable jumps in ITR for MediumDocEdit-Chat and MATH-Chat. COLLABLLM variants reduce conversation tokens relative to Base, with Online DPO showing the largest reductions in token counts. SFT and PPO also outperform Proactive Base on most metrics, but Online DPO tends to offer the best balance of task accuracy and engagement. Prompt engineering remains rigid and can cause unnecessary clarification questions, whereas trained models adapt more dynamically.
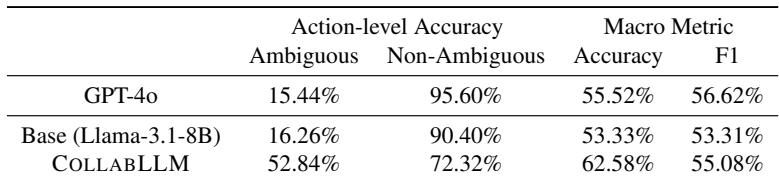
COLLABLLM, trained with online DPO on a coding assistance task, shows strong zero-shot generalization to conversational QA by asking clarifying questions for about half of ambiguous inputs while still answering non-ambiguous ones accurately. It achieves the highest macro accuracy across both input types and improves macro F1 over the base model, though it trails GPT-4o on F1. COLLABLLM asks clarifying questions for a substantially larger share of ambiguous inputs than GPT-4o or the base model, which rarely do so. COLLABLLM maintains high accuracy on non-ambiguous inputs, though slightly lower than the baselines, yielding the best overall macro accuracy. Its macro F1 improves over the base model but remains slightly below GPT-4o, indicating room for further refinement.
In a real-world user study with 201 participants, COLLABLLM consistently outperformed baseline models across document quality, user engagement, and task efficiency. Qualitative feedback highlights COLLABLLM's ability to guide users through interactive refinement, while baselines often exhibit issues like excessive agreement or repetitive questioning. COLLABLLM receives higher document quality ratings and a greater share of 'very good' scores compared to the Base model. User engagement with the Base model declines over longer conversations, whereas COLLABLLM sustains and increases engagement across turns. COLLABLLM reduces task completion time relative to both Baseline and Proactive Base, which tends to ask redundant questions. Participants praise COLLABLLM for prompting deeper thinking and helping them focus, but note limitations such as outdated information and repeated requests for already provided details.
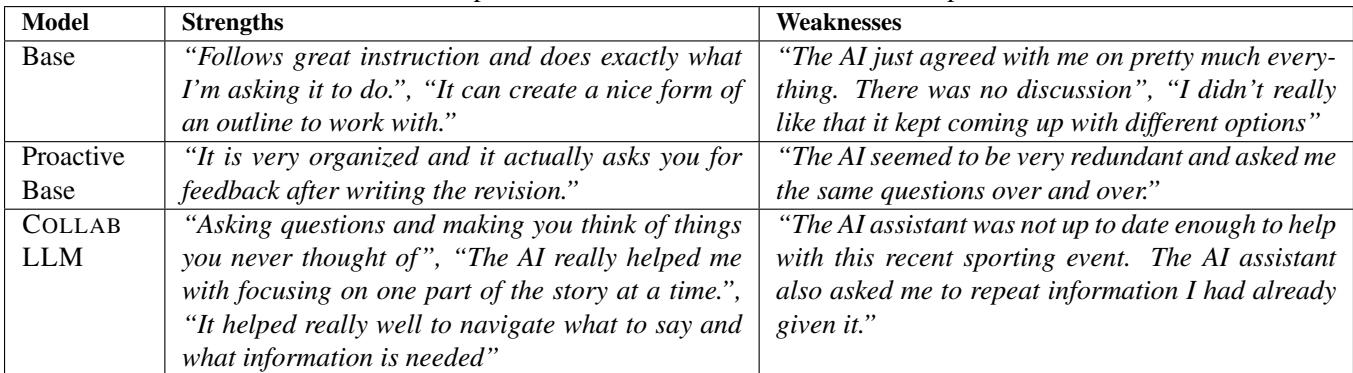
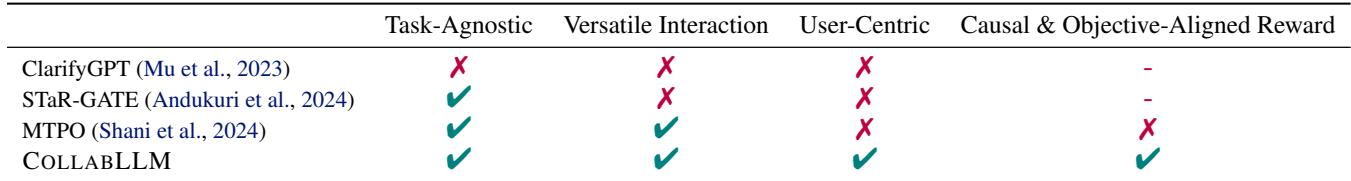
COLLABLLM uniquely satisfies all four evaluation dimensions, including causal and objective-aligned reward estimation, whereas other methods miss at least one. In user studies, COLLABLLM consistently outperforms baselines in document quality, engagement, and efficiency, and it maintains increasing user satisfaction over longer conversations while baselines decline. COLLABLLM is the only method that is task-agnostic, versatile in interaction, user-centric, and uses causal and objective-aligned rewards. COLLABLLM receives higher document quality and engagement ratings compared to the base and proactive baselines. COLLABLLM sustains or increases user ratings across interaction turns, whereas the base model shows declining ratings in longer sessions. COLLABLLM reduces interaction time by over 10% relative to the base model and even more compared to a proactive baseline that asks unnecessary questions.
The evaluation spans multiturn interactive datasets, a zero-shot conversational QA task, and a user study with 201 participants. Findings show that prompt engineering yields modest gains, while COLLABLLM variants, particularly with Online DPO, significantly improve task performance, efficiency, and interactivity, reducing token usage and boosting interaction ratings. COLLABLLM also demonstrates strong zero-shot generalization by asking clarifying questions for ambiguous inputs while maintaining high accuracy on non-ambiguous ones. In the user study, COLLABLLM consistently outperforms baselines in document quality, engagement, and efficiency, sustaining user satisfaction over longer conversations and reducing task completion time.