Command Palette
Search for a command to run...
ألفاإديت: تحرير المعرفة المقيّد بفراغ الصفر للنماذج اللغوية
ألفاإديت: تحرير المعرفة المقيّد بفراغ الصفر للنماذج اللغوية
Junfeng Fang Houcheng Jiang Kun Wang Yunshan Ma Jie Shi Xiang Wang Xiangnan He Tat-Seng Chua
الملخص
غالبًا ما تُظهر النماذج اللغوية الكبيرة هلوسات، فتُنتج معرفة غير صحيحة أو قديمة. ومن ثم، ظهرت طرق تحرير النماذج لتمكين تحديثات المعرفة المستهدفة. ولتحقيق ذلك، يُعدّ نهج «التحديد ثم التحرير» من النهج السائدة، إذ يحدّد أولًا المعلمات المؤثرة ثم يحرّرها عبر إدخال اضطراب. وعلى الرغم من فعالية هذا النهج، أثبتت الدراسات الحالية أن هذا الاضطراب يُعطّل حتمًا المعرفة المحفوظة أصلًا داخل النماذج اللغوية الكبيرة، لا سيما في سيناريوهات التحرير التسلسلي. ولمعالجة هذه المشكلة، نقدّم ألفاإديت، وهو حلّ جديد يُسقِط الاضطراب على فراغ الصفر الخاص بالمعرفة المحفوظة قبل تطبيقه على المعلمات. ونُثبت نظريًا أن هذا الإسقاط يضمن بقاء مخرجات النماذج اللغوية الكبيرة بعد التحرير دون تغيير عند الاستعلام عن المعرفة المحفوظة، مما يُخفّف من مشكلة التعطيل. تُظهر تجارب مكثّفة على نماذج لغوية كبيرة متعددة، تشمل LLaMA3 وGPT2-XL وGPT-J، أن ألفاإديت يعزّز أداء معظم طرق التحديد ثم التحرير بمتوسط 36.7% بسطر شيفرة إضافي واحد مخصّص للإسقاط فقط. الشيفرة المصدرية متاحة على الرابط: https://github.com/jianghoucheng/AlphaEdit.
One-sentence Summary
Researchers from the University of Science and Technology of China and the National University of Singapore propose AlphaEdit, a method that projects parameter perturbations into the null space of preserved knowledge to prevent disruption during sequential LLM editing, theoretically guaranteeing unchanged outputs for preserved queries and boosting existing locating-then-editing methods by an average of 36.7%.
Key Contributions
- The paper introduces AlphaEdit, which projects parameter perturbations into the null space of preserved-knowledge key matrices before applying them to large language models, enabling targeted knowledge updates while reducing disruption to existing knowledge.
- The method provides a theoretical formulation showing that this null-space projection keeps outputs unchanged for queries about preserved knowledge while still permitting updates to edited knowledge, and the projection can be added with a single line of code.
- Experiments on LLaMA3, GPT2-XL, and GPT-J show that AlphaEdit improves most locating-then-editing methods by an average of 36.7%, demonstrating a practical gain in editing performance with preserved knowledge.
Introduction
Large language models can store and recall extensive knowledge, but they often produce stale or incorrect facts, and full fine-tuning is frequently too costly for resource-limited settings. Model-editing methods address this by updating specific stored knowledge with minimal changes, especially through parameter-modifying locate-then-edit approaches that adjust feed-forward layer weights. A key limitation is that prior methods struggle to balance updating target knowledge and preserving existing knowledge: aggressively minimizing update error can shift hidden representations, overfit to the new fact, and cause forgetting or model collapse during sequential edits. The authors introduce AlphaEdit, which removes the preserved-knowledge loss from the objective and projects the parameter update into the null space of preserved key matrices. This preserves the model’s hidden representation distribution while updating facts, and works as a simple plug-and-play enhancement that improved existing editing methods by an average of 36.7 percent.
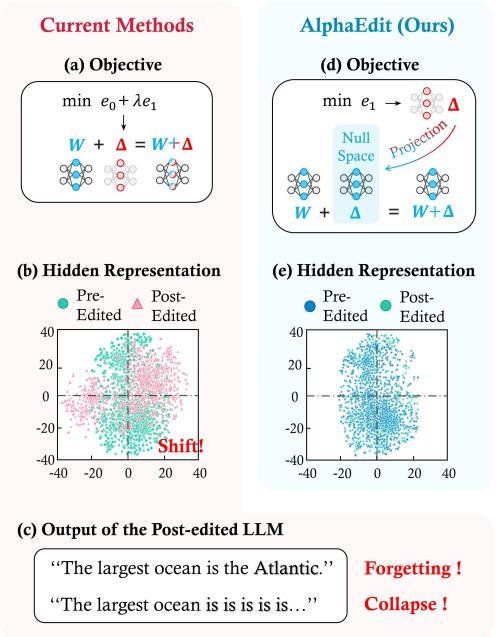
Method
The authors present AlphaEdit as a projection-based model editing method. Its central idea is to constrain a parameter update to a subspace that is inactive on preserved knowledge, rather than balancing knowledge updating and knowledge preservation through separate loss terms. Let W denote the selected weight matrix to be edited, let (K0,V0) denote preserved key-value associations, and let (K1,V1) denote the current knowledge that should be updated.
The method begins with the definition of a left null space. A matrix B lies in the left null space of A if and only if
BA=0.If an additive perturbation Δ′ satisfies Δ′K0=0, then applying it to the original parameters gives
(W+Δ′)K0=WK0+Δ′K0=WK0=V0.Thus, the projected perturbation does not change the output associated with preserved knowledge. AlphaEdit therefore first constructs a projection matrix that maps candidate perturbations into the null space of the preserved knowledge before they are applied to the model.
Direct projection into the null space of K0 is expensive because K0 can have a very large number of columns. The authors instead use the null space of the covariance matrix K0K0T∈Rd0×d0, since this smaller matrix shares the same null space as K0 while being much cheaper to handle when d0 is much smaller than the number of preserved samples. They compute
{U,Λ,UT}=SVD(K0K0T),where the columns of U are eigenvectors of K0K0T. The eigenvectors corresponding to nonzero eigenvalues are removed, and the remaining submatrix U^ is used to define the projection matrix
P=U^U^T.This matrix maps the column vectors of a perturbation into the null space of K0. As a result, for a projected perturbation ΔP, the update preserves the original key-value association:
(W+ΔP)K0=WK0=V0.With this projection available, the authors modify the usual model editing objective. Instead of minimizing both the error on the knowledge being updated and the error on preserved knowledge, they replace the raw perturbation Δ~ with the projected perturbation Δ~P. Because the projection already guarantees preservation of K0, the explicit preservation term can be removed. They also add a regularization term ∥Δ~P∥2 to stabilize the solution, yielding
Δ=Δ~argmin(∥(W+Δ~P)K1−V1∥2+∥Δ~P∥2).For sequential editing, the method additionally protects knowledge that has already been updated by previous edits. Let (Kp,Vp) denote the previously updated key-value associations. The corresponding protection term is
∥(W+Δ~P)Kp−Vp∥2.Because previous edits have already made WKp=Vp, this term reduces to
∥Δ~PKp∥2.Therefore, the sequential editing objective becomes
Δ=Δ~argmin(∥(W+Δ~P)K1−V1∥2+∥Δ~P∥2+∥Δ~PKp∥2).The authors define the current edit residual as
R=V1−WK1.By solving the corresponding normal equation, they obtain a closed-form projected perturbation:
ΔAlphaEdit=RK1TP(KpKpTP+K1K1TP+I)−1.This update is designed to incorporate the current knowledge into the model while keeping both preserved knowledge and previously updated knowledge stable. The key difference from common closed-form editing solutions such as MEMIT is the insertion of the projection matrix P into the update pathway. For comparison, a standard unprojected solution has the form
ΔMEMIT=RK1T(KpKpT+K1K1T+K0K0T)−1.The AlphaEdit variant replaces the explicit preservation term with the projected null-space constraint. Refer to the framework diagram.
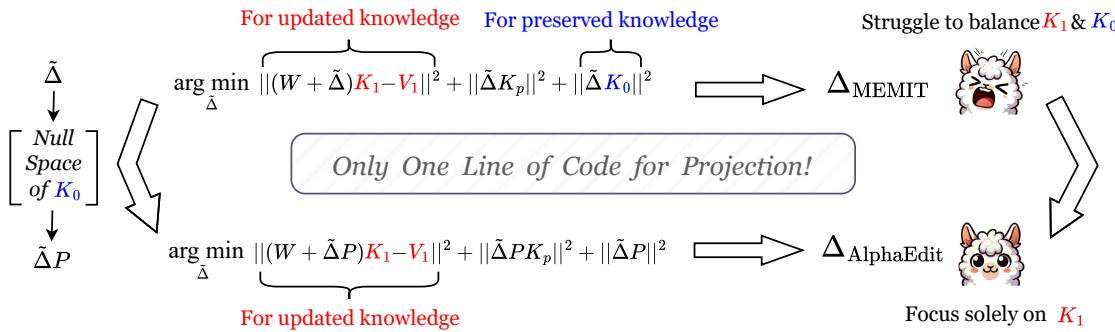
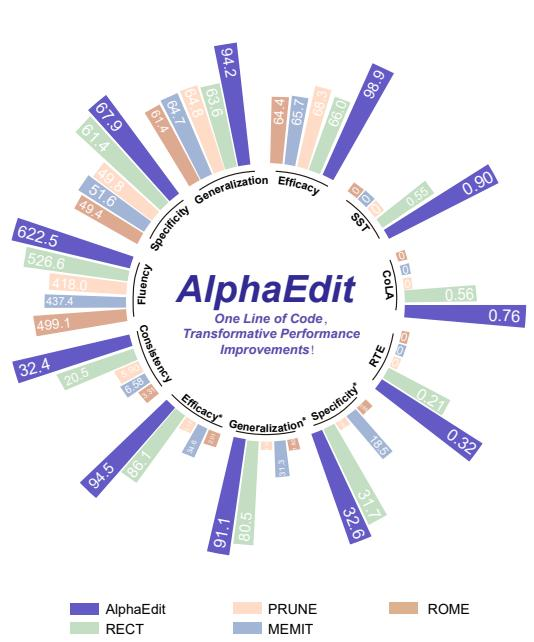
The projection matrix P depends only on preserved knowledge and not on the specific update being performed. Therefore, it can be computed once and reused across many editing operations. This makes the additional computational overhead small relative to existing editing pipelines. As shown in the figure below, this simple projection-oriented modification can lead to stronger editing performance while maintaining general capabilities in the evaluated settings.
Experiment
Experiments evaluate AlphaEdit on sequential knowledge editing, general capability retention, and hidden representation stability across multiple LLMs and editing baselines. Results show that AlphaEdit better balances knowledge update with knowledge preservation and fluency, while baseline methods often degrade general abilities and distort internal representations. The projection strategy also improves existing editing methods, indicating broad applicability and effectiveness.
AlphaEdit delivers the strongest overall results on sequential knowledge editing across multiple base models, with especially large gains in updating effectiveness and generalization. It also preserves generation quality better than existing approaches, improving fluency and consistency while avoiding the severe degradation seen in several baselines. These patterns suggest that better balancing knowledge updates with preservation is central to its advantage. AlphaEdit outperforms baselines across nearly all measured editing metrics and base models The method narrows the trade-off between editing effectiveness and generalization, with especially strong gains on LLaMA3 Several baselines lose generalization or consistency dramatically during sequential editing, while AlphaEdit maintains stronger overall retention
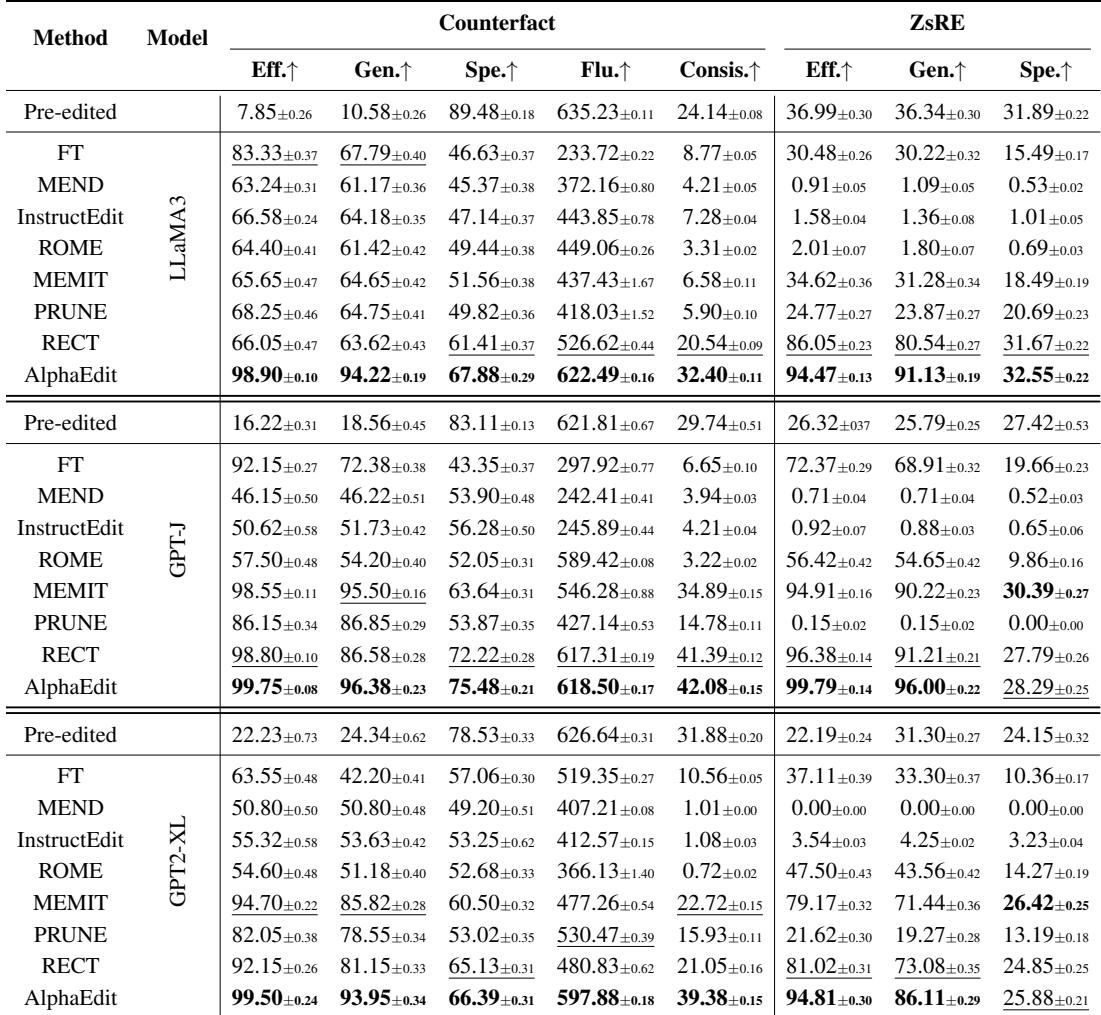
Experiments evaluate sequential knowledge editing across multiple base models and show that AlphaEdit achieves the strongest overall performance by improving update effectiveness and generalization while preserving generation quality. Compared with baselines, it better balances knowledge updates and preservation, with especially strong gains on LLaMA3. The results indicate that maintaining fluency and consistency is central to its advantage, whereas several baselines degrade sharply during sequential editing.