Command Palette
Search for a command to run...
تعلُّم محاكيات العالم الحقيقي التفاعلية
تعلُّم محاكيات العالم الحقيقي التفاعلية
Sherry Yang Yilun Du Kamyar Ghasemipour Jonathan Tompson Leslie Kaelbling Dale Schuurmans Pieter Abbeel
الملخص
لقد أحدثت النماذج التوليدية المُدرَّبة على بيانات الإنترنت ثورةً في طرق إنشاء المحتوى النصي والمرئي والفيديو. وربما تكون المحطة التالية للنماذج التوليدية هي محاكاة تجارب واقعية استجابةً للإجراءات التي يتخذها البشر والروبوتات والوكلاء التفاعليون الآخرون. تتنوع تطبيقات محاكيات العالم الحقيقي بين إنشاء محتوى قابل للتحكم في الألعاب والأفلام، إلى تدريب وكلاء مجسَّدين بالكامل داخل المحاكاة بحيث يمكن نشرهم مباشرةً في العالم الحقيقي. نستكشف إمكانية تعلُّم محاكٍ شامل (UniSim) للتفاعل مع العالم الحقيقي من خلال النمذجة التوليدية. نبدأ بملاحظة مهمة مفادها أن مجموعات البيانات الطبيعية المتاحة لتعلُّم محاكٍ للعالم الحقيقي غالبًا ما تكون غنيةً بأبعاد مختلفة (كالوفرة الكبيرة للأجسام في بيانات الصور، وكثافة عيّنات الإجراءات في بيانات الروبوتات، وتنوّع الحركات في بيانات الملاحة). من خلال التنسيق الدقيق بين مجموعات بيانات متنوعة، كلٌّ منها يوفر جانبًا مختلفًا من التجربة الشاملة، يمكننا محاكاة الناتج المرئي لكلٍّ من التعليمات عالية المستوى مثل «افتح الدرج» وضوابط المستوى المنخفض مثل «التحرّك بمقدار ∆x، ∆y» من مشاهد وأجسام ثابتة في الأصل. نستخدم المحاكي لتدريب كلٍّ من سياسات الرؤية-اللغة عالية المستوى وسياسات التعلُّم المعزَّز منخفضة المستوى، وكلٌّ منها قابل للنشر في العالم الحقيقي بتقنية اللقطة الصفرية (zero-shot) بعد التدريب المحض داخل المحاكاة. نُظهر أيضًا أن أنواعًا أخرى من الذكاء، مثل نماذج وصف الفيديو، يمكن أن تستفيد من التدريب بالتجربة المحاكاة، مما يفتح آفاقًا لتطبيقات أوسع. يمكن العثور على عروض الفيديو على الرابط: https://universal-simulator.github.io.
One-sentence Summary
Researchers at UC Berkeley, Google DeepMind, MIT, and the University of Alberta propose UniSim, a universal real-world simulator learned through generative modeling that orchestrates datasets rich in complementary dimensions to simulate visual outcomes of both high-level instructions and low-level controls such as Δx,Δy, enabling zero-shot real-world deployment of policies trained purely in simulation.
Key Contributions
-
UniSim is a generative real-world interaction simulator that combines datasets rich in objects, robot actions, and navigation movements to synthesize visual outcomes for high-level instructions such as “open the drawer” and low-level controls such as “move by ∆x, ∆y.” It formulates controllable video generation as dynamics modeling.
-
The simulator responds to inputs ranging from text instructions to robot control commands, creating visually realistic experiences from otherwise static scenes and objects. This provides realistic and unlimited environment access for training interactive agents.
-
High-level vision-language policies and low-level reinforcement learning policies trained purely in simulation can be deployed zero-shot in the real world, and video captioning models also improve when trained with simulated experience. These findings bridge the sim-to-real gap for policy learning and related models.
Introduction
Generative models can now produce highly realistic text, images, and video, motivating a broader goal: using them as visual simulators of the real world. Such simulators could let humans interact with synthetic scenes, enable robots to learn without physical risk, and generate large amounts of realistic training data for other intelligent systems. Prior work faced a data and modeling challenge because existing datasets capture different parts of reality, such as scenes, language, human activity, or robot motion, while previous world models and video generators were often limited to narrow domains, low levels of control, or simplified environments. The authors address this by building UniSim, a universal simulator that combines diverse datasets through an action-in-video-out framework, using a video diffusion model to predict future observations and roll them out autoregressively for long-horizon interaction. They demonstrate that both high-level vision-language policies and low-level control policies can be trained purely in simulation and transferred to real robots, helping narrow the sim-to-real gap in embodied learning.
Dataset
-
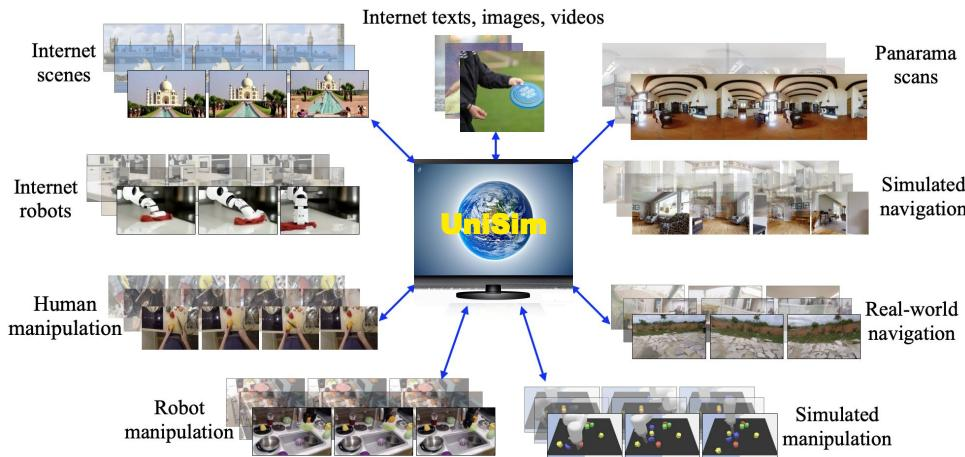
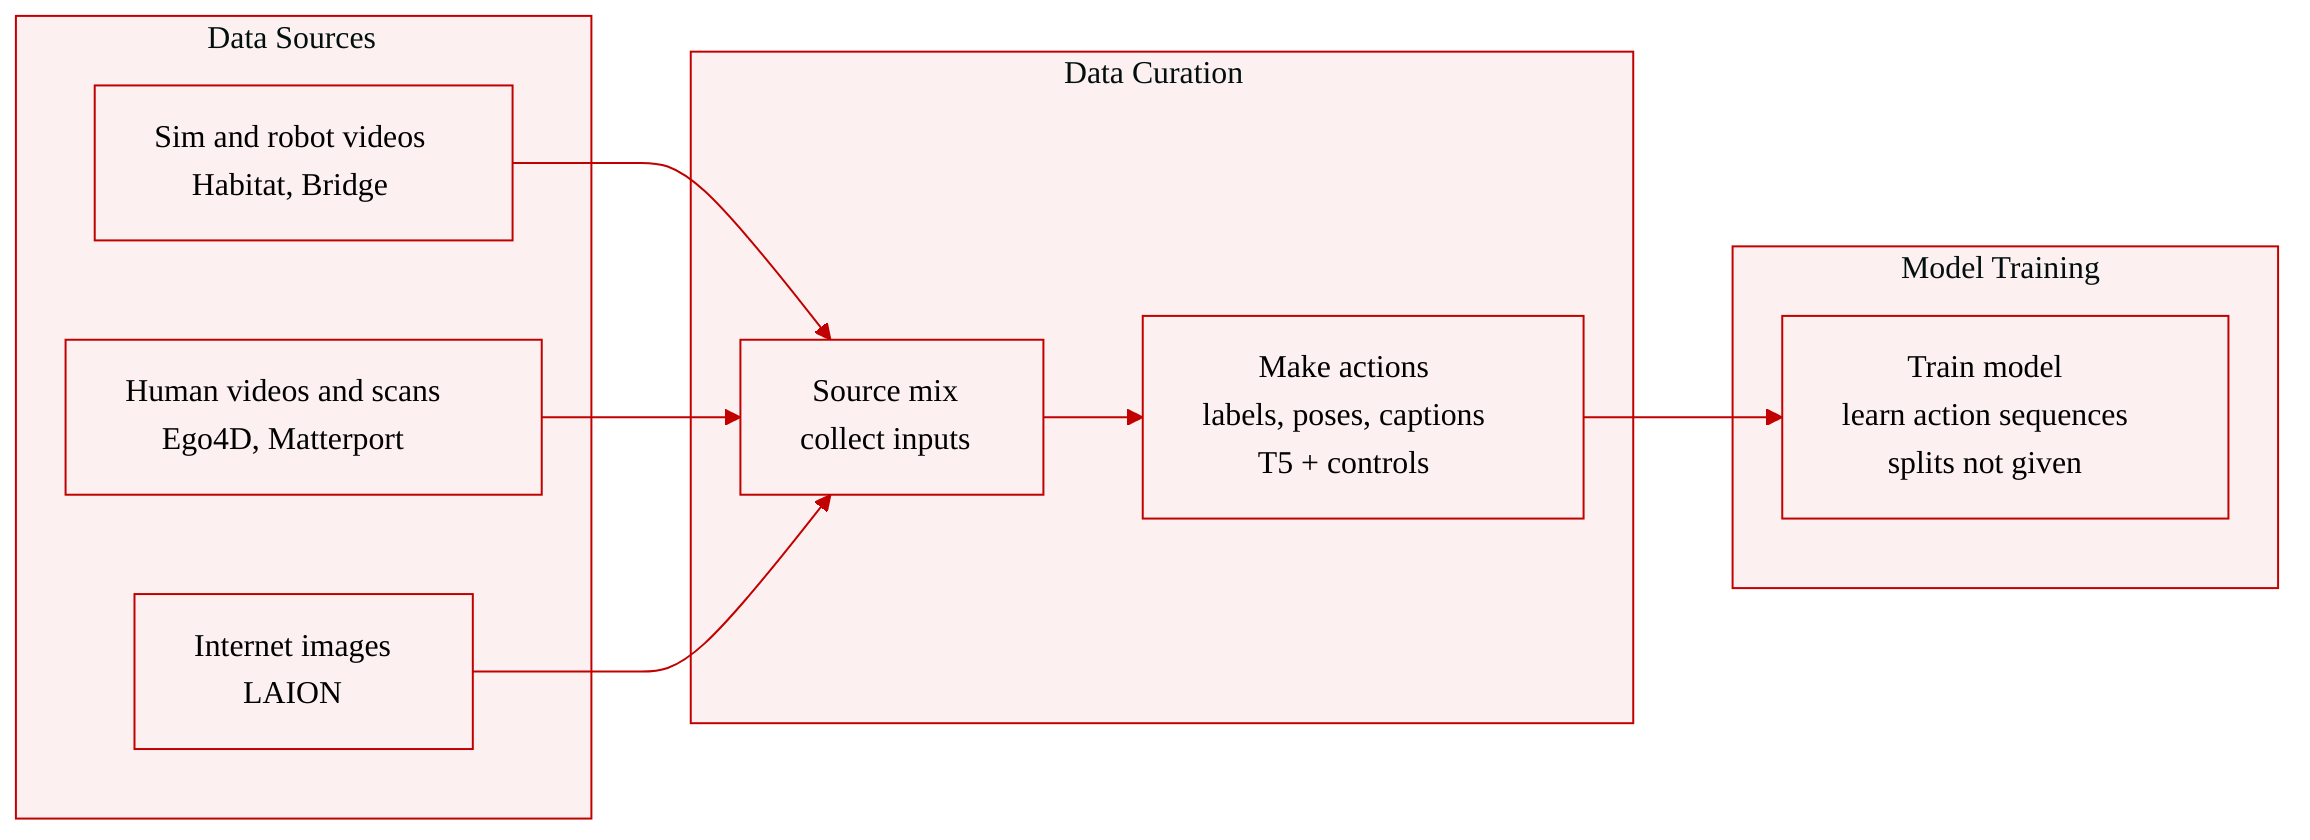
The authors assemble a diverse simulator training corpus by converting five kinds of video, scan, and image data into a common format of observation sequences with actions.
-
Simulated execution and renderings: They use simulator-generated data from Habitat object navigation with HM3D and Language Table Data. When available, text descriptions are extracted as actions. For continuous control actions, they encode control values through language embeddings and concatenate them with discretized control values.
-
Real robot data: They include real robot execution videos paired with task descriptions, such as Bridge Data and data used to enable RT-1 and RT-2. Task descriptions are treated as high-level actions, and discretized continuous control actions are added when available.
-
Human activity videos: They use large human activity datasets, including Ego4D, EPIC-KITCHENS, and Something-Something V2. Video labels are converted into text actions, and videos are subsampled into chunks of observations at a frame rate that captures meaningful actions.
-
Panorama scans: They use static 3D scan data such as Matterport3D, which originally lacks actions. Actions are constructed by truncating panorama scans and using camera pose differences between images, for example as turn actions.
-
Internet text-image data: They use paired text-image datasets such as LAION. Static images are treated as single-frame videos, and image captions are used as actions, especially when captions contain motion cues.
-
Unified action processing: For every subset, text tokens are converted into continuous representations using T5 language model embeddings. These embeddings are concatenated with low-level action information, such as robot control values, to form the unified action space used for training the simulator.
-
The provided section does not specify dataset sizes, train/validation/test splits, mixture ratios, or explicit filtering thresholds.
Method
The authors define an interactive real world simulator as a model that maps an action and recent visual history to a future visual segment. They formalize this process with an observation space O and an action space A. At an interactive step t, an agent observes a set of history frames ht−1∈O, selects a temporally extended action at−1∈A, and the simulator predicts the next set of video frames ot∈O. The core predictive problem is therefore to learn a model
p(ot∣ht−1,at−1).To support long horizon interaction, the authors generate future observations autoregressively by repeatedly sampling from this model and using the newly predicted frames as history for the next prediction. They simplify modeling by conditioning on a finite set of recent frames rather than attempting to maintain a recurrent state over the entire past.
A central design choice is to convert heterogeneous training sources into a common video prediction problem. Simulated environments contribute rendered videos together with text descriptions or low level control sequences. Robot execution datasets contribute visual videos paired with high level task descriptions and, when available, discretized control signals. Human activity datasets are processed by converting activity labels into text actions and by subsampling videos into chunks that capture meaningful motion. Static 3D panorama scans are converted into videos by cropping views and deriving camera motion actions from pose changes. Paired text image data are treated as single frame videos, with image captions serving as actions. Text inputs are embedded through a language model and concatenated with low level action representations, such as discretized robot commands or camera motion tokens. This produces a unified continuous action interface for all datasets.
As shown in the framework diagram:
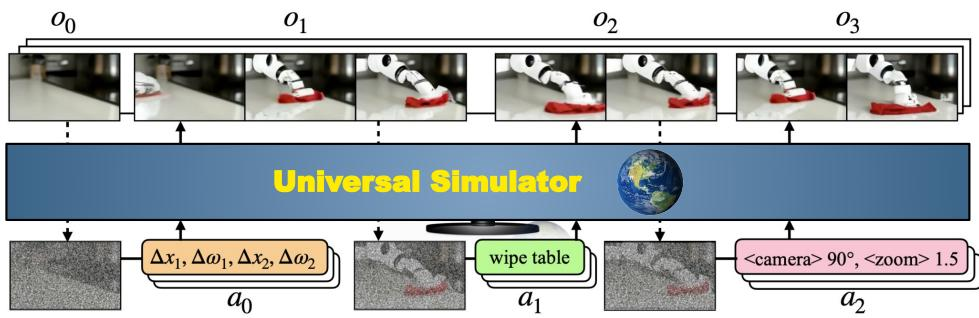
The unified simulator is parametrized as a video diffusion model. The reverse process learns a denoising model ϵθ(ot(k),k∣ht−1,at−1) that generates the next observation segment from initial noise ot(K)∼N(0,I) over K denoising steps. In practice, the model conditions on previous video frames only, while previous actions are omitted from the history. The conditioning frames are replicated at future frame indices and concatenated channelwise with the noisy video frames that are being denoised. Action conditioning is implemented through classifier free guidance. The guided denoising direction combines a conditional denoiser and an unconditional denoiser as
ϵ~θ(ot(k),k∣ht−1,at−1)=(1+η)ϵθ(ot(k),k∣ht−1,at−1)−ηϵθ(ot(k),k∣ht−1),where η controls the strength of action conditioning.
Training optimizes a standard denoising regression objective. Given clean target frames ot, noise ϵ∼N(0,I), and a noise level indexed by k, the loss is
LMSE=ϵ−ϵθ(1−β(k)ot+β(k)ϵ,k∣ht−1,at−1)2.Here β(k) is the noise schedule for diffusion step k. At inference, starting from ot(K)∼N(0,I), the model iteratively denoises from k=K to k=0 according to
ot(k−1)=α(k)(ot(k)−γ(k)ϵθ(ot(k),k∣ht−1,at−1))+ξ,ξ∼N(0,σk2I),where γ(k) is the denoising step size, α(k) is a decay term on the current denoised sample, and σk is a time varying noise level.
The architecture is a video U-Net with interleaved temporal and spatial attention and convolution layers in both downsampling and upsampling passes. This design allows the model to capture motion over time within a video segment while preserving detailed spatial structure in each frame. The implemented model has 5.6B parameters and is trained jointly across the unified action conditioned video data, allowing information from simulated environments, robot platforms, human activity videos, panorama scans, and image caption datasets to contribute to the same simulator.
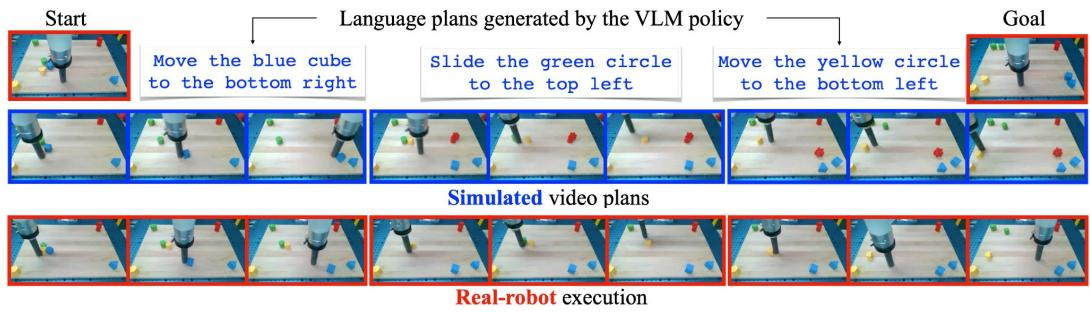
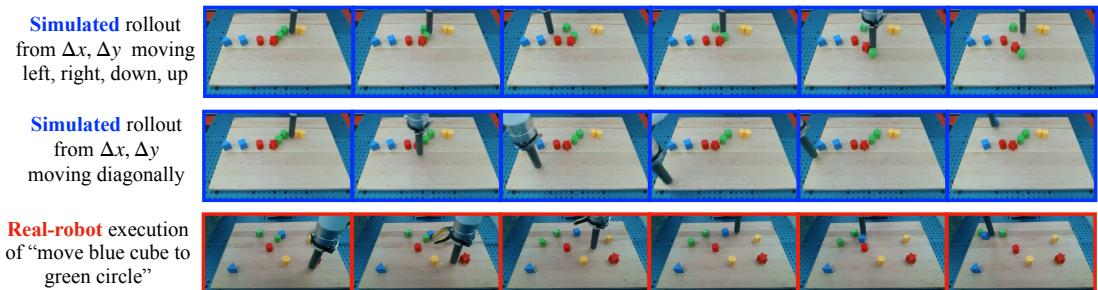
The authors use the simulator not only as a generative model but also as a training environment for policies. For long horizon vision-language-policy learning, they generate simulated trajectories by executing scripted language actions in UniSim and then apply hindsight relabeling. The final frame of each generated rollout becomes a goal image, while the sequence of scripted language instructions used to produce that rollout serves as supervised target actions for the policy. This produces long horizon training data that would otherwise require expensive real robot or long video collection. The simulator is used to predict visual consequences of language actions, and the resulting visual plans can be aligned with real robot execution for evaluation.
As shown in the figure below:
For reinforcement learning, the authors train a vision-language-action policy that maps an image observation and a natural language task description to low level control actions, such as endpoint movements in Δx and Δy. Because UniSim can accept low level control actions as input, the trained policy can perform model-based rollouts inside the simulator. A separate learned reward model maps the current simulated observation to a scalar reward, using proxies such as estimated steps-to-completion from training data. The policy is then optimized with REINFORCE, treating simulated rollouts as if they were real environment rollouts and using the learned reward model to provide feedback. This enables policy improvement without deploying exploration directly on the real robot.
As shown in the figure below:
Experiment
The experiments evaluate the simulator as a general environment for real-world manipulation and navigation, showing that it can generate action-rich, language-driven interactions, preserve state over long sequences, and capture diverse stochastic transitions while ablations indicate that moderate history conditioning and careful low-data handling improve simulation quality. The simulations are then used to support downstream learning, demonstrating that hindsight-generated trajectories can train long-horizon vision-language policies that transfer to real-robot execution and that simulator-based rollouts can reinforce visual control policies for zero-shot real-world task completion. The results also show broader value as synthetic data, where generated videos significantly improve vision-language captioning performance and cross-task transfer.
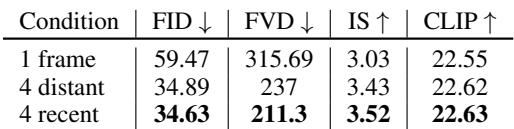
On Ego4D, conditioning on multiple past frames improves video generation quality compared with conditioning on only one frame. Four recent frames perform best overall, giving better FVD, FID, and Inception score than a single frame or distant history. Conditioning on more than four frames does not further improve performance on this dataset. Multiple-frame history conditioning improves quality over single-frame conditioning. Recent history is more effective than distant history, especially for video realism. CLIP alignment is only slightly affected by the choice of history conditioning.
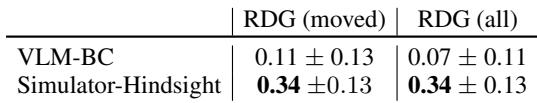
Training the VLM policy on simulated long-horizon data through hindsight relabeling leads to stronger long-horizon block rearrangement than training on the original short-horizon data. The simulator-trained policy shows a larger reduction in distance to goal for both the moved blocks and all blocks across evaluation runs. Simulator-based hindsight training improves goal progress over the short-horizon baseline. The improvement is seen for both moved-block and all-block reductions in distance to goal.
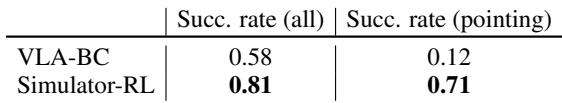
Simulator-based reinforcement learning improves the success rate of a vision-language-action policy over a behavioral cloning baseline across simulated tasks. The improvement is especially large on pointing-based tasks that have limited expert demonstrations. The simulator-trained policy also transfers zero-shot to real-robot executions in the reported deployment. RL finetuning in the simulator yields substantially better rollout success than the baseline policy Performance improves most markedly on pointing-based tasks with limited expert demonstrations The simulator-trained policy generalizes to zero-shot real-robot executions
Finetuning a pretrained vision-language model on videos generated by UniSim markedly improves video captioning performance on ActivityNet compared with no finetuning, while reaching most of the performance achieved with finetuning on real ActivityNet data. The simulated-data model also generalizes better to other captioning benchmarks than the model finetuned on true ActivityNet captions, which tends to specialize more to ActivityNet. Simulated training data provides a large captioning improvement over no finetuning. Simulated-data finetuning transfers better across multiple captioning tasks than finetuning on real ActivityNet data. Real-data finetuning can overfit to ActivityNet despite achieving the highest in-domain captioning score.
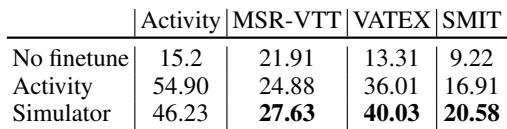
Across Ego4D, simulated manipulation, and video captioning evaluations, the experiments show that conditioning video generation on four recent frames yields the best realism, while simulated data and reinforcement learning enhance policy goal progress, task success, and real-robot transfer. Multi-frame history improves generation quality over single-frame conditioning, simulator-based hindsight training and RL outperform short-horizon or behavioral cloning baselines, and UniSim-generated videos support strong captioning finetuning with broader generalization than real-data finetuning alone.