Command Palette
Search for a command to run...
الأساس الآلي لاعتماد البيانات والتعلّم المفاجئ في مهمة تصنيف ضمن السياق
الأساس الآلي لاعتماد البيانات والتعلّم المفاجئ في مهمة تصنيف ضمن السياق
Gautam Reddy
الملخص
تُظهر نماذج المحول تعلّمًا ضمن السياق: أي القدرة على توقّع استجابة دقيقة لاستعلام جديد استنادًا إلى أمثلة توضيحية موجودة في تسلسل المدخلات. ويتناقض هذا التعلّم ضمن السياق مع التعلّم التقليدي ضمن الأوزان للعلاقات بين الاستعلامات والمخرجات. فما الجوانب في توزيع بيانات التدريب وفي البنية المعمارية التي تُرجّح كفة التعلّم ضمن السياق على التعلّم ضمن الأوزان؟ أظهرت أبحاث حديثة أن خصائص توزيعية محدّدة متأصّلة في اللغة، مثل التندّد، والقواميس الضخمة، والتوزيعات المائلة للرتبة-التكرار، تتحكّم في المقايضة بين هذين الشكلين من التعلّم أو ظهورهما المتزامن. نُبيّن أوّلًا أن هذه النتائج تتكرّر في شبكة اهتمام فقط مدربة على مجموعة بيانات مبسّطة. يتحقّق التعلّم ضمن السياق (ICL) من خلال ظهور مفاجئ لرأس استحثاث، يتنافس بعد ذلك مع التعلّم ضمن الأوزان. ومن خلال تحديد مقاييس التقدّم التي تسبق التعلّم ضمن السياق وتجارب موجّهة، نبني نموذجًا بمعاملين لرأس الاستحثاث يحاكي اعتماديات التوزيع الكامل للبيانات التي تُظهرها الشبكة القائمة على الاهتمام. يُعزى نموذج ظاهري لتكوين رأس الاستحثاث ظهوره المفاجئ إلى التعلّم المتسلسل لثلاثة لوغاريتمات مرجّحة متداخلة يُمكّنها منهج تدريبي باطني. نقترح أنّ الانتقالات الحادّة في الشبكات القائمة على الاهتمام تنشأ بسبب سلسلة محدّدة من عمليات متعددة الطبقات ضرورية لتحقيق التعلّم ضمن السياق، والتي تُنفَّذ عبر لا خطيات متداخلة تُتعلَّم تباعًا أثناء التدريب.
One-sentence Summary
Researchers at Princeton University, NTT Research, and Harvard University reveal the mechanistic basis of in-context learning in attention-only transformers by demonstrating that its abrupt emergence is driven by induction head formation through sequential learning of nested logits enabled by an intrinsic curriculum, and that a minimal two-parameter model recapitulates data distributional effects including burstiness and skewed rank-frequency distributions.
Key Contributions
- The paper reproduces the distributional dependencies that influence the balance between in-context learning and in-weights learning in a minimal attention-only network trained on a simplified dataset, showing that in-context learning is driven by the abrupt emergence of an induction head.
- This work builds a two-parameter model of an induction head and identifies progress measures and targeted experiments that capture how features such as burstiness, large dictionaries, and skewed rank-frequency distributions shape learning dynamics, with the model emulating the broader distributional dependencies of the attention-based network.
- The paper develops a phenomenological model of the loss landscape to explain abrupt in-context learning transitions as the sequential learning of three nested logits enabled by an intrinsic curriculum, offering a mechanistic account of sharp transitions in transformer training.
Introduction
Large language models exhibit in-context learning, where example query-response pairs in the prompt allow the model to answer a new query without weight updates. This matters because it supports zero-shot generalization and often appears abruptly during training, sometimes alongside the formation of induction heads that support simple associative copying. Prior work identified data distribution features that favor in-context learning over in-weights learning, but the mechanistic origin of the abrupt transition and the minimal circuit required remained unclear. The authors leverage a simplified two-layer attention-only setting to show that induction-head formation drives this transition, and they build a minimal model with a loss-landscape analysis to explain the sharp dynamics created by nested nonlinearities.
Method
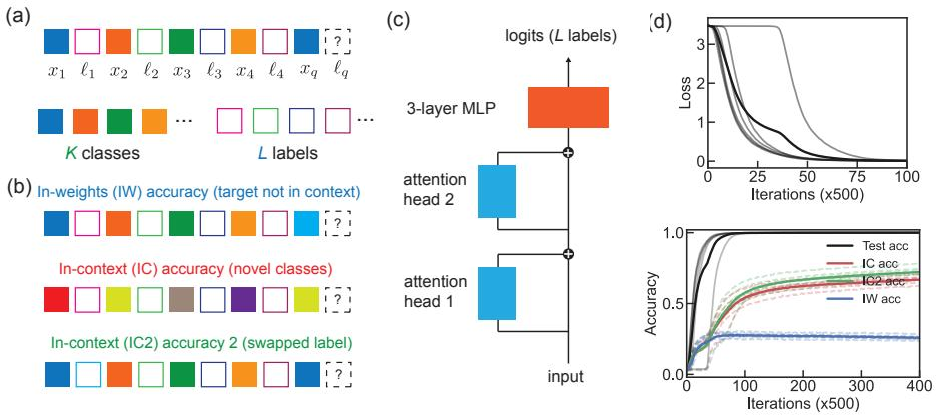
The authors leverage a causal sequence-based framework that trains a transformer-like attention network to predict the label of a target item from an alternating sequence of context items and labels. The network observes a prompt of the form x1,ℓ1,x2,ℓ2,…,xN,ℓN,xq,? and is trained to assign the target xq to one of L labels. The first N labeled pairs provide the in-context signal, while the final unassigned query requires prediction. This setup allows the model to rely either on in-weights learning, where it uses class structure memorized in its parameters, or on in-context learning, where it uses label information explicitly supplied by the prompt. Refer to the framework diagram.
Each item and label is represented in P+D dimensions. The first P dimensions encode position, while the remaining D dimensions encode content. Position is represented by a one-hot vector, and the input sequence is placed in a random window of length 2N+1 within the positional range. This random-window placement encourages translation-invariant computation, reducing reliance on absolute positional cues and making the task more sensitive to local associative structure between items and labels.
The item content is generated from a Gaussian mixture model with K classes. For a class k with mean vector μk, the normalized content vector of item xi is
x~i=1+ε2μk+εη,where η has the same distribution as μk, and ε controls within-class variability. The normalization keeps the average item norm close to one. Classes are assigned to L labels, and label vectors are also drawn from the same content distribution before training. Within a given prompt, each label appears equally often, while the training objective guarantees that at least one context item belongs to the target’s class. Training uses a cross-entropy loss on the final label prediction.
The data distribution can be modulated beyond the number of classes and within-class noise. The main control variables are the class rank-frequency distribution and burstiness. Burstiness specifies how many repeated items from the same class appear in a prompt, and a fraction pB of training sequences follows this bursty structure. This parameterization makes it possible to expose the network to varying degrees of in-context redundancy and class imbalance.
To distinguish in-weights learning from in-context learning, the authors use complementary evaluation protocols. For in-weights learning, the target and context items are sampled independently from the training class distribution, making it unlikely that the target class appears in the prompt. The network must therefore rely on class structure encoded in its weights. For in-context learning, the target and context items belong to novel classes, and only the label associations are available through the prompt. The network must use the in-context label structure rather than memorized class knowledge. A second in-context metric further removes the benefit of label memorization by swapping the labels during evaluation, so the model must follow the label bindings provided in the prompt.
The architecture is a two-layer attention-only encoder followed by a classification head. Each attention layer contains one causal attention head. Given an input sequence u1,u2,…,un, the first attention layer computes
vi=ui+V1j≤i∑pij(1)uj,and the second layer computes
wi=vi+V2j≤i∑pij(2)vj.The attention weights are defined as
pij(μ)=∑k≤iexp((Kμuk)⊤(Qμui))exp((Kμuj)⊤(Qμui)),where Qμ, Kμ, and Vμ are the query, key, and value matrices for layer μ. The final representation wn is passed to a three-layer MLP with ReLU activations and a softmax output over the L labels. The classifier is intentionally deep so that strong in-weights classification remains feasible even when the number of underlying classes is large.
Training uses fixed core parameters unless otherwise varied, including L=32, N=8, D=63, ε=0.1, and a flat class rank-frequency exponent α=0. The attention query-key dimension and MLP hidden dimension are both 128. Each experiment is repeated across multiple random seeds, with training using a batch size of 128 and vanilla stochastic gradient descent at a learning rate of 0.01. The training curves track both in-weights and in-context accuracy, enabling the model’s learning dynamics to be interpreted as a trade-off between memorizing class structure and exploiting label associations in the prompt.
Experiment
Using a simplified transformer trained on synthetic sequences, the experiments systematically vary data distribution properties such as burstiness, class diversity, within class variation, and frequency skew to test when in context learning and in weights learning emerge, compete, or coexist. The results reproduce known distributional trade-offs, show that highly skewed frequencies can promote both forms of learning, and demonstrate that separate mechanisms can be acquired together. Attention dynamics and ablation studies with a minimal induction head model show that an initial slow phase of learning contextual labels prepares the network for an abrupt transition to structured attention and zero shot copying, supporting induction head formation as the core mechanism behind in context learning. A phenomenological loss landscape analysis further explains this abruptness as sequential optimization over nested decision logits and indicates that easier contextual cues can provide an intrinsic curriculum for reliably acquiring the in context solution.