Command Palette
Search for a command to run...
نحو نظرية إحصائية لاختيار البيانات في ظل الإشراف الضعيف
نحو نظرية إحصائية لاختيار البيانات في ظل الإشراف الضعيف
Germain Kolossov Andrea Montanari Pulkit Tandon
الملخص
بفرض توفّر عينة حجمها N، غالبًا ما يكون من المفيد اختيار عينة فرعية أصغر حجمًا n < N تُستخدَم للتقدير الإحصائي أو التعلّم. هذه الخطوة من اختيار البيانات مفيدة لتقليل متطلبات وسم البيانات والتعقيد الحسابي للتعلّم. نفترض توفّر N عينة غير موسومة xii≤N، وإمكانية الوصول إلى «نموذج بديل» قادر على التنبؤ بالتسميات yi بشكل أفضل من التخمين العشوائي. هدفنا هو اختيار مجموعة فرعية من العينات، يُرمز لها بـ xii∈G، بحجم ∣G∣=n<N. ثم نحصل على تسميات لهذه المجموعة ونستخدمها لتدريب نموذج عبر تبسيط المخاطرة التجريبية المنظَّمة. من خلال استخدام مزيج من التجارب العددية على بيانات حقيقية وتخليقية، واستنتاجات رياضية في ظل التقاربات منخفضة ومرتفعة البُعد، نُظهر أنّ: (أ) يمكن أن يكون اختيار البيانات فعالًا للغاية، ولا سيما التفوّق على التدريب على العينة الكاملة في بعض الحالات؛ (ب) بعض الخيارات الشائعة في طرق اختيار البيانات (مثل إعادة أخذ العينات الفرعية غير المتحيزة المُعاد وزنُها، أو أخذ العينات الفرعية القائمة على دالة التأثير) يمكن أن تكون دون المثالية بشكل جوهري.
One-sentence Summary
Researchers from Granica Computing, Inc. develop a statistical theory for data selection under weak supervision, demonstrating that selecting a subset of size n<N from N unlabeled samples via a surrogate model and training with regularized empirical risk minimization can outperform full-sample training, while showing that popular strategies such as unbiased reweighted subsampling or influence function-based subsampling can be substantially suboptimal.
Key Contributions
-
A theoretical and empirical analysis of selecting labeled subsets from unlabeled examples using a surrogate model shows that data selection can outperform full-sample training, with subsets as small as 0.4 of the data yielding lower test error.
-
For convex M-estimators, low-dimensional and high-dimensional asymptotic analyses establish that unbiased reweighted subsampling and influence-function-based selection can be substantially suboptimal, while biased selection can improve expected-risk curvature and optimal probabilities depend nontrivially on the subsampling fraction n/N.
-
The analysis identifies uncertainty-based subsampling as an effective practical rule and shows that better surrogate models do not always improve plug-in selection. Real and synthetic experiments further indicate that optimal choices can favor harder or easier examples depending on the low-dimensional or high-dimensional regime.
Introduction
Labeling is labor-intensive, and data selection-based learning addresses this cost by selecting a small informative subset from a fixed unlabeled pool, labeling it, and then training through weighted empirical risk minimization. This setting matters for pool-based active learning, where the goal is to retain near full-sample accuracy with far fewer labels. Prior approaches such as Bayesian uncertainty sampling, gradient or loss heuristics, leverage scores, influence functions, and margin-based selection are often tied to specific assumptions, problem formulations, or small subsampling regimes, and many theoretical treatments enforce unbiased weights proportional to the inverse of the selection probability. These restrictions can make selection suboptimal, especially when the retained sample is a constant fraction of the data and the usefulness of each point depends on the target selection rate. The authors leverage a unified analysis of biased and unbiased weighted ERM across low- and high-dimensional asymptotics, showing that fraction-aware, surrogate-based selection rules can improve over standard unbiased schemes, that uncertainty can guide effective selection, and that good subsampling can sometimes outperform full-sample training.
Method
The proposed method is a label-free selective empirical risk minimization framework. Its core design is to separate the expensive labeling and full training process into a lightweight surrogate prediction stage, a data scoring and subsampling stage, and a final reduced-data training stage. Given a large unlabeled pool x1,…,xN, the method assumes access to a surrogate probability kernel Psu(dy∣x). The surrogate may either approximate the true conditional distribution of the labels or be a weaker predictive model. The final model is trained on a subset of size n<N chosen using only the feature vectors and surrogate outputs, not the true labels.
The selection process is encoded through random variables Si(xi)≥0, which depend on xi, the surrogate prediction Psu(⋅∣xi), and independent randomness across samples. The final estimator minimizes the selectively weighted empirical risk
R^N(θ)=N1i=1∑NSi(xi)L(θ;yi,xi)+λΩ(θ),L(θ;y,x):=ℓ(y,f(x;θ)).Here λΩ(θ) is a regularizer. The subsampling budget is enforced in expectation through
n=i=1∑NEπ(xi),π(xi):=P(Si(xi)>0∣X,y).A central design choice is whether the selection scheme is unbiased. An unbiased scheme satisfies
E{S(x)∣X,y}=1.In this case, the weights compensate for the sampling probabilities, effectively preserving the expected risk. In the classical fixed-dimension regime, the optimal unbiased scheme is determined by a conditional influence-function-type score. Define the conditional gradient covariance and Hessian
G(x):=E{∇θL(θ∗;y,x)∇θL(θ∗;y,x)⊤∣x}, H(x):=E{∇θ2L(θ∗;y,x)∣x}.The optimal unbiased sampling probability has the form
πunb(x)=min(1,c(γ)Z(x)1/2),where
Z(x):=Tr(G(x)H−1QH−1).The constant c(γ) enforces the target subsampling fraction γ=n/N. Equivalently, under the surrogate prediction, the algorithm selects samples whose expected squared influence under the surrogate is large. For generalized linear models, this score reduces to a natural geometric score involving the model curvature and the surrogate-conditional uncertainty. In linear regression, for example, the score becomes proportional to a population leverage score.
The method further studies biased non-reweighting schemes, which are simpler in practice because the selected samples are used with weight one. In this design, the selection rule is defined only by a probability π(x), so that
S(x)={1,0,with probability π(x),otherwise.This avoids modifying the training objective and therefore integrates more directly into standard machine-learning pipelines. However, because no reweighting is applied, the effective Hessian and gradient covariance are no longer those of the full population distribution. Instead, they are computed under the selected distribution:
Gπ:=EπG(x),Hπ:=EπH(x),where Eπ denotes expectation under the distribution induced by π. The optimal biased selection rule uses a thresholded score
Z(x;π):=−Tr{G(x)Hπ−1QHπ−1}+2Tr{H(x)Hπ−1QHπ−1GπHπ−1}.The optimal non-reweighting probability selects examples with large Z(x;π) subject to the target sample size. This yields a greedy selection rule based on difficult or informative samples, but the score itself is coupled to the final selected distribution. As a result, the optimal subset depends nontrivially on the target fraction γ, and selecting the most uncertain or highest-score examples is not always the best strategy.
The same principle is extended to a high-dimensional setting where the feature dimension p, pool size N, and subset size n diverge together. For generalized linear models with responses depending on a one-dimensional projection ⟨θ0,x⟩, the surrogate model is summarized by two quantities: alignment with the true projection direction and norm of the orthogonal error component. The asymptotic test error is characterized by a saddle-point problem involving the loss, the selection rule, and the surrogate-dependent statistics. This makes it possible to compare selection rules that emphasize hard examples, uncertain examples, or more balanced uncertainty scores without requiring exact knowledge of the true labels.
A practical consequence of the framework is that data selection is not only a computational shortcut. The authors show that selecting a smaller, more informative subset can improve final accuracy relative to training on the full dataset. This is possible because biased selection can change the effective curvature of the expected risk. Unbiased selection preserves the original population curvature, while biased selection can favor regions of the feature space that improve statistical efficiency. The method is therefore designed as a surrogate-driven filtering workflow: a small weak or strong surrogate model is first trained, conditional predictions or uncertainty scores are computed on the unlabeled pool, a subset is selected according to a biased or unbiased scoring rule, and the final model is trained on the selected subset with regularized empirical risk minimization.
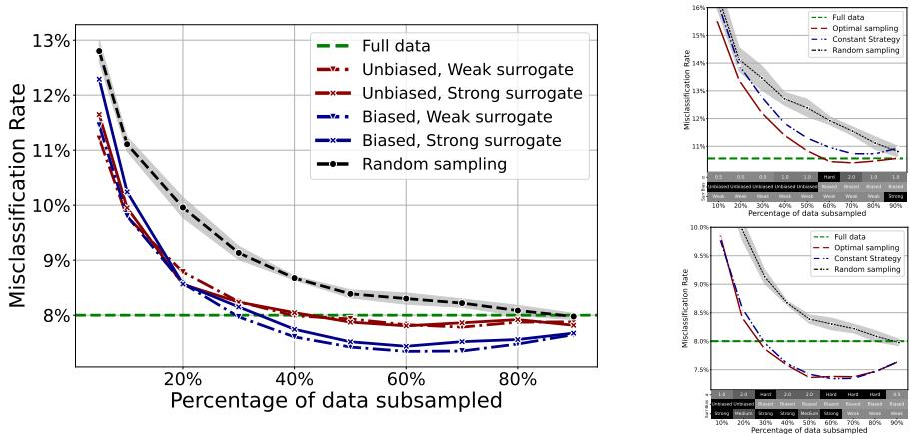
The empirical behavior of the method reflects the design. A weak surrogate can still produce an effective selection rule, biased selection can outperform unbiased reweighting, and the selected subset can yield lower test error than using all available examples. As shown in the figure below:
In the depicted setting, the pipeline uses image embeddings and a simple final classifier. The scoring module may emphasize hard examples through an exponent parameter, while the training module optimizes a ridge-regularized loss. The comparison illustrates that the quality of the final model depends not only on the amount of data used, but also on the interaction among surrogate strength, selection bias, regularization, and target subsampling fraction.
Experiment
The evaluation combines theoretical low- and high-dimensional asymptotics with synthetic simulations and a real-data autonomous-vehicle classification task, testing uncertainty-based one-parameter subsampling for logistic regression. The experiments validate the asymptotic predictions, showing that biased subsampling can be more accurate than unbiased schemes and that sample utility depends on the sampling fraction rather than surrogate quality alone. Across settings, uncertainty-driven selection often approaches or exceeds full-sample performance even with small fractions, though optimal bias toward easy or hard examples varies with dimension, model misspecification, and budget.