Command Palette
Search for a command to run...
الصورة تقول ألف كلمة، لكن هل يستطيع الجميع الإصغاء؟ حول التحويل الإبداعي للصور لتحقيق الملاءمة الثقافية
الصورة تقول ألف كلمة، لكن هل يستطيع الجميع الإصغاء؟ حول التحويل الإبداعي للصور لتحقيق الملاءمة الثقافية
Simran Khanuja Sathyanarayanan Ramamoorthy Yueqi Song Graham Neubig
الملخص
مع تزايد المحتوى متعدد الوسائط، يتجه المترجمون البشريون بشكل متزايد إلى تكييف المحتوى ثقافياً ليس فقط على مستوى الكلمات بل أيضاً على مستوى وسائط أخرى كالصور، لنقل المعنى نفسه. ورغم أن عدة تطبيقات قد تستفيد من ذلك، تظل أنظمة الترجمة الآلية محصورة في معالجة اللغة فيSpeech والنص. في هذا العمل، نقدّم مهمة جديدة تتمثل في ترجمة الصور لجعلها ملائمة ثقافياً. أولاً، نبني ثلاثة خطوط معالجة تتضمن أحدث النماذج التوليدية لأداء هذه المهمة. ثم نبني مجموعة بيانات تقييم ثنائية الجزء: (i) المفهوم: وتتألف من 600 صورة متسقة ثقافياً، تركز على مفهوم واحد لكل صورة؛ و(ii) التطبيق: وتتألف من 100 صورة منسّقة من تطبيقات حقيقية. نجري تقييماً بشرياً متعدد الأبعاد للصور المترجمة لتقييم الملاءمة الثقافية والحفاظ على المعنى. نجد أنه حتى تاريخه، تفشل نماذج تحرير الصور في هذه المهمة، لكنها يمكن أن تتحسن بالاعتماد على النماذج اللغوية الكبيرة وأنظمة الاسترجاع ضمن الحلقة. أفضل خطوط المعالجة لا تترجم سوى 5% من الصور لبعض البلدان في مجموعة بيانات المفاهيم الأسهل، ولا تنجح أي ترجمة لبعض البلدان في مجموعة بيانات التطبيقات، مما يبرز مدى صعوبة هذه المهمة.
One-sentence Summary
Carnegie Mellon University introduces image transcreation, a new task for culturally adapting images across languages, proposing three generative pipelines augmented with LLMs and retrievers alongside a two-part evaluation dataset of 600 concept images and 100 application images, and finding that even the best approaches succeed on only 5% of images in some countries, underscoring the task's difficulty.
Key Contributions
-
The paper introduces image transcreation, a new machine-learning task for culturally adapting visual content for target audiences while preserving original meaning, extending translation beyond speech and text.
-
Three baseline pipelines combine state-of-the-art generative image-editing models with large language models and retrievers in the loop, showing that explicit language understanding and retrieval improve over direct end-to-end image editing.
-
A two-part evaluation dataset is released, with a 600-image concept set and a 100-image application set drawn from educational worksheets and children's literature. Human evaluation across seven countries shows current image-editing models largely fail, with the best pipelines successfully transcreating only 5% of images for some countries in the concept set and no images for some countries in the application set.
Introduction
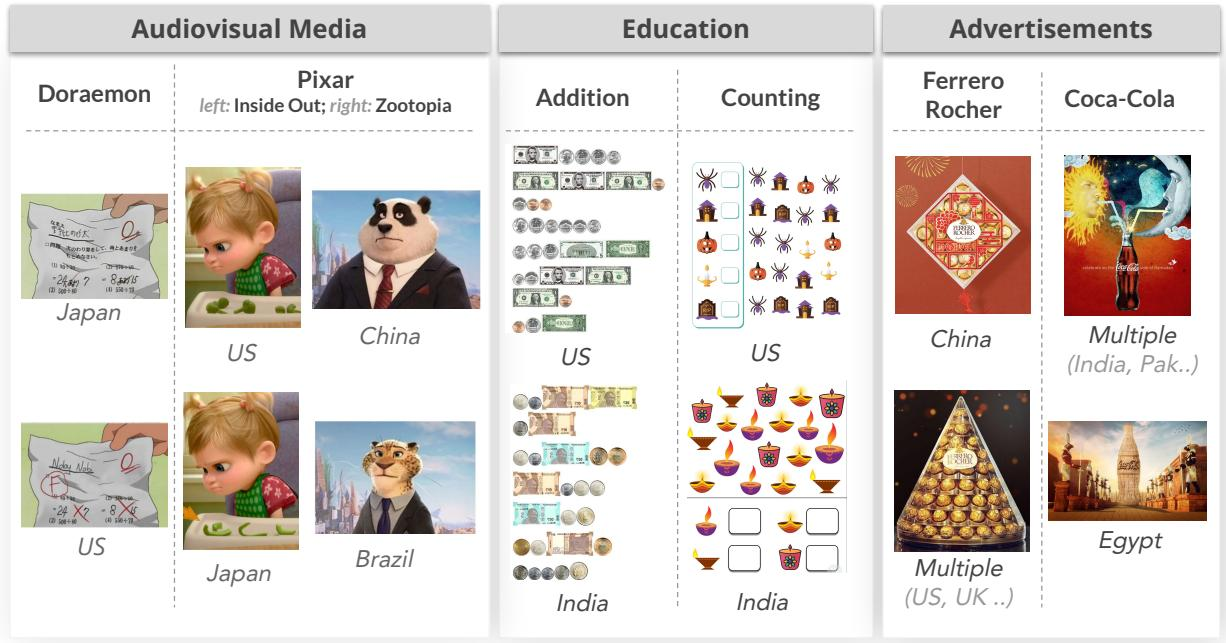
Translation has broadened from words to multimodal meaning, because visuals, music, and context shape audience response. This matters in areas like film, education, and advertising, where local objects, currencies, foods, and celebrations help preserve the intended effect. Prior work mostly studies cultural bias in text translation or image generation, while current image editing models often handle surface style changes rather than deep cultural meaning. The authors introduce image transcreation as a new ML task, build three pipelines using direct editing, LLM based caption rewriting, or retrieval, create a cross country dataset for concept and real applications, and show through human evaluation that today’s models struggle while LLM and retriever loops improve results.
Dataset
-
The authors build a two-part evaluation dataset: a concept prototype subset and an application subset grounded in education and literature.
-
Concept subset:
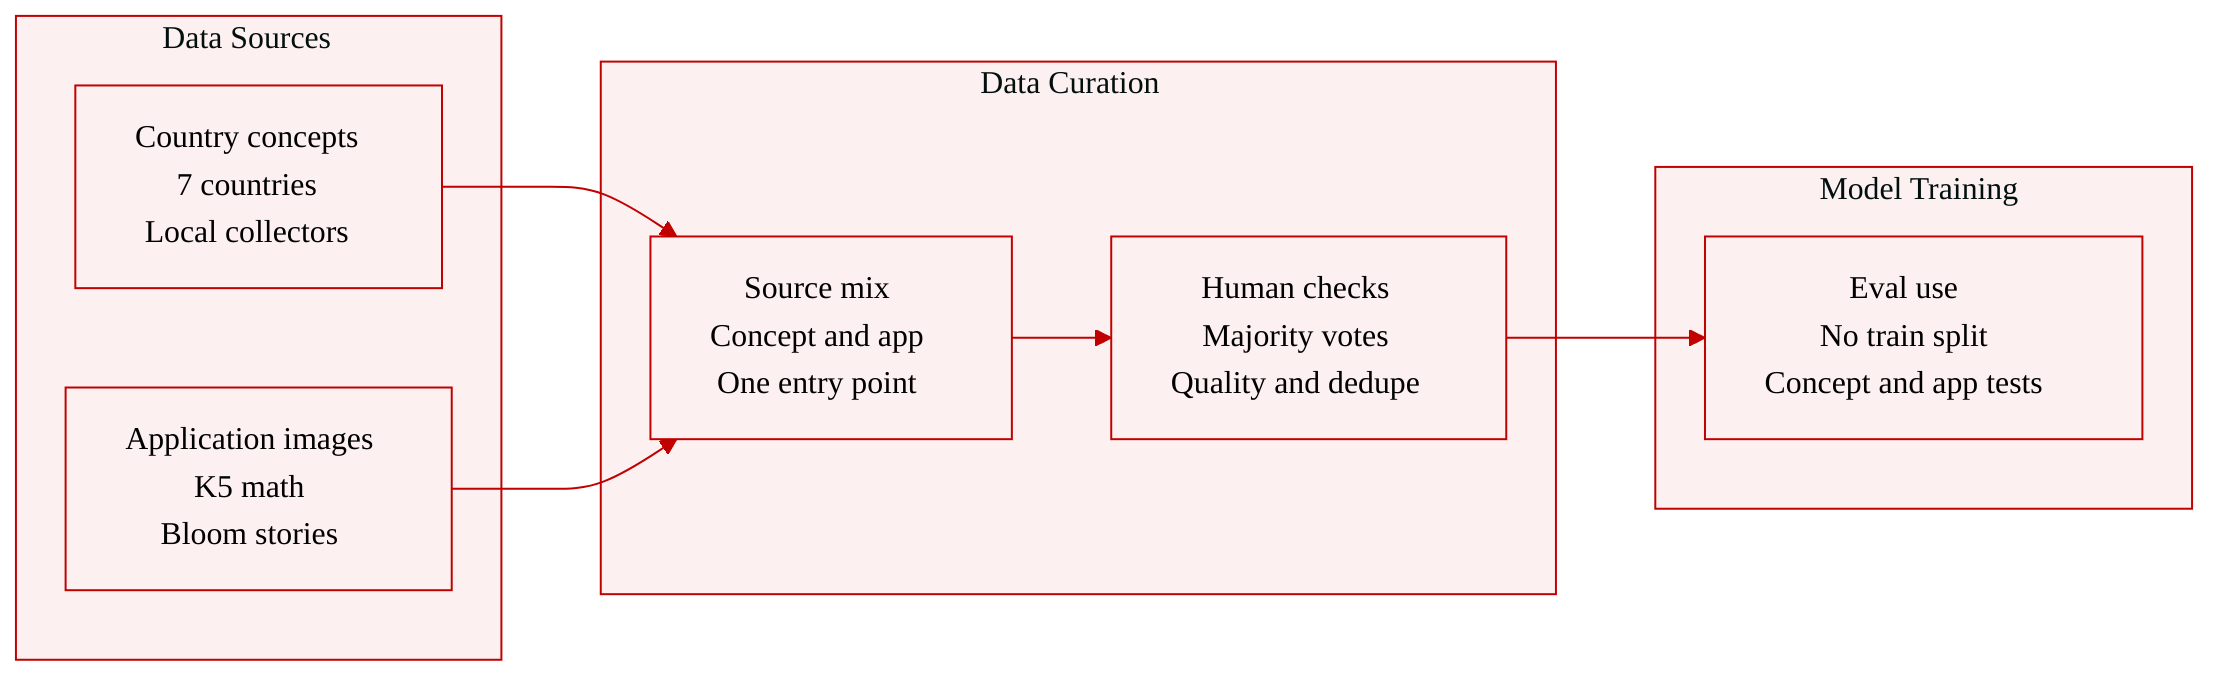
- Source and composition: images of universal concepts collected across seven countries: Brazil, India, Japan, Nigeria, Portugal, Turkey, and United States.
- Annotation source: local annotators in each country drive collection under the MaRVL protocol, helping capture lived cultural context.
- Concept selection: five culture-familiar annotators per country list five salient, commonly seen, concrete concepts. The top five most frequent concepts are retained for each country.
- Filtering: three native speakers verify selected concepts and images, and items without at least two votes are removed.
- Scale: about 85 images per country, yielding roughly 580 images overall after filtering.
- Schema and metadata: images are tied to countries and universal concept categories, with each image intended to represent a single concept or object in isolation.
-
Application subset:
- Source: real-world application data from K5 Learning math worksheets for grades 1-3 and Bloom Library children’s stories.
- Education data: sourced from K5 Learning, a US-based learning platform. Worksheet images include task-specific constraints, such as preserving object counts or using objects that can support measurement.
- Literature data: sourced from Bloom Library. The authors use the first image from each selected story along with its text to guide transcreation.
- Selection: from 400 English-language Bloom Library stories, they manually select about 60 images that are high quality and de-duplicated.
-
Usage in the paper:
- The data is described as an evaluation dataset, not a training set. No training split, mixture ratio, or model-training data usage is reported.
- The concept subset serves as a controlled research prototype with diverse countries, one object per image, and loose output constraints to support error analysis.
- The application subset evaluates harder real-world settings with complex scenes, text guidance, and application-specific constraints.
-
Additional processing notes:
- Processing is mainly annotator-driven filtering and manual curation.
- Major filtering rules include majority voting for concept images and manual quality and deduplication checks for application images.
- No cropping strategy is described. Metadata and organization are defined by country, concept category, source application, and associated story text where applicable.
Method
The authors leverage three generative pipelines for image transcreation, each starting from a source image and a target country specification and aiming to produce an output whose visual content, cultural cues, and depicted concepts are more naturally aligned with that country. The overview of the three designs is presented in the framework diagram.
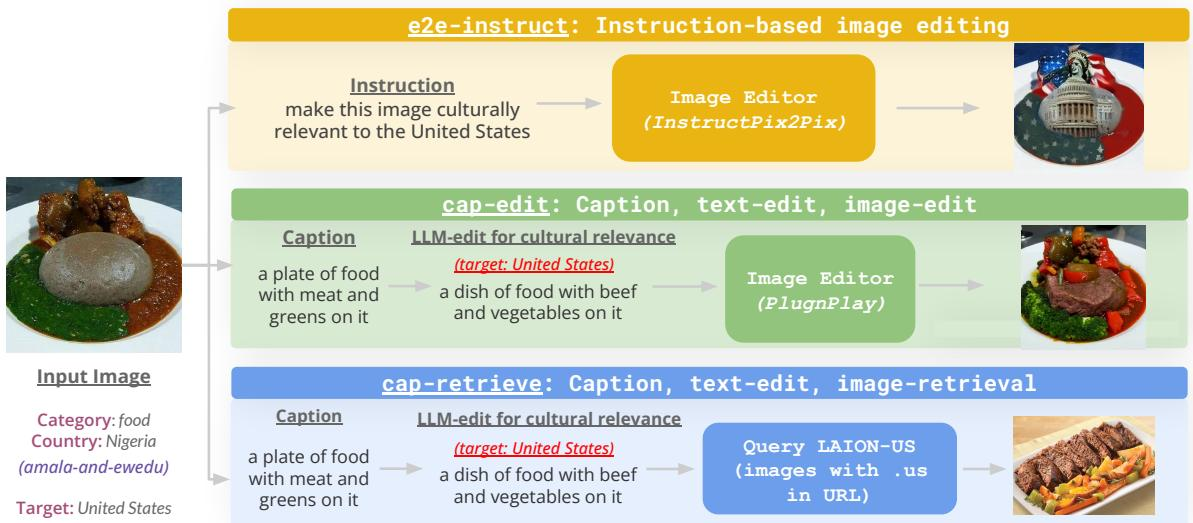
The first pipeline is a direct instruction-based editing design, referred to as e2e-instruct. It feeds the original image and a natural language instruction into an instruction-based image editing model, asking the model to make the image culturally relevant to the target country. This single-pass approach is simple and flexible because it does not require segmentation masks, example output images, or other auxiliary annotations. However, it relies heavily on the image editing model’s ability to infer culturally appropriate changes, which is a significant limitation when the model has not been explicitly trained for such transformations.
The second pipeline is a modular caption, text-edit, image-edit design. It offloads part of the cultural reasoning burden from the image editing model to a large language model. The process begins with an image captioning model that converts the input image into a textual description. A language model then edits this caption so that the described objects, foods, people, scenes, or visual details are culturally relevant to the target country. The revised caption is used as the editing instruction for an image editing model, which modifies the original image while preserving its overall structure. In the implementation described, an image captioning model produces the initial description, a language model performs the culturally relevant caption transformation, and an instruction-based image editor synthesizes the localized image.
The third pipeline is a retrieval-based alternative called cap-retrieve. It follows the same initial path as the caption, text-edit, image-edit pipeline by first captioning the image and then using a language model to rewrite the caption for cultural relevance. Instead of generating a new image through direct editing, it uses the edited caption as a retrieval query against country-specific subsets of a web-scale image collection. These subsets are constructed by parsing image URLs and assigning them to countries based on country-code top-level domains, such as grouping URLs containing a Japan domain suffix into the Japan subset. This design addresses a limitation of direct editing, where image editing models may preserve spatial layout too rigidly and therefore fail to depict concepts in a way that appears naturally within the target country.
Experiment
The study evaluates image transcreation on a two-part dataset comprising culturally annotated universal-concept images from seven countries and real-world application images from education and literature. Human experiments assess whether generated edits are meaningful, preserve the original category, improve cultural relevance, and satisfy application-specific constraints, revealing that pipelines struggle even on isolated concepts and perform worse on complex real-world tasks. Quantitative analyses show that standard embedding-based metrics only partially align with human judgments, indicating that stronger evaluation methods are needed for this task.
The evaluation compares three image transcreation pipelines across several human-rated properties, including visual change, semantic equivalence, spatial layout, cultural relevance, naturalness, and offensiveness. cap-edit tends to make moderate and more meaningful edits that better preserve the original semantic category, while e2e-instruct often makes little change or superficial edits, and cap-retrieve makes more substantial changes but with more variable quality. Successful transcreation remains difficult and uneven across countries, and standard quantitative metrics do not fully capture overall edit quality. cap-edit is generally associated with meaningful edits that better preserve the universal category of the original image. e2e-instruct often scores poorly on visual change and can produce superficial edits that do not reliably convey cultural relevance. cap-retrieve usually edits images more strongly than the other pipelines, but its results vary widely by target country and task. Different applications impose different constraints, so success depends on balancing edit amount, layout preservation, cultural relevance, and naturalness. Overall transcreation success is low and highly country-dependent, indicating the task is far from solved.
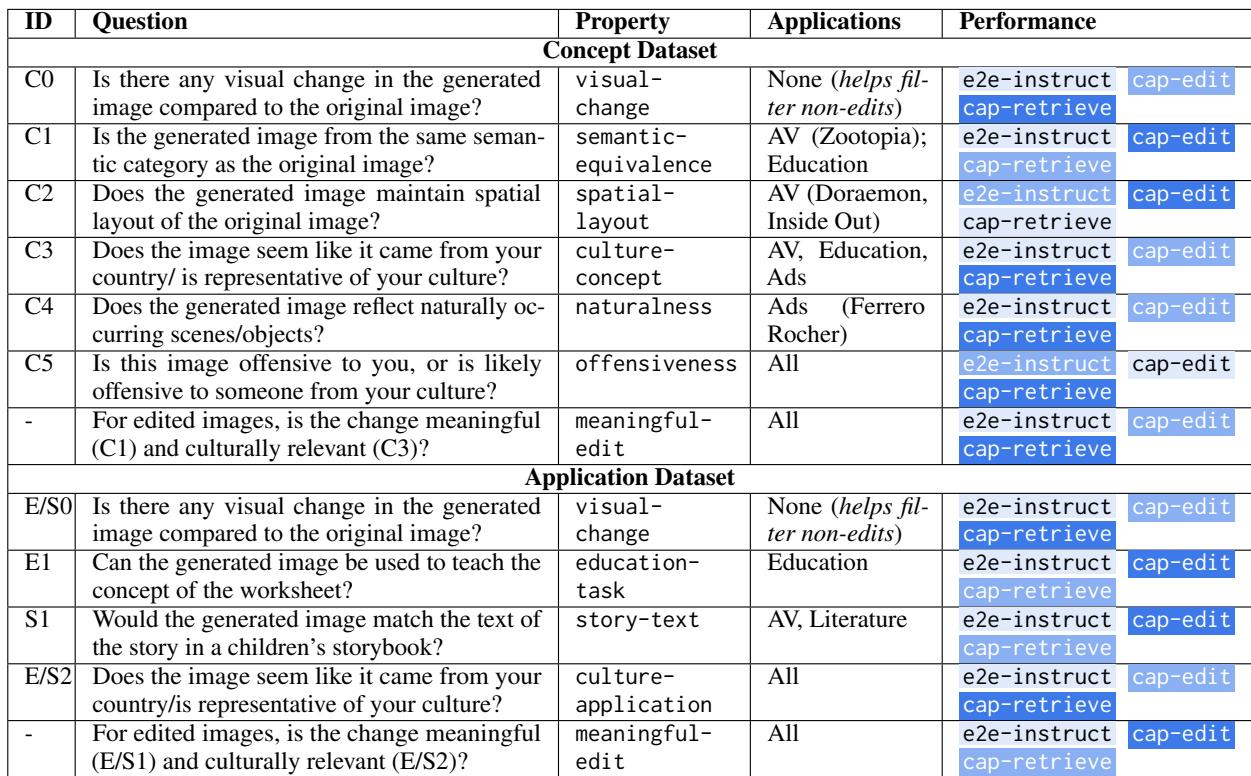
Experiments compare cap-edit, e2e-instruct, and cap-retrieve for image transcreation using human judgments of visual change, semantic equivalence, layout, cultural relevance, naturalness, and offensiveness. cap-edit generally makes moderate, meaningful edits that preserve the original semantic category, whereas e2e-instruct often changes little or superficially and cap-retrieve makes larger but less consistent edits. Overall results show transcreation success is low, uneven across countries, and not well captured by standard metrics, so practical success requires balancing edit amount, layout, cultural relevance, and naturalness.