Command Palette
Search for a command to run...
كلماتٌ بألفِ صورة: قياسُ التباين الإدراكي في توليد الصور من النص وفهمُه
كلماتٌ بألفِ صورة: قياسُ التباين الإدراكي في توليد الصور من النص وفهمُه
Raphael Tang Xinyu Zhang Lixinyu Xu Yao Lu Wenyan Li Pontus Stenetorp Jimmy Lin Ferhan Ture
الملخص
تُمثّل نماذج الانتشار أحدثَ ما توصّل إليه العلمُ في مجال توليد الصور من النص، لكنّ تباينها الإدراكي لا يزال محلّ دراسةٍ ناقصة. في هذه الورقة، نفحص كيف تؤثّر المطالبات النصّية (prompts) في تباين الصور المُنتَجة بواسطة نماذج الانتشار المُغلَقة (صندوق أسود). نقترح مقياس W1KP، وهو مقياسُ تباينٍ مُعايرٌ بشريًّا لمجموعة من الصور، مُستنتَجٌ بطريقة التمهيد (bootstrap) انطلاقًا من مسافات إدراكية سابقة بين أزواج الصور. بما أنّ المجموعات البياناتية الحالية لا تغطّي نماذج الانتشار الحديثة، فقد أعدَدْنا ثلاث مجموعات اختبار للتقييم. يتفوّق أفضلُ مقياسٍ إدراكيّ عندنا على تسعة أسس مقارنة بفارقٍ يبلغ 18 نقطةً في الدقة، وتُطابقُ معايَرَتُنا أحكامَ البشر المُدرَّجة بنسبة 78%. باستخدام W1KP، ندرس قابلية إعادة استخدام المطالبات النصّية ونُظهر أنّ مطالبات Imagen يمكن إعادةُ استخدامها لعددٍ يتراوح بين 10 و50 بذرة عشوائية قبل أن تصبح الصور الجديدة مشابهةً جدًّا للصور المُنتَجة سابقًا، بينما يمكن إعادةُ استخدام مطالبات Stable Diffusion XL وDALL-E 3 من 50 إلى 200 مرّة. أخيرًا، نُحلّل 56 سِمةً لسانيةً في مطالبات نصّية حقيقية، فنجد أنّ طول المطالبة، ومعيار تضمين CLIP، وملموسية الكلمات، ودلالاتها هي العواملُ الأكثر تأثيرًا في التباين. وبحسبِ ما نعلم، نحن أوّل من يُحلّل تباين نماذج الانتشار من منظور بصري-لساني. صفحة المشروع على الرابط http://w1kp.com.
One-sentence Summary
Researchers at Comcast AI Technologies, the University of Waterloo, University College London, and the University of Copenhagen propose W1KP, a human-calibrated measure of perceptual variability in text-to-image diffusion models that outperforms nine baselines by up to 18 points in accuracy and reveals how prompt length, CLIP embedding norm, concreteness, and word senses influence image variability.
Key Contributions
-
The paper introduces W1KP, a human-calibrated framework for measuring perceptual variability in sets of generated images by bootstrapping existing image-pair perceptual distances and calibrating them against graded human judgments. The best calibrated distance outperforms nine baselines by up to 18 points in accuracy and matches human judgments 78% of the time.
-
The work applies W1KP to assess prompt reusability in black-box diffusion models and curates three evaluation sets for recent systems. Measurements show that Imagen prompts can be reused for 10 to 50 random seeds before new images become too similar to already generated images, while Stable Diffusion XL and DALL-E 3 can be reused 50 to 200 times.
-
The study analyzes 56 linguistic features of real prompts to examine linguistic sources of diffusion variability. Prompt length, CLIP embedding norm, concreteness, word senses, keywords, syntactic complexity, and semantic richness influence variability.
Introduction
The research sits within text-to-image generation, especially diffusion models, where a single prompt can produce many visually different images depending on the random seed. Understanding how prompt language drives this variation matters for practitioners who need controlled, diverse, or reusable image generation.
Prior methods mainly measured pairwise perceptual similarity and were not calibrated to human-friendly similarity levels, making scores hard to interpret when a prompt can generate a near-infinite image set.
The authors address this gap by proposing W1KP, a human-calibrated framework for estimating perceptual variability from existing distance metrics. They validate the method on human judgments, use it to measure prompt reusability across models, and show that linguistic features such as concreteness, embedding norm, and word senses influence image variability.
Dataset
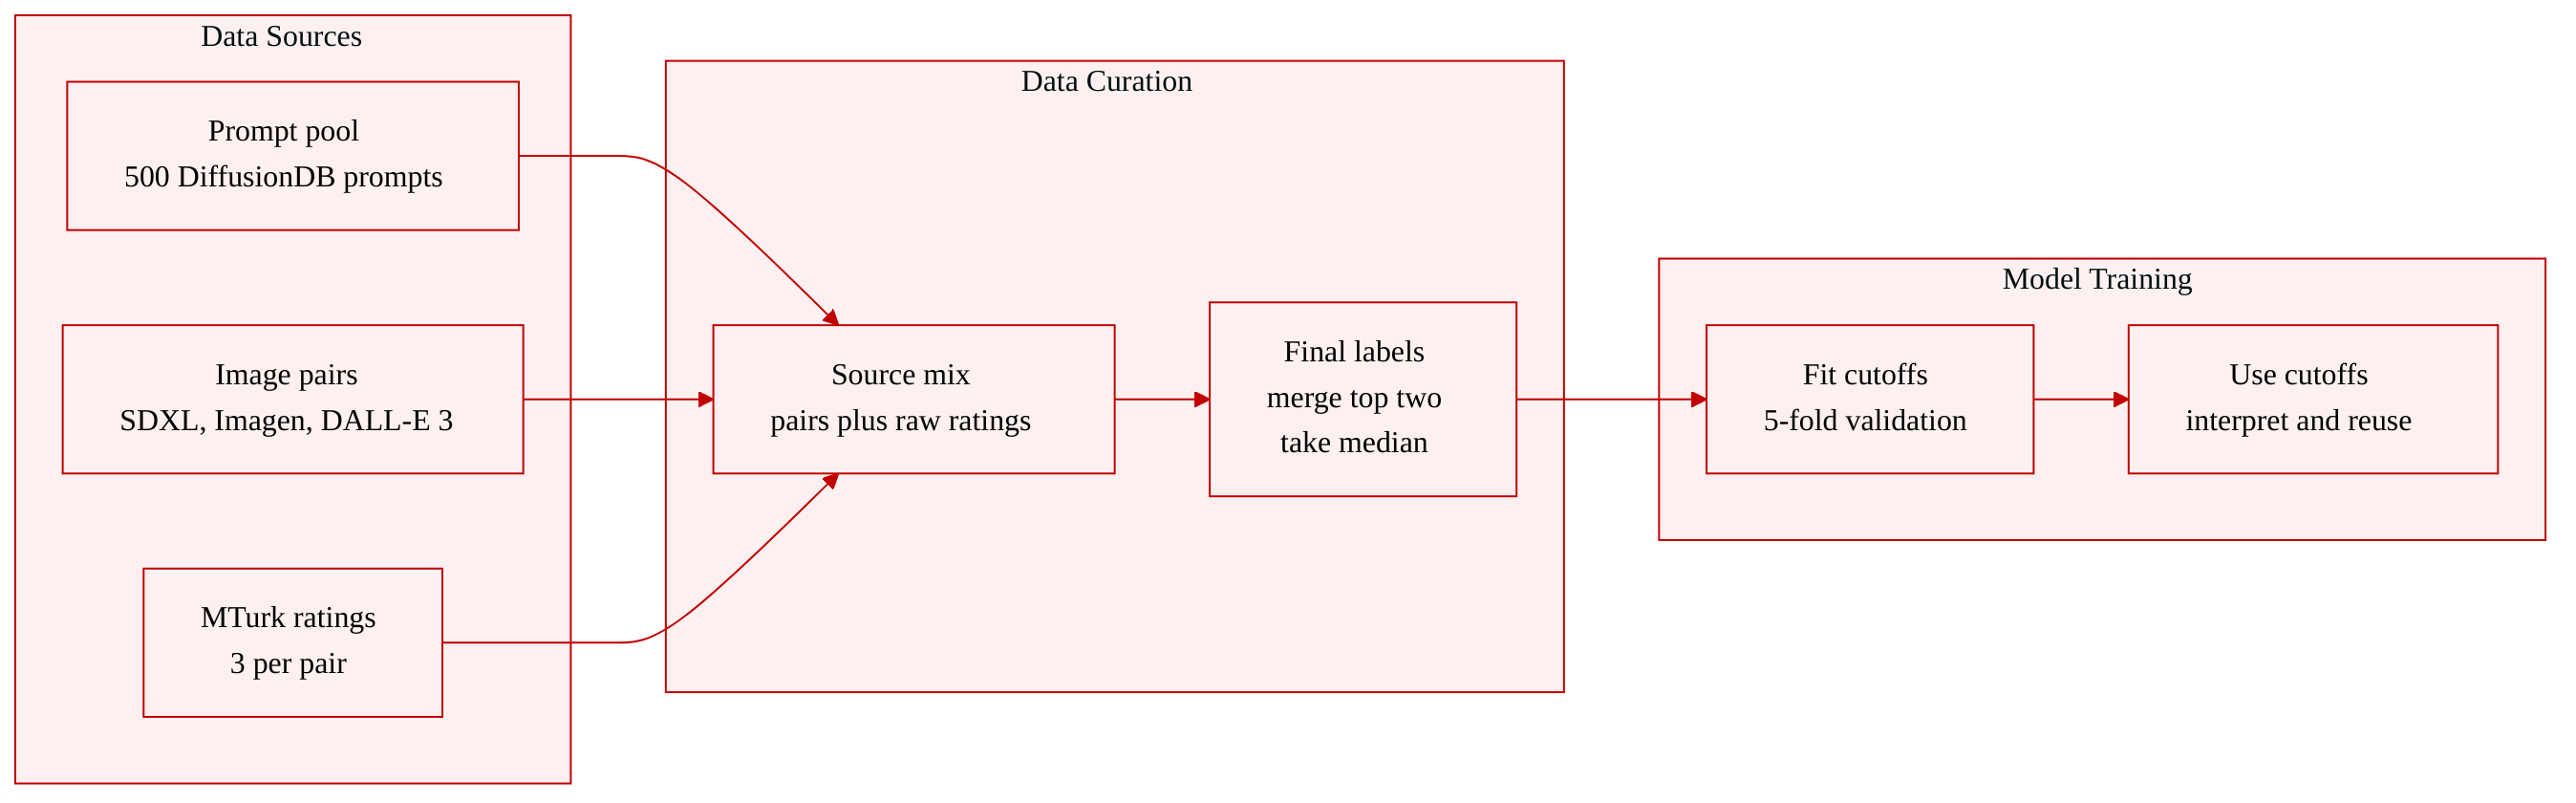
- The authors use a human-annotated calibration dataset collected on MTurk to grade visual similarity between generated image pairs.
- The image pairs are generated from 500 random prompts sampled from DiffusionDB and collected separately for SDXL, Imagen, and DALL-E 3, giving about 500 annotated pairs per generator and 1,500 median judgments in total.
- For each pair, three unique workers rate similarity on a 1 to 5 integral scale, where 1 means “not similar at all” and 5 means “the same.”
- The authors merge the top two categories, “same” and “very similar,” because the highest rating is mostly used for attention checks, producing four final labels: no similarity, low similarity, medium similarity, and high similarity.
- Each pair receives a single ground-truth label by taking the median of the three worker ratings.
- The resulting median labels are roughly distributed as 10%, 30%, 40%, and 20% across similarity ratings 1 through 4.
- Each record can be viewed as a prompt-pair annotation containing the prompt, two generated images, the generating model, three raw worker ratings, and the median four-way similarity label.
- The dataset is used to fit and validate the W1KP similarity thresholds with five-fold cross validation, producing low, mid, and high similarity cutoffs.
- The authors then use these calibrated cutoffs to interpret W1KP scores, including using the high-similarity cutoff for downstream prompt-reusability analysis.
Method
The authors evaluate visual diversity in synthetic images generated by text to image diffusion models. Such a model is treated as a black box, denoted by G({wi};s,θ), where a prompt {wi}, a random seed s, and learned parameters θ define the generated image. To study variability, the pipeline generates multiple images from the same prompt by changing the seed while keeping the text condition fixed. The resulting image set is then analyzed through feature embeddings, pairwise perceptual distances, normalization, and calibrated similarity labels.
As shown in the figure below:
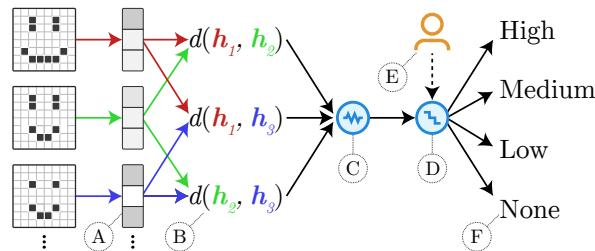
The framework first maps each image into an embedding space using a feature extractor f. Pairwise distances between embedded images are then computed with a perceptual distance function d. Because raw perceptual distances may be unbounded or concentrated in narrow ranges, the method standardizes them through a cumulative distribution transform. The normalized distance is defined as
d∗(Ia,Ib):=F(d(f(Ia),f(Ib))),where F is estimated from a large empirical sample of generated image pairs. This transform produces values in the unit interval, making scores more interpretable across models and prompts.
Using these normalized distances, the authors construct variability measures through U statistics. Let I={Ii}i=1n be an independently sampled set of images generated from a single prompt. A general family of set level scores is defined as
Ud,h(I):=(αn)11≤i1<⋯<iα≤n∑h(f(Ii1),…,f(Iiα);d),where h is an α arity kernel built from the distance function. Two important instances are used. The pairwise mean score aggregates similarity over all image pairs:
ηmean(I)=(2n)1i<j∑d∗(Ii,Ij).The k expected maximum score instead measures the expected closest pair similarity among subsets of size k:
ηk(I)=(kn)11≤i1<⋯<ik≤n∑r=smind∗(Iir,Iis).For readability, the final score is inverted so that higher values indicate higher similarity. The authors denote this similarity oriented score as
η~:=1−η.The calibration module then maps normalized scores into human interpretable categories. Human judgments of image pair similarity are collected as labels, such as high, medium, low, or no similarity. The method learns cutoff points βlow, βmid, and βhigh that partition the score range and maximize agreement with those labels:
argβlow,βmid,βhighmaxN1i=1∑NI(η~({Ixi,Iyi})∈Szi).The intervals are defined as Snone=[0,βlow), Slow=[βlow,βmid), Smid=[βmid,βhigh), and Shigh=[βhigh,1].
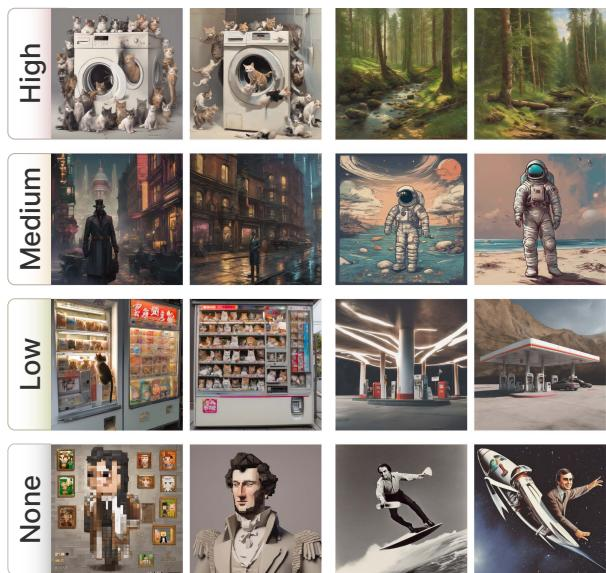
The calibrated score range corresponds to perceptual similarity levels, and the examples below illustrate how image pairs from the same prompt are assigned to high, medium, low, or no similarity categories based on the score:
Experiment
Experiments use human-annotated similarity judgments to validate and calibrate W1KP, a perceptual variability metric based on a DreamSim-inspired backbone. The calibration yields interpretable similarity cutoffs that align well with human ratings and shows lower model-wise bias than alternatives. Applying W1KP to image generation reveals that prompt reusability varies across text-to-image models, and linguistic features such as CLIP embedding norm, prompt length, concreteness, and polysemy consistently predict visual variability, including in controlled single-word prompt settings.
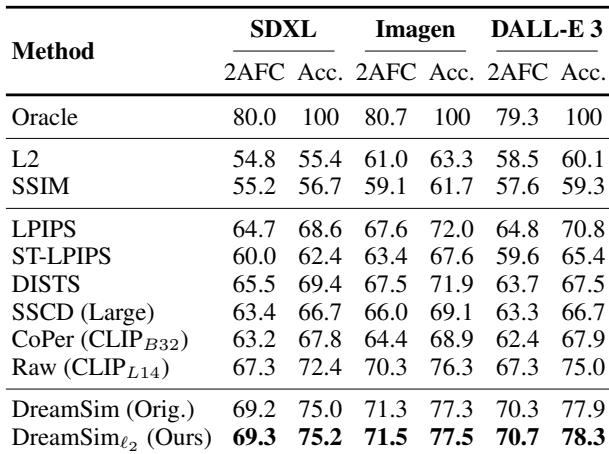
The evaluation compares perceptual distance backbones against human judgments for images generated by SDXL, Imagen, and DALL-E 3. Neural perceptual metrics show stronger agreement with human preferences than raw pixel distance and structural similarity. Among the evaluated non-oracle backbones, LPIPS and DISTS are the strongest, with their relative ranking varying slightly by image generation model. Neural perceptual backbones outperform simple Euclidean distance and SSIM across the tested image models. LPIPS and DISTS provide the highest non-oracle agreement with human choices, with LPIPS performing best for Imagen and DALL-E 3 and DISTS slightly better for SDXL. The oracle reference achieves the highest agreement and accuracy, setting an upper performance bound for the backbone evaluation.
Significant linguistic features group into interpretable factors, showing that prompt wording and style keywords form structured dimensions rather than isolated signals. Keyword-based style cues, such as resolution, realism, and art-site tags, cluster strongly together, while broader lexical features also relate to prompt interpretability. Related findings indicate that concrete, single-sense prompts are associated with lower perceptual variability than abstract or polysemous prompts. Style keywords load together on one interpretable factor, indicating correlated visual style cues in prompts. Low-loading and insignificant features are removed, emphasizing reliable associations between linguistic features and prompt behavior. Concrete and monosemous words are associated with less variability than abstract and polysemous words.
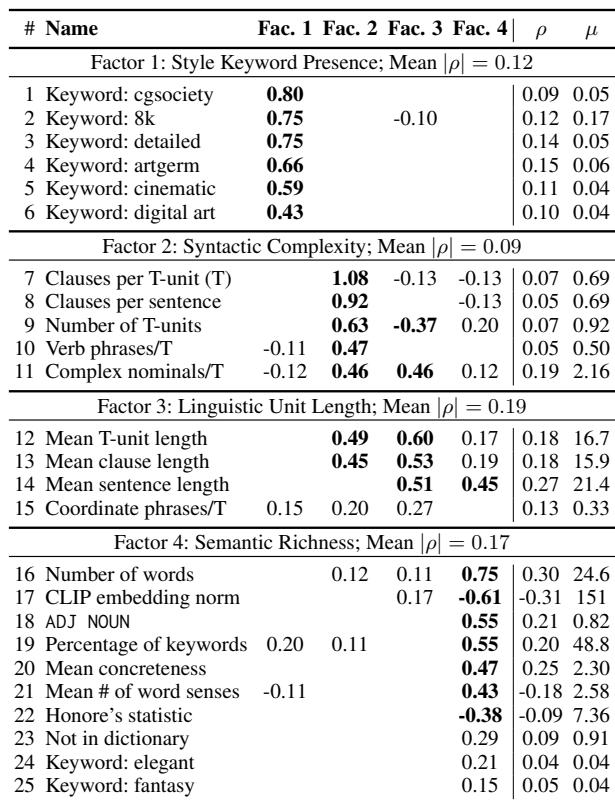
The experiments evaluate perceptual distance backbones against human preferences for images generated by SDXL, Imagen, and DALL-E 3, showing that neural metrics align more closely with human judgments than raw pixel or structural similarity measures. Among non-oracle backbones, LPIPS and DISTS perform most strongly, with LPIPS favored for Imagen and DALL-E 3 and DISTS slightly favored for SDXL, while the oracle reference defines the upper bound. Additional analysis of prompt linguistic features finds that style-related cues cluster into interpretable dimensions, and concrete, single-sense prompts tend to be associated with lower visual variability than abstract or polysemous prompts.