Command Palette
Search for a command to run...
أخُدع مرة؟ مقارنة بين التفسيرات النصية والمرئية في سياق دعم القرار السريري
أخُدع مرة؟ مقارنة بين التفسيرات النصية والمرئية في سياق دعم القرار السريري
Maxime Kayser Bayar Menzat Cornelius Emde Bogdan Bercean Alex Novak Abdala Espinosa Bartlomiej W. Papiez Susanne Gaube Thomas Lukasiewicz Oana-Maria Camburu
الملخص
تؤدي القدرات المتنامية لنماذج الذكاء الاصطناعي إلى اتساع نطاق استخدامها، بما في ذلك في المجالات الحساسة للسلامة. يهدف الذكاء الاصطناعي القابل للتفسير (XAI) إلى جعل استخدام هذه النماذج أكثر أمانًا من خلال زيادة شفافية عملية الاستدلال الخاصة بها. غير أن طرق التفسير الحالية تُقيَّم نادرًا بالطريقة المقصود استخدامها بها، أي من قِبَل المستخدمين النهائيين في العالم الحقيقي. ولمعالجة هذا القصور، أجرينا دراسة مستخدم واسعة النطاق شملت ٨٥ من ممارسي الرعاية الصحية في سياق التحليل التشاركي بين الإنسان والذكاء الاصطناعي للأشعة السينية للصدر. وقد قيَّمنا ثلاثة أنواع من التفسيرات: التفسيرات المرئية (خرائط الأهمية)، والتفسيرات القائمة على اللغة الطبيعية، وتركيبة من النمطين معًا. ودرسنا على وجه التحديد كيفية تأثير أنواع التفسير المختلفة في المستخدمين تبعًا لما إذا كانت نصائح الذكاء الاصطناعي وتفسيراته صحيحة واقعيًا. وتبيّن أن التفسيرات النصية تؤدي إلى إفراط كبير في الاعتماد عليها، وهو ما يُخفَّف بدمجها مع خرائط الأهمية. كما لاحظنا أن جودة التفسيرات، أي مقدار المعلومات الصحيحة واقعيًا التي تتضمنها، ومدى توافق ذلك مع صحة مخرجات الذكاء الاصطناعي، يؤثران تأثيرًا كبيرًا في فاعلية الأنواع المختلفة من التفسيرات.
One-sentence Summary
In a large-scale user study of 85 healthcare practitioners in chest X-ray analysis at the University of Oxford, Vienna University of Technology, and partner institutions, researchers found that text-based explanations induce significant over-reliance when AI advice is incorrect, and that combining them with visual saliency maps alleviates this effect.
Key Contributions
-
A large-scale user study with 85 healthcare practitioners evaluates visual saliency maps, natural language explanations, and their combination in human-AI collaborative chest X-ray analysis.
-
Text-based explanations cause significant over-reliance on AI advice, and combining them with saliency maps reduces this effect while accounting for whether AI recommendations and explanations are factually correct.
-
The results show that the amount of factually correct information in explanations and its alignment with AI correctness strongly influence the usefulness of visual, language, and combined explanations.
Introduction
Generative AI is increasingly used in medicine, especially through language-based interfaces that can feel natural to users and increase trust, but medical imaging models still face adoption barriers because their reasoning is opaque and may be brittle, biased, or unsafe in high-stakes clinical settings. Prior explainability research is difficult to evaluate because explanations can be judged by different criteria, user preference often does not reflect usefulness, and few clinical studies examine explanations under realistic conditions where both the AI prediction and the explanation may be incorrect. The authors leverage a large human-subject study in a chest X-ray clinical decision-support setting, comparing natural language explanations, saliency maps, their combination, and no explanation while varying the correctness of the AI and the explanation. They find that language explanations can encourage overreliance, that combining language and visual explanations is most useful, and that alignment between explanation correctness and AI correctness strongly determines whether explanations help or harm user performance.
Dataset
-
The authors base their study data on chest X-rays that are paired with human-written radiology reports. The study sample is built from images for which AI advice and explanations have already been generated, allowing the authors to evaluate how different explanation types behave in an imperfect XAI setting.
-
The human participant pool is drawn from medical students and doctors who have received training in reading chest X-rays but are not specialist radiologists. The authors choose this group because they are competent enough to avoid over-reliance on AI, yet still representative of users who may benefit from clinical decision support. Their sample size is estimated through power simulations based on pilot studies.
-
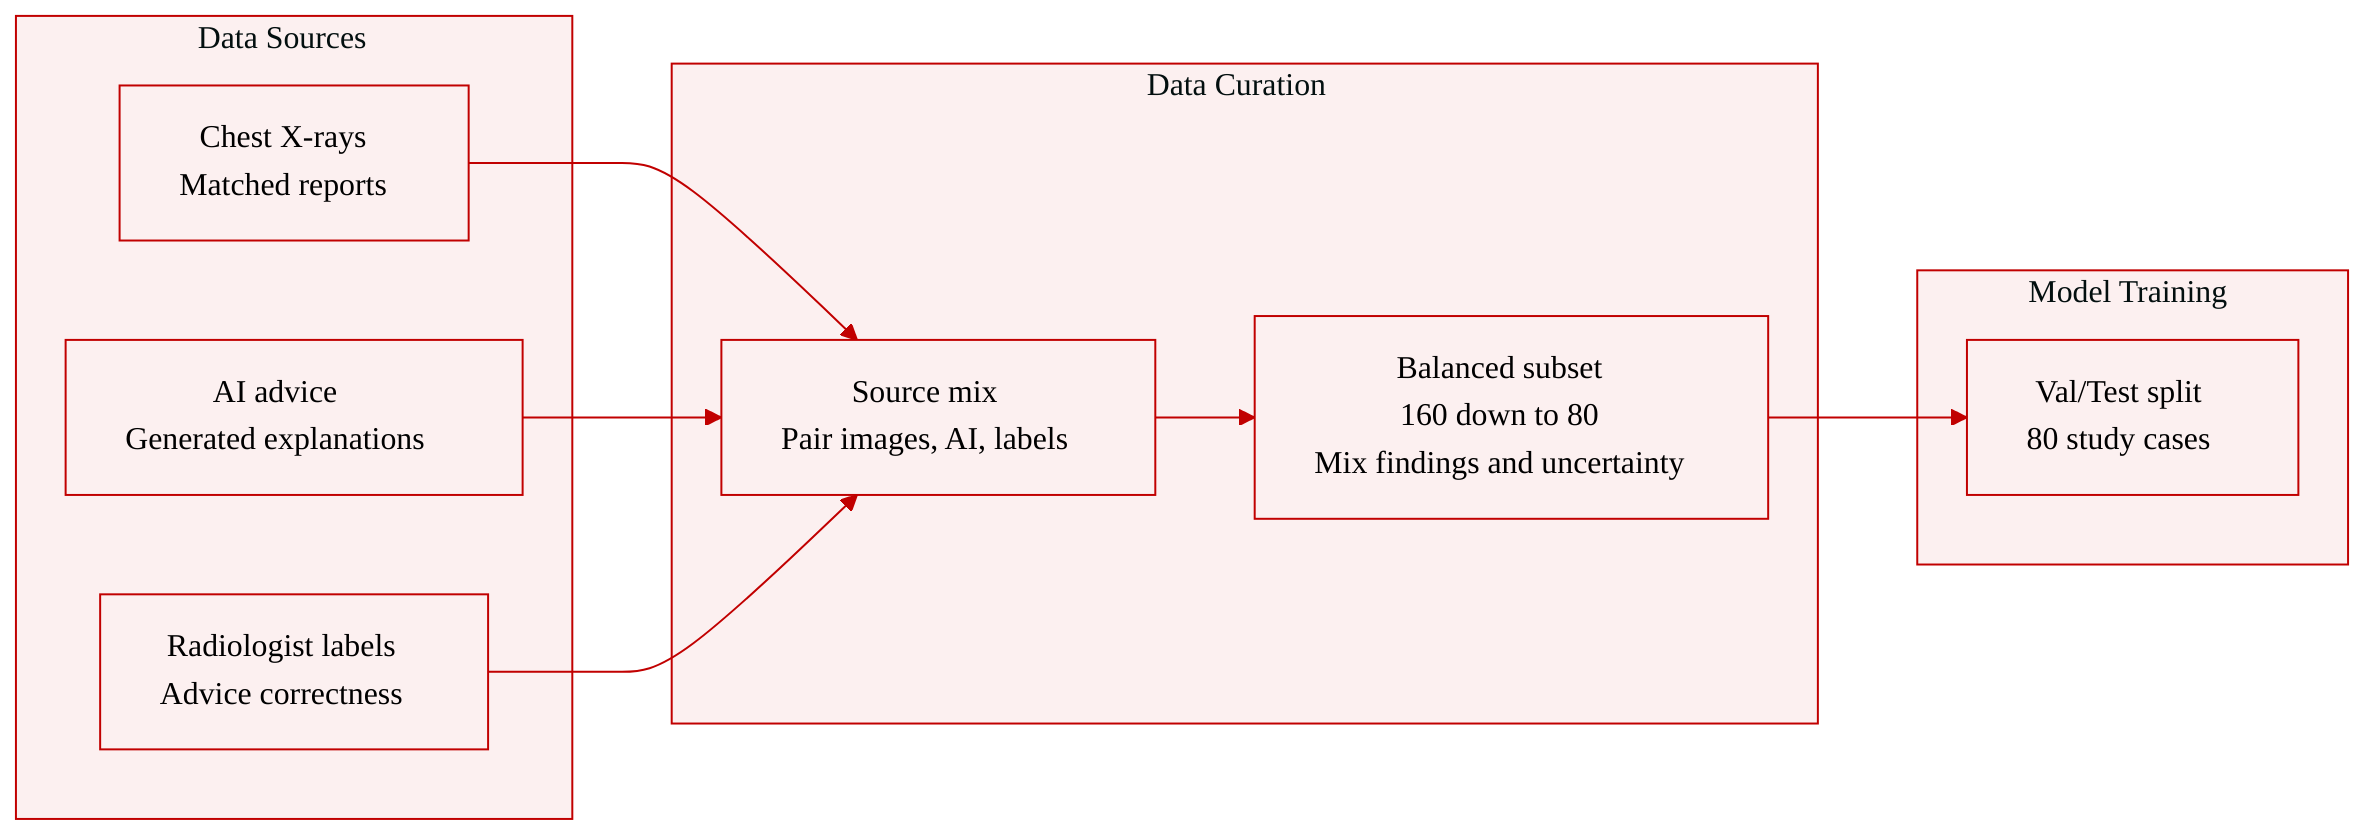
For the main study samples, the authors start from 160 examples. Three experienced radiologists annotate the correctness of the AI advice and explanations. From this larger set, they carefully select 80 cases to use in the study.
-
The selection process is controlled to balance several factors across the final subset: the share of incorrect predictions by class, the level of case ambiguity, and the distribution of C_χ scores. This makes the study set more suitable for evaluating how users respond to correct, incorrect, and uncertain AI advice.
-
The selected cases cover common chest X-ray findings, including pneumonia, atelectasis, pulmonary edema, fluid overload or heart failure, aspiration, and alveolar haemorrhage. These categories help ensure the study includes a diverse but clinically relevant set of scenarios.
-
In practice, the authors use the curated 80-case subset as the evaluation dataset for participant-facing study material, not as a training set. The key constructed metadata for each case appears to include the radiographic finding or class, whether the AI advice is correct, and indicators such as ambiguity and C_χ score. No cropping strategy, additional metadata schema, or model-specific training mixture is described in the provided text.
Method
The authors build a controlled clinical decision-support pipeline around a shared classifier and four explanation conditions. To keep the comparisons internally consistent, participants are presented with what appear to be four different AI systems, but these systems are all derived from the same visual backbone. This design isolates the effect of the explanation modality, while holding the underlying prediction model fixed.
The core model is a vision language system for chest X-ray classification. A DenseNet vision encoder processes each X-ray image and produces a 7×7 feature map with 1024 channels. These features support two parallel pathways. In one pathway, the feature map is pooled to perform multi-label image classification and produce the AI prediction. In the second pathway, the feature map is flattened into token sequences that serve as prefixes to a transformer decoder, enabling natural language explanation generation. The decoder is conditioned on the predicted label and the learned image representation, so the final natural language explanation is tied to both the visual input and the model’s classification output.
Training uses paired X-ray data with radiology findings and naturally occurring natural language explanations extracted from clinical reports. This supervision allows the model to learn clinically realistic wording patterns, including information about location, size, severity, certainty, and differential diagnoses. As a result, the explanations are not generated from a separate post-hoc paraphrase module. Instead, they are learned jointly with the visual reasoning representation, and aspects such as assertiveness are treated as part of the explanation content itself.
From this unified architecture, the study forms four experimental variants:
χNoneuses only the DenseNet classifier and provides no explanation. The second variant,
χSMuses the same classifier but adds visual saliency maps. The third variant,
χNLEuses the full vision language model to generate natural language explanations without saliency maps. The fourth variant,
χCombcombines natural language explanations with saliency maps.
For the visual explanation module, saliency maps are obtained through Grad-CAM applied to the DenseNet backbone. This method is selected for its broad acceptance and suitability for medical imaging, and its behavior is checked against alternative attribution methods. The resulting saliency maps highlight image regions that support the model’s prediction.
The study also explicitly models the usefulness of explanations through two correctness variables. Advice correctness is denoted by
CAI∈{0,1},which captures whether the AI prediction is correct or incorrect. Explanation correctness is denoted by Cχ, which captures how clinically and factually accurate the explanation is. These two variables are treated as distinct, because a correct prediction can still be accompanied by a weak explanation, and an incorrect prediction can still be supported by a fluent or visually plausible explanation.
To ensure the study cases cover meaningful interaction patterns, the authors obtain expert annotations and then select a balanced subset of examples. The selection controls the distribution of advice correctness, explanation correctness, ambiguity, and finding type. The resulting case set spans the main combinations of advice and explanation quality, ranging from supportive cases where correct advice is paired with a strong explanation, to deceptive cases where incorrect advice is paired with an explanation that still appears persuasive. As shown in the figure below:
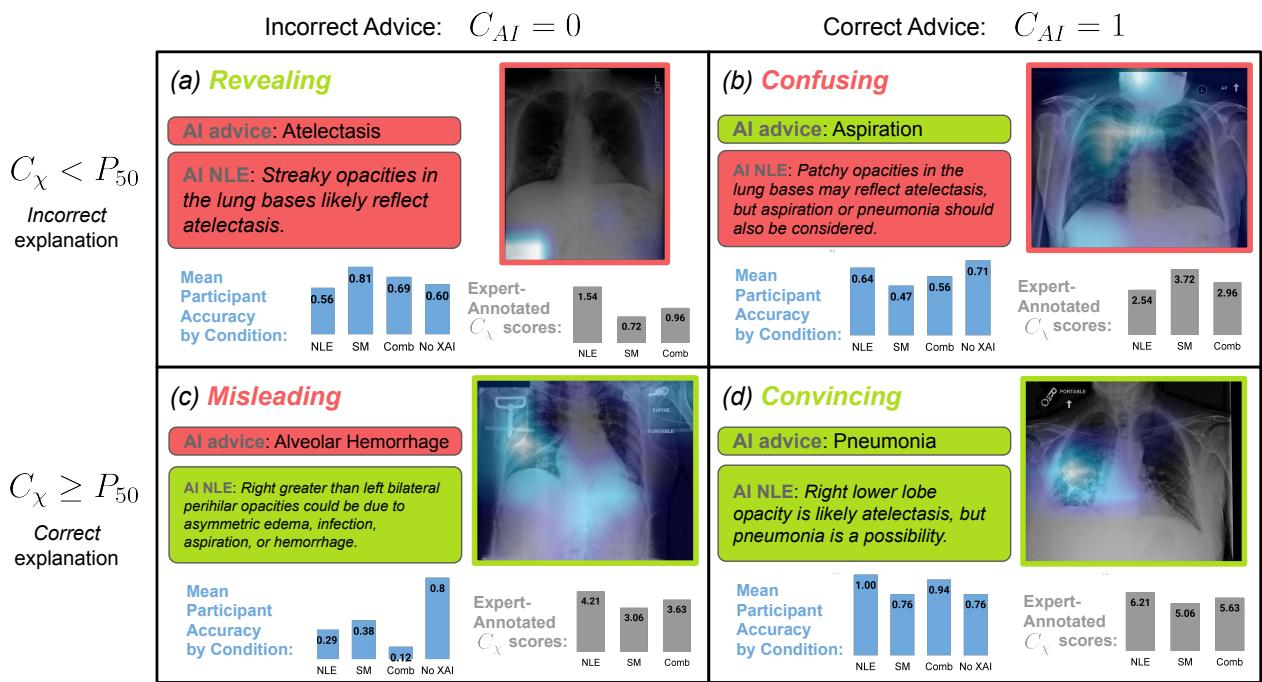
The resulting framework allows the study to examine whether explanations improve human judgment, remain neutral, or even increase overreliance on the AI system. In particular, the method separates the effect of the explanation format from the correctness of the underlying advice and the correctness of the explanation itself, so performance differences can be attributed to the interaction between these factors rather than to model performance alone.
Experiment
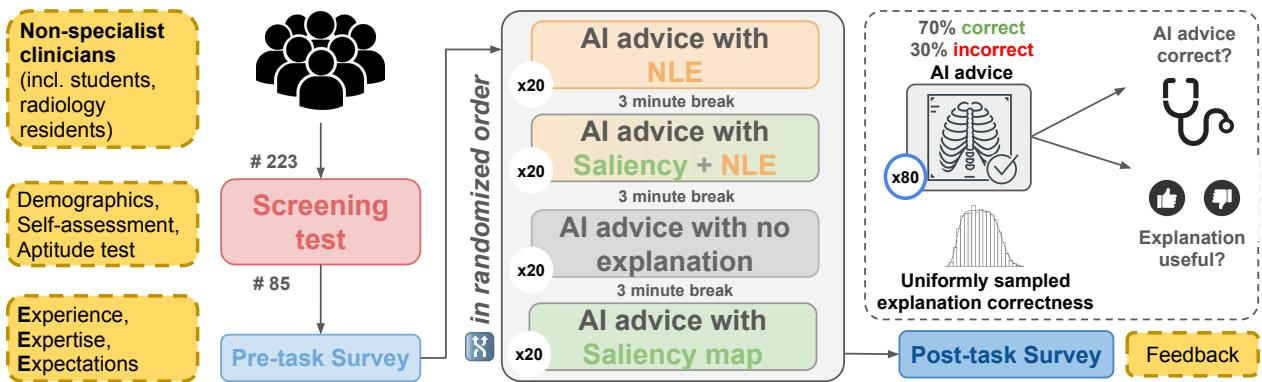
A large-scale, pre-registered study with clinicians evaluated how no explanation, saliency maps, natural language explanations, and their combination affect agreement with AI advice, alongside explanation correctness and perceived usefulness. A mixed-effects statistical model, post-study surveys, and exploratory measures validated that language-based explanations are preferred and perceived as helpful but can encourage overreliance when the AI is wrong, while visual or combined explanations help users recognize misleading advice when explanation correctness aligns with advice correctness. Overall, explanation usefulness depends on the explanation type and the alignment between the explanation and the AI advice, with combined explanations offering a more reliable path to safer use.
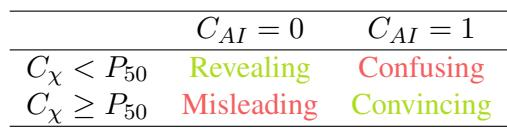
The table categorizes explanations by whether the AI advice is correct and whether the explanation is below or above the median for explanation correctness. Explanations that align with the advice are generally helpful, with convincing explanations appearing when correct advice is paired with a strong explanation. Explanations that do not align with the advice can be harmful, especially when a strong explanation accompanies incorrect advice and may encourage overreliance. Revealing explanations occur when incorrect AI advice is paired with a weak explanation and can help users detect that the AI is wrong. Misleading explanations occur when incorrect AI advice is paired with a strong explanation and can make users more likely to agree with the AI.
Participants strongly favored natural language explanations over saliency maps in post-task preference rankings, with combined explanations also appearing near the top. Models with no explanation and saliency maps were viewed less favorably overall and were more often placed last. Natural language explanations received the best average preference ranking Saliency maps were the least preferred option and were frequently ranked last Combined explanations were as likely as natural language explanations to receive the top ranking
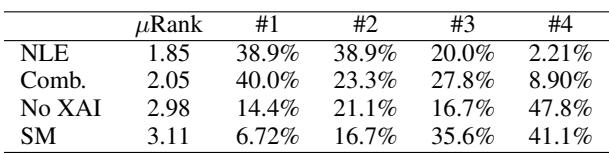
Experiments evaluated how explanation quality, alignment with AI advice, and explanation format affect user behavior and preference. Explanations that matched the advice were generally helpful, especially when correct advice was paired with convincing explanations, while strong explanations accompanying incorrect advice could be misleading and encourage overreliance, whereas weak explanations could help reveal errors. User preference results showed that natural language explanations were most favored, saliency maps were least preferred, and combined explanations were comparable to natural language in receiving top rankings.