Command Palette
Search for a command to run...
رؤية تقليلية ببكسلات حرة الشكل
رؤية تقليلية ببكسلات حرة الشكل
Jeremy Klotz Shree K. Nayar
الملخص
يستخدم نظام الرؤية التقليلية أقل عدد ممكن من البكسلات لحل مهمة رؤية بصرية. بينما تستخدم الكاميرات التقليدية شبكة كبيرة من البكسلات المربعة، تستخدم الكاميرا التقليلية بكسلات حرة الشكل يمكن أن تتخذ أشكالًا اعتباطية لزيادة محتواها المعلوماتي. نبين أن العتاد الصلب للكاميرا التقليلية يمكن نمذجته بوصفه الطبقة الأولى من شبكة عصبية، حيث تُستخدم الطبقات اللاحقة للاستدلال. يؤدي تدريب الشبكة على أي مهمة معينة إلى استنتاج أشكال البكسلات الحرة للكاميرا، حيث يُنفَّذ كلٌّ منها باستخدام كاشف ضوئي وقناع بصري. صمّمنا كاميرات تقليلية لمراقبة المساحات الداخلية (بثمانية بكسلات)، وقياس إضاءة الغرفة (بثمانية بكسلات)، وتقدير تدفق المرور (بثمانية بكسلات). الأداء الذي تُظهره هذه الأنظمة يضاهي أداء كاميرا تقليدية تحتوي على بكسلات أكثر بعشرات المرات. للرؤية التقليلية ميزتان أساسيتان؛ أولًا، تميل بشكل طبيعي إلى حماية خصوصية الأفراد في المشهد، لأن المعلومات المُلتقَطة غير كافية لاستخراج التفاصيل البصرية. ثانيًا، بما أن عدد القياسات التي تجريها الكاميرا التقليلية صغير جدًا، نبين أنها يمكن أن تكون مكتفية ذاتيًا بالكامل، أي تعمل دون مصدر طاقة خارجي أو بطارية.
One-sentence Summary
Columbia University presents a minimalist vision system that models a freeform-pixel camera as the first layer of a neural network, where training discovers pixel shapes implemented via photodetectors and optical masks, demonstrating that 8-pixel cameras can match traditional high-resolution systems while preserving privacy and enabling self-powered operation.
Key Contributions
-
A minimalist vision system models freeform pixels, implemented with photodetectors and optical masks, as the first layer of a neural network, allowing training to determine pixel shapes for a target vision task.
-
Eight-pixel minimalist cameras are designed for indoor-space monitoring, room-lighting measurement, and traffic-flow estimation, with performance on par with conventional cameras that use orders of magnitude more pixels.
-
Simulations show that the freeform-pixel cameras cannot support meaningful face recognition, and the small number of pixels can harvest incident light to read out and wirelessly transmit measurements without an external power supply or battery.
Introduction
The authors focus on “lightweight vision” tasks such as occupancy counting, zone monitoring, traffic flow, lighting estimation, and door-state detection, which need scene statistics rather than detailed images. Traditional cameras capture far more visual information than these tasks require, creating privacy risks and consuming substantial power through pixel readout, analog-to-digital conversion, processing, and transmission. Earlier privacy-focused cameras, optical-computing systems, and single-pixel cameras often still use many pixels, reconstruct images, or reduce inference computation rather than minimizing the number of measurements needed for a task. Their main contribution is minimalist vision, which uses freeform pixels, each formed by an optical mask and photodetector, to make a small number of information-rich linear projections. By training the camera pixels and inference network as a single neural network, the first layer becomes the fabricated camera design, and the prototype demonstrates these tasks with only a few pixels while being powered and wirelessly read out using only ambient light.
Method
The authors leverage freeform pixels as the fundamental sensing element of a minimalist camera. A freeform pixel consists of an arbitrary optical mask placed in front of a photodetector, so the pixel records a learned weighted sum of the incoming scene rather than a fixed square region. The mask is described by a transmittance function M(x,y), where 0≤M(x,y)≤1. If the detector is modeled as infinitesimally small, its measurement is
p=∬x,yI(x,y)M(x,y)dxdy,where I(x,y) is the scene projection onto the mask plane. This formulation shows that each freeform pixel implements a linear projection of the scene, and a collection of such pixels can therefore be interpreted as the first linear layer of a task-specific vision system. Refer to the framework diagram.
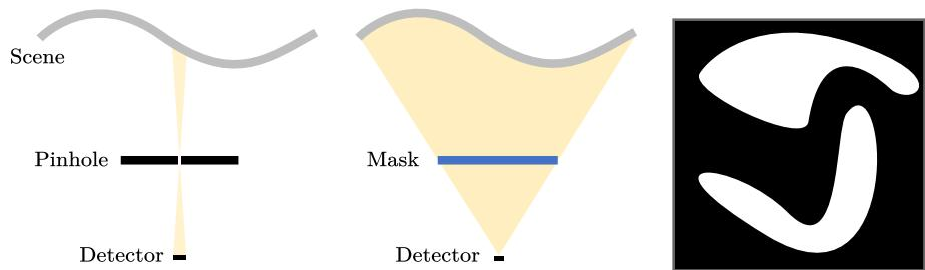
Because a freeform pixel performs a linear projection, the authors embed the entire camera model into a network. The optical masks form a fully connected layer without bias terms, and their outputs are passed to a downstream inference network that produces the final task prediction. During development, a conventional camera captures training scenes, and the combined optical and digital system is optimized end to end using task labels. After training, the learned mask weights can be fabricated as physical masks, for example by printing them onto a transparency film. In this formulation, a traditional square pixel is a special case in which every mask is a fixed box function. When the measurement budget is constrained, learned freeform masks can concentrate sensing effort on information relevant to the task.
A key part of the method is that the first layer is not treated as an unconstrained linear layer. The mask transmittance must be physical, the detector has directional response and finite active area, and its output is affected by gain, noise, and saturation. The authors incorporate these effects into the training process so that the learned masks remain deployable on real hardware. As shown in the figure below.
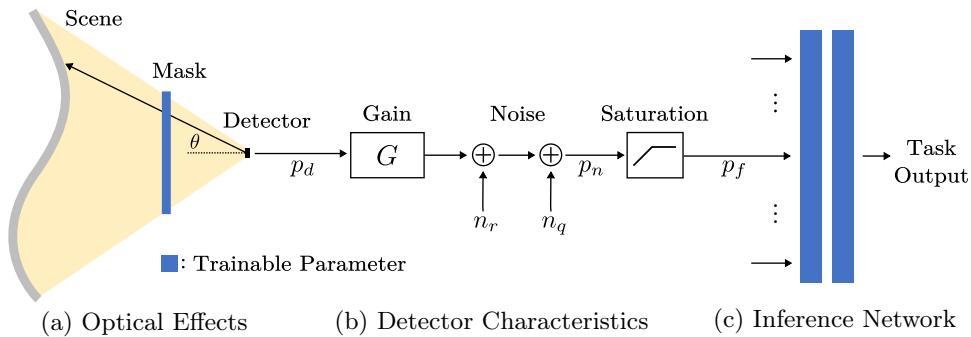
The detector directional response is modeled by d(x,y), and the finite active area is modeled by blurring the scene irradiance with a kernel b(x,y). The light energy reaching the detector is then
pd=∬x,y(I(x,y)∗b(x,y))M(x,y)d(x,y)dxdy.To keep the trainable mask bounded between 0 and 1, the authors define M(x,y)=σ(Mt(x,y)), where σ is the sigmoid function and Mt(x,y) are the trainable mask parameters. The detector stage is modeled with gain G, read noise nr, and quantization noise nq:
pn=Gpd+nr+nq.Since real detectors saturate, the authors apply a soft clipping operation to preserve gradients during training:
pf={pn,α(pn−pmax)+pmax,pn≤pmax,pn>pmax,where pmax is the detector saturation limit and α is a small positive slope. The resulting value pf is the physical output of one freeform pixel and becomes the input to the inference network. This differentiable sensor model is important because hardware effects such as limited dynamic range can strongly influence the final learned pixel shape.
The training pipeline therefore treats the camera and classifier as a single optimized system. The mask parameters are initialized, often with uniform noise, and the network is optimized with a task loss such as cross entropy. For counting or classification tasks, the inference network may be a small feedforward network operating directly on the pixel outputs. A conventional low resolution camera can serve as a baseline because it corresponds to the same architecture with fixed square masks. The learned freeform pixels, in contrast, use continuous and irregular transmittance patterns that can encode the task more compactly. Refer to the example results.
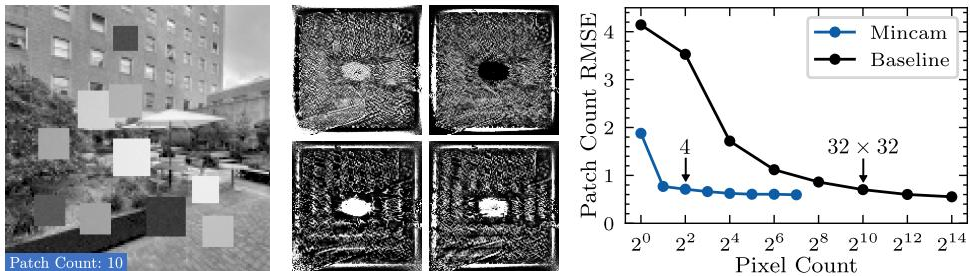
In the synthetic counting example, the authors train minimalist cameras with a growing number of freeform pixels. The learned four pixel configuration achieves accuracy comparable to a much larger traditional pixel array, illustrating the main design goal: use only the number of optical measurements required by the task. The learned masks also show how the optimization discovers spatial regions that are informative for the downstream inference network.
The hardware implementation follows the same optical and electrical model. The authors build a minimalist camera with a small array of photodiodes, one detector per freeform pixel. The learned masks are printed on a single transparent film and placed in front of the detector array. Each detector current is converted to voltage by a transimpedance amplifier, and the analog outputs are multiplexed and digitized by a microcontroller that transmits the measurements wirelessly. A conventional camera is co-located in the prototype during development and comparison, while the minimalist camera captures only its few learned projections. The hardware implementation is shown in the figure below.
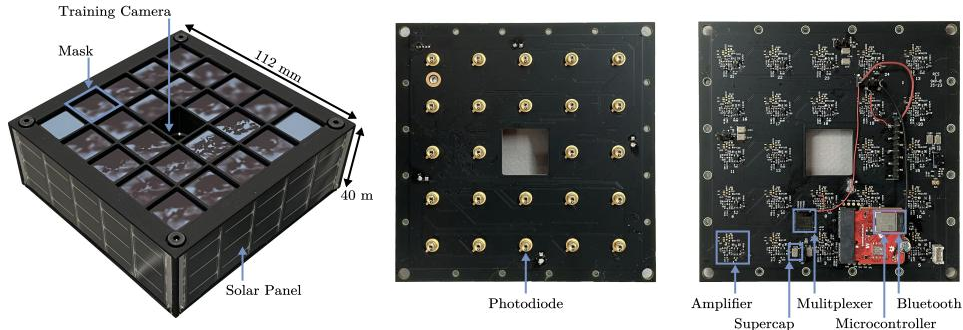
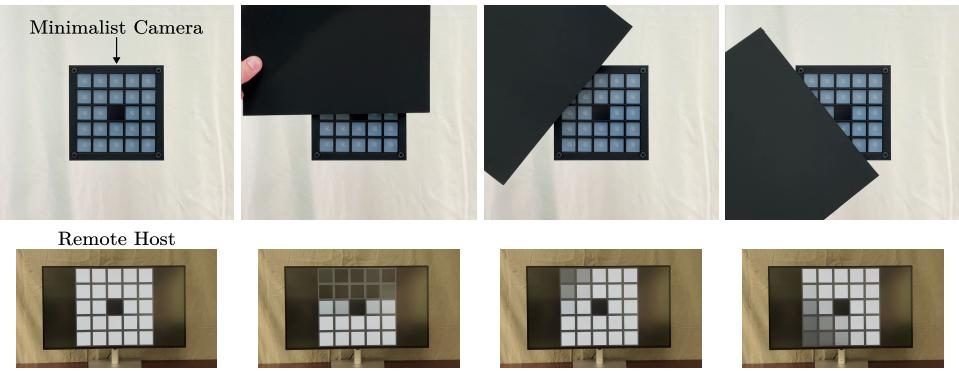
Because the camera produces only a few measurements, readout and wireless transmission require very little power. The prototype can therefore operate with energy harvesting rather than a battery or wired supply. Solar panels on the camera body charge a supercapacitor, enabling continuous operation in indoor lighting. This batteryless capability follows naturally from the minimalist sensing strategy, since fewer pixels reduce both sensing burden and energy demand. The operating demonstration is shown in the figure below.
Experiment
The experiments evaluate minimalist cameras using freeform pixels on a synthetic patch-counting task and several real lightweight vision applications, including workspace monitoring, room lighting estimation, and traffic speed estimation. Compared with traditional cameras, the learned freeform pixels can perform targeted sensing tasks with far fewer pixels and without needing conventional high-resolution images. The workspace monitoring results also suggest that the compressed measurements do not support meaningful face recognition, supporting privacy-friendly operation.