Command Palette
Search for a command to run...
CURE: تعزيز التعلم الموحّد القائم على النقد لتحسين الذات في وقت الاستدلال
CURE: تعزيز التعلم الموحّد القائم على النقد لتحسين الذات في وقت الاستدلال
Guirong Chen Shuqi Ye Wenkai Yang Shiqi Shen Guangyao Shen Yankai Lin
الملخص
يتحول نموذج التطور في نماذج اللغة الكبيرة (LLMs) من توسيع نطاق حساب التدريب إلى توسيع نطاق حساب وقت الاستدلال. وبينما أصبح التعزيز باستخدام المكافآت القابلة للتحقق (RLVR) محركًا رئيسيًا لهذا التحول، غالبًا ما تفشل الأساليب القياسية في تزويد النماذج بقدرات التحسين الذاتي المستقلة اللازمة لتوسيع نطاق وقت الاستدلال. وتحاول الأساليب الحالية الموجهة بالنقد التخفيف من هذه المشكلة بالاستفادة من التغذية الراجعة الخارجية أو الإشارات المرجعية الحقيقية؛ غير أن هذه الاعتماديات غير متاحة في وقت الاستدلال، مما يحد بشكل أساسي من قدرة النموذج على التحسين الذاتي المستمر. ولسد هذه الفجوة، نقترح CURE (التعلم المعزز الموحد القائم على النقد)، وهو إطار يعمل على تحسين سياسة واحدة بشكل مشترك للمهام القياسية، والنقد، وإعادة الاستكشاف الموجهة. وبشكل فريد، يسهل CURE إعادة الاستكشاف من خلال توليد تلميحات استراتيجية مع تجاهل الحلول الأولية غير الصحيحة للتخفيف من تحيز التثبيت. وتظهر النتائج التجريبية عبر معايير متنوعة للاستدلال الرياضي وتوليد الأكواد أن CURE لا يحافظ على أداء الجولة الواحدة التنافسي فحسب، بل والأهم من ذلك، يفتح آفاقًا فعالة لتوسيع نطاق وقت الاستدلال، مما يمكن النموذج من تعزيز الدقة بشكل ملحوظ من خلال التحسين الذاتي التكراري.
One-sentence Summary
Researchers from Renmin University of China and Tencent introduce CURE (Critique-driven Unified REinforcement Learning), a framework that jointly optimizes a single policy for solving, critiquing, and guided re-exploration, which generates strategic hints while discarding incorrect initial solutions to mitigate anchoring bias, enabling effective test-time self-improvement across diverse mathematical reasoning and code generation benchmarks.
Key Contributions
- CURE (Critique-driven Unified REinforcement Learning) is a framework that jointly optimizes a single policy for solving, critiquing, and guided re-exploration, enabling autonomous test-time self-improvement without external supervision.
- To mitigate anchoring bias, CURE generates high-level strategic hints while discarding initial incorrect solutions, then restarts reasoning from a fresh state conditioned only on those hints.
- Experiments on math and code benchmarks show competitive single-turn performance alongside effective inference-time scaling; on AIME25, CURE improves by 2.8% at the second turn and reaches a total gain of 4.2% through iterative self-improvement.
Introduction
The field of Large Language Models is shifting from scaling training-time compute to scaling test-time compute, where two paradigms have emerged: parallel scaling, which samples and evaluates multiple candidate solutions, and sequential scaling, which extends chain-of-thought reasoning through reinforcement learning with verifiable rewards. However, both approaches fall short of supporting human-like iterative refinement. Parallel scaling merely samples independent solutions without improving them, while sequential scaling models struggle with reliable self-verification and correction because these abilities are not explicitly optimized during training. Prior critique-guided methods attempt to address this by using external feedback, but they depend on stronger supervision that is impractical or on ground-truth signals that are unavailable at test time, breaking the self-improvement loop.
To bridge this gap, the authors propose CURE, a unified reinforcement learning framework that jointly optimizes three atomic capabilities within a single policy: solving, critiquing, and critique-guided re-exploration. A key design choice is that during re-generation, the model discards its initial incorrect solution and only conditions on high-level strategic hints, which mitigates anchoring bias and prevents repetition of previous mistakes. The authors integrate these capabilities into a unified RLVR pipeline, where solving is enhanced by replaying successful re-exploration trajectories, critiquing is optimized via supervised learning on verification judgments plus delayed accuracy-based rewards, and re-exploration is aligned to follow the generated hints. Experiments on math and code tasks show that CURE maintains competitive single-turn performance while achieving superior inference-time scalability, with a 4.2% total gain on AIME25 through iterative self-improvement. This work demonstrates that a self-contained improve loop can be instilled into LLMs without external dependencies.
Method
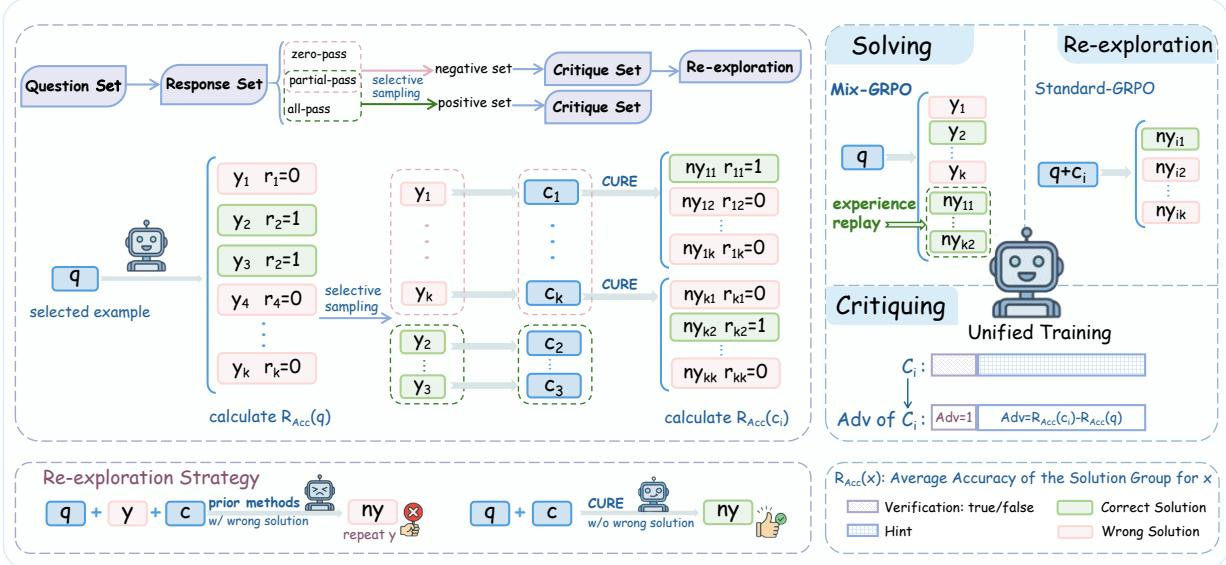
The authors propose the Critique-driven Unified REinforcement Learning (CURE) framework, which integrates solving, critiquing, and critique-guided re-exploration into a single unified policy. This design enables autonomous self-improvement by training the model to verify its own outputs and generate strategic hints, operating independently of external supervision. As illustrated in the framework diagram, the training process operates through an iterative online reinforcement learning loop that jointly optimizes these capabilities.
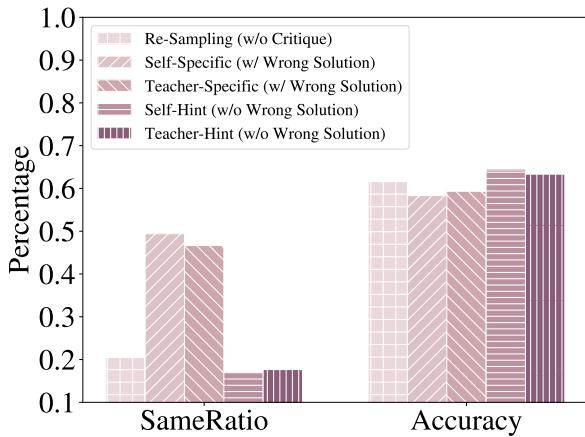
Each training iteration is divided into three distinct phases. In the initial solution generation phase, the policy samples a group of K responses for a given query and evaluates them using an outcome verifier to obtain binary rewards. Following this, the critique generation phase employs a selective sampling strategy to construct a critique batch. The system categorizes queries based on group-level accuracy, prioritizing zero-pass and partial-pass instances where the model either fails completely or exhibits inconsistency. To maintain training stability and prevent trivial verification patterns, the batch enforces a balanced ratio of correct and incorrect samples. For each selected sample, the model generates a critique comprising a verification judgment and a strategic hint. The third phase, critique-guided re-generation, utilizes the strategic hint as a scaffold for exploration. The system constructs a guided prompt by concatenating the original query with the generated hint, while deliberately discarding the initial incorrect solution. This approach mitigates anchoring bias, a common issue in self-correction paradigms where appending faulty reasoning traces leads to repetitive errors. As shown in the figure below, removing the incorrect context significantly reduces the repetition of wrong answers and improves overall re-generation accuracy.
To optimize the model, the authors formulate a unified training objective that combines standard solving, critiquing, and guided solving tasks using Group Relative Policy Optimization (GRPO). The solving objective incorporates an experience replay mechanism. Successful guided solutions from the re-exploration phase are selectively incorporated back into the initial solution group. This augmentation recalibrates the advantage function by elevating the group mean reward, thereby assigning strongly negative advantages to original incorrect solutions and positive advantages to replayed trajectories. The critique objective employs a hybrid advantage function that adapts to the token segments. For the verification segment, a fixed positive advantage is assigned, effectively transforming the task into supervised optimization to ensure accurate judgment grounding. For the hint segment, a centered advantage is calculated by subtracting the baseline average accuracy from the total critique reward. This contrastive signal only yields positive advantages when the hint leads to improved performance, effectively suppressing the generation of unhelpful text. Finally, the guided solving objective optimizes the policy to generate reasoning paths conditioned on the hints, ensuring compliance with the model's own strategic advice. The overall optimization computes advantages independently within each subtask group, averages the loss over generated tokens, and sums the task losses with equal weights to prevent destructive interference during joint training.
Experiment
CURE is evaluated across mathematical reasoning and code generation using instruction-tuned and base models against a GRPO baseline, with a unified training setup for both domains. The approach matches or slightly improves single-turn accuracy, but its main strength is enabling effective inference-time self-improvement, where iterative refinement yields sustained gains over the baseline, which tends to stagnate. Analysis shows CURE gradually converts hard failures into successes during training, and ablations confirm that both verification and hint optimization are critical for scaling, while replaying only successful guided solutions from previously zero-pass groups provides the best stability and performance.
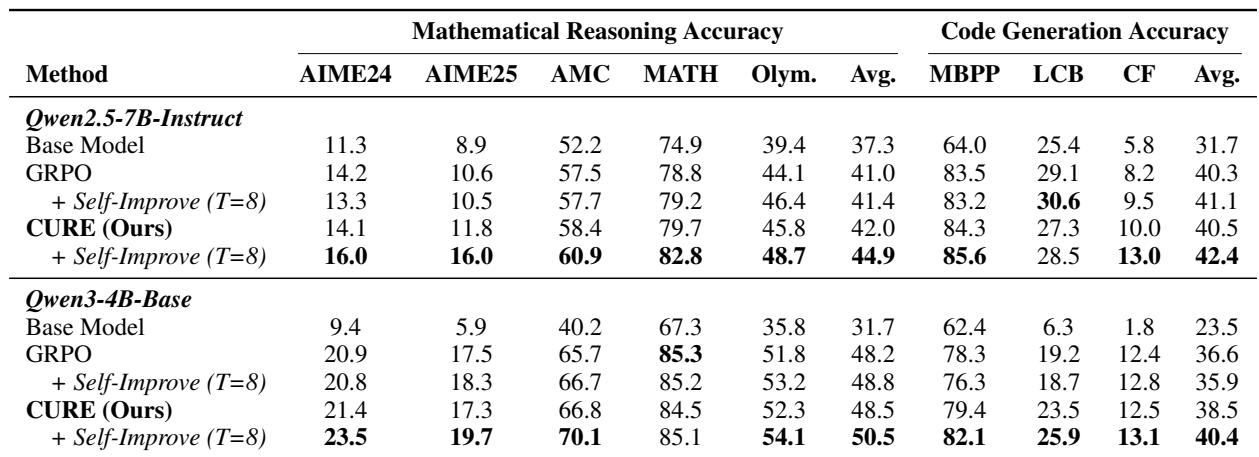
CURE achieves comparable or better single-turn accuracy than the GRPO baseline across math and code benchmarks, and its main advantage is a sustained boost from inference-time self-improvement. On Qwen2.5-7B-Instruct, iterative self-improvement raises CURE's average math accuracy from 42.0% to 44.9%, surpassing the baseline's scaling ceiling. The gains are domain-agnostic, with notably larger improvements on CodeForces compared to GRPO. CURE improves average math accuracy from 42.0% to 44.9% with self-improvement, exceeding the GRPO baseline's ceiling of 41.4%. On CodeForces, CURE gains +3.0% from self-improvement versus only +1.3% for GRPO, indicating stronger test-time scaling. CURE maintains competitive single-turn accuracy while enabling effective iterative refinement across both mathematical and coding tasks.
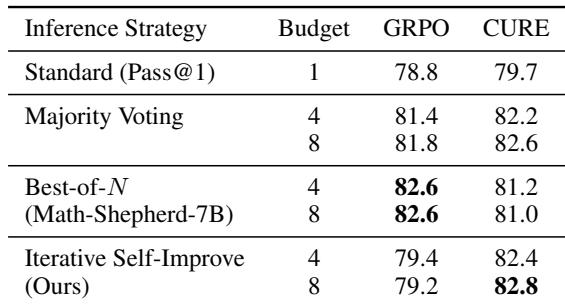
CURE consistently outperforms GRPO under standard decoding, majority voting, and iterative self-improvement across matched budgets. However, with Best-of-N using an external reward model, CURE's performance drops below GRPO, likely due to distribution shift in the reward model. Iterative self-improvement with CURE achieves the highest accuracy at the largest budget. CURE improves over GRPO at both budget levels for majority voting and iterative self-improvement. Under Best-of-N with Math-Shepherd-7B, CURE underperforms GRPO, with accuracy declining as budget increases. The best overall result is CURE with iterative self-improvement at budget 8, reaching 82.8%.
Under the same maximum generation budget, CURE with iterative self-improvement achieves slightly higher accuracy than GRPO with Best-of-N while using far fewer generated tokens and comparable latency. This suggests that CURE allocates additional inference-time computation toward efficient self-refinement rather than increased parallel sampling. CURE's iterative refinement yields marginally better accuracy than Best-of-N with an external reward model. CURE generates substantially fewer tokens than Best-of-N, yet latency remains nearly identical in this setup. The token efficiency advantage indicates a more effective conversion of compute into targeted improvement.
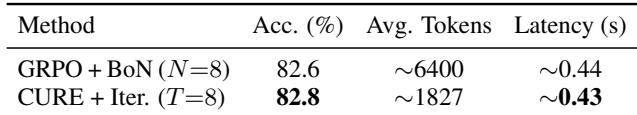
CURE matches or exceeds the GRPO baseline on single-turn math and code tasks while delivering a substantial boost through inference-time self-improvement, raising average math accuracy from 42.0% to 44.9% versus GRPO's 41.4% ceiling and showing stronger gains on CodeForces. Across controlled budgets, CURE outperforms GRPO under standard decoding, majority voting, and iterative self-improvement, though it falls behind under Best-of-N with an external reward model due to distribution shift, with iterative self-improvement at budget 8 yielding the best overall result (82.8%). Additionally, CURE achieves comparable or better accuracy than GRPO with Best-of-N while generating far fewer tokens and similar latency, indicating that its compute is used for efficient self-refinement rather than expanded parallel sampling.