Command Palette
Search for a command to run...
الانتباه المتفرق الأصلي: آلية انتباه متفرقة متوافقة مع العتاد وقابلة للتدريب أصليًا
الانتباه المتفرق الأصلي: آلية انتباه متفرقة متوافقة مع العتاد وقابلة للتدريب أصليًا
الملخص
يُعد نمذجة السياقات الطويلة أمرًا بالغ الأهمية لنماذج اللغة من الجيل التالي، إلا أن التكلفة الحسابية العالية لآليات الانتباه القياسية تُشكّل تحديات حسابية كبيرة. يُقدّم الانتباه المتفرق اتجاهًا واعدًا لتحسين الكفاءة مع الحفاظ على قدرات النموذج. نقدّم في هذا العمل آلية NSA، وهي آلية انتباه متفرقة قابلة للتدريب أصليًا تجمع بين الابتكارات الخوارزمية والتحسينات المتوافقة مع العتاد لتحقيق نمذجة فعّالة للسياقات الطويلة. تعتمد NSA على استراتيجية انتقاء متفرق هرمية ديناميكية تجمع بين الضغط الخشن للرموز والانتقاء الدقيق لها، مما يحافظ على الوعي بالسياق العام والدقة الموضعية في آنٍ واحد. يُعزّز نهجنا تصميم الانتباه المتفرق عبر ابتكارين رئيسيين: (1) تحقيق تسريع جوهري من خلال تصميم خوارزمي متوازن من حيث الشدة الحسابية، مع تحسينات تنفيذية مصمّمة خصيصًا للعتاد الحديث. (2) تمكين التدريب من البداية إلى النهاية، مما يقلل من تكلفة التدريب المسبق دون المساس بأداء النموذج. وكما هو موضح في الشكل 1، تُظهر التجارب أن النموذج المُدرَّب مسبقًا باستخدام NSA يُحافظ على أداء النماذج ذات الانتباه الكامل أو يتفوق عليها عبر المعايير العامة، ومهام السياقات الطويلة، والاستدلال المبني على التعليمات. وفي الوقت نفسه، تحقق NSA تسريعًا كبيرًا مقارنةً بالانتباه الكامل على تسلسلات بطول 64k عبر فك الترميز والانتشار الأمامي والانتشار الخلفي، مما يؤكد كفاءتها طوال دورة حياة النموذج.
One-sentence Summary
Peking University, DeepSeek-AI, and University of Washington propose NSA, a natively trainable sparse attention mechanism that uses a dynamic hierarchical strategy combining coarse-grained token compression with fine-grained token selection to enable end-to-end training and achieve substantial speedups over Full Attention on 64k-length sequences while maintaining or exceeding performance across general and long-context benchmarks.
Key Contributions
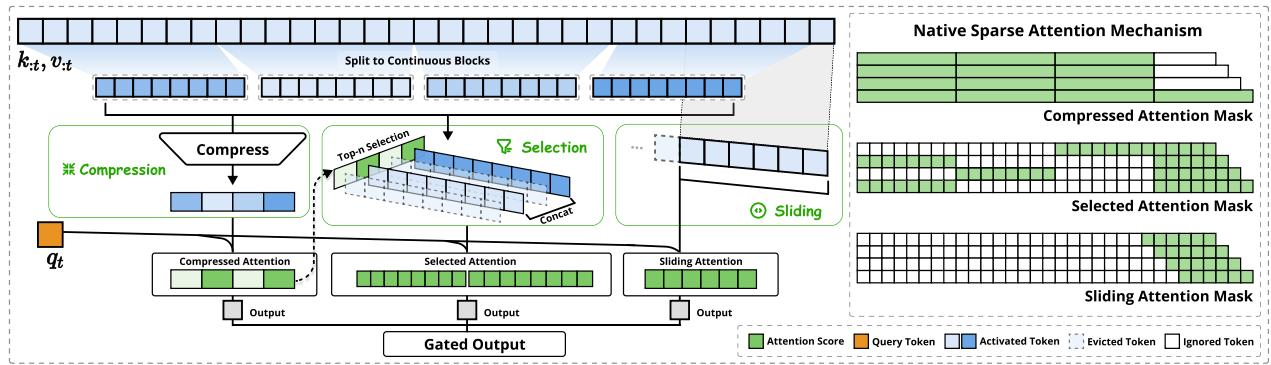
- NSA is a natively trainable sparse attention mechanism for long-context modeling that organizes keys and values into temporal blocks and combines compressed coarse-grained tokens, selected fine-grained tokens, and sliding windows.
- It introduces a hardware-aligned blockwise sparse attention design with specialized kernels for balanced arithmetic intensity and memory access, along with trainable forward and backward operators for stable end-to-end training and reduced pretraining computation.
- Experiments on a 27B-parameter transformer pretrained with 260B tokens show NSA matches or exceeds full attention on general, long-context, and reasoning benchmarks while achieving increasing speedups over full attention at 64k-length sequences on A100 GPUs.
Introduction
Long context modeling is increasingly important for large language models because applications such as repository-level code generation, document understanding, reasoning, and autonomous agents require coherent processing over thousands or tens of thousands of tokens. Softmax attention is effective for these long-range dependencies, but its computational cost grows quickly and can dominate decoding latency for very long sequences.
Prior sparse attention methods aim to exploit the inherent sparsity of attention through techniques such as KV cache eviction, blockwise selection, sampling, clustering, and hashing. However, these methods often do not translate theoretical reductions into real hardware speedups, and many lack training-time support needed for stable end-to-end model training.
The authors introduce NSA, a natively trainable sparse attention architecture that organizes keys and values into hierarchical token blocks and uses compressed coarse-grained tokens, selected fine-grained tokens, and sliding windows for local context. They also design hardware aligned kernels and trainable operators so that sparse attention can accelerate both inference and training while matching or surpassing full attention performance.
Method
The authors design NSA as a natively trainable sparse attention mechanism that addresses two bottlenecks in long-context language modeling: the quadratic attention computation in training and prefilling, and the memory-bound key-value access pattern in decoding. Starting from standard causal self-attention, the output for query token qt is
ot=Attn(qt,k:t,v:t),where
Attn(qt,k:t,v:t)=∑j=1tαt,j∑i=1tαt,ivi,αt,i=exp(dkqt⊤ki).The design relies on the observation that attention computation and memory access dominate different execution phases. During training and prefilling, batched attention operations have high arithmetic intensity and are usually compute-bound. During auto-regressive decoding, only one new token is generated per forward pass, but the full key-value cache must be accessed, causing low arithmetic intensity and memory bandwidth constraints. NSA therefore reduces computation in dense attention phases while reducing memory traffic during decoding.
The core idea is to replace the full preceding key-value memory k:t,v:t with compact, information-dense representations constructed for each query:
K~t=fK(qt,k:t,v:t),V~t=fV(qt,k:t,v:t).Instead of attending to every past token, NSA constructs several categories of remapped key-value pairs and aggregates their outputs with learned gates:
ot∗=c∈C∑gtc⋅Attn(qt,K~tc,V~tc),where C={cmp,slc,win} denotes compression, selection, and sliding-window branches. The total number of remapped keys and values is
Nt=c∈C∑size[K~tc],and the design maintains high sparsity by ensuring Nt≪t. The overall architecture is presented in the framework diagram below:
The first branch is token compression. It aggregates temporally consecutive blocks of keys and values into block-level representations. For block length l and sliding stride d, the compressed key branch is
fKcmp(k:t)={ϕ(kid+1:id+l)1≤i≤⌊dt−l⌋},where ϕ is a learnable MLP with intra-block positional encoding that maps a block of keys into a single compressed key. The corresponding compressed values are produced in an analogous way. When d<l, adjacent blocks overlap, which mitigates information fragmentation caused by rigid non-overlapping chunking. This branch captures coarse-grained semantic patterns while substantially reducing the attention sequence length.
The second branch is token selection. Because compressed representations may lose fine-grained information, NSA selectively preserves a small number of original token blocks. Selection is blockwise rather than tokenwise, both for hardware efficiency and because attention importance often exhibits spatial continuity. Blockwise memory access and computation better align with modern GPU behavior, enabling dense reads and better utilization of Tensor Core operations.
To avoid extra overhead from scoring every selection block, NSA derives selection block importance from the attention scores computed over compressed keys:
ptcmp=Softmax(qt⊤K~tcmp).If compression blocks and selection blocks share the same blocking scheme, the compression attention scores can directly serve as selection block importance scores. Otherwise, importance is aggregated according to the spatial relationship between selection blocks and compression blocks. For grouped-query attention or multi-query attention, scores are also summed across query heads sharing the same key-value group:
ptslc′=h=1∑Hptslc,(h).The top-n selection set is then
It={i∣rank(ptslc′[i])≤n}.The selected keys are concatenated as
K~tslc=Cat[{kil′+1:(i+1)l′∣i∈It}],with an analogous construction for V~tslc. This retained subset participates in fine-grained attention while evicting less relevant tokens from the computation.
The third branch is a sliding window. Local context often adapts rapidly and can dominate learning if handled implicitly. NSA therefore isolates recent tokens in a dedicated branch:
K~twin=kt−w:t,V~twin=vt−w:t.Separating local attention from compression and selection reduces shortcut learning, where the model could rely heavily on nearby tokens and under-utilize long-range sparse patterns. The output uses independent key-value projections for each branch and a learned gating mechanism derived from input features via an MLP and sigmoid activation. This supports stable end-to-end training by reducing gradient interference between local, coarse-grained, and fine-grained information pathways.
The hardware implementation focuses on the sparse selection branch, since compression and sliding-window attention can reuse existing efficient kernels for GQA and MQA architectures. For sparse selection, standard FlashAttention-style loading of temporally contiguous query blocks can be inefficient because queries in the same block may require disjoint KV blocks. The kernel therefore uses a group-centric loading strategy. For each position t, it loads all queries in a GQA group, Q∈R[h,dk], together with their shared selected KV block indices It. The inner loop then sequentially fetches continuous key and value blocks indexed by It into SRAM, where the kernel block size Bk divides the selection block size l′. Query and output loops are scheduled on the grid because the inner-loop length is approximately constant across query blocks. The kernel organization is presented in the figure below:
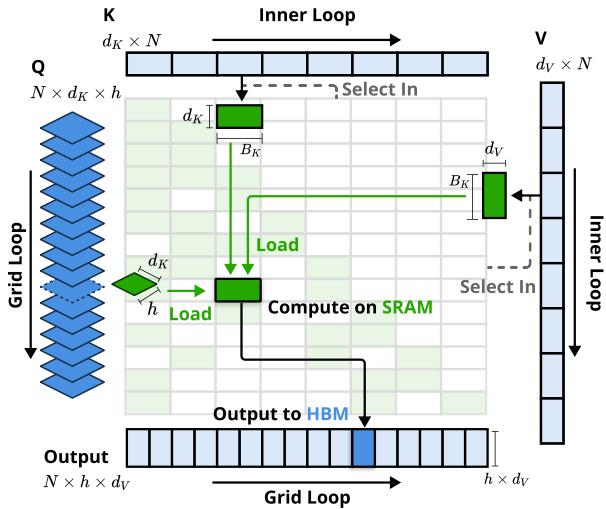
This kernel design reduces redundant KV cache movement by sharing the same selected blocks across all query heads in a GQA group. It also balances streaming multiprocessor workloads and increases effective arithmetic intensity. By combining hierarchical compression, blockwise selection, sliding-window attention, learned gating, and group-centric hardware execution, the method converts theoretical sparsity into practical speedups during both compute-bound and memory-bound phases.
Experiment
Experiments evaluate NSA against Full Attention and sparse attention baselines on general, long-context, reasoning, and efficiency settings using a large GQA-MoE model. NSA remains competitive on standard benchmarks, with notable reasoning gains, and its hierarchical sparse attention enables robust long-context retrieval and superior performance on long-context tasks. After mathematical reasoning fine-tuning, NSA outperforms the Full Attention baseline, suggesting that sparse attention can preserve long-range logical dependencies. Efficiency analyses show that NSA achieves increasingly pronounced training and decoding speedups as context length grows.
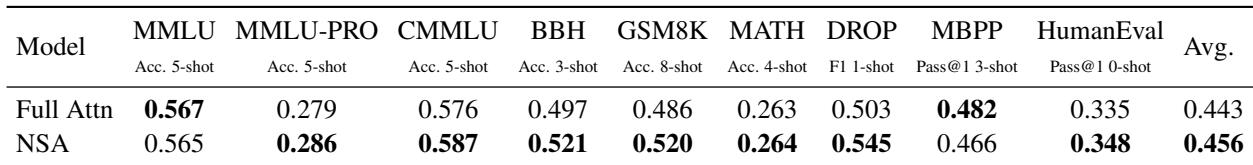
Across knowledge, reasoning, and coding benchmarks, NSA improves the overall average over Full Attention while operating with high sparsity. It outperforms the dense baseline on most individual tasks, with particularly clear gains on reasoning benchmarks, while remaining close on coding tasks and slightly below the baseline on MMLU and MBPP. NSA gives a higher average score than Full Attention despite using sparse attention The largest relative gains appear on reasoning tasks such as DROP and GSM8K, suggesting effective learning of important context information
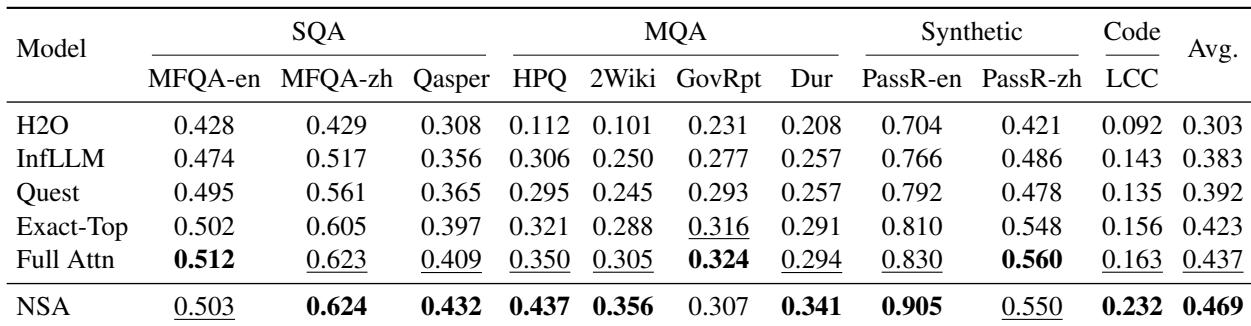
NSA obtains the strongest overall LongBench average among the evaluated sparse attention baselines and Full Attention. The advantage is driven by long-context reasoning tasks, especially multi-hop question answering, code understanding, and passage retrieval, although some single-document QA results remain close to or slightly behind Full Attention. NSA reaches the highest overall LongBench score across all compared methods. The largest qualitative gains appear on multi-hop QA, passage retrieval, and code tasks. Full Attention remains competitive on some single-document QA subsets, so NSA's strength is most visible in harder long-context settings.
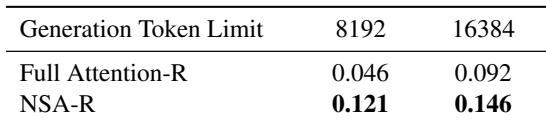
After supervised fine-tuning with mathematical reasoning traces, NSA-R attains higher average accuracy on AIME than the Full Attention-R baseline under both short and extended generation limits. The sparse variant shows a clear advantage for reasoning, with the gain being most pronounced at the 8k limit and still sustained at 16k. NSA-R outperforms Full Attention-R on AIME after supervised fine-tuning. The sparse variant achieves a larger relative improvement at the shorter generation limit. The performance advantage remains present when the generation limit is extended.
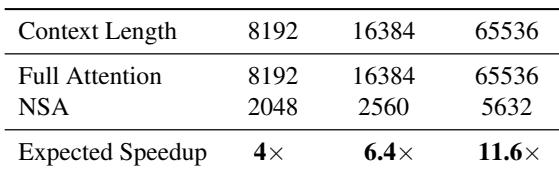
The decoding analysis estimates memory access volume in token equivalents and shows that the sparse attention method accesses far fewer tokens than full attention across increasing context lengths. Because decoding is memory-bound, this reduced KV cache loading is expected to translate into proportionally larger speedups as sequence length grows. The advantage becomes especially pronounced at long contexts, where the sparse method approaches an order of magnitude speedup. Memory access volume stays much lower than full attention as context length increases. Expected decoding speedup grows with longer sequences, reaching roughly twelvefold at the longest tested context.
Experiments evaluated Native Sparse Attention on standard knowledge, reasoning, and coding benchmarks, long-context LongBench tasks, and math reasoning after supervised fine-tuning, alongside a decoding memory-access analysis. NSA generally achieves stronger overall performance than full attention while remaining sparse, with the clearest gains on reasoning and harder long-context tasks, though it is close to or slightly below full attention on some coding and single-document QA cases. The fine-tuned sparse variant also outperforms its dense counterpart on mathematical reasoning across different generation limits. Decoding analysis shows that NSA accesses far fewer tokens than full attention, yielding especially large expected speedups as context length grows.