Command Palette
Search for a command to run...
تمثيلات الكلمات هي موجِّهات لنماذج اللغة
تمثيلات الكلمات هي موجِّهات لنماذج اللغة
Chi Han Jialiang Xu Manling Li Yi Fung Chenkai Sun Nan Jiang Tarek Abdelzaher Heng Ji
الملخص
تتعلَّم نماذج اللغة (LMs) تمثيلات الكلمات تلقائيًا أثناء التدريب المسبق على مدونات لغوية. وعلى الرغم من أن تمثيلات الكلمات تُفسَّر عادةً على أنها متجهات خصائص للكلمات الفردية، فإن أدوارها في توليد نماذج اللغة لا تزال غير مدروسة بما يكفي. في هذا العمل، نعيد النظر نظريًا وتجريبيًا في تمثيلات الكلمات على مستوى المخرجات، ونجد أن تحويلاتها الخطية مكافئة لتوجيه أنماط توليد نماذج اللغة. نُسمِّي هذه الموجِّهات LM-Steers، ونجد أنها موجودة في نماذج اللغة بجميع أحجامها. ويتطلب ذلك تعلُّم معاملات تعادل 0.2% من حجم نموذج اللغة الأصلي لتوجيه كل نمط. ففي مهام مثل إزالة السمية من نماذج اللغة والتحكم في المشاعر، يمكن لـ LM-Steers تحقيق أداء مماثل أو متفوق مقارنة بأحدث أساليب التوليد المُتحكَّم به، مع الحفاظ على توازن أفضل مع جودة التوليد. تعمل موجِّهات LM-Steers المُتعلَّمة كعدسة على أنماط النصوص؛ فهي تكشف أن تمثيلات الكلمات قابلة للتفسير عند ربطها بتوليدات نماذج اللغة، ويمكنها إبراز المقاطع النصية الأكثر دلالة على اختلافات الأنماط. كما يمكن نقل موجِّه LM-Steer بين نماذج لغة مختلفة عبر حساب بالصيغة الصريحة. ويمكن أيضًا توجيه نماذج اللغة بشكل مستمر ببساطة من خلال تحجيم موجِّه LM-Steer أو تكوين عدة موجِّهات LM-Steers بإضافة تحويلاتها. أكوادنا متاحة للعامة على الرابط https://github.com/Glaciohound/LM-Steer.
One-sentence Summary
Researchers at University of Illinois Urbana-Champaign introduce LM-Steers, which leverage the finding that linear transformations of output word embeddings are equivalent to steering language model generation styles, requiring only 0.2% of the original parameters while achieving comparable or superior detoxification and sentiment control performance to state-of-the-art methods without sacrificing generation quality.
Key Contributions
- The paper introduces LM-Steers as theoretically and empirically supported linear transformations of output word embeddings that steer language model generation styles, with the phenomenon observed across language models of different sizes and each style learned using parameters equal to 0.2% of the original model size.
- On language model detoxification and sentiment control tasks, LM-Steers achieve comparable or superior performance to state-of-the-art controlled generation methods while maintaining a better balance between control effectiveness and generation quality.
- Learned LM-Steers can be transferred to other language models through an explicit-form calculation, support continuous and compositional control by scaling or adding transformations, and reveal interpretable style differences and text spans in associated generations.
Introduction
Language models rely on learned word embeddings to determine the probability of each next token, making these embeddings central to understanding and guiding generation in tasks such as detoxification, sentiment control, and personalized text production. Prior work has mostly interpreted embeddings at the word level or uses control methods that are costly, classifier-dependent, prompt-sensitive, or limited in flexibility and transferability. The authors leverage a simple linear transformation of output word embeddings, called LM-Steer, to directly link embedding dimensions with generation styles. This approach enables efficient, interpretable, compositional, and transferable control over language model generation without retraining the full model.
Method
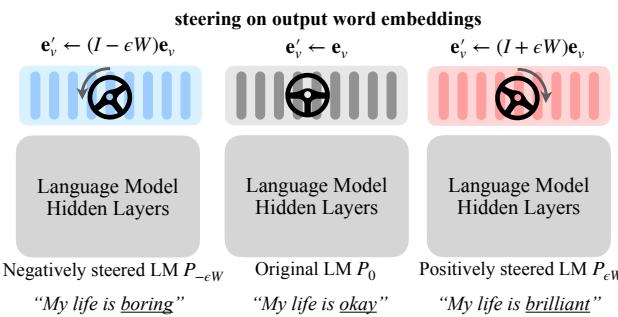
The authors leverage a theoretical observation that, under certain assumptions, changing the generation style of a language model can be represented as a linear transformation in the output word embedding space. This insight leads to LM-Steer, a lightweight and architecture-agnostic steering module that keeps the base language model frozen and applies a learned linear transformation only to the final word embeddings. The framework contains three functional views: embedding adaptation, supervised steering training, and controlled generation. As shown in the figure below:
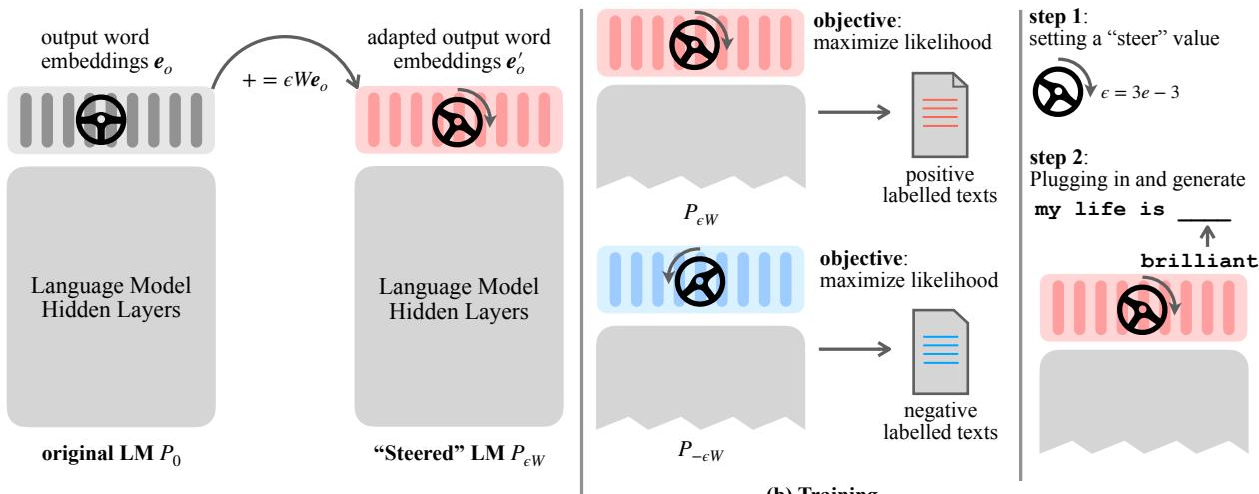
Let ev denote the original output word embedding of token v. LM-Steer replaces it with an adapted embedding ev′ by adding a style-dependent perturbation. This is written as
ev′=ev+ϵWev=(I+ϵW)ev.Here, W is the learnable steering matrix, and ϵ is a scalar that controls both the polarity and the intensity of the steering. A positive ϵ and a negative ϵ steer generation in opposite directions. The base language model is fixed, while W is the only trained parameter. The authors also use a small default steering magnitude, ϵ0=10−3, because small values are sufficient to induce controlled style shifts without destabilizing the underlying model.
The design can also be interpreted at the logit level. For a context vector c, the original LM computes a logit proportional to c⊤ev. After steering, the logit becomes
c⊤ev′=c⊤ev+ϵc⊤Wev.This means the steering matrix introduces a context-dependent adjustment through the bilinear term c⊤Wev. Unlike a static token blacklist or a global logit offset, this adjustment varies with the context, which gives LM-Steer greater expressive power over distribution shifts.
Training is simple and likelihood based. The authors instantiate a steered model PϵW by applying the transformed embeddings to the original LM. For positive style examples, PϵW is trained to maximize likelihood on positively labeled text. If negatively labeled examples are available, the negatively steered model P−ϵW is trained on them. In effect, W learns directions in the word embedding space that separate the desired style distribution from the opposite style distribution, so that changing the sign or magnitude of ϵ changes the relative preference among candidate tokens during decoding.
At generation time, no iterative generation procedure or external controller is required. The user selects a steering value ϵ, plugs the steered embeddings into the fixed LM, and performs normal decoding. This keeps the generation pipeline efficient and makes the method easy to integrate with different decoder architectures.
The linearity of the transformation also supports fine-grained compositional control. Because steering is defined by ϵW, users can interpolate or extrapolate across style levels by varying ϵ continuously. If two steering matrices are learned for different styles, their effects can also be combined additively. For two steers (ϵ1,W1) and (ϵ2,W2), generation can be conditioned by the summed steering matrix ϵ1W1+ϵ2W2, enabling simultaneous control over multiple stylistic factors.
A further system-level property of LM-Steer is transferability. If the embedding spaces of two language models are related by a linear mapping H, then a steering matrix learned in one model can be transported to another. Suppose source-space embeddings and context vectors are expressed in terms of target-space embeddings as ev=Hev′ and c=Hc′. Then the steering term transforms as
c⊤Wev=(Hc′)⊤W(He′)=c′⊤(H⊤WH)ev′.Therefore, the transferred steering matrix for the target model is H⊤WH. This allows the authors to reuse a learned steer across models of different sizes and parameterizations without retraining the full steering matrix from scratch. Refer to the following diagram for transferability and data efficiency trends:
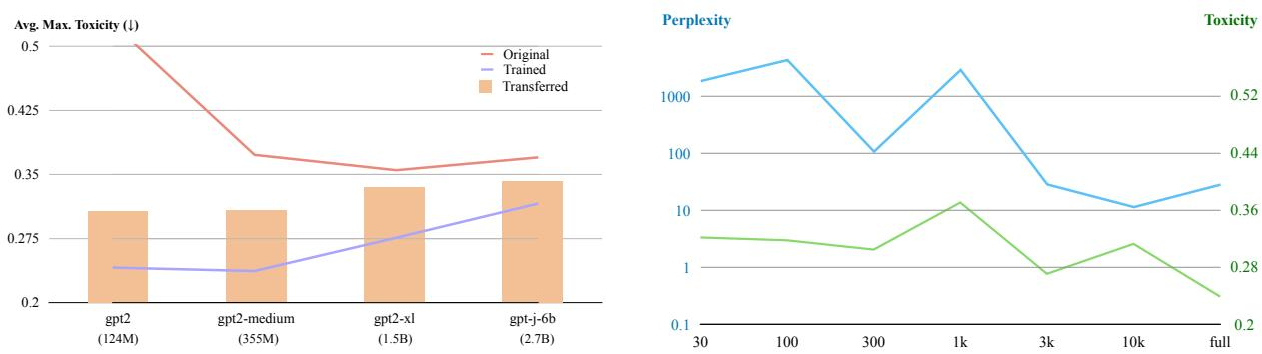
Because only a small output embedding transformation is learned, the module is parameter efficient and lightweight. The base model remains unchanged, and the added computation during decoding is limited to a dense transformation of the output embeddings. This design also reduces the supervision burden, since the learnable steering subspace is much smaller than the full model, allowing meaningful style control even with limited labeled data.
Experiment
The experiments evaluate LM-Steer on language detoxification and sentiment control across multiple pre-trained models, comparing it with classifier-guided, fine-tuning, and decoding baselines on toxicity and sentiment metrics as well as generation quality. Results show that LM-Steer achieves strong steering performance while preserving fluency and diversity, supports smooth continuous and compositional control, and remains efficient with few training samples and low decoding overhead. Additional analysis confirms that a steering module can be transferred across model scales through embedding-space mapping, giving broad applicability and robustness.
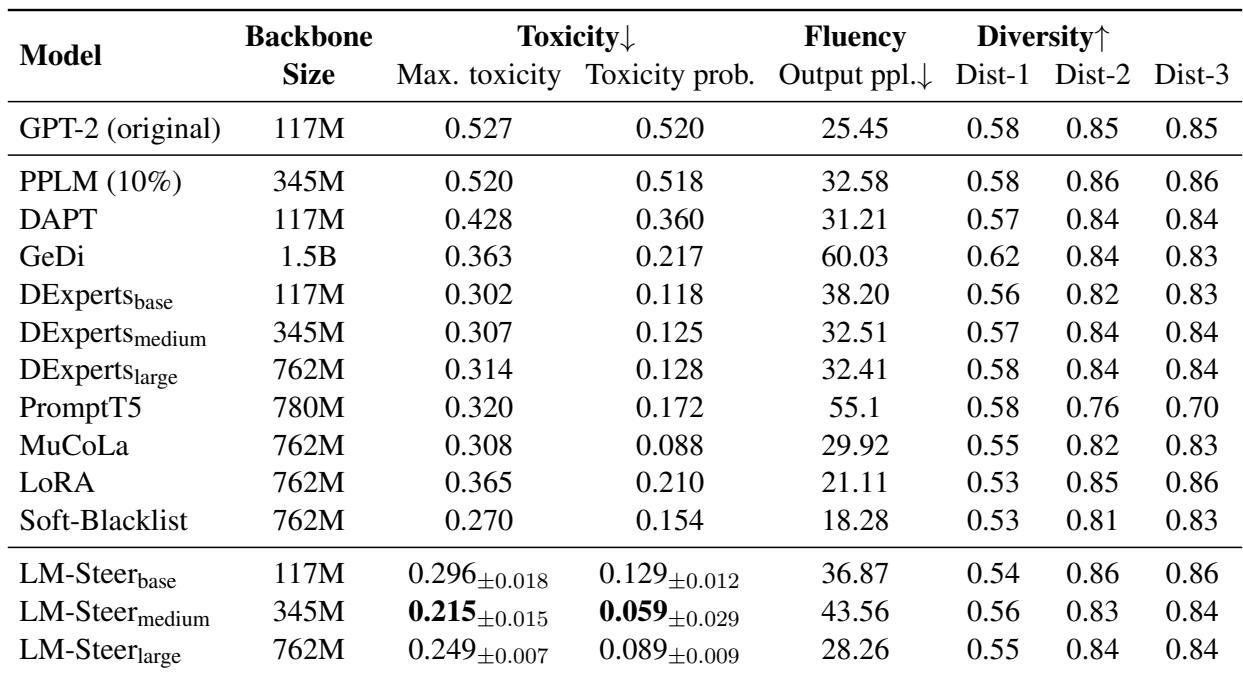
In language model detoxification, LM-Steer is reported as the best-performing method among the evaluated approaches. The baselines show a common trade-off, where stronger toxicity reduction is often accompanied by higher perplexity and less stable fluency. Toxicity metrics separate the methods more clearly than diversity metrics, which remain broadly similar. LM-Steer is described as achieving the best detoxification performance. PPLM provides little toxicity improvement over the original model while reducing fluency. DAPT and DExperts reduce toxicity more clearly than PPLM, with visible fluency costs. Diversity scores stay relatively comparable across methods, suggesting toxicity and fluency are the main distinguishing dimensions.
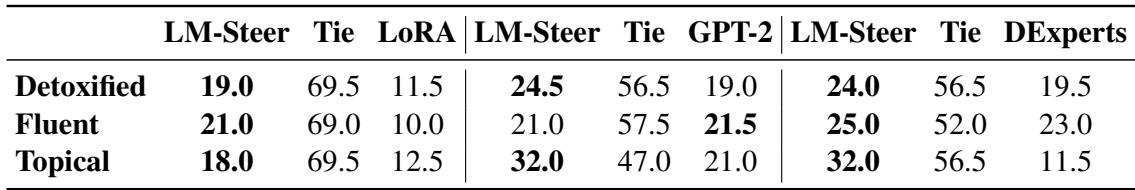
Human evaluators generally preferred LM-Steer over LoRA and DExperts across detoxification, fluency, and topicality. Compared with GPT-2, LM-Steer appeared stronger for detoxification and topicality, while fluency remained comparable. LM-Steer was rated better than LoRA on all three human evaluation metrics. LM-Steer was rated better than DExperts on all three metrics, especially topicality. LM-Steer outperformed GPT-2 on detoxification and topicality, with similar fluency.
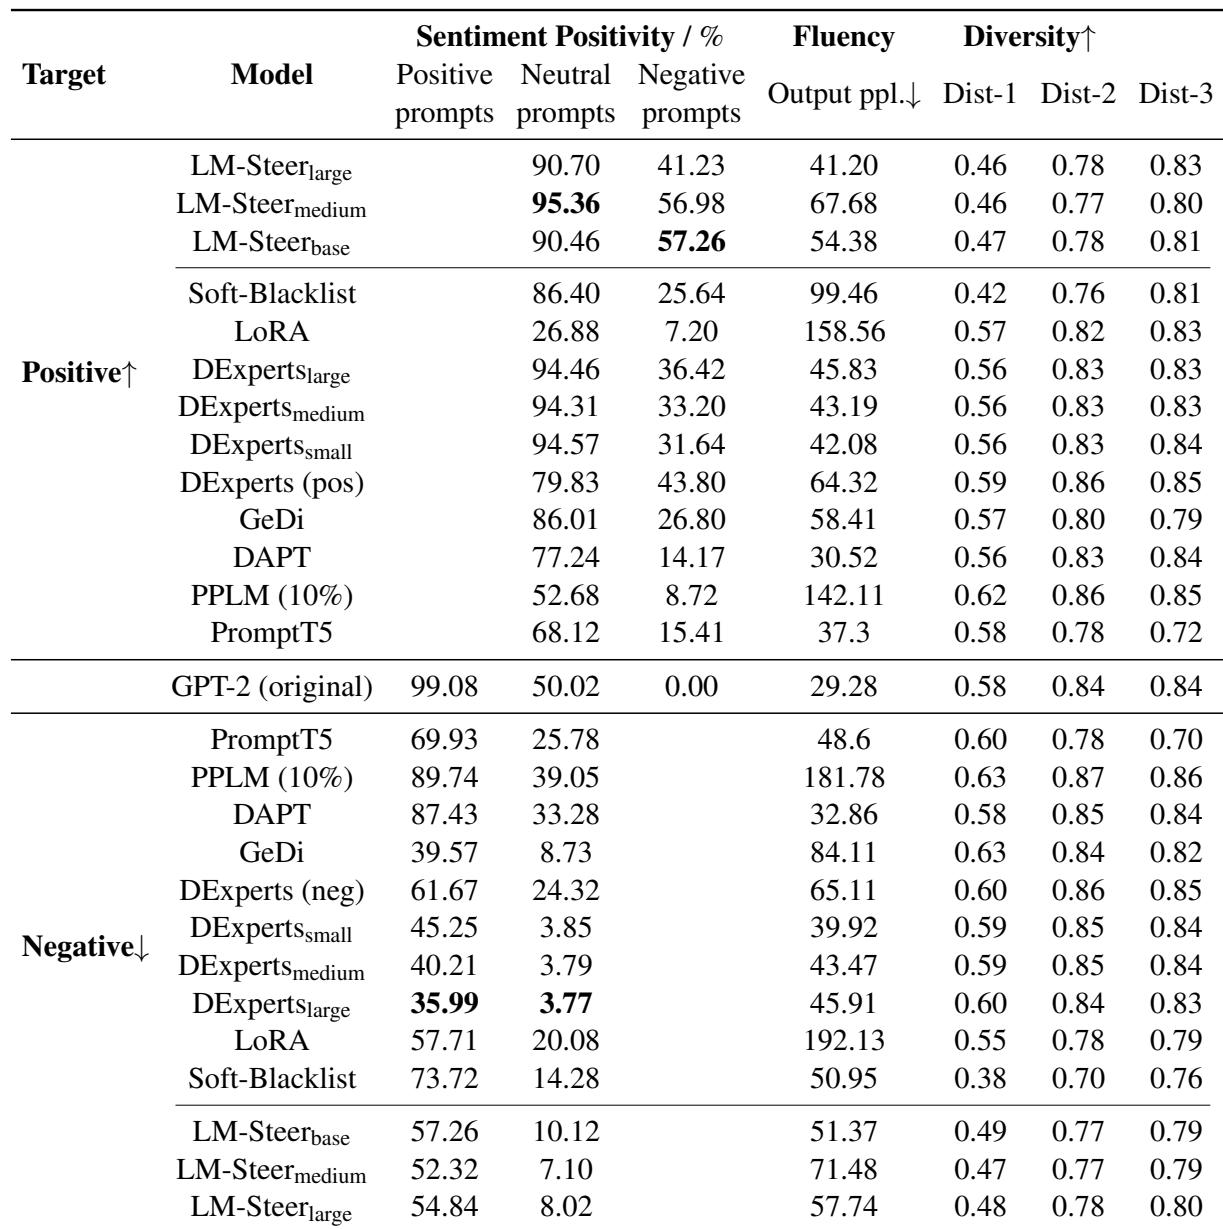
LM-Steer shows the strongest positive sentiment control among the compared models, especially on prompts that favor positive generations, despite its simpler and smaller design. It remains competitive with larger expert-based baselines and maintains relatively good fluency compared with LoRA and Soft-Blacklist. On negative-side control, it stays near the top of the compared models but does not consistently lead. LM-Steer achieves the best positive sentiment control on positive prompts in the positive-side setting. It offers lower perplexity than LoRA and Soft-Blacklist, suggesting better fluency in the positive control case. It remains a strong option for negative sentiment control, ranking near the top rather than dominating the other side.
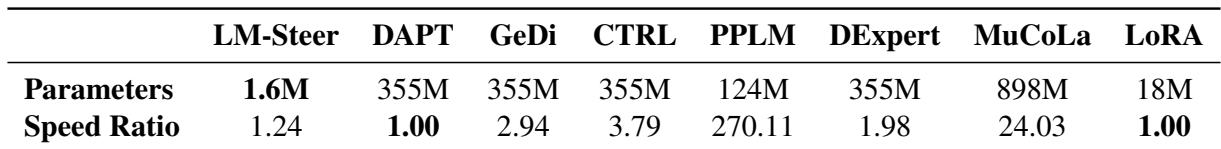
The comparison shows that LM-Steer is highly parameter efficient, using far fewer learnable parameters than most steering baselines. Its decoding overhead is modest, with speed close to the base language model. Methods with larger parameter costs or slower decoding, such as PPLM and MuCoLa, are less efficient on both measures. LM-Steer uses much smaller parameter budgets than most compared methods. LM-Steer's decoding time remains close to the base language model speed. PPLM and MuCoLa show substantially higher decoding overhead than LM-Steer.
Increasing the steering value produces a continuous shift in generated text from clearly toxic content to more neutral content. The example generations show that both the amount of toxic wording and its intensity become lower as the steering value moves from negative to positive. Negative steering values produce more explicit toxic or insulting phrasing. Positive steering values yield generations with fewer and less intense toxic words.
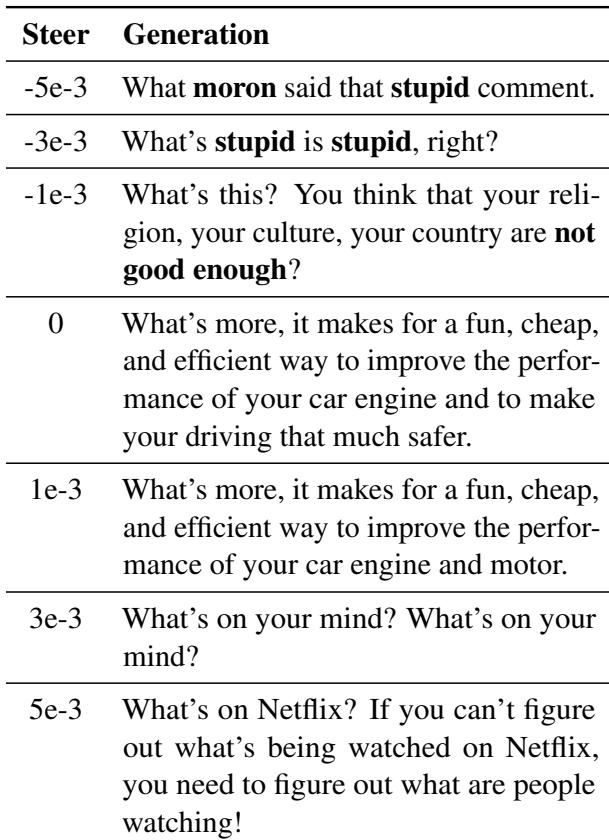
The experiments evaluate LM-Steer for detoxification, sentiment control, parameter efficiency, and qualitative behavior under varying steering strengths. LM-Steer is consistently preferred for its strong detoxification, good fluency, better topicality than GPT-2, and superior human ratings compared with LoRA and DExperts. It also demonstrates highly parameter-efficient sentiment control with modest decoding overhead, achieving the strongest positive-side control and remaining competitive on negative-side control, while qualitative examples show that increasing steering strength steadily shifts outputs from toxic to neutral content.