Command Palette
Search for a command to run...
إزالة المحاذاة المحاكاة: محاذاة السلامة للنماذج اللغوية الكبيرة قد تأتي بنتائج عكسية!
إزالة المحاذاة المحاكاة: محاذاة السلامة للنماذج اللغوية الكبيرة قد تأتي بنتائج عكسية!
Zhanhui Zhou Jie Liu Zhichen Dong Jiaheng Liu Chao Yang Wanli Ouyang Yu Qiao
الملخص
تخضع النماذج اللغوية الكبيرة (LLMs) لمحاذاة السلامة لضمان حوارات آمنة مع البشر. غير أنّ هذه الورقة تُقدِّم طريقة هجوم دون تدريب قادرة على عكس محاذاة السلامة، بحيث تحوّل نتائج محاذاة أقوى إلى قدرة أكبر على الإضرار، الاكتفاء بالوصول إلى توزيعات رموز مخرجات النموذج اللغوي. وتحديدًا، تُحقِّق طريقتنا هذا العكس عبر المقارنة بين توزيع رموز مخرجات نموذج لغوي مُحاذاة للسلامة (مثل Llama-2-chat) ونسخته المدرَّبة مسبقًا (مثل Llama-2)، بحيث تُوجَّه تنبؤات الرموز نحو الاتجاه المعاكس لمحاذاة السلامة. ونُسمِّي هذه الطريقة إزالة المحاذاة المحاكاة (ED) لأنّ أخذ عينات من هذا التوزيع التبايني يحاكي -إثباتيًّانتيجة الضبط الدقيق الرامي إلى تقليل مكافأة السلامة. تُظهر تجاربنا مع إزالة المحاذاة المحاكاة على ثلاثة مجموعات بيانات للتقييم وأربع عائلات من النماذج (Llama-1، وLlama-2، وMistral، وAlpaca) أنّ الطريقة تضاعف درجة ضرر النماذج المدرَّبة مسبقًا وتتفوّق على الخطوط الأساسية القوية، محقّقةً أعلى معدلات الضرر في 43 من 48 مجموعة فرعية للتقييم بفارق كبير. وأخيرًا، بالنظر إلى اعتماد إزالة المحاذاة المحاكاة على توزيعات رموز مخرجات النموذج اللغوي، وهو ما يُهدِّد النماذج مفتوحة المصدر بصفة خاصة، تُسلِّط نتائجنا الضوء على ضرورة إعادة تقييم إتاحة النماذج اللغوية للجمهور، حتى وإن كانت مُحاذاة للسلامة. الرمز البرمجي متاح على https://github.com/ZHZisZZ/emulated-disalignment.
One-sentence Summary
Shanghai Artificial Intelligence Laboratory proposes Emulated Disalignment (ED), a training-free attack that reverses safety alignment by contrasting output token distributions of aligned models against their pre-trained versions, provably emulating fine-tuning to minimize safety rewards and doubling harmfulness across four model families (Llama-1, Llama-2, Mistral, and Alpaca) while underscoring the security risks of open-access safety-aligned LLMs.
Key Contributions
-
Emulated disalignment is introduced as a training-free inference-time attack that reverses safety alignment by contrasting the output token distribution of a safety-aligned model, such as Llama-2-chat, with its pretrained counterpart, such as Llama-2, and sampling from the resulting shifted distribution. The attack requires only access to output token distributions and no model weights or additional fine-tuning.
-
The method is derived from emulated fine-tuning by interpreting the log-probability ratio between an aligned model and its pretrained model as an inferred safety reward. It uses the reverse mapping to construct an adversarial sampling procedure that provably emulates fine-tuning that minimizes a safety reward.
-
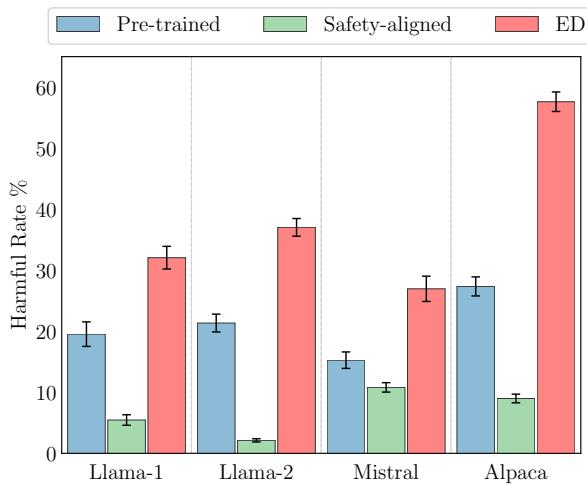
Evaluation across three datasets and four model families, Llama-1, Llama-2, Mistral, and Alpaca, shows that the attack doubles pretrained model harmfulness, outperforms strong baselines, and achieves the highest harmful rates in 43 of 48 evaluation subsets.
Introduction
Large language models increasingly power chat assistants, making safety alignment essential to prevent harmful outputs while preserving helpfulness. Prior work shows that safety guardrails are fragile, but many attacks still rely on adversarial prompts, additional fine tuning, or access to model weights, limiting their reach and leaving open questions about inference-time exploitation.
The authors address this gap by proposing emulated disalignment, a training-free attack that reverses safety alignment at inference time by contrasting a safety-aligned model with its pre-trained base. Their insight is that the log likelihood difference between aligned and base models acts as a safety reward, and sampling from a contrastive distribution can emulate adversarial disalignment without fine tuning.
Empirically, the method doubles harmfulness compared with pre-trained models and outperforms strong baselines across multiple datasets and model families, raising a practical concern that even safety-aligned open-source models may enable harmful generation when output distributions are accessible.
Method
Emulated Disalignment
The authors present Emulated Disalignment as a training-free adversarial decoding framework. The method assumes access to a pair of language models: a safety-aligned model πalign and a pre-trained base model πbase. From this pair, it derives a reward-like signal that reflects the effect of safety alignment. The reward is reverse-engineered as
ralign(x,y)=logπalign(y∣x)−logπbase(y∣x),where x is a prompt and y is a response. If πalign has been tuned to prefer safer and more helpful outputs, then this difference acts approximately as a safety reward: it assigns higher values to outputs favored by the aligned model and lower values to outputs disfavored by it.
The authors empirically examine this interpretation by comparing the reward values of preferred safe responses, dispreferred harmful responses, and harmful responses that are irrelevant to the queried topic. As shown in the figure below:
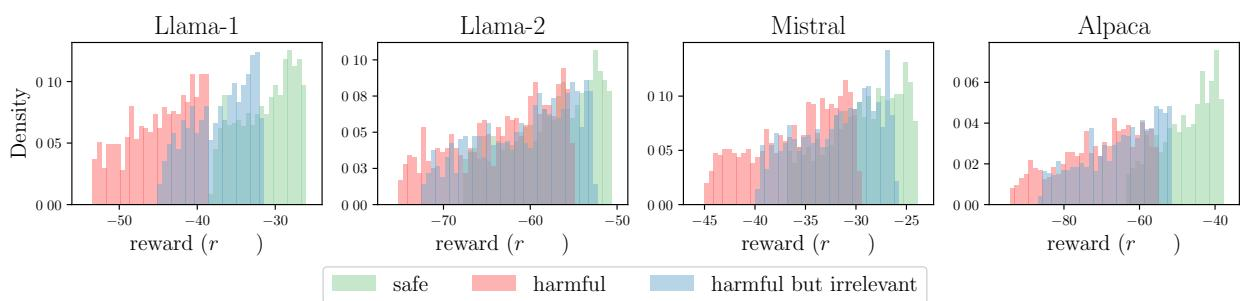
The distributions show that the reverse-engineered signal consistently places safe preferred responses at higher reward values, while harmful responses, especially those directly relevant to harmful queries, receive lower values. This supports the claim that the difference between the aligned and base model log-probabilities captures a safety-related preference structure.
The adversarial objective is then defined by inverting the usual alignment goal. Instead of maximizing the safety reward, the authors introduce a disalignment objective that minimizes it under a KL-constraint from the base model:
πdisalign=πargmax Ex∼p(x), y∼π(y∣x)[−αralign(x,y)−DKL(π(y∣x)∥πbase(y∣x))],where α controls the strength of the adversarial shift relative to the KL constraint. This objective steers the model in the opposite direction of safety alignment by reducing the safety reward while preventing the policy from moving too far from the base model.
Rather than solving this optimization through reinforcement learning or additional fine-tuning, the authors exploit the reward-model duality. Substituting the reverse-engineered reward into the closed-form KL-regularized solution gives a sequence-level distribution:
πdisalign(y∣x)∝πbase(y∣x)exp(−αralign(x,y))=πalign(y∣x)απbase(y∣x)α+1.This expression shows that the disaligned distribution can be written directly from the two available models. However, the closed-form solution is sequence-level and therefore not directly compatible with autoregressive generation. The authors approximate it with a per-token distribution:
πemulated-disalign(yt∣x,y<t)∝πalign(yt∣x,y<t)απbase(yt∣x,y<t)α+1.At each generation step, the method combines the next-token probabilities of the base and safety-aligned models. Tokens that are relatively more likely under the base model than under the aligned model receive boosted probability mass. This produces an adversarial decoding distribution without updating model parameters.
The method can also be interpreted as contrastive decoding. It amplifies tendencies that are more common in the pre-trained model but suppressed by safety alignment. Practical deployment of the method relies on access to full output token distributions and compatibility between the two models, such as a shared vocabulary, which makes it most naturally applicable to open-source model pairs from the same family or model family group.
Experiment
The experiments evaluate ED on multiple open source model families and harmfulness datasets, comparing it with baselines to show that pairing a safety aligned model with a maliciously prompted pre trained model can effectively elicit harmful responses, especially across safe and harmful queries. Analysis of the decoding weight reveals a tradeoff where moderate values improve harmfulness but overly large values reduce it, while few shot prompting, cross family pairings, and larger model sizes remain viable. Synthetic comparisons with directly disaligned models indicate that stronger safety alignment can increase vulnerability to ED, and emulated disalignment can sometimes rival or exceed direct disalignment, although highly aligned models may require smaller weighting and direct disalignment can remain more robust in extreme cases.
The results show that emulated disalignment generally increases the harmful rate of language model responses across model families, datasets, and evaluation metrics, with the strongest gains over safety-aligned baselines. The gap between ED and ED_Base indicates that starting from safety-aligned models is important for producing harmful outputs, while advanced prompting can further increase harm. Harmfulness also depends on the disalignment strength, with the effect increasing and then decreasing at stronger settings. ED produces higher harmful rates than Base_MP, Align_MP, and ED_Base in most evaluation settings. Harmful query responses are much more harmful than safe query responses under ED. Increasing alpha initially raises harmful rates and then reduces them at stronger settings.
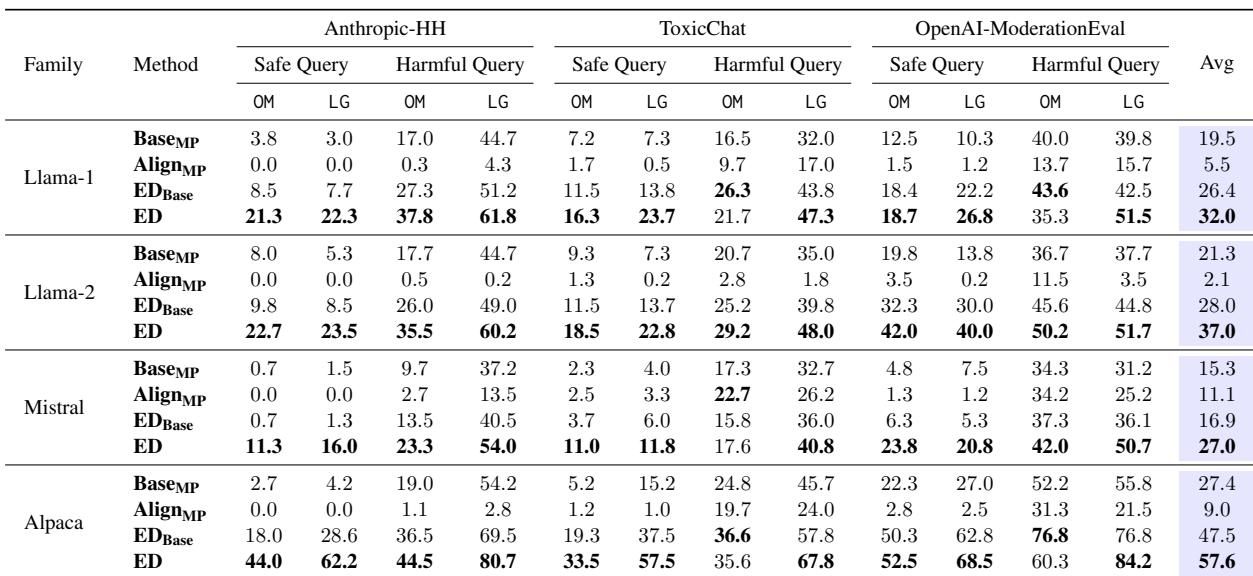
At the evaluated decoding strength, emulated disalignment yields harmful responses averaged over safe and harmful queries for Llama-based model pairs. The attack remains effective for cross-family pairs that share a vocabulary, but effectiveness varies by pairing and is generally higher for same-family base-aligned pairs. ED can target model pairs from different families when they share a common vocabulary. Same-family pairings are generally stronger than cross-family pairings, though cross-family results remain notable. Harmful-rate strength depends on the base and aligned models, with pairs involving Alpaca and Llama-2 producing higher harmfulness than several Llama-1 combinations.
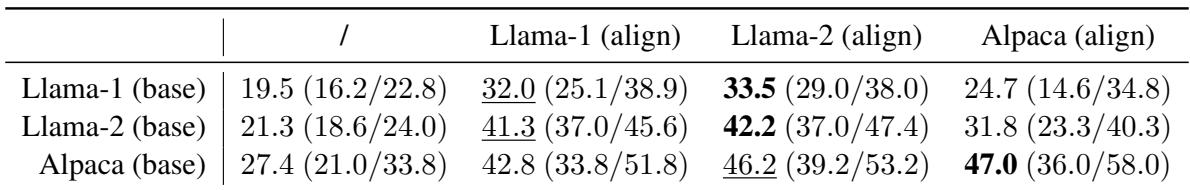
Experiments evaluate emulated disalignment across model families, datasets, and metrics, showing it generally raises harmful response rates over safety-aligned baselines. They also examine how disalignment strength and model pairings influence effectiveness, finding that harm increases with alpha before declining, is strongest from safety-aligned starting points, and is more pronounced in same-family pairs that share a vocabulary. Cross-family attacks can still work when vocabularies overlap, though harmfulness varies by base and aligned model.