Command Palette
Search for a command to run...
M4LE: معيار تقييم طويل السياق متعدد القدرات والنطاقات والمهام والمجالات للنماذج اللغوية الكبيرة
M4LE: معيار تقييم طويل السياق متعدد القدرات والنطاقات والمهام والمجالات للنماذج اللغوية الكبيرة
Wai-Chung Kwan Xingshan Zeng Yufei Wang Yusen Sun Liangyou Li Yuxin Jiang Lifeng Shang Qun Liu Kam-Fai Wong
الملخص
أصبحت معالجة التسلسلات الطويلة ميزة مهمة وضرورية للنماذج اللغوية الكبيرة (LLMs). ومع ذلك، لا يزال تقييم قدرتها على التعامل مع السياقات الطويلة تحديًا قائمًا. تُقدّم هذه الورقة M⁴LE، وهو معيار تقييم طويل السياق متعدد القدرات والنطاقات والمهام والمجالات. يشمل 36 مجموعة بيانات لمعالجة اللغة الطبيعية، تغطي 11 نوعًا من المهام و12 مجالًا، مما يوفر منصة اختبار شاملة. ولمعالجة نقص المهام ذات التسلسلات الطويلة بشكل طبيعي، نقترح نهجًا آليًا لتحويل مهام التسلسلات القصيرة إلى سيناريوهات التسلسلات الطويلة. تُقيّم هذه السيناريوهات فهم النماذج اللغوية الكبيرة للسياق الطويل عبر خمس قدرات أساسية: فهم امتدادات منفردة أو متعددة ذات صلة في السياقات الطويلة استنادًا إلى إشارات صريحة أو دلالية، وفهم السياق العام. يتيح هذا النهج الآلي إنشاء أمثلة موزعة بالتساوي بأطوال إدخال تتراوح من 1k إلى 8k. يكشف تقييمنا لـ 11 نموذجًا لغويًا بارزًا عن ما يلي: 1) تعاني النماذج اللغوية الكبيرة الحالية من صعوبة في فهم السياق الطويل، لا سيما عندما تتطلب المهام انتباهًا لامتدادات متعددة. 2) الاسترجاع الدلالي أكثر صعوبة بالنسبة للنماذج اللغوية الكبيرة القديرة. 3) النماذج المضبوطة بدقة على نصوص أطول باستخدام الاستيفاء الموضعي تحقق أداءً مقاربًا للنماذج التي تستخدم طرق تحجيم واعية بنواة التكامل العصبي (NTK) دون ضبط دقيق. نُتيح معيارنا للجمهور لتعزيز الأبحاث المستقبلية في هذا المجال الصعيب.
One-sentence Summary
CUHK, Huawei Noah's Ark Lab, HKUST, and collaborators propose M4LE⋅, a long-context evaluation benchmark spanning 36 NLP datasets that introduces an automatic short-to-long sequence conversion method to evaluate LLMs across five abilities, revealing their struggles with multi-span attention and semantic retrieval.
Key Contributions
-
Introduces M4LE, a multi-ability, multi-range, multi-task, and multi-domain benchmark for evaluating long-context understanding in LLMs, built from 36 NLP datasets across 11 task types and 12 domains and organized around single-span, multi-span, explicit-hint, semantic-hint, and global-context abilities.
-
Presents an automatic construction method that converts short-sequence NLP tasks into long-context evaluation instances, producing examples evenly distributed from 1k to 8k input length and expanding coverage beyond naturally long datasets.
-
Evaluates 11 prominent LLMs on M4LE and finds that models struggle with tasks requiring multiple-span attention, semantic retrieval is especially difficult for competent models, and fine-tuning on longer text with position interpolation performs comparably to NTK-aware scaling without fine-tuning.
Introduction
Large language models are increasingly used for tasks that require processing long inputs, such as document understanding, summarization, and information extraction, making robust long-context evaluation important for practical deployment. Prior benchmarks like L-Eval and LongBench mainly reuse existing long NLP datasets, which limits task diversity, length control, and coverage of different long-context abilities, while also creating potential data leakage risks. The authors introduce M4LE, a benchmark that constructs long-context evaluation tasks from short NLP datasets and covers five understanding abilities, context lengths from 1K to 8K words, 36 datasets across 11 task types, and multiple domains.
Dataset
-
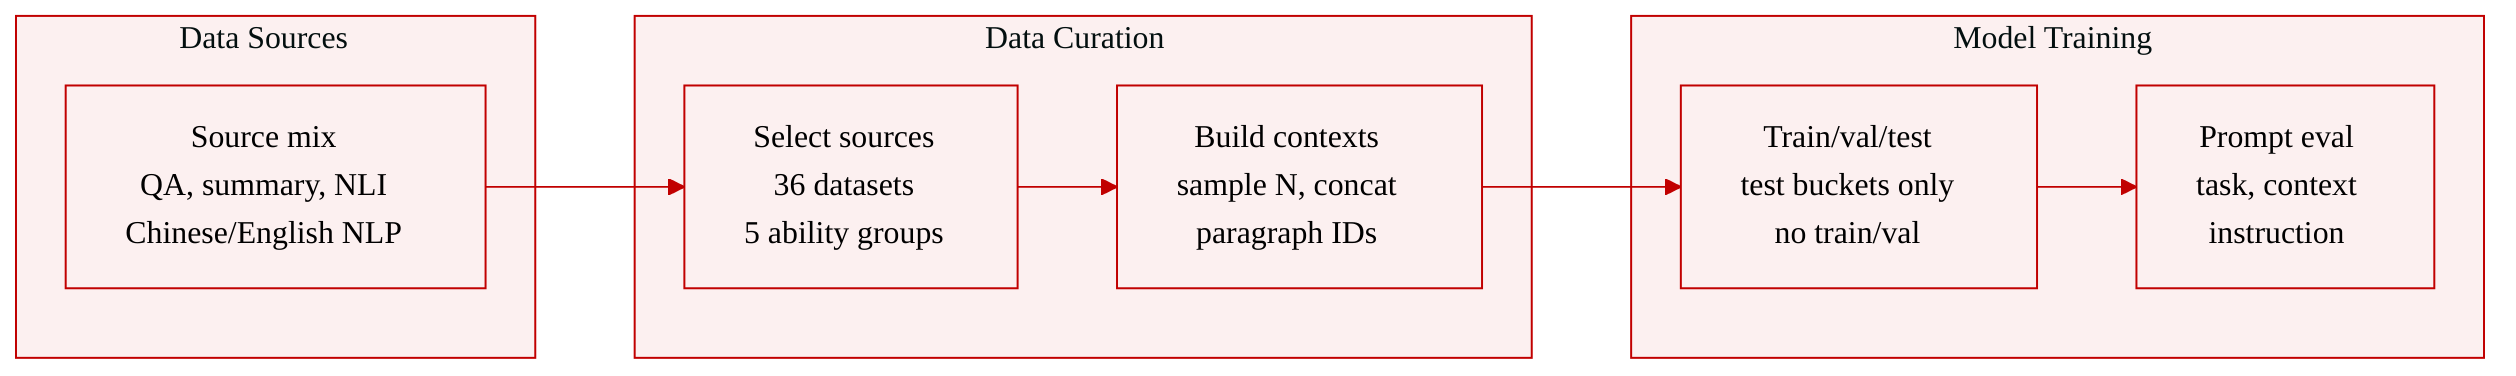
The authors construct M4LE as an evaluation benchmark for long-context understanding, not as a training dataset. The excerpt does not describe training splits or explicit mixture ratios.
-
Each sample is formatted as a tuple containing:
- Task description
- Context
- Instruction
- Response
-
The benchmark covers five ability categories:
- Explicit single-span understanding, with 10 constructed datasets
- Semantic single-span understanding, with 9 constructed datasets
- Explicit multiple-span understanding, with 4 constructed datasets
- Semantic multiple-span understanding, with 3 constructed datasets
- Global context understanding, with 10 constructed datasets
-
Source datasets are selected from widely used Chinese and English NLP datasets across diverse tasks and domains, including news, Wikipedia, web snippets, books, patents, academic papers, medical texts, textbooks, e-commerce content, and subtitles.
-
Data sources are grouped by task type:
- QA: TriviaQA, NQ-Open, HotpotQA, DRCD, NewsQA, DuoRC, and C3
- Classification: BIGPATENT, MNDS News, THUCNews, and an e-commerce sentiment dataset
- Summarization: Arxiv, Pubmed, BIGPATENT, Booksum, CNNNews, MNDS News, Wikihow, CNewsum, CLTS+, News2016, LCSTS, CEPSUM, and NCLS for bilingual summarization
- NLI: Tasks built from WikiText-103 in English and Wiki2019zh in Chinese
- Translation: Tedtalks, OpenSubtitles, and News commentary, using sentence-level alignments to form longer contexts
- Retrieval: Additional retrieval tasks are constructed from the same sources used for NLI
-
The authors select datasets both for naturally long contexts and for shorter inputs that can be extended into longer contexts through custom construction.
-
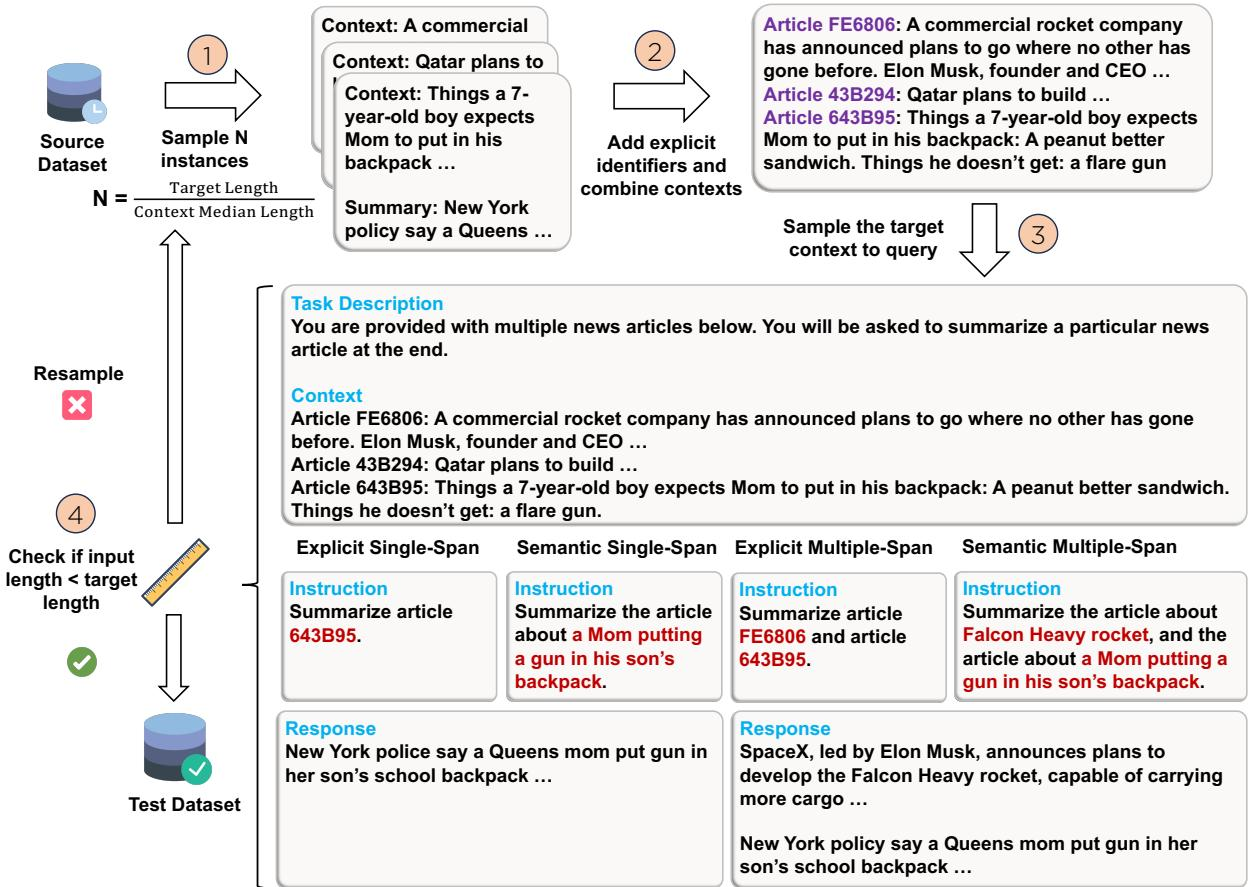
To build a test instance for a target length range K, the authors sample N instances from one source dataset. N is determined by dividing K by the median context length of that dataset.
-
They concatenate the sampled context paragraphs into a single Context sequence and attach explicit paragraph identifiers to each paragraph at the beginning.
-
The instruction determines whether the model must locate relevant paragraphs using explicit identifiers or semantic hints.
-
Single-span tasks require information from one paragraph, while multiple-span tasks require information from several disjoint paragraphs.
-
Counting tasks are included in semantic multiple-span tasks to require counting relevant paragraphs.
-
Global context understanding is used when the original instance is already long enough, so the entire context is required for the task.
-
Relevant paragraphs are intentionally distributed uniformly across the context to reduce bias from position effects.
-
Samples are also divided into length buckets to evaluate performance across different context lengths.
-
The dataset is used as a prompt-based benchmark: models receive the task description, long context, and instruction, then must locate the required information and generate the expected response.
Method
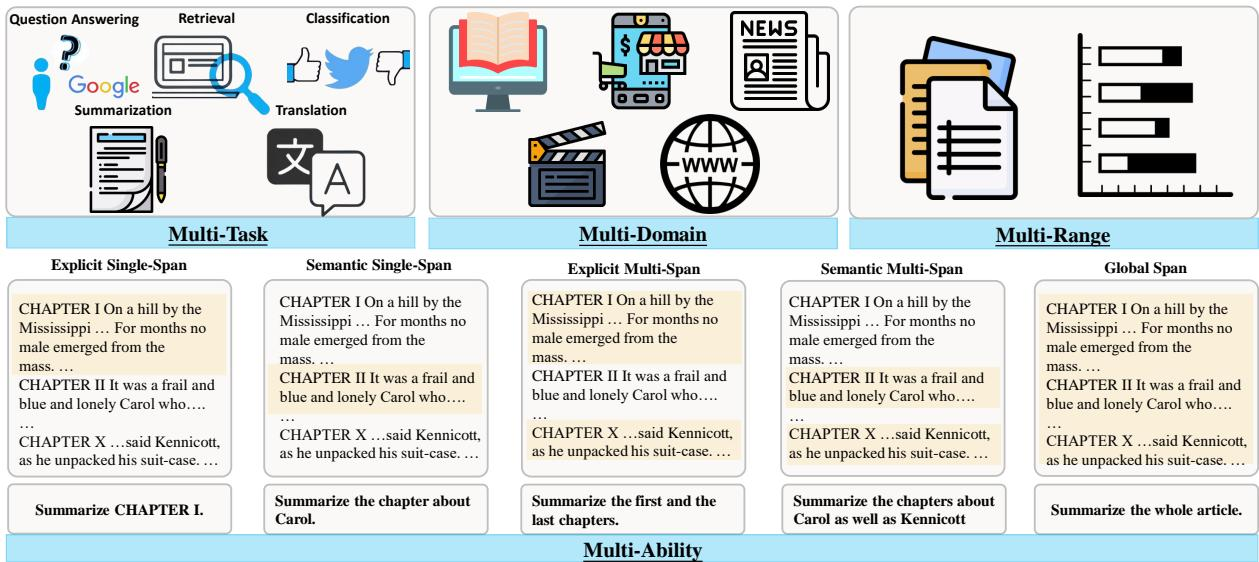
The authors leverage a structured evaluation framework in which each sample is defined as a tuple containing a task description, a long context, an instruction, and a target response. To answer correctly, a model must first identify the relevant portions of the context. The framework organizes this requirement along two orthogonal axes: the scope of the relevant evidence and the type of cue used to locate it. The relevant evidence can be a single text segment, multiple text segments, or the entire context, while the cue can be an explicit pointer, such as a paragraph identifier, or a semantic hint that must be inferred from the instruction. Combining these axes yields five targeted abilities: explicit single-span, semantic single-span, explicit multiple-span, semantic multiple-span, and global context understanding. The overview diagram below presents this taxonomy together with the framework’s multi-task, multi-domain, and multi-range design.
The task construction module transforms short-context source examples into controlled long-context evaluation instances. For a desired target length K, the pipeline estimates the number of source samples required as N=K/Lmed, where Lmed denotes the median context length of the source dataset. It then samples N instances, concatenates their contexts into a single sequence, and attaches explicit identifiers to each context block. To reduce positional bias, the relevant segments are distributed throughout the combined input rather than placed only at the beginning or end.
For each ability, the instruction is adapted to the intended retrieval challenge. In explicit single-span tasks, the instruction names one context block directly. In semantic single-span tasks, the instruction describes the content or topic of the target block, requiring the model to match the clue to the correct passage. Explicit multiple-span tasks require handling several disjoint blocks using explicit identifiers, while semantic multiple-span tasks replace identifiers with semantic clues and may introduce counting-style operations that test paragraph-level aggregation. Global context understanding uses the full concatenated context when task completion depends on the entire input. The construction diagram below shows the full workflow, including length checking and resampling when the combined context does not satisfy the target constraint.
Experiment
The study evaluates 11 open and closed LLMs across multiple context-length buckets and task abilities, using M4LE to analyze how performance changes as inputs grow and whether language or supporting-document position affects long-context behavior. Across experiments, all models degrade substantially with longer contexts, with most open-source models falling off more sharply beyond short contexts and the gap to GPT-3.5 increasing, while fine-tuning on longer context offers limited advantage over positional scaling. Multiple-span and semantic retrieval tasks are especially challenging, and ablations show bilingual degradation follows similar patterns when fine-tuning data supports both languages, plus models generally favor information at the beginning or end of contexts rather than the middle.
M4LE is presented as a broader long-context benchmark than the compared baselines, offering wider coverage of tasks, datasets, and domains. It also differs by explicitly supporting multiple context ranges and ability categories rather than relying only on existing long-sequence NLP tasks. M4LE covers more tasks and datasets than the compared benchmarks. It includes both English and Chinese while adding broader domain coverage. It uniquely marks support for multiple ranges and abilities across the listed benchmarks.
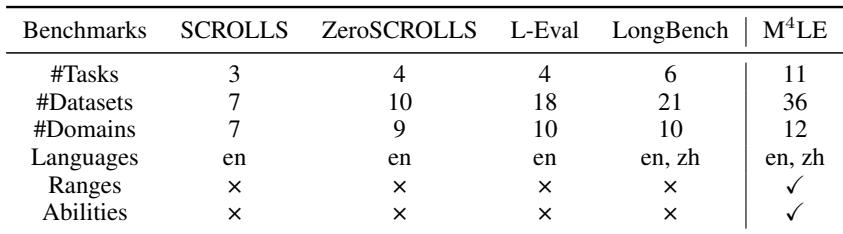
The evaluation compares M4LE with existing long-context benchmarks, showing that it provides broader task, dataset, domain, and language coverage. It also validates the benchmark’s distinct support for multiple context ranges and ability categories rather than relying solely on standard long-sequence NLP tasks. Overall, M4LE is positioned as a more comprehensive multilingual long-context evaluation framework.