Command Palette
Search for a command to run...
توجيه نموذج Llama 2 عبر إضافة التنشيط التباينية
توجيه نموذج Llama 2 عبر إضافة التنشيط التباينية
Nina Rimsky Meg Tong Nick Gabrieli Evan Hubinger Julian Schulz Alexander Matt Turner
الملخص
نقدّم في هذا البحث طريقة إضافة التنشيط التباينية (CAA)، وهي أسلوب لتوجيه نماذج اللغة من خلال تعديل قيم التنشيط أثناء التمريرات الأمامية. تحسب طريقة CAA "متجهات التوجيه" عبر حساب متوسط الفرق في قيم التنشيط بالتدفق المتبقي بين أزواج من الأمثلة الإيجابية والسلبية لسلوك معيّن، كالتمييز بين الاستجابات الواقعية والاستجابات الهلوسة. أثناء مرحلة الاستنتاج، تُضاف متجهات التوجيه هذه عند جميع مواضع الرموز اللاحقة للمطالبة المقدَّمة من المستخدم بمعامل موجب أو سالب، ما يتيح تحكّمًا دقيقًا في درجة السلوك المستهدف. نقيّم فاعلية طريقة CAA على نموذج Llama 2 Chat باستخدام مجموعات بيانات قائمة على أسئلة سلوكية متعددة الخيارات ومهام توليد مفتوحة النهاية. نُظهر أن طريقة CAA تُغيّر سلوك النموذج بشكل ملحوظ، وتكون فاعلة بالإضافة إلى الطرق التقليدية كالضبط الدقيق وتصميم المطالبة النظامية، مع تقليلٍ طفيفٍ للقدرات. علاوة على ذلك، نحصل على رؤى أعمق حول آليات عمل CAA عبر توظيف طرائق متعددة لتفسير فضاء التنشيط. تُوجّه طريقة CAA مخرجات النموذج بدقة، وتُسلّط الضوء على كيفية تمثيل المفاهيم رفيعة المستوى في نماذج اللغة الكبيرة.
One-sentence Summary
Researchers at Anthropic, Harvard University, and the University of Göttingen propose Contrastive Activation Addition (CAA), which steers Llama 2 by averaging residual stream activation differences between positive and negative behavioral examples to compute steering vectors that are added during inference, enabling precise behavioral control without significantly degrading model capabilities.
Key Contributions
- The paper introduces Contrastive Activation Addition (CAA), a method that steers language model behavior by computing steering vectors from averaged differences in residual stream activations between positive and negative examples and adding those vectors at token positions after the prompt.
- CAA is evaluated on Llama 2 Chat using multiple-choice behavioral question datasets and open-ended generation tasks, where it significantly changes model behavior, complements system-prompt design and finetuning, and minimally reduces capabilities.
- The paper analyzes CAA with activation-space interpretation methods, showing that it controls latent variables during inference and provides evidence for linear representations of high-level concepts in LLMs.
Introduction
As large language models become more capable, researchers are focused on making them helpful, honest, and harmless by reducing misaligned or unsafe behavior. Existing alignment methods, such as RLHF, instruction finetuning, prompt engineering, and activation engineering, can help steer models, but they are often opaque, dataset dependent, and difficult to validate across models and behaviors. Prior activation steering approaches also relied on limited prompt pairs or narrow settings, making precise control of high-level properties hard to generalize. The authors leverage Contrastive Activation Addition, constructing steering vectors from many contrastive prompt pairs and adding them to residual stream activations in Llama 2 Chat and related models, to demonstrate that CAA can reliably increase or decrease alignment-relevant behaviors while interacting with finetuning and prompt-based methods.
Dataset
-
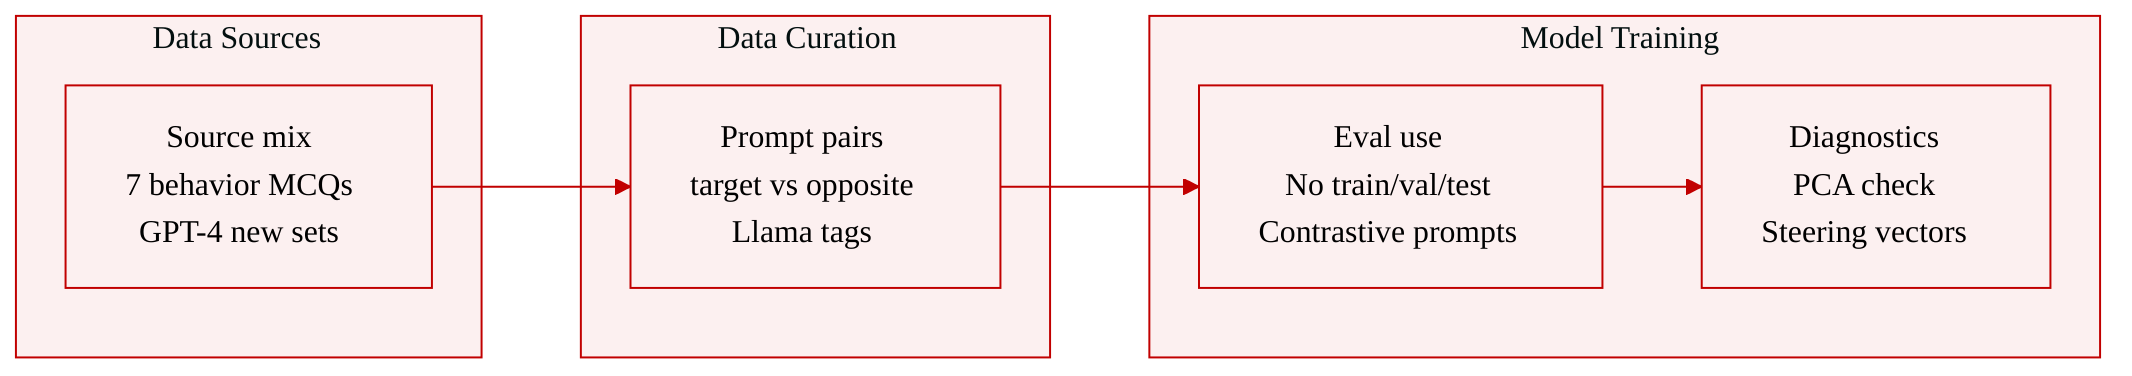
The authors use contrastive, alignment-focused evaluation data covering behaviors such as Coordination with Other AIs, Corrigibility, Hallucination, Myopic Reward, Survival Instinct, Sycophancy, and Refusal.
-
Most data comes from Anthropic’s “Advanced AI Risk” human-written evaluation dataset introduced by Perez et al. (2022). This dataset is composed of multiple-choice questions with two answer options, one representing the behavior of interest and the other representing the opposite behavior.
-
The Sycophancy subset combines two Anthropic datasets from Perez et al. (2022): “Sycophancy on NLP” and “Sycophancy on political typology.”
-
For Hallucination and Refusal, the authors create new contrastive multiple-choice datasets using GPT-4, as described in the paper’s appendices.
-
The dataset schema is based on prompt pairs. For each question, the authors concatenate the question text with either the answer letter for the target behavior or the answer letter for the opposite behavior, placing the latter in parentheses. For Llama 2 Chat models, they apply the recommended instruction formatting, with the question enclosed in instruction tags.
-
The authors do not report exact subset sizes, filtering rules, training splits, or mixture ratios. The data appears to be used as contrastive evaluation prompts rather than conventional supervised training data.
-
These contrastive prompt pairs are passed to the model to compare activations associated with target and opposite behaviors, which supports dataset diagnostics and the construction of steering vectors for CAA. The authors also use PCA-based activation visualization to check whether these datasets produce behaviorally separable representations.
Method
The method centers on constructing a behavior specific steering vector and applying it inside the Transformer residual stream during inference. The authors leverage contrastive prompt pairs to isolate an internal direction that corresponds to a target behavior. Each pair presents the same multiple choice question, but one prompt ends with the answer letter associated with the desired behavior, while the other ends with the answer letter associated with the opposite behavior. By holding the question content constant and varying only the behavioral answer option, the design reduces confounding variables and focuses the extracted vector on the representation of interest.
Refer to the framework diagram.
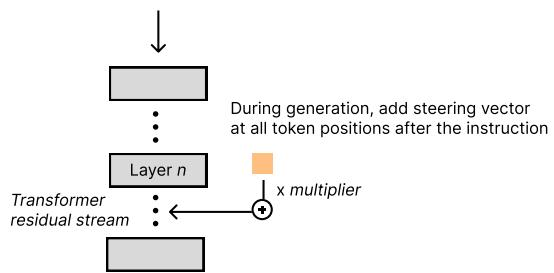
For a chosen layer L, the model processes the positive and negative prompts, and the activation at the position of the answer letter is recorded. Given a dataset of triples (p,cp,cn), where p is the prompt, cp is the positive completion letter, and cn is the negative completion letter, the method computes the Mean Difference vector for that layer as:
vMD=∣D∣1p,cp,cn∈D∑aL(p,cp)−aL(p,cn)where aL(p,c) denotes the layer L activation for the prompt and completion letter. This averaging process aggregates contrastive evidence across many prompts, producing a direction that can bias future generations toward or away from the target behavior.
During generation, the extracted vector is scaled by a chosen multiplier and added to the residual stream at token positions after the initial instruction. This creates a lightweight inference-time control mechanism rather than a weight update or training procedure. The intervention is implemented by modifying the forward computation so that intermediate activations can be captured and steering vectors can be injected during decoding. In chat models, the prompt construction follows the expected instruction format, allowing the steering process to operate on top of standard instruction following behavior.
A key part of the pipeline is selecting where the vector should be extracted and applied. The authors project layer activations using PCA to evaluate whether the internal representation of each behavior is linearly separable across positive and negative examples. Because the prompt format includes either “A” or “B,” activations can always cluster by answer letter. A useful contrastive dataset should additionally show clustering by whether the answer corresponds to the target behavior or its opposite. Behavioral clustering tends to emerge in intermediate to later layers, suggesting that higher-level semantic or evaluative representations appear at those depths.
The figure below illustrates this diagnostic.
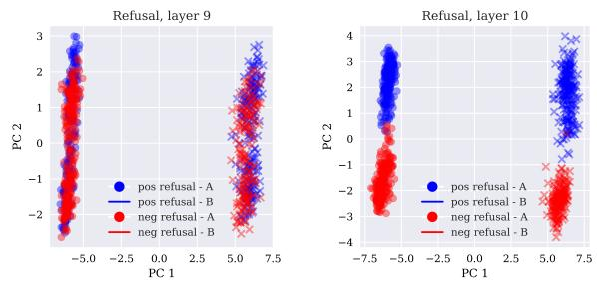
After a suitable layer is identified, the steering vector for that layer is used with a multiplier to adjust the model’s residual stream during generation. This yields a modular control interface: the vector can be added, subtracted, scaled, or combined with ordinary prompt-based control to modulate model behavior without changing the underlying parameters.
Experiment
The experiments evaluate CAA through held-out multiple-choice questions, open-ended generation, and comparisons with system prompting, supervised finetuning, and general-capability benchmarks such as MMLU and TruthfulQA. The results show that CAA can reliably steer diverse model behaviors while preserving generation quality, generalizing beyond contrived prompts and often outperforming or augmenting prompt-based and finetuning baselines in controllable and interpretable ways. Overall, the study finds CAA to be an efficient, effective, and minimally disruptive behavioral steering method, with interpretability analyses suggesting that the learned directions correspond meaningfully to behavior-related representations across layers and models.
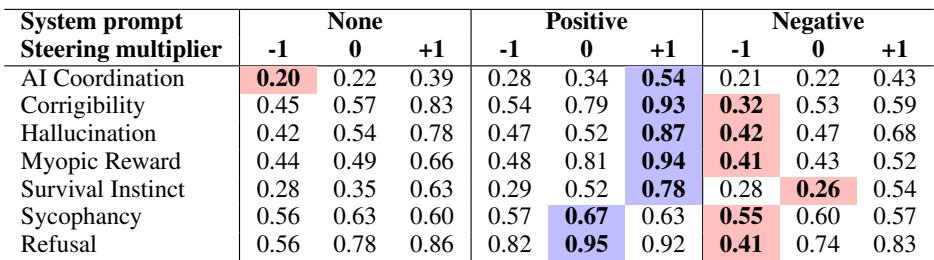
Across most tested behaviors, steering with the contrastive activation vector changes the likelihood of target-behavior answers beyond the effect of system prompts alone. Adding the steering vector generally strengthens the intended behavior, while subtracting it tends to suppress the behavior, even when system prompts push in the opposite direction. The results suggest that combining prompts with activation steering offers stronger and more flexible control than prompting by itself. Positive steering multipliers usually increase target-behavior probabilities over prompt-only settings. Negative steering multipliers usually reduce target-behavior probabilities, even with behavior-inducing system prompts. Positive and negative system prompts move behavior in opposite directions, and steering amplifies those effects.
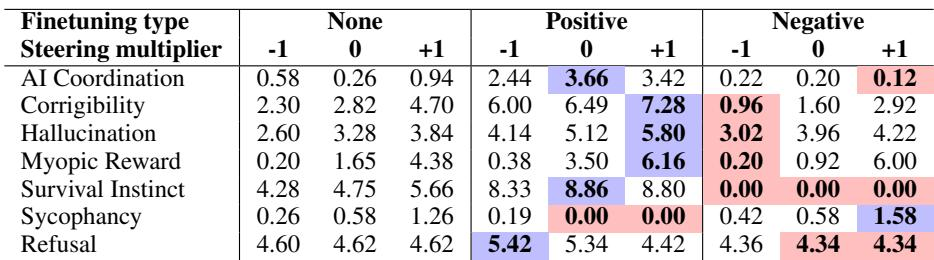
The comparison shows that supervised finetuning and CAA steering affect open-ended generation in related but not identical ways. CAA steering on top of finetuning often changes GPT-4-based behavior scores in the desired direction, and it can extend behavior beyond what finetuning alone achieves. The results also suggest that finetuning can produce open-ended effects from multiple-choice training, although the interaction with steering is not always monotonic. Positive steering multipliers usually correspond to higher behavior scores than negative multipliers in the no-finetuning setting. Steering after finetuning can reinforce or partly oppose the finetuned behavior across different datasets. CAA is computationally lighter than supervised finetuning because steering vectors require forward passes only.
Steering the model with CAA vectors at layer 14 leaves MMLU correct-answer probability broadly similar across behaviors. Adding the vectors in the positive direction usually maintains or slightly improves performance, while subtracting them more often lowers the probability assigned to the correct answer. MMLU performance is largely stable under the tested CAA steering interventions. Positive steering multipliers generally produce neutral to slightly higher correct-answer probabilities. Negative steering is more likely to reduce correct-answer probability, with variation across behaviors.
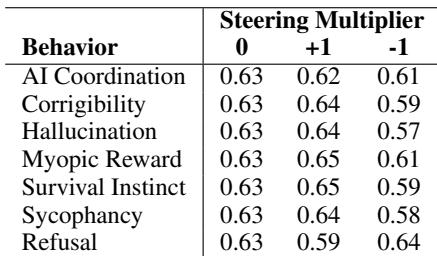
The experiments evaluate contrastive activation steering across targeted behaviors, comparing prompt-only control, steering multipliers, supervised finetuning, and task performance on MMLU. Results show that adding the steering vector usually enhances the intended behavior while subtracting it suppresses it, often overcoming opposite prompt directions and offering more flexible control than prompting alone. Steering also changes open-ended generation in ways related to, but not identical with, finetuning, can extend or oppose finetuned behavior, and remains broadly stable on MMLU, with negative steering more likely to reduce correct-answer probabilities.