Command Palette
Search for a command to run...
ترجمة الكلام باستخدام نماذج الأساس الصوتية والنماذج اللغوية الكبيرة: ما المتاح وما الناقص؟
ترجمة الكلام باستخدام نماذج الأساس الصوتية والنماذج اللغوية الكبيرة: ما المتاح وما الناقص؟
Marco Gaido Sara Papi Matteo Negri Luisa Bentivogli
الملخص
شهد مجال معالجة اللغات الطبيعية مؤخرًا تحوّلًا جذريًا بفضل ظهور نماذج الأساس، ولا سيما النماذج اللغوية الكبيرة (LLMs) التي أحدثت ثورة في معالجة اللغات الطبيعية القائمة على النص. وقد امتد هذا النموذج البراديغمي إلى وسائط أخرى، بما في ذلك الكلام، حيث يسعى الباحثون بنشاط إلى دمج نماذج الأساس الصوتية (SFMs) والنماذج اللغوية الكبيرة في نماذج موحّدة واحدة قادرة على أداء مهام متعددة الوسائط. ومن بين هذه المهام، تُركّز هذه الورقة على ترجمة الكلام إلى نص (ST). ومن خلال استعراض الأوراق المنشورة في هذا الموضوع، نقترح رؤية موحّدة للحلول المعمارية واستراتيجيات التدريب المُقدَّمة حتى الآن، مُبرزين أوجه التشابه والاختلاف بينها. وبناءً على هذا الاستعراض، لا نُرتّب الدروس المستفادة فحسب، بل نُبيّن أيضًا كيف تُعيق الإعدادات المتنوعة وأساليب التقييم المختلفة تحديد الحلّ الأفضل أداءً لكلّ مكوّن معماري وخيار تدريبي. وأخيرًا، نُبرز توصيات للأعمال المستقبلية في هذا الموضوع تهدف إلى فهم أفضل لنقاط القوة والضعف في حلول SFM+LLM لترجمة الكلام.
One-sentence Summary
Fondazione Bruno Kessler surveys the integration of Speech Foundation Models (SFMs) and Large Language Models (LLMs) for speech-to-text translation, proposing a unified taxonomy of architectures and training strategies, showing how inconsistent evaluation settings obscure optimal design choices, and outlining future research directions for improving SFM+LLM systems.
Key Contributions
-
This survey introduces a unified architectural abstraction for speech-to-text translation models that combine speech foundation models with large language models, organizing them into five building blocks: speech representation extraction, length adaptation, modality adaptation, prompt-speech merging, and translation generation.
-
It compares published architectural and training choices to show that inconsistent settings, training recipes, and evaluation protocols hinder identification of the best-performing solution for each building block and training choice.
-
It proposes recommendations for future work, including standardized comparisons with end-to-end and cascade speech-to-text methods, efficiency evaluation against 100 to 300 million parameter models through task-aware pruning, dynamic layer selection, and efficient decoding, and study of in-context learning transfer to speech translation.
Introduction
Foundation models have reshaped NLP, and speech foundation models now enable rich speech understanding, motivating multimodal speech-to-text translation systems that combine speech foundation models with large language models. However, prior SFM+LLM work has emerged rapidly in parallel, with inconsistent architectures, training recipes, datasets, languages, and evaluations, making fair comparison and reproducibility difficult. The lack of standard open benchmarks, reliable semantic metrics, and comparisons against conventional cascade or end-to-end ST systems further obscures strengths, weaknesses, efficiency, and transfer of LLM in-context learning abilities. The authors leverage a systematic review of publicly available SFM+LLM ST solutions to identify a common five-block architecture, organize architectural and training choices, and propose best practices for standard training, evaluation, and future analysis.
Dataset
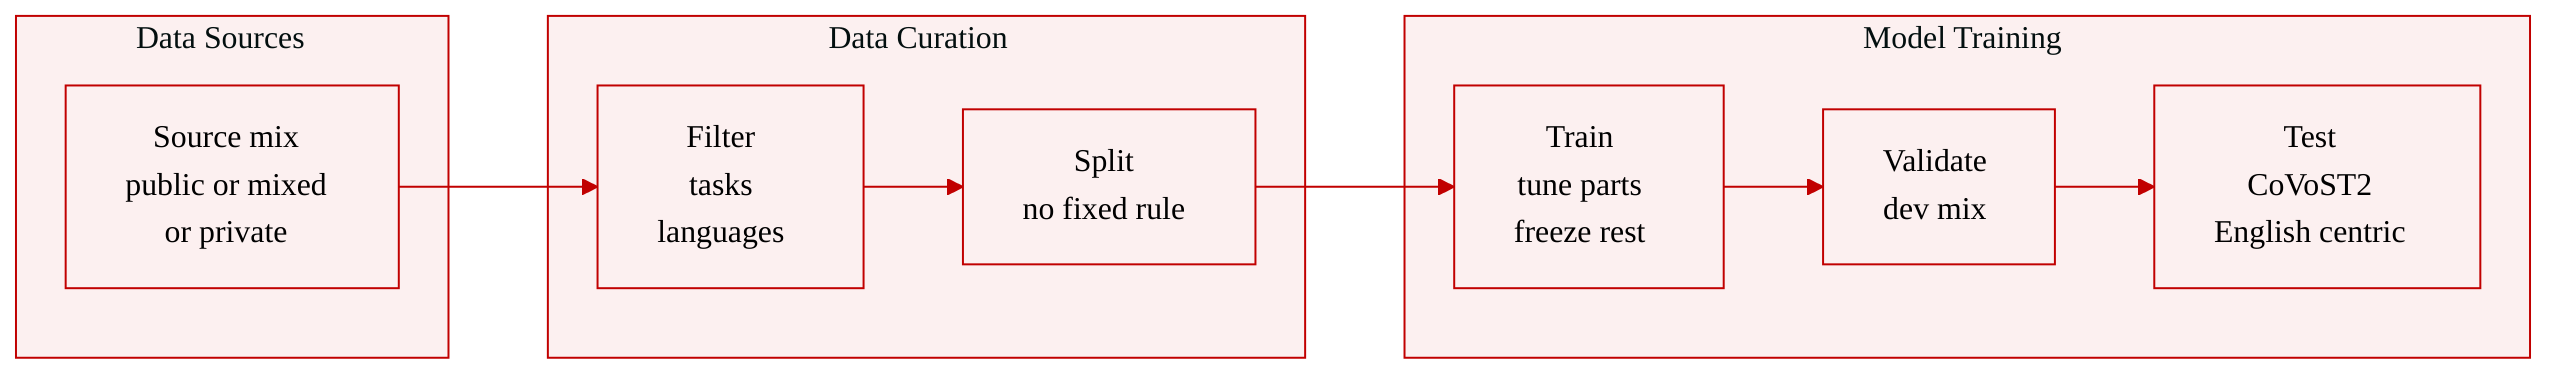
-
The paper describes dataset usage across 9 speech foundation model and LLM papers rather than presenting one unified corpus. The authors organize the data by public, mixed, and proprietary sources, and they report language codes using ISO 639 notation.
-
Training data is highly varied. Five of nine papers use only publicly available data. LST, COSMIC, and Conformer-LLaMA rely on one or two datasets. SALM uses all 11 speech corpora from the IWSLT 2023 Offline Speech Translation Shared Task. SALMONN uses 12 datasets. SLM and LLM-ST combine in-house and open data, while Speech-LLaMa and Qwen-Audio use proprietary data.
-
The paper does not provide a common training protocol. It reports no uniform splits, mixture ratios, scaling experiments, or dataset-level filtering rules, so dataset construction cannot be compared directly across the surveyed models.
-
Training examples go beyond ASR and ST for several models. SLM includes instruction-tuning data. LLM-ST includes four translation-related tasks and two speech-related tasks. SALMONN trains on staged task groups, beginning with ASR and AAC, then instruction tuning with 12 tasks, then activation tuning with longer-response tasks such as AQA and ABST. Qwen-Audio incorporates 26 additional speech, audio, and music tasks. COSMIC uses ASR and SQA data during training but is also tested on ST, while Conformer-LLaMA uses ASR data only.
-
Evaluation datasets are also inconsistent. CoVoST2 is the most common benchmark, used in 5 papers, with coverage of 15 English-to-many directions and 21 many-to-English directions. MuST-C is used in 3 English-to-many evaluations. COSMIC adds TEDLIUM and FLEURS. LLM-ST adds GigaST and private in-house test sets. Four papers evaluate English-to-many directions, two evaluate many-to-English directions, two evaluate both, and one does not report evaluation results.
-
Supported languages are English-centric. In many-to-English settings, Qwen-Audio covers 5 source languages, Speech-LLaMa covers 13 of 21 CoVoST2 pairs, and SLM covers all 21 CoVoST2 pairs. In English-to-many settings, the surveyed papers cover only 2 to 4 target languages, and LLM-ST covers only en-zh. Most reported results focus on de-en or en-de, with en-zh as the next common setting.
-
The paper does not detail cropping strategies, metadata construction, exact token or duration counts, or other low-level preprocessing steps for the datasets it summarizes.
Method
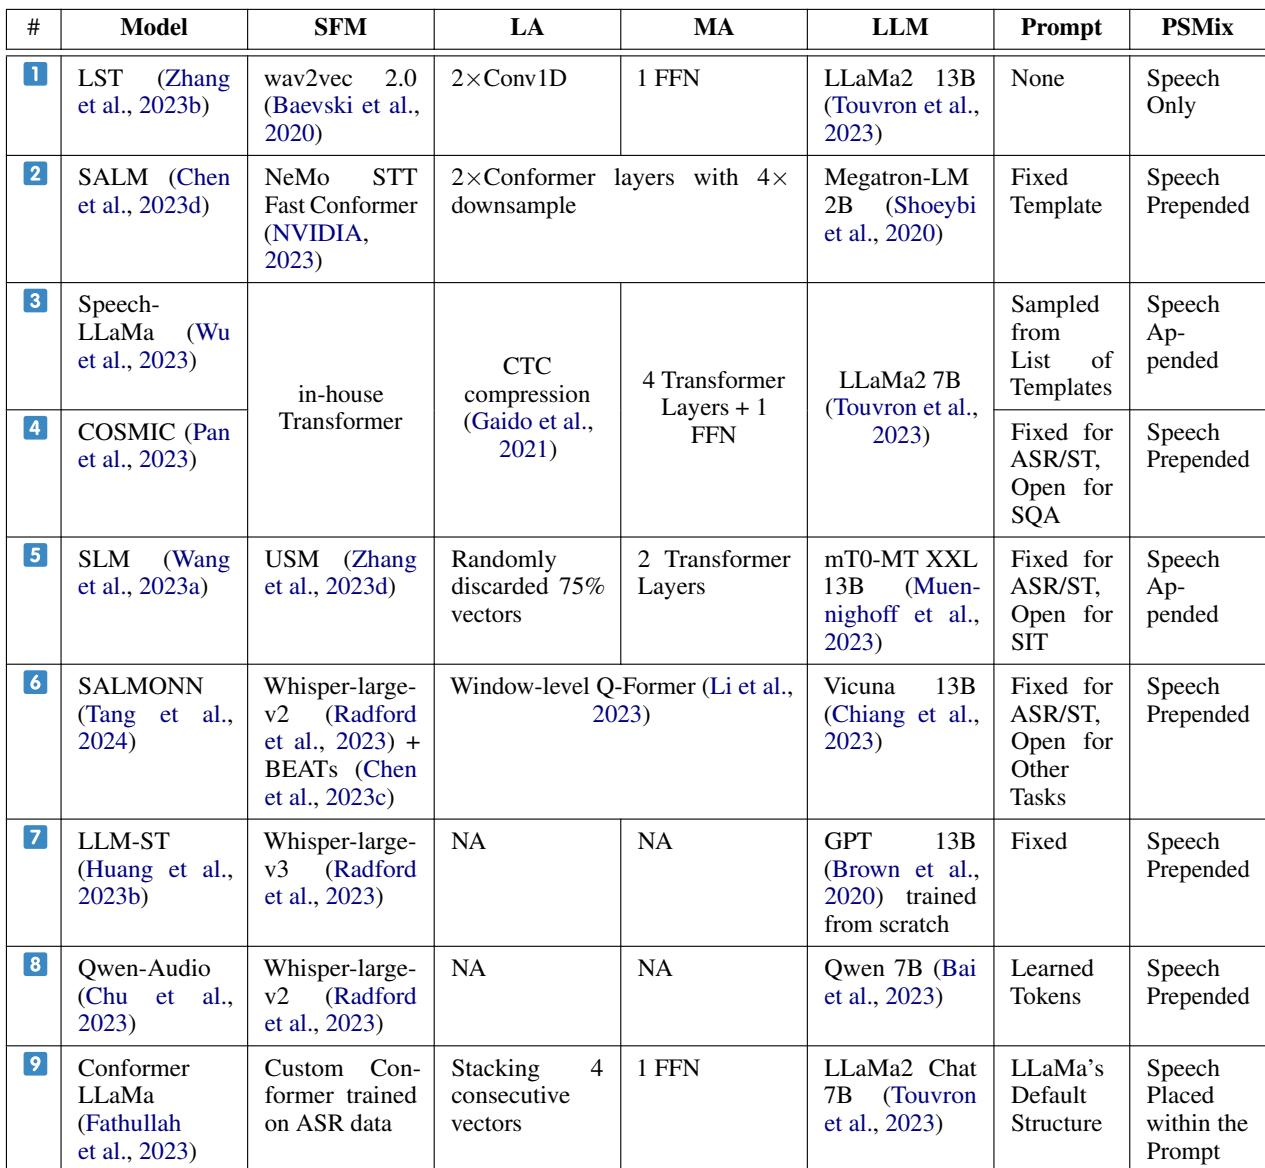
The authors organize SFM+LLM speech translation systems around a common modular pipeline. Even when individual papers differ in model choices or training strategies, the overall architecture can be decomposed into five functional components: a speech foundation model, a length adapter, a modality adapter, a prompt-speech mixer, and a large language model. Refer to the framework diagram.
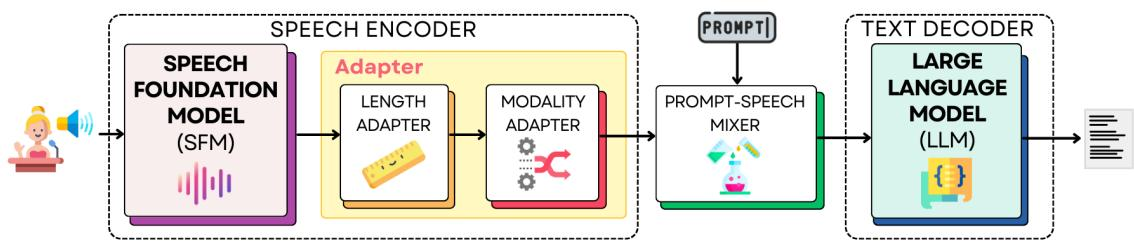
The first component is the SFM, which acts as the audio frontend. It encodes the input speech signal into a sequence of semantic embeddings that can later be aligned with the textual embedding space of the LLM. In practice, SFMs are often based on Transformer or Conformer encoders and can differ substantially in training data, language coverage, supported tasks, and public availability. Some systems rely on ASR focused encoders, while others use multilingual models trained for broader speech tasks. Because the SFM provides the main semantic bridge between audio and text, its representation quality directly affects downstream speech translation performance.
The second component is the length adapter, which reduces the temporal size of the speech embedding sequence. This step is important because audio sequences are typically longer than their corresponding text sequences, and Transformer based LLMs have self attention costs that grow quadratically with input length. Reducing the number of audio tokens therefore helps limit computational cost and memory demand while also reducing the modality mismatch between speech and text. The authors discuss several designs for this module. One family uses CTC related compression: one variant averages embeddings associated with the same CTC prediction, while another removes embeddings aligned to blank tokens. Another family uses Q-Former style adapters. In a window-level variant, the speech sequence is divided into chunks of size ns, and each chunk is processed with nq learned query vectors, reducing the sequence length by a factor of ns/nq. The authors note that length compression affects not only translation quality but also efficiency, and that systematic comparisons among adapters remain limited.
The third component is the modality adapter. This is a smaller trainable network that maps the adapted speech representation into an embedding space compatible with the LLM. It can be implemented as a simple feed-forward network, a stack of Transformer layers, or it can be fused with the length adapter. In some cases, the modality adapter is omitted entirely. Its necessity depends strongly on the training strategy. If the LLM is finetuned, the model may learn to consume the new embedding space directly, reducing the need for a separate mapping module. If the LLM and SFM are frozen, the modality adapter becomes more important because it is responsible for aligning the two representation spaces. The authors emphasize that the size and effectiveness of this adapter have not yet been analyzed systematically.
The fourth component is the prompt-speech mixer. Its role is to combine the adapted speech representations with the textual instruction prompt before feeding the combined sequence to the LLM. Many systems use fixed instruction templates, for example a phrase that asks the model to translate from a source language to a target language. The mixing can be implemented by prepending the speech tokens before the prompt embeddings, appending them after the prompt embeddings, or interleaving speech tokens between a prompt prefix and suffix. Some systems also omit the prompt entirely and provide the LLM with speech representations only. The authors point out that the relative benefits of these strategies are not yet clear.
The final component is the LLM, which receives the mixed prompt and speech sequence and generates the textual translation. This module is responsible for the core language understanding and generation behavior. Different systems use different open language models, often from the LLaMa family or variants trained for instruction following and chat style generation. The authors note that stronger pretrained language models can improve speech translation quality, but the field lacks controlled comparisons across LLM choices, especially when the surrounding speech frontend and adapter design are kept fixed.
Experiment
The experimental analysis surveyed training and evaluation settings for SFM and LLM speech translation systems, covering datasets, training tasks, finetuning choices, test benchmarks, and language pairs. It found that adapting the LLM, especially through low rank adaptation, tends to improve results, though the benefit is confounded by domain adaptation and missing scaling studies. Expanding tasks beyond ASR and ST can increase generalization and emergent capabilities, but the effect on translation quality varies across language directions. Overall, heterogeneous data, task designs, benchmarks, and English-centric language coverage make fair cross model comparisons difficult.
The surveyed SFM+LLM systems share a common structure built around a speech foundation model, adapters, a prompt-speech mixer, and an LLM, but they differ widely in component choices and training configurations. Results suggest that adapting the LLM gives significant speech translation gains, while the sources of remaining performance differences are unclear. Benchmark and language coverage are inconsistent, although CoVoST2 is commonly used and the methods are broadly English-centric. Different systems choose diverse SFMs and length adapters, with little shared practice or controlled comparison under the same framework. LLM adaptation appears important for speech translation quality, but its interaction with other module designs and training choices remains uncertain. Evaluation is fragmented across test sets and directions, with CoVoST2 providing a relatively common benchmark. Supported translation settings are mostly centered on English, and many-to-English coverage tends to be broader than English-to-many coverage.
Experimental settings for SFM plus LLM systems vary widely across public versus proprietary training data, the breadth of training tasks, and the extent of model adaptation. LLM finetuning is often applied, frequently with LoRA, while SFM adaptation is less consistent and less studied. Evaluation remains fragmented around CoVoST2 and English centric translation pairs, limiting direct comparisons. Training data choices range from public corpora to in house or proprietary data, with no shared recipe across systems. Training scopes expand beyond ASR and speech translation for several models, including instruction tuning and diverse speech or audio tasks. Evaluation is concentrated on CoVoST2, while language coverage is English centered and split between English to many and many to English directions.
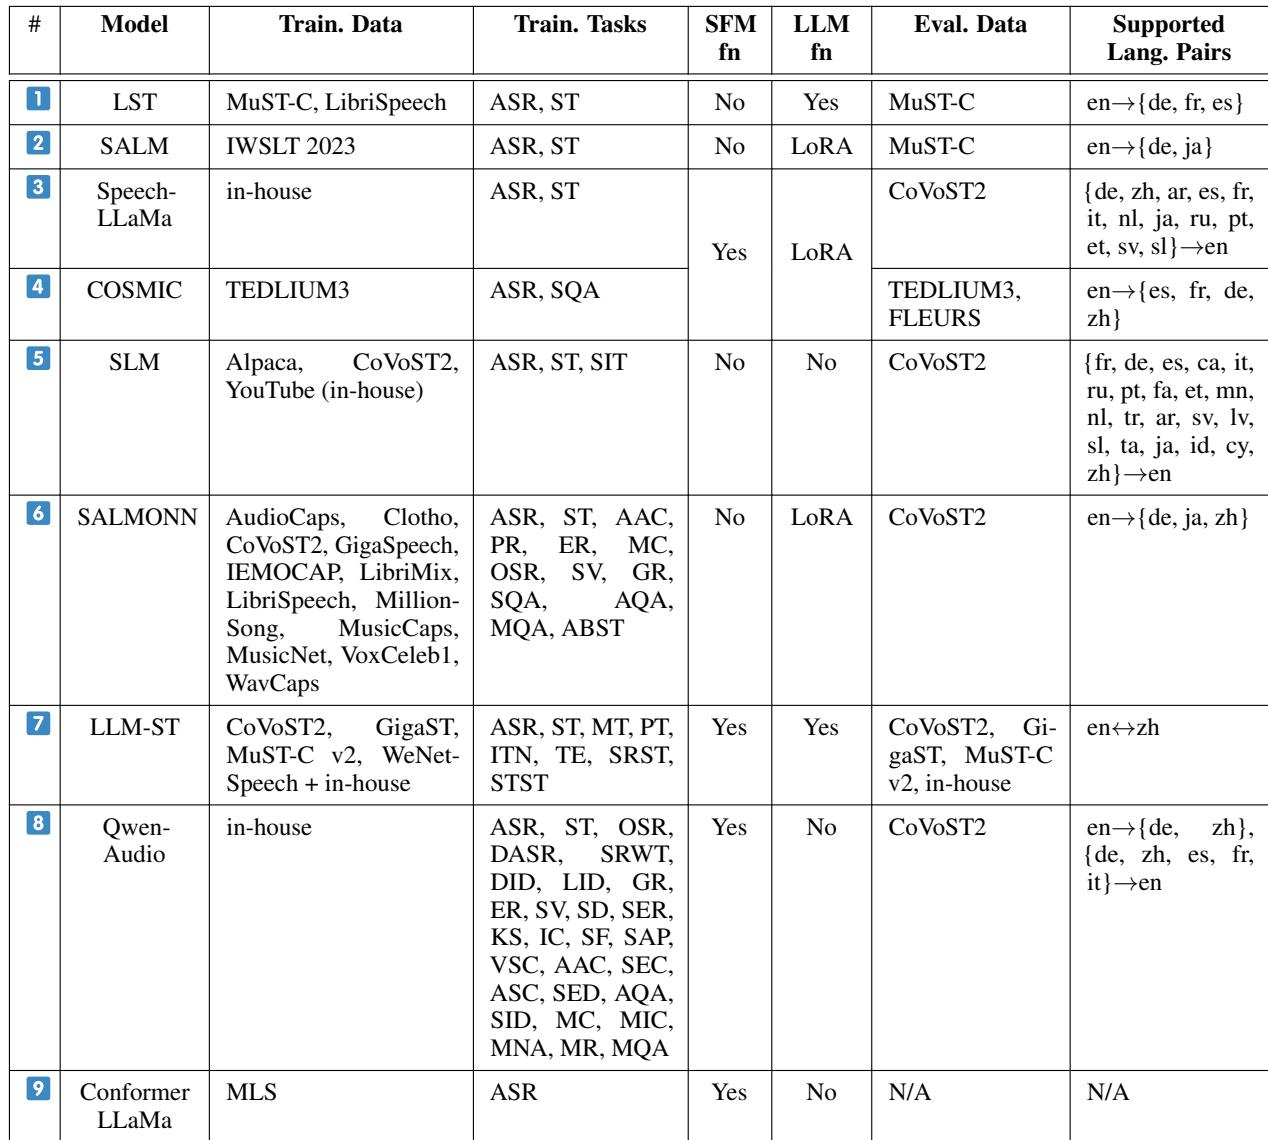
The compared SFM+LLM systems are evaluated across speech translation tasks with varying architectures, training data sources, task scopes, and adaptation methods. Experiments indicate that LLM adaptation, often implemented with LoRA, provides major gains in translation quality, while the impact of other component choices remains uncertain because settings are rarely controlled. Evaluation is fragmented around CoVoST2 and mostly English-centric translation pairs, limiting direct comparison and highlighting inconsistent benchmark and language coverage.