Command Palette
Search for a command to run...
التعرّف على إيماءة اليد إلى الفم متعددة الوسائط في مقاطع الفيديو المدمجة RGB-الحرارية الموجَّهة نحو النشاط (ملخّص طالب)
التعرّف على إيماءة اليد إلى الفم متعددة الوسائط في مقاطع الفيديو المدمجة RGB-الحرارية الموجَّهة نحو النشاط (ملخّص طالب)
Glenn Fernandes Meixi Lu Farzad Shahabi Jiayi Zheng Aggelos Katsaggelos Nabil Alshurafa
الملخص
تُحدث السلوكيات المحفوفة بالمخاطر الصحية، مثل الإفراط في الأكل والتدخين، أثرًا جوهريًا في الصحة العامة، مما يجعل رصدها والتخفيف من حدّتها أمرًا بالغ الأهمية. وتُستخدَم كاميرات RGB-الحرارية القابلة للارتداء لمراقبة هذه السلوكيات عبر التقاط إيماءات اليد إلى الفم (HTM). غير أنّ نماذج الكشف المعتمدة على وسائط مفردة، سواء كانت RGB أو حرارية، غالبًا ما تعاني من صعوبة التمييز الدقيق بين الإيماءات المتشابهة المرتبطة بالأكل أو التدخين، وذلك بسبب قيود الاستشعار الجوهرية، كالانحساس تجاه ظروف الإضاءة أو الانحجابات الحرارية. نقدّم هنا عائلة من نماذج الدمج التي تُدمج بيانات الفيديو الحرارية وبيانات RGB باستخدام بنية دمج مبكّر ودمج على مستوى القرار وبنية دمج وسطي جديدة نسمّيها شبكة فيديو الدمج RGB-الحرارية (RTFVNet)، وذلك بهدف تعزيز التعرّف على إيماءات اليد إلى الفم المرتبطة بالأكل والتدخين. تُظهر نتائج تقييمنا أنّه على الرغم من تحقيق الدمج على مستوى القرار أعلى درجة F1 تبلغ 88% (0.44 TFLOPs)، فإنّ RTFVNet يوفّر توازنًا أمثل بين الأداء (85%) والتعقيد الحسابي (0.37 TFLOPs) في تصنيف إيماءات الأكل والتدخين والأنشطة غير الإيمائية.
One-sentence Summary
Northwestern University proposes RTFVNet, a novel mid-fusion architecture within a family of early-, decision-, and mid-fusion RGB-Thermal models that recognizes hand-to-mouth gestures for eating and smoking monitoring in wearable footage, achieving an optimal balance between 85% F1-score and 0.37 TFLOPs computational cost.
Key Contributions
- An RGB-Thermal video dataset of 441.9 hours captured in free-living environments is provided for multi-class hand-to-mouth gesture recognition of eating, smoking, and non-gesture activities.
- A family of early-, mid-, and decision-fusion models combines RGB visual detail with thermal heat cues to distinguish confounding eating, smoking, and non-gesture hand-to-mouth gestures.
- RGB-Thermal Fusion Video Network (RTFVNet), a novel mid-fusion architecture, is presented for multi-class hand-to-mouth gesture recognition in activity-oriented camera footage; RTFVNet reaches 85% F1 at 0.37 TFLOPs, offering an optimal balance of accuracy and computational complexity compared with decision fusion at 88% F1 and 0.44 TFLOPs.
Introduction
RGB-Thermal wearable Activity-Oriented Camera systems are necklace-mounted devices that monitor health-risk behaviors such as eating and smoking from a non-egocentric perspective. This matters because reliable detection of hand-to-mouth gestures can support behavior tracking, health monitoring, and intervention. Prior work usually relied on RGB or thermal data alone, but RGB struggles in low light while thermal can be affected by ambient temperature changes and occlusions. To address these limitations, the authors contribute a large free-living RGB-Thermal video dataset, a family of fusion models for distinguishing eating, smoking, and non-gesture activities, and RTFVNet, a mid-fusion architecture designed for efficient multi-class gesture recognition.
Dataset
-
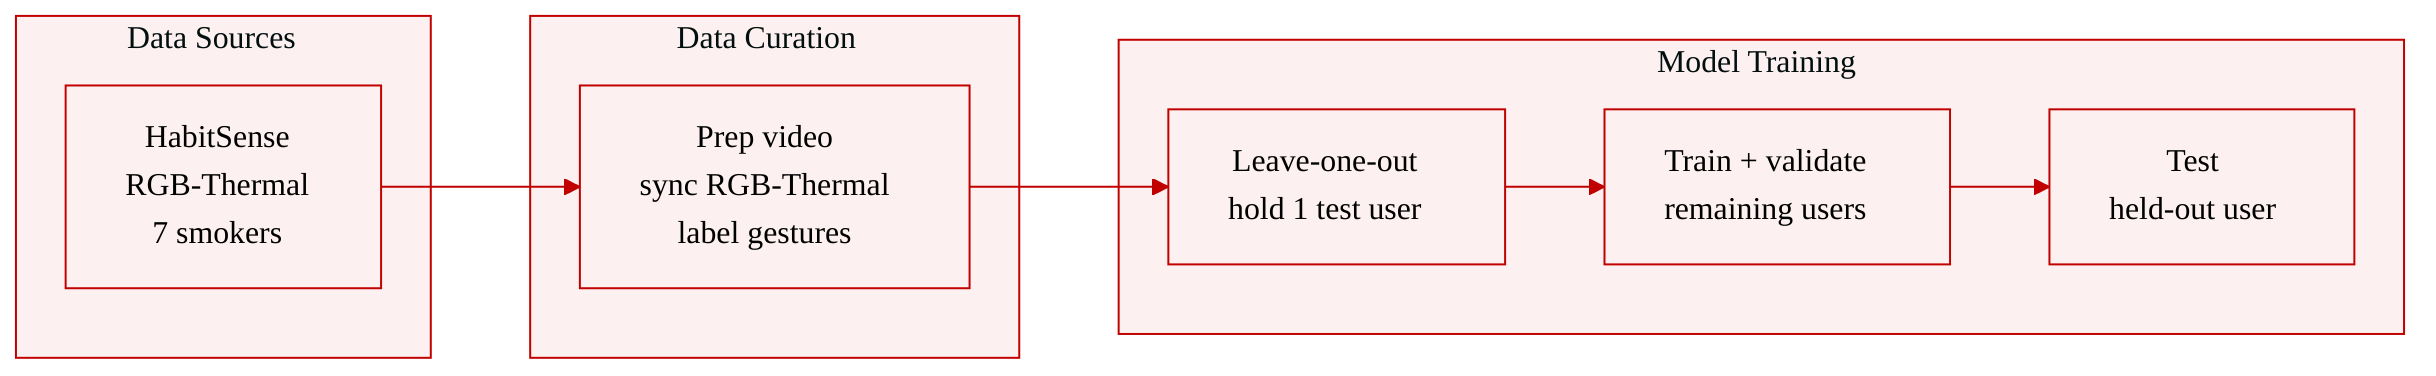
Dataset source: The authors collected the dataset using HabitSense, a neck-worn RGB-Thermal camera system designed to record activity-oriented video from the wearer’s face.
-
Dataset scale and composition: The dataset contains 441.9 hours of paired RGB and thermal video, collected from 7 smokers.
-
Modality setup: Each sample includes synchronized RGB and Thermal streams, reflecting the RGB-Thermal nature of the sensing system.
-
Annotation schema: The dataset is annotated with start and end points for eating and smoking gestures, providing temporal segment labels for these target actions.
-
Subset details: The provided text describes a single RGB-Thermal dataset rather than multiple labeled subsets, with participant information limited to the number of subjects.
-
Data usage in evaluation: The authors use the dataset for gesture recognition experiments and evaluate models using leave-one-participant-out cross-validation.
-
Training/validation strategy: Under this protocol, data from one participant are held out for testing, while the remaining participants are used for training and validation.
Method
The proposed framework uses three fusion strategies to distinguish eating, smoking, and non gesture activities from paired RGB and thermal video streams. For decision fusion, the authors train two independent TimeSformer classifiers, one on the RGB stream and one on the thermal stream, then combine their predicted class outputs. For early fusion, RGB and thermal frames are concatenated before being input into a single TimeSformer model, allowing the video transformer to process the combined visual signal from the beginning.
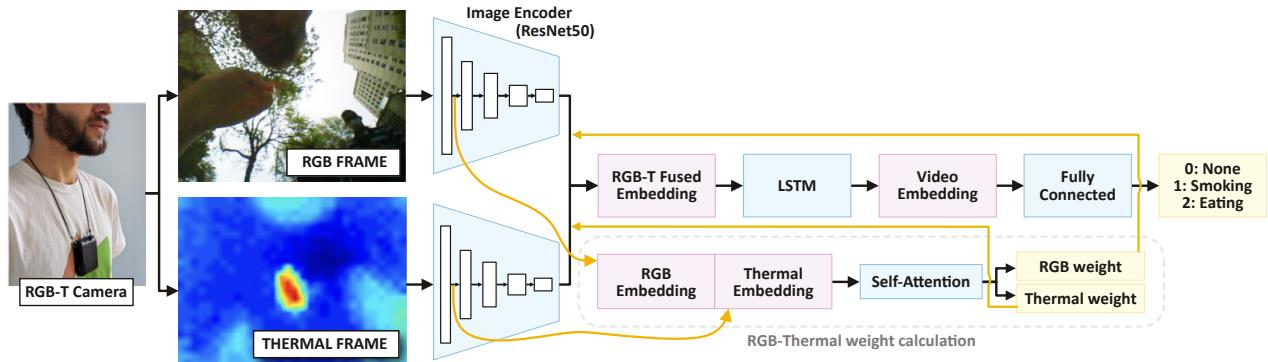
The core contribution is RTFVNet, a novel mid fusion architecture adapted for multiclass gesture classification. The design is inspired by RGB thermal segmentation networks, but it removes the shortcut connections that transfer thermal encoder features into the RGB encoder. This modification allows each encoder branch to specialize in extracting features from its own modality, reducing cross modal interference before fusion and improving the use of modality specific evidence.
As shown in the architecture diagram:
In this module, RGB and thermal frames are first processed by separate early ResNet50 encoders. These encoders extract spatial embeddings from each modality independently. The RGB and thermal embeddings are then concatenated to form a joint representation. A self attention mechanism estimates the relative importance of the RGB and thermal streams for each frame pair. If zRGB and zT denote the latent features and wRGB and wT denote the learned modality weights, the fused representation can be expressed as:
z=wRGBzRGB+wTzTThe weighted features are then combined and passed through an LSTM layer to capture temporal dependencies across frames. A fully connected layer finally maps the resulting video embedding into three classes: none, smoking, or eating. The complete model family is trained and evaluated using leave one participant out cross validation, with performance assessed through classification metrics and computational cost.
Experiment
The experiments evaluate RGB-Thermal eating and smoking gesture recognition on a multi-participant dataset collected with a neck-worn HabitSense system, using leave-one-participant-out validation to compare single-modality and fusion approaches. These tests show that thermal and RGB streams each capture useful but incomplete cues, while decision fusion can improve accuracy at the expense of much higher computation. The proposed mid-fusion RTFVNet is validated as a more efficient alternative that retains strong recognition performance without the heavy cost of decision-level fusion.
The results compare single-modality RGB and thermal models with early, mid, and decision fusion approaches for detecting gestures. Decision fusion achieves the highest overall accuracy but has the highest computational cost, while mid fusion with RTFVNet provides a strong balance of performance and efficiency. RGB-based models generally outperform thermal-only models in the reported metrics. Decision fusion gives the best F1-score but requires about twice the compute of the single-modality models. Mid fusion with RTFVNet improves on RGB, thermal, and early fusion while using less compute than decision fusion. Thermal-only modeling has the lowest reported performance among the compared architectures.
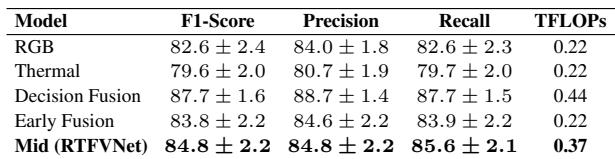
The experiments evaluate RGB, thermal, and fused models for gesture detection, comparing early, mid, and decision fusion. Decision fusion achieves the best overall accuracy and F1-score but requires roughly twice the compute of single-modality models. Mid fusion with RTFVNet provides a stronger performance efficiency balance than RGB, thermal, and early fusion, while RGB models generally outperform thermal-only models, which show the weakest results.