Command Palette
Search for a command to run...
Coda-DaVinci: إعادة تصور توليد الفيديو باستخدام Code2Video
Coda-DaVinci: إعادة تصور توليد الفيديو باستخدام Code2Video
الملخص
يستخدم Code2Video وكلاء ثلاثية الأبعاد من تأليف الوكيل لتوجيه توليد الفيديو، مما يتيح تحكمًا صريحًا في البنية والديناميكيات. ومع ذلك، لا يزال كيفية بناء الوكلاء والمطالبات لتحقيق جودة مثلى للمراحل اللاحقة غير مستكشفة بشكل كافٍ، وكذلك قدرات هذا النموذج وقيوده. من خلال تجارب مضبوطة وتقييم بشري معمى، ندرس دقة الوكيل، ومحاكاة الفيزياء، وصياغة المطالبات. تكشف النتائج عن مقايضات تعتمد على المهمة: تفضل الوكلاء الخشنة الحركة الطبيعية، بينما تفضل الوكلاء متوسطة الدقة الاتساق. كما تعمل محاكاة الفيزياء والمطالبات المتوافقة مع الوكيل على تحسين متوسط الجودة. واسترشادًا بهذه النتائج، نقدم Coda-DaVinci، وهو إطار وكيل تكيفي مع المهام لتوليد Code2Video يختار بين التوليد الموجه بالوكيل والتوليد المباشر، ويكيف دقة النمذجة لكل كيان، وينسق المحاكاة مع المطالبات المرتكزة على الوكيل. يحافظ حزام الوكلاء المتعددين على أصول المشهد ويوجه الإصلاحات من خلال الفحص البصري والمراجعة المستقلة. تُظهر التجارب ريادة في اتباع التعليمات على VTR واتساق المشهد على R2M، وتحسنًا في المعقولية الفيزيائية مقارنة بالتوليد المباشر، وواقعية بصرية أعلى من خطوط الأساس المقارنة لـ Code2Video. كما تُظهر تقييمات الفيديو الطويل مكاسب في بنية الأحداث والاتساق عبر التفاعلات المتتالية، مع كشف قيود في استقرار الانتقالات والالتزام بإعدادات المشهد.
One-sentence Summary
Researchers from Nanjing University, KlingAI Research, Peking University, et al. propose Coda-DaVinci, a task-adaptive agentic Code2Video framework that selects between proxy-guided and direct generation, adapts modeling granularity per entity, and coordinates physics simulation with proxy-grounded prompting; experiments show leading instruction following on VTR and improved scene consistency on R2M.
Key Contributions
- The paper systematically analyzes proxy granularity, physics simulation, and prompting in Code2Video generation, identifying task-dependent trade-offs such as coarse proxies favoring natural motion and medium-grained proxies favoring consistency.
- The paper introduces Coda-DaVinci, a task-adaptive agentic framework that selects between proxy-guided and direct generation, adapts modeling granularity per entity, and coordinates physics simulation with proxy-grounded prompting through a persistent scene workspace, visual inspection, and independent acceptance review.
- The paper empirically characterizes Code2Video capabilities and limitations across tasks, agent-generator pairings, rendering engines, and long-video settings. It reports leading instruction following on VTR, scene consistency on R2M, improved physical plausibility over direct generation on World Models’ Last Exam in Physics, higher visual realism than the compared Code2Video baselines on the T2AV-Compass subset, and remaining limitations in transition stability and setting adherence.
Introduction
Recent video generation models can synthesize realistic clips from text or reference media, but they still struggle with detailed instruction following, scene-state consistency, and physically plausible interactions. Code2Video approaches address this by using a coding agent to construct and render a 3D proxy that guides video synthesis, yet prior methods are sensitive to proxy design: overly detailed proxies can introduce geometric or motion errors, reduce motion naturalness, and complicate prompt alignment. The authors investigate these tradeoffs through controlled human evaluations and derive task-dependent guidelines for proxy granularity, physics simulation, and prompting. Their main contribution is Coda-DaVinci, a task-adaptive agentic framework that selectively uses 3D modeling, medium-grained or coarse proxies, Blender-based physics, agent-authored prompts, persistent scene assets, and visual feedback to improve instruction following, consistency, and physical plausibility over prior Code2Video and direct-generation baselines.
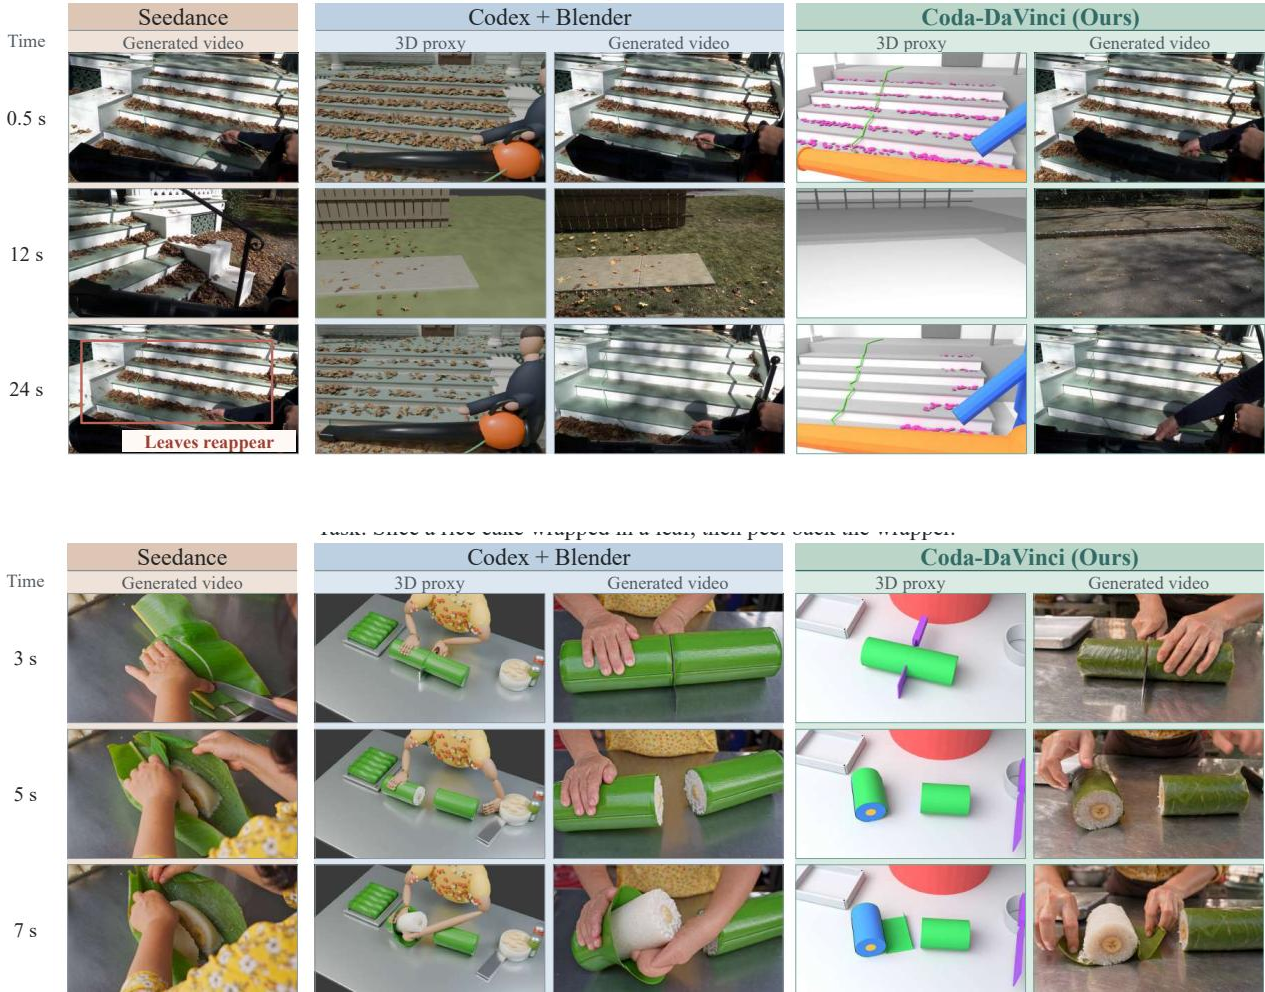
Method
The authors introduce Coda-DaVinci, a task-adaptive agentic framework designed for code-to-video generation. This system dynamically selects a generation pathway based on specific task requirements, applying tailored modeling and prompting strategies. An execution harness coordinates the entire scene construction and video synthesis process, leveraging visual feedback to guide iterative revisions.
As shown in the figure below:
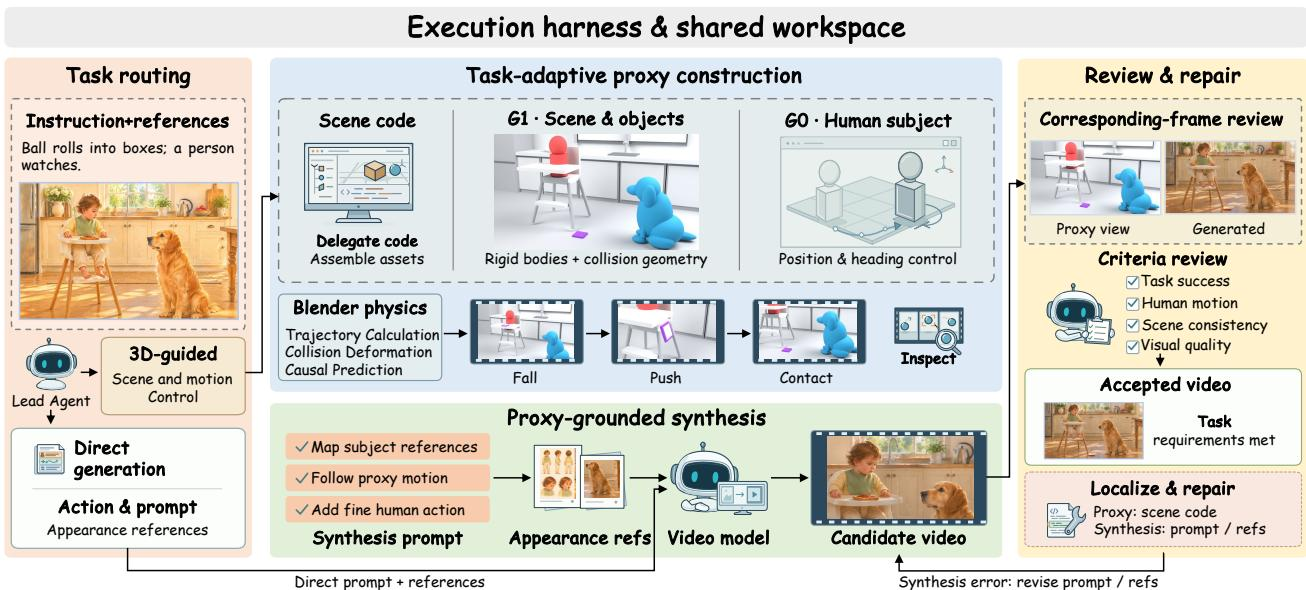
The pipeline begins with task routing, where the framework evaluates the input instruction and reference media. For tasks demanding precise control over scene structure or motion, the system selects a 3D-guided pathway utilizing scene and motion control. Conversely, for tasks centered on natural body movement where explicit control is unnecessary, it opts for direct generation to avoid the stiffness that simplified proxy animations might introduce.
In the task-adaptive proxy construction phase, the framework employs entity-wise modeling policies. It utilizes a G1 policy for environments and structured objects, handling rigid bodies and collision geometry, while a G0 policy manages human subjects through position and heading control. The system integrates Blender physics to calculate trajectories, handle collisions, predict deformations, and simulate causal interactions. A lead generation agent orchestrates this process within a shared Blender workspace, delegating separable modeling tasks to coding subagents and integrating the returned assets for inspection.
Following proxy construction, the framework transitions to proxy-grounded synthesis. The agent inspects the rendered proxy sequence and revises the scene code if the depicted events deviate from the initial request. It then formulates a synthesis prompt that links subject descriptions to the corresponding proxy entities and appearance references, ensuring the prompt follows the proxy actions while specifying fine-grained visual details. Before synthesis, the harness verifies the alignment between the proxy video and its shot description. The generation tool subsequently passes the prompt, proxy video, and reference media to the video model to produce a candidate video. The direct generation pathway bypasses the proxy, directly supplying a task-derived action and camera prompt alongside available references.
To ensure high-quality outputs, the system implements a robust review and repair mechanism. Visual inspection compares generated frames side-by-side with corresponding proxy views to pinpoint discrepancies. Errors originating in the proxy trigger scene code revisions, whereas synthesis-induced discrepancies prompt adjustments to the prompt or reference inputs. An independent acceptance agent evaluates each candidate against the original task criteria, including task success, human motion, scene consistency, and visual quality. If requirements are unmet, the harness localizes the failure and returns specific instructions for repair, maintaining a continuous feedback loop until the final video is accepted.
Experiment
The first set of experiments analyzes code-to-video design choices by varying proxy granularity, physics simulation, and prompt enhancement across scene revisitation, instruction following, and physical simulation benchmarks, showing that Code2Video most consistently improves consistency and instruction following while fine motion remains challenging; medium-grained proxies with physics simulation and agent-guided prompt enhancement form the best overall configuration, while coarse proxies can improve naturalness on motion-heavy tasks. The second set evaluates Coda-DaVinci against direct generation, agentic baselines, and other code-to-video methods, finding that it leads in scene consistency and instruction following, with explicit scene modeling improving physical fidelity and adaptive routing preserving visual realism. Ablations show robustness across coding agents, benefits from independent review and entity-wise granularity, and higher quality with Blender at greater token cost, while long-video and qualitative results indicate that reusable 3D scenes support state persistence across clips though some transition and continuity limitations remain.
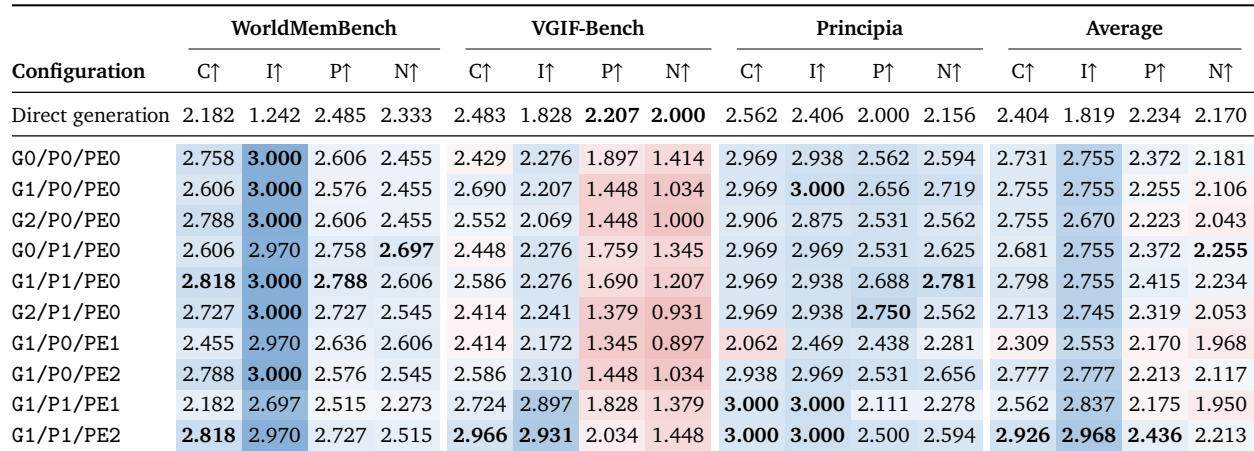
Explicit 3D proxy configurations improve consistency and instruction following over direct generation across the evaluated benchmarks. On WorldMemBench and Principia they outperform direct generation on all four evaluation dimensions, while on VGIF-Bench they improve instruction following but often score lower on physical plausibility and naturalness/realism. The best overall configuration, G1/P1/PE2, leads the pooled four-metric mean and consistency, instruction following, and physical plausibility averages, though its naturalness/realism average trails a coarser proxy setting. On WorldMemBench and Principia, all structured configurations outperform direct generation on consistency, instruction following, physical plausibility, and naturalness/realism. On VGIF-Bench, structured configurations improve instruction following but tend to reduce physical plausibility and naturalness/realism. With PE0 fixed, coarse-grained proxies lead on physical plausibility and naturalness for VGIF-Bench, while medium-grained proxies often lead consistency. G1/P1/PE2 ranks first in the pooled four-metric mean and in consistency, instruction following, and physical plausibility averages; G0/P1/PE0 ranks first in naturalness/realism.
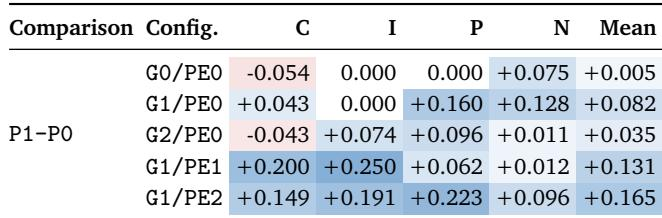
Across the pooled benchmark samples, every tested configuration improves the four-metric mean and the naturalness and realism average. Instruction following and physical plausibility either improve or remain unchanged, while consistency changes in both directions. The largest mean gain and the largest physical plausibility gain occur under the G1/PE2 configuration. The four-metric mean and the naturalness and realism average improve in every listed configuration. Physical plausibility and instruction following never decline, but consistency drops under G0/PE0 and G2/PE0. G1/PE2 produces the largest four-metric average gain and the largest physical plausibility improvement.
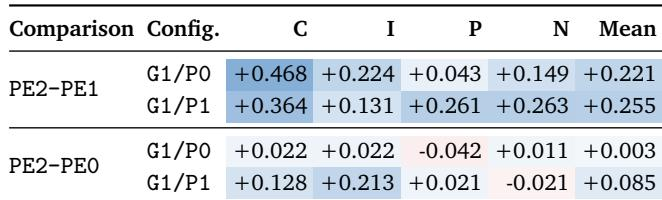
With G1 fixed, PE2 improves average performance over PE1 across consistency, instruction following, physical plausibility, and naturalness under both physics settings, with a larger mean gain under P1. Compared with PE0, PE2 shows a small overall improvement under P1, driven by consistency, instruction following, and physical plausibility, while naturalness and realism decline slightly. Under P0, the PE2 and PE0 averages are nearly equivalent. PE2 outperforms PE1 in all four metrics under both physics settings, with stronger mean improvement under P1. PE2 versus PE0 shows clear gains in consistency and instruction following under P1, but a slight decline in naturalness and realism.
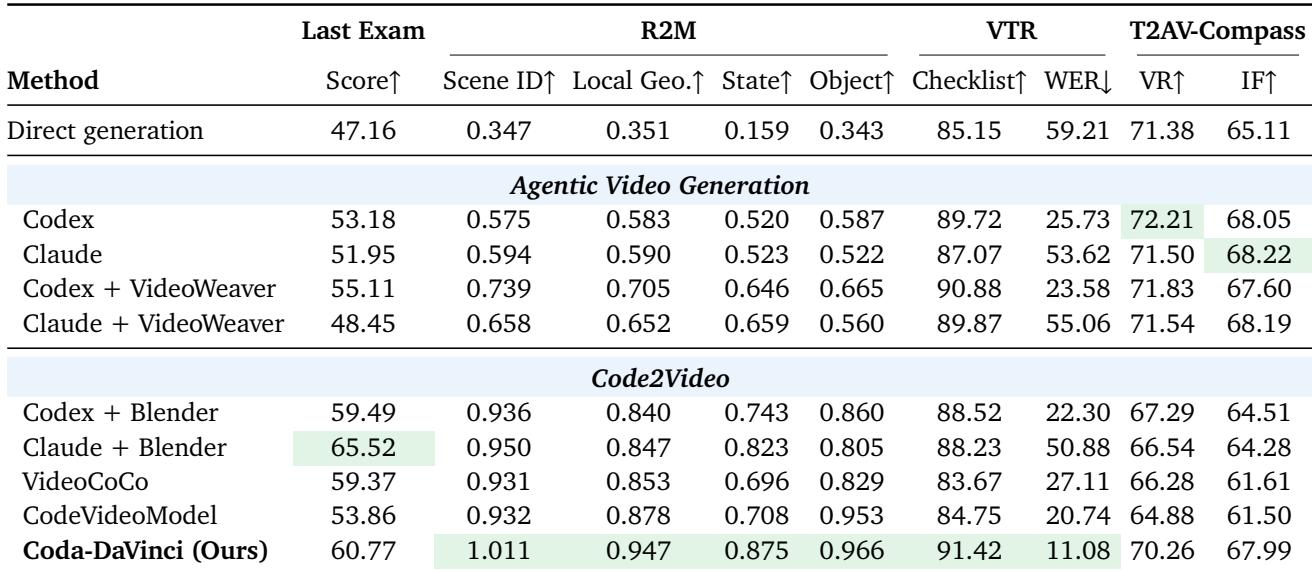
Compared with direct generation, agentic video generation methods improve the overall exam score, R2M, VTR, and most T2AV-Compass scene understanding dimensions. Codex + VideoWeaver is the strongest overall on exam score, R2M, VTR, local geometry, and state, while direct generation still leads on object score and word error rate. The results indicate that adding explicit scene modeling helps instruction following and state-related metrics but does not improve all evaluation dimensions uniformly. Codex + VideoWeaver leads on last exam score, R2M, VTR, local geometry, and state; Claude + VideoWeaver leads on T2AV-Compass scene ID. Direct generation has the best object score and the lowest word error rate, showing a trade-off in explicit modeling methods.
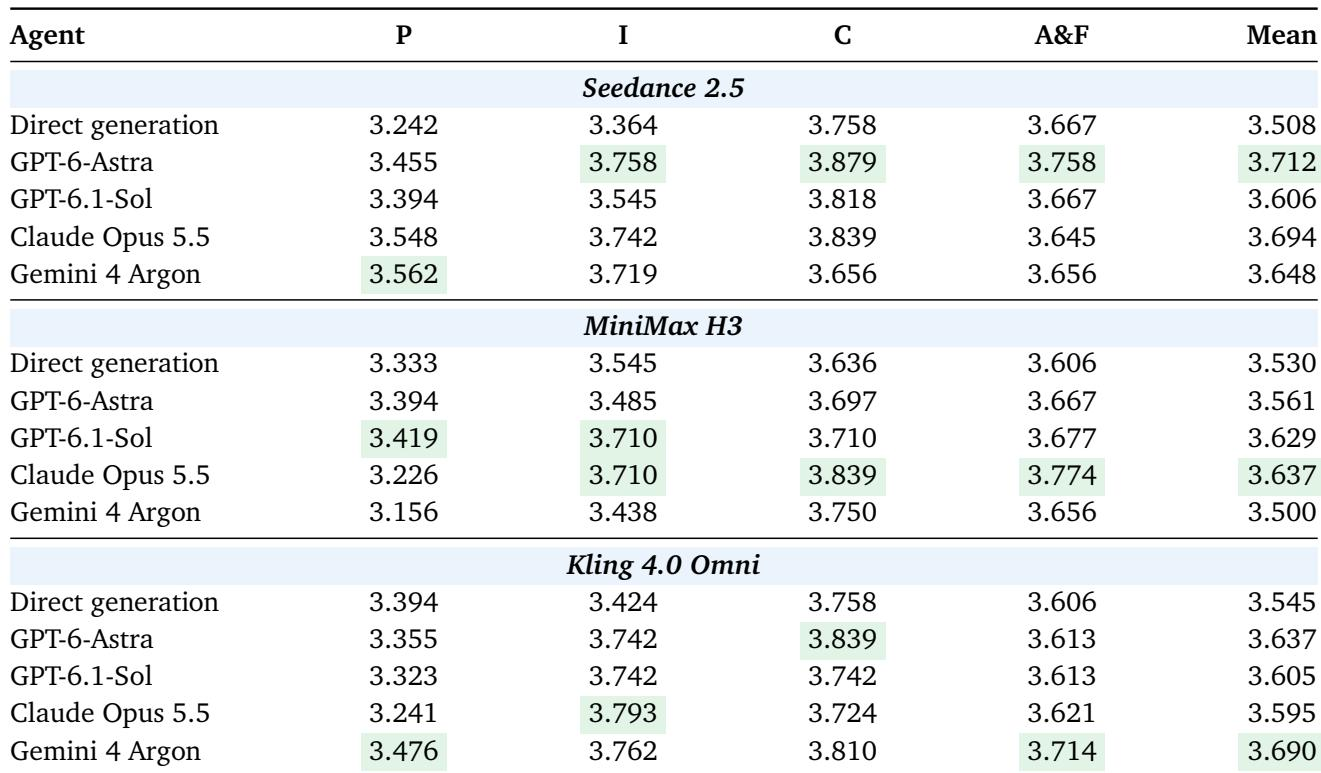
Adding a coding agent improves mean video quality over direct generation, and overall scores remain similar across the tested coding agents. Removing independent acceptance, adaptive routing, or entity-wise granularity lowers all evaluated dimensions, with independent acceptance contributing most to consistency. Both Blender and Three.js improve over direct generation; Blender scores higher across dimensions but requires roughly twice the agent tokens. Direct generation has the lowest mean compared with coding agent configurations on the Seedance 2.5 subset. Independent acceptance is especially important for visual consistency; fixed routing or uniform entity granularity mainly affects instruction following and aesthetics. Blender outperforms Three.js on all four dimensions but has roughly double the token cost.
These experiments compare explicit 3D proxy configurations and agentic video generation pipelines against direct generation across several benchmarks. Structured proxy settings generally improve consistency and instruction following, with G1/P1/PE2 performing best overall, although naturalness and realism can favor coarser proxies and VGIF-Bench shows trade-offs in physical plausibility. Agentic coding pipelines improve mean video quality and exam-related metrics over direct generation, with Codex + VideoWeaver strongest on scene and state understanding, while direct generation remains better on object fidelity and word error rate; ablations show independent acceptance and Blender contribute notably to consistency and quality.