Command Palette
Search for a command to run...
من TeleChat إلى Xing4: تطوير نماذج وكيلية رائدة على رقاقات وأطر عمل محلية
من TeleChat إلى Xing4: تطوير نماذج وكيلية رائدة على رقاقات وأطر عمل محلية
الملخص
نقدم Xing 4، وهي سلسلة من نماذج اللغة الكبيرة التي توسع سلالة TeleChat من خلال تطورات منسقة في بنية النموذج والبنية التحتية للتدريب على منصة Ascend. في حين تُدرَّب معظم النماذج مفتوحة المصدر على وحدات معالجة الرسوميات، فإن التوسع على الرقاقات وأطر العمل المحلية يطرح تحديات أنظمة كبيرة. يصف هذا التقرير مبادئ التصميم وهندسة النظم الكامنة وراء السلسلة، ويغطي اختيار البنية، والتدريب المسبق واسع النطاق، والتدريب اللاحق الاستدلالي والوكيلي. ندرس كيف توازن آليات التنشيط المتفرق، وتصميم الانتباه، وعمق النموذج وعرضه، وفك الترميز التخميني بين سعة النموذج والحساب، والوصول إلى الذاكرة، وأعباء التنفيذ. تجمع الإعدادات التمثيلية بين MLA وDSA ومشاركة الفهرس عبر الطبقات لخدمة السياقات الطويلة، وتدمج مشغلات MHC محسّنة لتعزيز الاستقرار والكفاءة الحسابية، وتعتمد طوبولوجيا خليط الخبراء الأوسع والأقل عمقًا، وتقرن نموذج مسودة كتليًا برؤوس تصحيح خفيفة لفك الترميز التخميني. لقد فتحنا المصدر لعضو MoE بحجم 29B، وهو نموذج دُرِّب بالكامل على وحدات Ascend NPU باستخدام MindSpore، ينشط 4B معلمة فقط لكل رمز مع دعم سياقات أصلية بطول 256 ألف رمز. تعتمد بنيتنا التحتية للتدريب المسبق على MindSpore HyperParallel، وتجمع بين التجزئة الهجينة المدركة للطوبولوجيا، والتنفيذ الفعال للموزع الموزع، والإدارة المنسقة لأعباء العمل ذات التسلسلات الطويلة وذاكرة التنشيط. كما يقلل تقييد المعالجات وعزل النوى من تداخل جدولة المضيف. تدعم هذه الآليات مجتمعةً التدريب المسبق لنموذج بحجم 285B معلمة على 8192 بطاقة Ascend 910C مستمدة من عنقود إنتاج واسع النطاق، مما يوفر بيئة ملموسة للدراسات المعمارية والأنظمة. تُظهر القياسات تحسنًا في إنتاجية التعبئة المسبقة يصل إلى 4.68× مقارنة بخط أساس يعتمد على MLA فقط، وتحسنًا في إنتاجية فك الترميز يتراوح بين 2.67× و3.77× بفضل فك الترميز التخميني، وتحسنًا بنسبة 16.1% في الإنتاجية عند إزالة توازي خطوط الأنابيب. بالنسبة للتدريب اللاحق، نقدم TeleGym، وهي منصة موحدة لتنفيذ الوكلاء تربط التنفيذ والتقييم وبناء المسارات بتحسين السياسات. يستوعب التنفيذ غير المتزامن المفكك، والإفراط المحدود في أخذ العينات، والتشغيل الجزئي مدد المهام غير المتجانسة مع الحفاظ على استمرارية المسارات عبر تحديثات السياسة. تؤسس هذه التطورات مجتمعةً أساسًا تدريبيًا موجهًا نحو Ascend للتطوير المستمر لـ Xing 4 عبر مقاييس النماذج وأعباء العمل الاستدلالية والوكيلية المتزايدة التعقيد. كما يوسع العضو مفتوح المصدر بحجم 29B والتدريب الجاري بتريليون معلمة السلسلة ضمن منظومة Ascend وMindSpore.
One-sentence Summary
Researchers from Xingchen AGI Lab, China Telecom, Huawei, and Harbin Institute of Technology (Shenzhen) introduce Xing 4, a TeleChat-derived agentic model series trained on Ascend NPUs and MindSpore that combines MLA, DSA, cross-layer IndexShare, optimized MHC operators, a wider-and-shallower mixture-of-experts topology, and block-wise speculative decoding with lightweight correction heads; the open-sourced 29B MoE member activates only 4B parameters per token, supports native 256K-token contexts, and achieves up to 4.68× prefill throughput, 2.67× to 3.77× decoding throughput from speculative decoding, and a 16.1% throughput improvement from eliminating pipeline parallelism, while TeleGym supports agent post-training through disaggregated asynchronous execution, bounded oversampling, and partial rollout.
Key Contributions
- The paper contributes a coordinated architecture and decoding design for the Xing 4 model series, combining MLA with DSA and cross-layer IndexShare for long-context serving, optimized MHC operators, a wider-and-shallower MoE topology, and a block-wise draft model with lightweight correction heads for speculative decoding. An open-sourced 29B MoE member trained entirely on Ascend NPUs activates 4B parameters per token with native 256K-token contexts, and measurements show up to 4.68× prefill throughput over an MLA-only baseline, 2.67× to 3.77× decoding throughput from speculative decoding, and a 16.1% throughput improvement from eliminating pipeline parallelism.
- This work contributes an Ascend-oriented large-scale pretraining system built on MindSpore HyperParallel, integrating topology-aware hybrid sharding, owner-based Muon execution, long-sequence workload balancing, KV compaction, activation-memory management, and CPU affinity and core isolation. The system is demonstrated by pretraining a 285B-parameter MoE model on 8,192 Ascend 910C cards.
- This work presents TeleGym, a unified agent execution platform that connects execution, evaluation, and trajectory construction to policy optimization, using disaggregated asynchronous execution, bounded oversampling, and partial rollout to accommodate heterogeneous task durations while preserving trajectory continuity across policy updates.
Introduction
The Xing 4 series extends the TeleChat family of large language models, building on prior pretraining, instruction tuning, reasoning, and mixture-of-experts work while targeting long-context reasoning, code generation, and agentic applications on the Ascend and MindSpore ecosystem. Scaling such models introduces practical bottlenecks: larger capacity must be balanced against per-token computation and the cost of storing, communicating, and updating the full model, while long-context attention adds indexing, KV-access, and activation-memory costs; packed documents can also create uneven computational loads, and host scheduling or variable task durations can stall training and reinforcement learning. The authors address these challenges through Ascend-oriented architectural design that jointly considers sparse activation, compressed KV attention, depth-width tradeoffs, and speculative decoding; a pretraining system with topology-aware sharding, owner-based Muon optimization, long-sequence workload balancing, and CPU scheduling controls; and TeleGym, a unified asynchronous reinforcement-learning platform for reasoning, coding, and multi-turn agent tasks.
Dataset
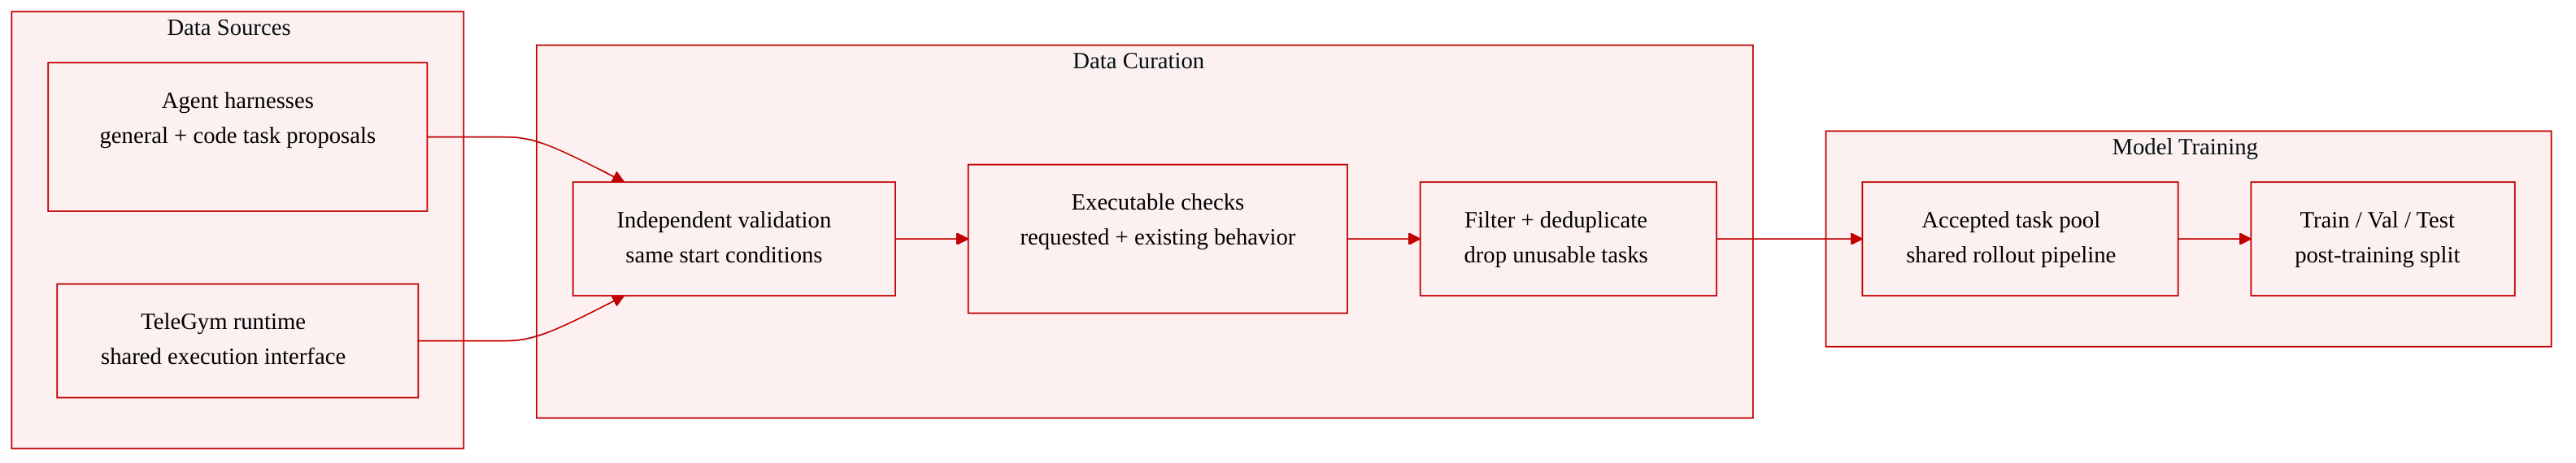
The authors describe a synthesized task dataset for post-training general and code agents. It is not drawn from a static corpus. Instead, tasks are proposed, refined, validated, and deduplicated through multiple agent harnesses, with execution handled through the TeleGym runtime.
-
Dataset composition and sources
- General-agent tasks are built around information retrieval, document processing, and tool use.
- Code-agent tasks are built around software projects and programming requirements, including implementation and bug fixing.
- Multiple harnesses contribute to task design, instruction refinement, test review, and validation.
-
General-agent subset
- Instructions are paired with relevant files and tool interfaces.
- Covers single-turn and multi-turn scenarios with varied constraints and interaction steps.
- Feedback from multiple harnesses is used to refine instructions, tool requirements, and evaluation criteria.
- Validation uses programmatic checks or model-based assessment against shared criteria.
-
Code-agent subset
- Tasks start from an initial code workspace and dependency configuration.
- Shared executable tests verify both the requested changes and preservation of existing functionality.
- Independent attempts expose environment issues and mismatches between task descriptions and tests before selection.
-
Processing and filtering
- Each task combines an instruction, an initial environment, and evaluation criteria.
- Candidate tasks are validated independently across harnesses from equivalent task conditions.
- Validation and deduplication remove unusable or repetitive examples.
- Accepted tasks enter the shared rollout pipeline through TeleGym’s execution interface.
-
Usage in the model
- The accepted tasks are used as executable post-training tasks for general and code agents in the shared rollout pipeline.
- The text does not specify dataset sizes, training split proportions, or mixture ratios.
- No cropping strategy or explicit metadata schema is described beyond the task structure of instruction, initial environment, and evaluation criteria.
Method
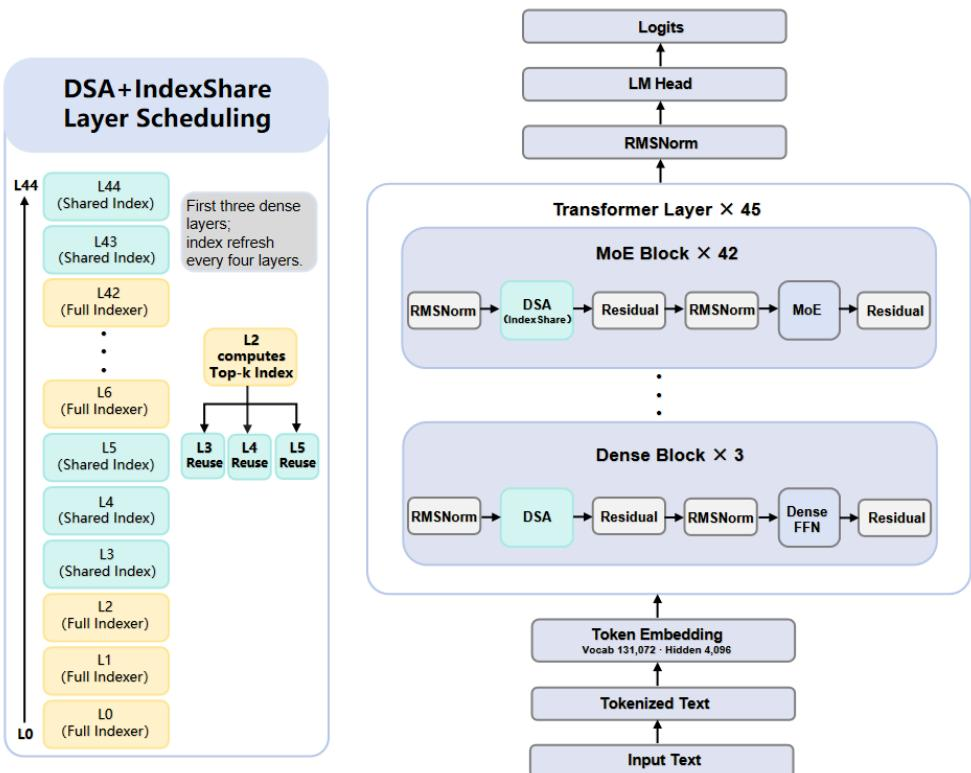
The authors design the Xing 4 architecture to balance model capacity, long-context execution, and hardware efficiency on Ascend 910C clusters. As a concrete implementation, the 285B representative model utilizes a decoder-only Mixture-of-Experts (MoE) backbone. Refer to the framework diagram for the structural layout. The model consists of 45 transformer layers, where the first three layers use Dense Feed-Forward Networks (FFNs) and the remaining 42 layers employ MoE FFNs to expand capacity through sparse activation. To address long-context inference bottlenecks, the attention mechanism combines Multi-head Latent Attention (MLA) with DeepSeek Sparse Attention (DSA) and IndexShare. MLA compresses KV representations to reduce cache memory, while DSA uses a lightning indexer to select Top-K historical KV states. IndexShare further reuses sparse indices across layers to minimize repeated indexer computation. For inference-time efficiency, the architecture integrates DSpark, a speculative decoding component that uses a block-wise draft model, a lightweight Markov head, and an acceptance confidence head to increase the number of tokens committed per verifier invocation.
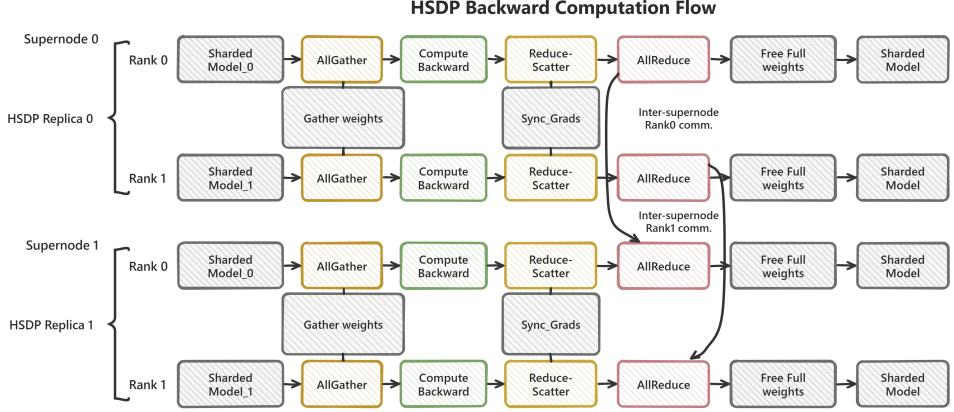
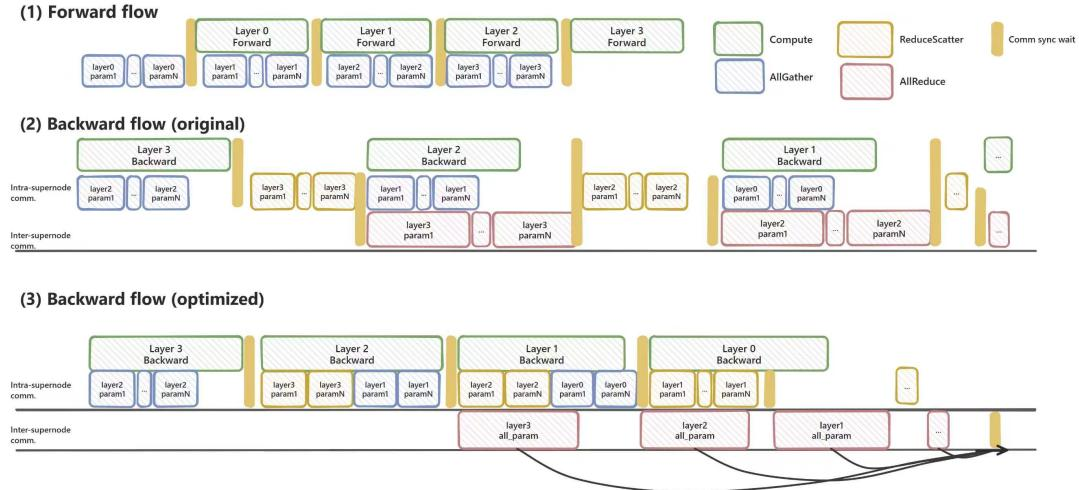
To support large-scale pretraining without the structural pipeline bubbles inherent in pipeline parallelism, the authors implement HyperParallel-FSDP, a hybrid sharded data parallelism scheme tailored to the Ascend SuperPoD architecture. Model parameters are FSDP-sharded within each SuperPoD and replicated across SuperPoDs, confining frequent weight-gathering and sharded-gradient synchronization to high-bandwidth intra-SuperPoD links. The backward-pass workflow is illustrated in the following figure.
To optimize communication, HyperParallel-FSDP eliminates the flattened intermediate buffers and associated copy-in and copy-out operations used in standard FSDP. Instead, it performs AllGather and ReduceScatter directly on individual parameter tensors, achieving zero-copy communication as shown in the comparison below.
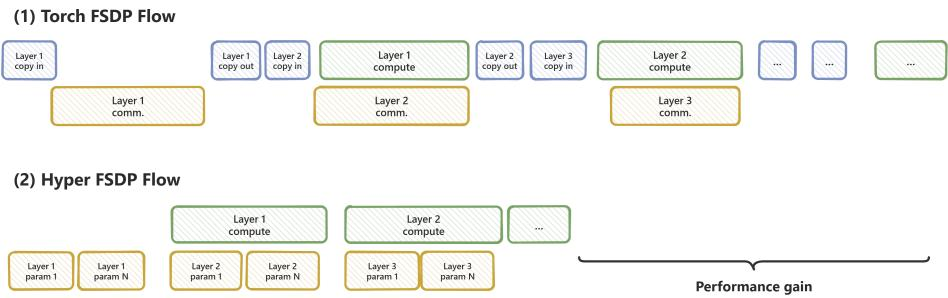
Furthermore, the system implements a three-way communication overlap strategy during the backward pass. Intra-SuperPoD AllGather and ReduceScatter operations are asynchronously scheduled and overlapped with backward computation, while inter-SuperPoD gradient reduction is deferred and fused. The execution timelines demonstrate how this optimized schedule hides communication latency behind layer computations.
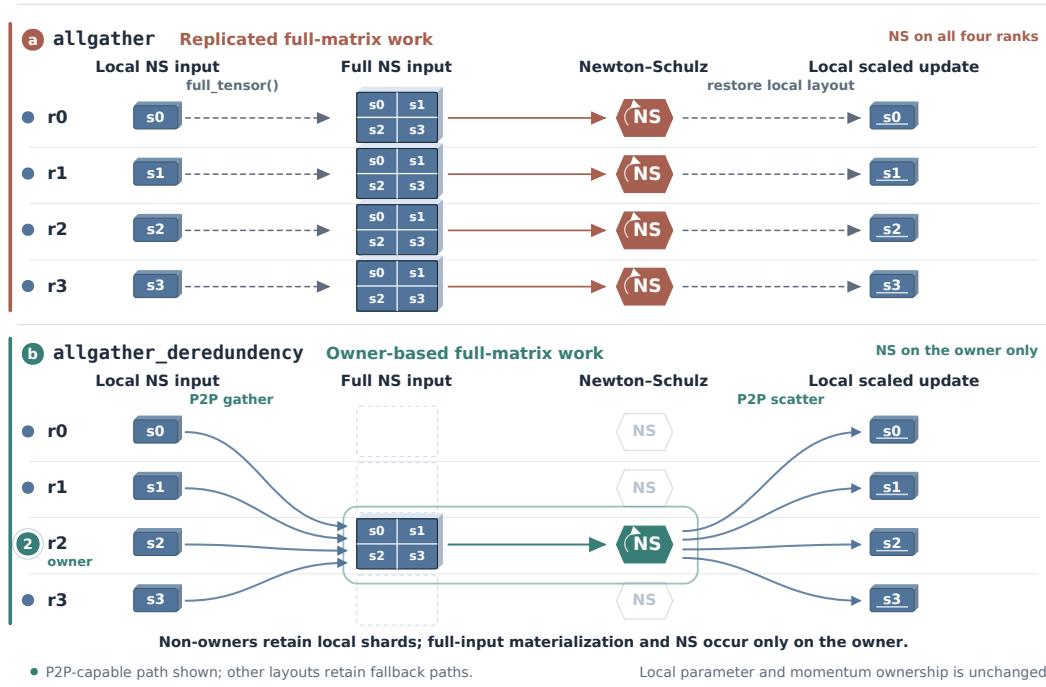
For the distributed Muon optimizer, which requires full weight matrices for Newton-Schulz iteration, the authors introduce an owner-based execution strategy to remove redundant full-matrix computations across ranks. In the baseline approach, every rank reconstructs the full matrix and runs the iteration independently. The optimized approach assigns a single owner rank within each shard group to perform the full-matrix computation. Non-owner ranks send their input shards to the owner via point-to-point transfers. The owner assembles the input, runs the Newton-Schulz iteration, and scatters the scaled update shards back. The reassignment of full-matrix work is depicted in the figure below.
Experiment
The experiments cover speculative decoding, distributed training, gradient scheduling, and host-resource management. DSpark is benchmarked against the base configuration and MTP3 on mathematical reasoning and code generation tasks, demonstrating improved decoding throughput through parallel block-wise drafting and lightweight Markov corrections. HyperParallel-FSDP is evaluated on a 285B-parameter MoE model on a 1,024-NPU cluster and compared with pipeline-parallel schedules, showing that hybrid sharding eliminates the pipeline bubble and improves step time. The layer-wise indexer backward optimization is tested against an HSDP plus Muon baseline and provides the largest single-feature gain by avoiding late auxiliary-graph backpropagation, while CPU pinning and core isolation are evaluated on 512- and 8,192-accelerator clusters and show that reducing host scheduling contention increases training throughput, with greater benefits at larger scale.
Enabling CPU pinning and core isolation together increases training throughput relative to the baseline at both tested cluster sizes. The improvement is larger on the 8,192-accelerator cluster than on the 512-accelerator cluster. The results link the larger gain to reduced scheduling delays and shorter critical-path synchronization waits. Combined CPU pinning and core isolation improved throughput at both cluster scales. The larger cluster showed a greater relative gain, attributed to reduced scheduling delays and shorter synchronization waits.
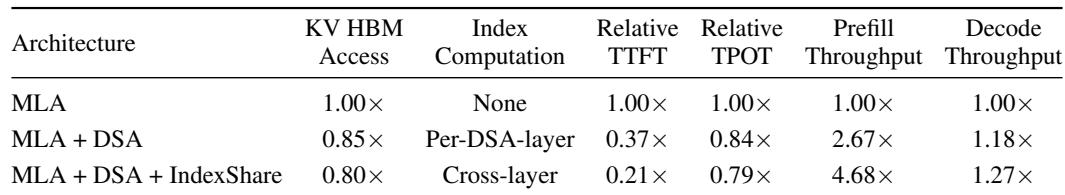
In the 285B simulation, adding DSA to MLA improves latency and throughput relative to the MLA baseline while reducing KV HBM access. Combining DSA with cross-layer index sharing yields the largest gains, with the lowest time-to-first-token and the highest prefill and decode throughput among the variants. All metrics are normalized to the MLA baseline. MLA + DSA reduces time-to-first-token to about a third of the MLA baseline and more than doubles prefill throughput. With cross-layer index sharing, the variant achieves the lowest KV HBM access and time-to-first-token while delivering the highest prefill and decode throughput.
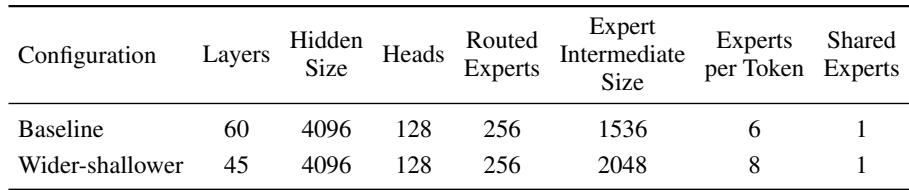
The depth-width study compares a baseline configuration with a wider-shallower variant. The wider-shallower model reduces the number of layers but increases expert intermediate size and the number of experts used per token. Hidden size, attention heads, routed expert count, and shared expert count remain unchanged between the two configurations. The wider-shallower configuration lowers depth while increasing expert capacity per token and expert intermediate size. Hidden size, attention heads, routed expert count, and shared expert count stay fixed across both configurations.
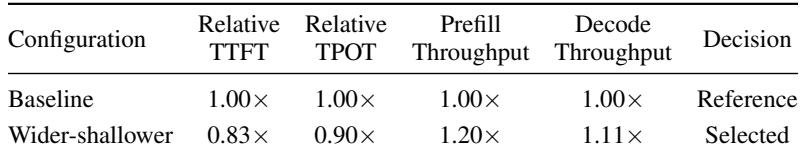
In the 285B depth-width comparison, the selected wider-shallower configuration improves normalized inference efficiency relative to the baseline. It lowers latency while increasing throughput, which supports its selection over the reference design. The wider-shallower configuration reduces relative time-to-first-token and per-output-token latency compared with the baseline. It achieves higher prefill throughput and decode throughput than the reference configuration.
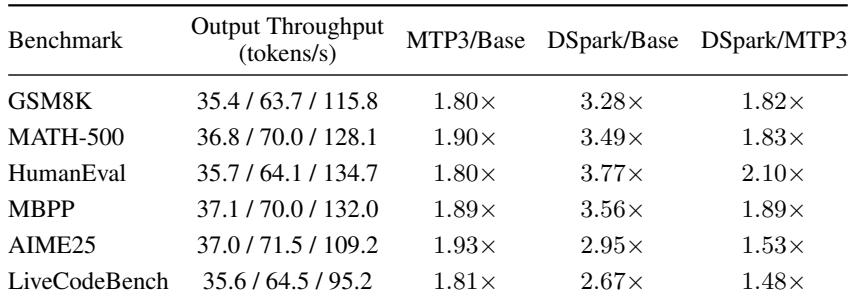
Across six mathematical-reasoning and code-generation benchmarks, DSpark consistently achieves higher decoding throughput than both the base configuration and MTP3 for the 285B model. MTP3 improves output throughput by roughly 1.8x to 1.9x over the base, while DSpark reaches about 2.7x to 3.8x over the base and about 1.5x to 2.1x over MTP3. The largest DSpark advantage appears on HumanEval, and the smallest appears on LiveCodeBench. DSpark delivers the highest output throughput on every benchmark, with speedups over the base configuration ranging from roughly 2.7x to 3.8x. Relative to MTP3, DSpark adds the largest throughput gain on HumanEval and the smallest gain on LiveCodeBench.
Across the experiments, the work validates system and model optimizations: CPU pinning combined with core isolation improves training throughput at both cluster scales, with larger gains attributed to reduced scheduling and synchronization delays, while adding DSA to MLA and combining it with cross-layer index sharing lowers KV HBM access and improves prefill and decode throughput. A wider-shallower 285B configuration also lowers latency and increases throughput relative to the deeper baseline, supporting the selected depth-width design. On mathematical reasoning and code generation benchmarks, DSpark consistently achieves the highest decoding throughput, outperforming both the base configuration and MTP3.