Command Palette
Search for a command to run...
VibePrevisBench: تقييم الترميز الوكيل لتوليد المشاهد رباعية الأبعاد في Blender
VibePrevisBench: تقييم الترميز الوكيل لتوليد المشاهد رباعية الأبعاد في Blender
الملخص
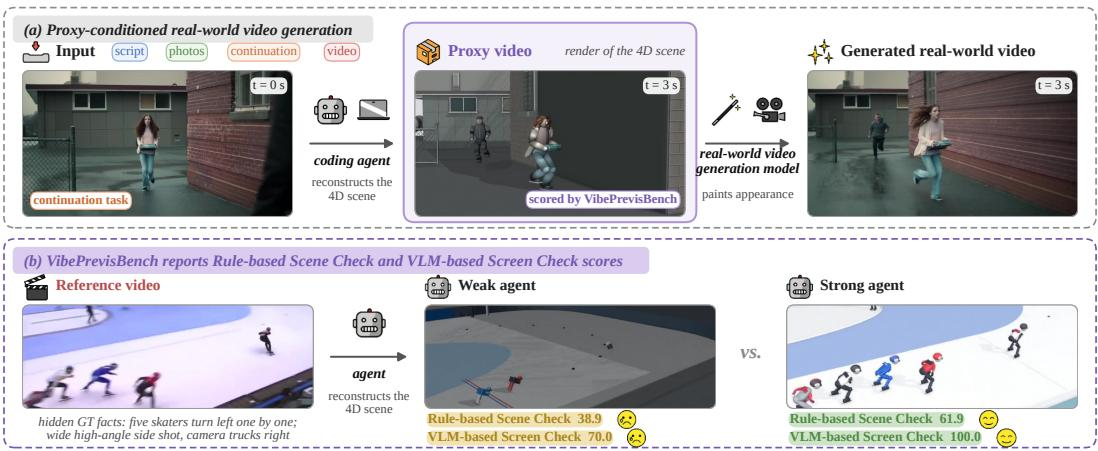
يمكن لنماذج توليد الفيديو الواقعي القابلة للتحكم أن تُشترط بفيديو وسيط رمادي الصندوق مُعاد عرضه، مما يثبّت التخطيط والحركة والكاميرا. يستطيع وكلاء الترميز بناء مثل هذه الفيديوهات عبر إعادة بناء مشهد رباعي الأبعاد في Blender، غير أنه لا يوجد معيار يفحص كلاً من هذه الفيديوهات والمشاهد الطويلة متعددة اللقطات الكامنة خلفها. نقدم VibePrevisBench، وهو معيار لإعادة بناء المشاهد رباعية الأبعاد: يحوّل الوكيل موجزًا إلى مشهد رباعي الأبعاد قابل للتنفيذ ويعرض فيديوه الوسيط. تغطي مهامه البالغ عددها 242 مهمة أربعة أنواع من المدخلات، تشمل النصوص والصور والاستكمالات والفيديوهات المرجعية. يُقيَّم كل تسليم على بُعدين للتقييم. يعيد فحص المشهد القائم على القواعد تشغيل الكود ويقارن المشهد رباعي الأبعاد المُصدَّر بحقائق مرجعية خفية في تسعة أبعاد. يطلب فحص الشاشة القائم على نماذج اللغة البصرية من حكم بصري لغوي تحديد ما إذا كانت الحقائق الناجحة يمكن التعرف عليها في الفيديو الوسيط. نحلل نتائج التقييم ومسارات 11 وكيل ترميز رائدًا ونحدد ثلاث ملاحظات رئيسية. أولاً، يميز الفهم متعدد الوسائط بين الوكلاء، خاصة في فهم الفضاء وحركة الكاميرا. ثانيًا، يبدو أن جميع الوكلاء يتقنون بالفعل أعمال الكاميرا الأساسية والتوزيع المسرحي، ويفشلون في الطلبات الصعبة. ثالثًا، يفحص الوكلاء عروضهم الخاصة لكنهم يفشلون في تصحيح أخطائهم. يحتاج الوكلاء إذن إلى فهم بصري أفضل للفضاء والكاميرا، وفحوصات صريحة للطلبات الصعبة، وتحقق بندًا ببند من العروض مقابل الموجز.
One-sentence Summary
Researchers from Tianjin University, Kling AI, Beijing University of Posts and Telecommunications, et al. introduce VibePrevisBench, a 242-task benchmark that evaluates coding agents converting briefs into executable Blender 4D scenes and rendered proxy videos, scores them via rule-based Scene Check and VLM-based Screen Check, and finds that frontier agents need better spatial and camera understanding and error correction.
Key Contributions
- VibePrevisBench provides 242 tasks across scripts, photos, continuations, and reference videos, requiring coding agents to reconstruct an executable 4D scene and render its proxy video.
- Rule-based Scene Check re-runs the code and compares the exported 4D scene with hidden ground-truth facts in nine dimensions, while VLM-based Screen Check asks a VLM judge whether facts that pass can be recognized in the proxy video.
- Analysis of 11 frontier coding agents shows that multimodal understanding of space and camera motion separates agents, challenging staging and filming requests remain difficult, and agents inspect their own renders but fail to correct their errors.
Introduction
Controllable real-world video generation increasingly depends on proxy video rendered from a 4D scene, which fixes layout, people, actions, cameras, and cuts. Coding agents can build these scenes by writing Blender code, but errors in the proxy propagate into the final real-world video. Existing benchmarks only partially evaluate this task: they use narrow inputs, focus on static content, or rely on screen-only evaluation, without checking the underlying 4D scene against ground truth for long multi-shot scenes with people. The authors introduce VibePrevisBench, a benchmark where agents turn scripts, photos, continuations, or reference videos into executable 4D scenes and proxy videos, evaluated through rule-based scene checks and VLM-based screen checks.
Dataset
VibePrevisBench dataset
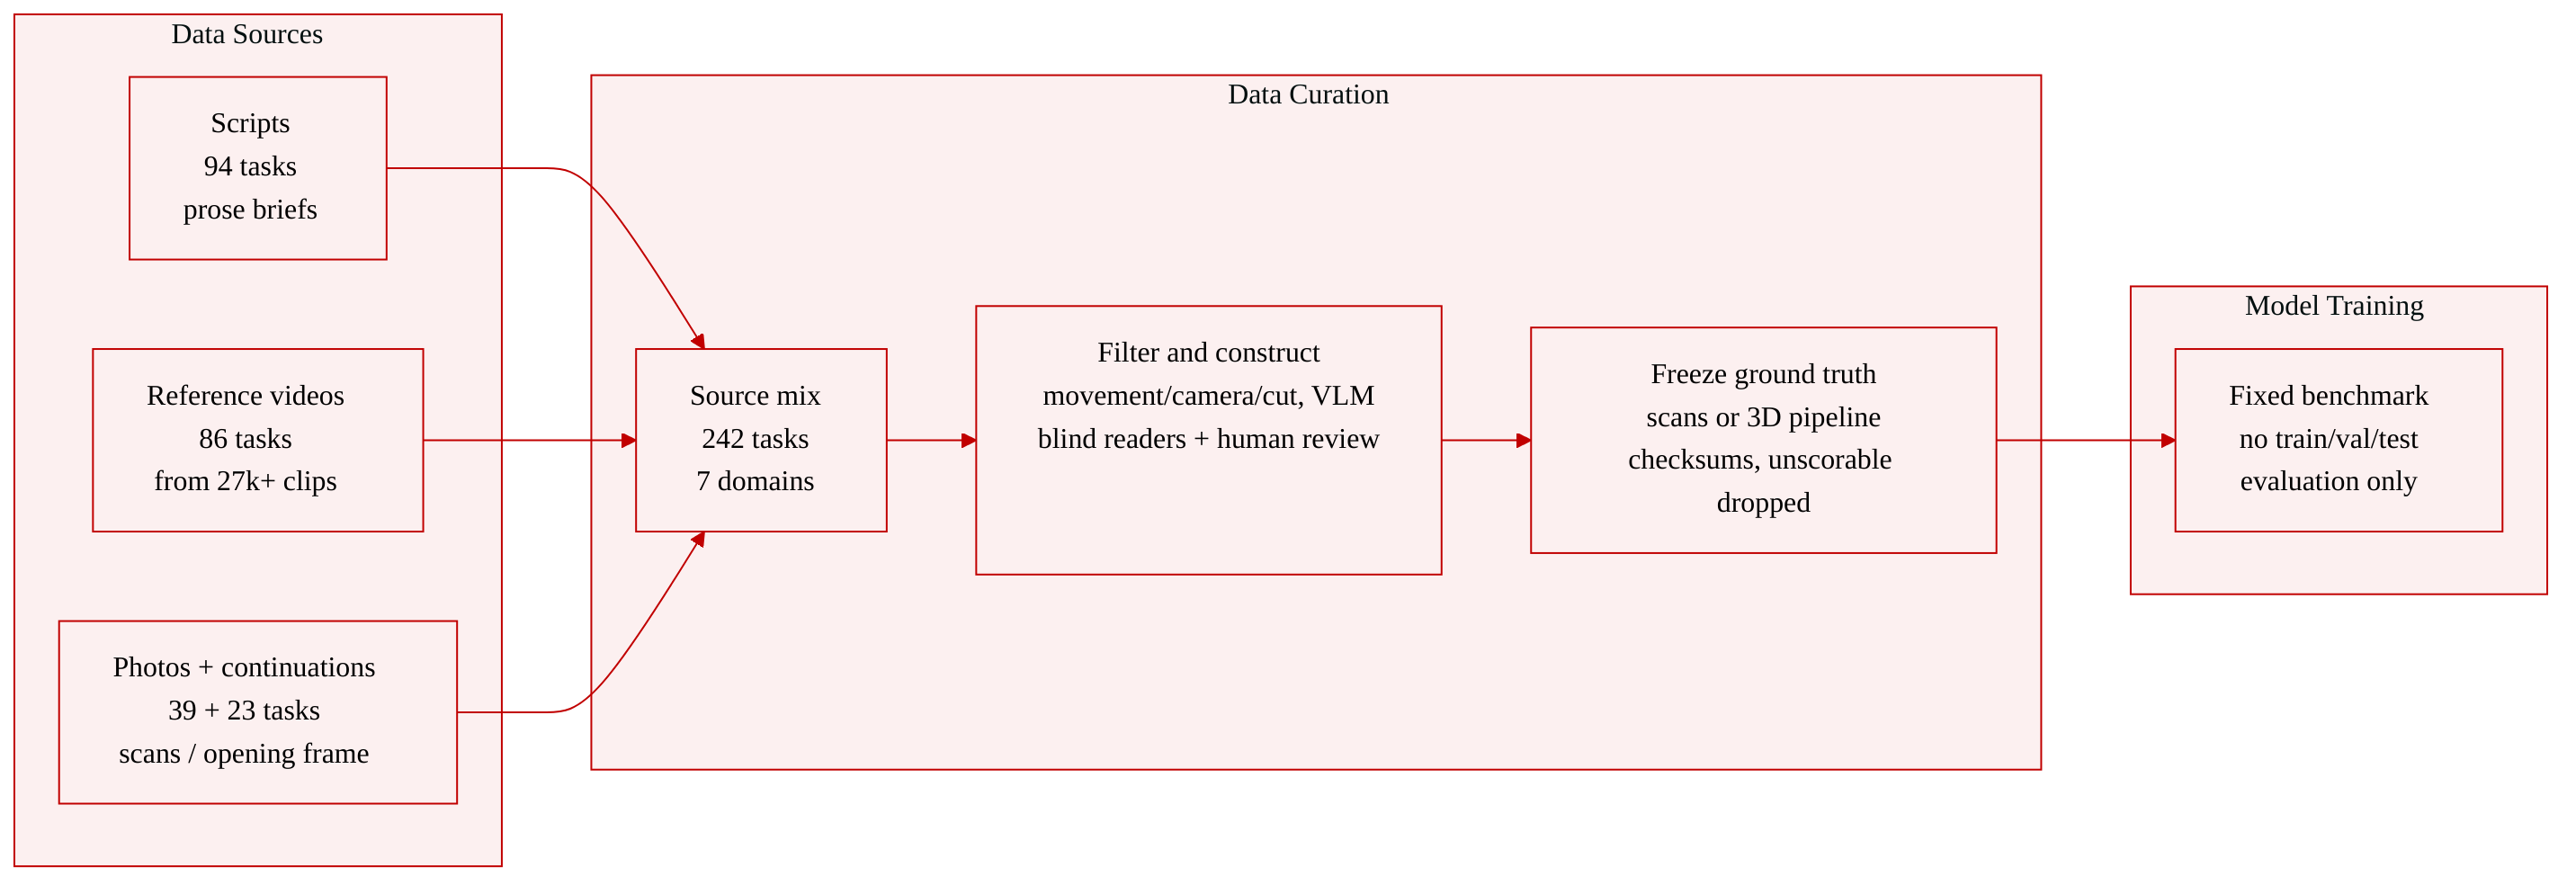
The authors introduce VibePrevisBench as a 242-task benchmark for 4D scene reconstruction. Each task is a tuple (b,m,E,o): an English brief b, optional media m, a list E of places and subjects with ids, and output requirements o specifying the frame count, frame rate, and resolution of the proxy video. The benchmark covers seven scene domains and four input kinds.
Subsets and sources
- Scripts: 94 tasks. The scene is specified in prose alone, without distances or angles. Script briefs are relatively long, around 800 words.
- Reference videos: 86 tasks. Clips come from more than 27,000 source videos. The authors keep clips with several moving people, camera motion, or cuts, leaving 1,800 clips. Of these, 388 pass VLM checks for live action, visible events, and distinct subjects, and human reviewers choose the final video tasks.
- Photo tasks: 39 tasks. A total of 38 tasks draw on scan datasets with measured 3D boxes and camera poses. One photo task is estimated by the reconstruction pipeline.
- Continuations: 23 tasks. Each task shows the opening frame of a clip and describes the next seconds.
Schema and hidden ground truth
Every task pairs a brief with hidden ground-truth facts that can be checked individually. A fact is one checkable statement about the scene, such as where subjects stand, how places connect, who moves where and when, or how cameras frame, move, and cut. The facts belong to nine dimensions: entities, layout, spaces, picture structure, routes, events, camera, cuts, and physical validity. Picture structure is checked only for photo, continuation, and video tasks, because it compares depth, normals, and segmentation with reference frames. Appearance is never checked.
Construction and processing
- Collection and curation: Two frozen taxonomies set quotas for what a scene holds and how a task is asked. Video and continuation clips are selected from a large source pool through movement, camera, and cut filters, followed by VLM checks and human review.
- Task construction: For script tasks, a model builds a scene from a card and writes the script. Two blind readers from the Claude and DeepSeek families reconstruct the events from the script alone; claims neither recovers are reworded or dropped. Media briefs assign each place and subject an id and description. Human reviewers check and correct every brief and its hidden facts.
- Ground truth and checks: Scripts take hidden facts from the built scene, and photo tasks from scans. For videos, most continuations, and one photo task, a pipeline estimates ground truth by recovering shots, subjects, cameras, depth, and bodies and lifting them to 3D. Facts the pipeline cannot verify are marked unscorable and never count. Candidate tasks that did not separate 11 agents were dropped based on item-rest correlation and spread, not on any single agent score. Tasks, media, hidden facts, and scorer are frozen with checksums.
Scale and statistics
The 242 tasks are distributed as 94 scripts, 86 reference videos, 39 photo tasks, and 23 continuations. Each of the seven domains holds 19 to 46 tasks, and each of the 33 places appears in 3 to 13 tasks. Briefs range from 153 to 1,200 words, with a median of 368 words. A task carries 20 to 2,175 checks, with a median of 408 and 99,000 checks in total. Most tasks are demanding: 88% have two or more shots, 80% have a moving camera, 79% have two or more people, 69% have hand-object interaction, and 61% involve two or more places.
How the benchmark is used
VibePrevisBench is used for evaluation rather than model training. An agent returns a Blender program p. The benchmark runs p in a fresh sandbox, exports the 4D scene S frame by frame, and renders the proxy video V. The hidden ground-truth facts form a rubric used to score the scene.
- Rule-based Scene Check: It binds subjects and places by tagged ids and matches untagged objects by class. Script facts are relational, while media facts are metric and are compared after similarity alignment. Scores are corrected for chance and missing entities, then averaged over the dimensions a task exercises.
- VLM-based Screen Check: A VLM judge, Gemini, watches the proxy video at 2 fps blind to the agent and object names, retells the clip, then receives the brief and checklists from the hidden facts. It rates items as no, partial, or yes across recognition, action, visibility, and story. Photo tasks use recognition only.
- Overall score: The final score is (Scene+Screen)/2.
No train/validation/test split is described, since the dataset is a fixed benchmark whose scoring is reproducible from the released checksums.
Method
The authors formulate a task τ=(b,m,E,o) comprising an English brief b, optional media m, a list of places and subjects E, and output requirements o. The agent responds with a Blender program p. To evaluate this, the program is executed to generate a 4D scene S=({xe(t)}e∈E,c(t),K) and a proxy video V.
Refer to the framework diagram for the evaluation pipeline.
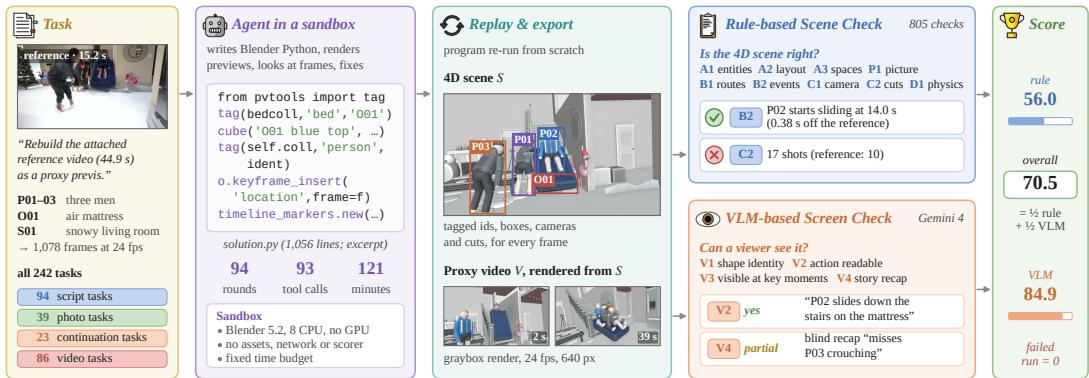
The pipeline ensures that the delivered program runs independently in a fresh sandbox, exporting the scene frame by frame and rendering the proxy video. This prevents agents from submitting pre-rendered videos that do not match the underlying code. The evaluation consists of two main checks. The Rule-based Scene Check verifies if the 4D scene is structurally correct. It binds subjects and places by tagged IDs and matches untagged objects by class. The score is calculated in three steps: computing a raw score Pb for a block of facts, correcting for chance and missing entities using Qb=clip((Pb−Rb)/(1−Rb))κb, where Rb is the chance rate and κb is the share of existing entities, and combining blocks into dimension scores. The VLM-based Screen Check, utilizing a VLM judge, assesses whether the correct scene elements are visible. The judge watches the proxy video and rates items across dimensions like recognition, action, visibility, and story. The final score is the average of the Scene and Screen scores.
The authors construct the benchmark in three stages to ensure high quality and reproducibility.
As shown in the figure below:
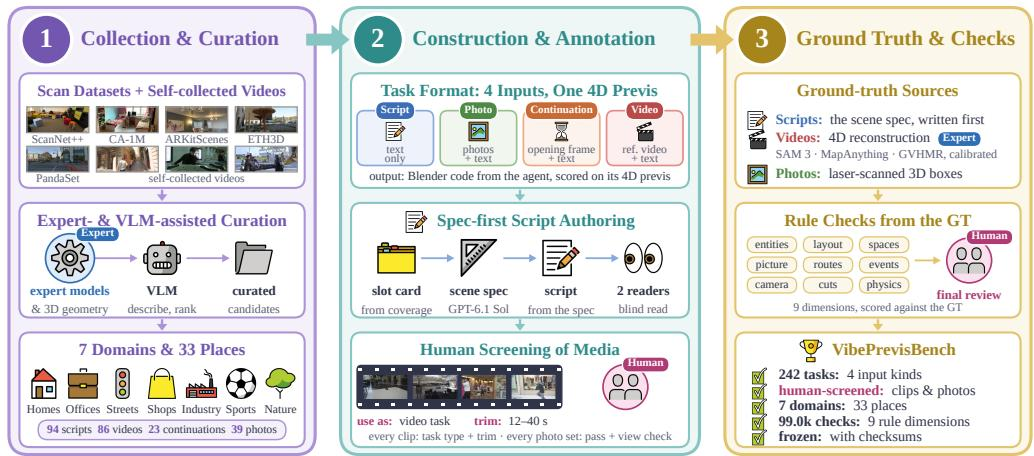
Stage 1 involves collection and curation from scan datasets and self-collected videos, filtered by expert models and VLMs into specific domains and places. Stage 2 focuses on task construction, where scripts are written spec-first and validated by blind readers from different model families, while media briefs are screened by humans. Stage 3 establishes ground truth and checks. For scripts, facts come from the built scene; for videos, a pipeline recovers shots, subjects, and cameras to lift them to 3D. Tasks that fail to separate agent performance based on item-rest correlation and spread are dropped, ensuring a robust benchmark frozen with checksums.
Experiment
The study evaluates 11 frontier coding agents in a Blender sandbox with a four-hour budget, scoring their ability to generate, render, and revise scenes across different input kinds. GPT-6 Astra leads overall at 77.7, but no agent approaches solving the benchmark, and cost does not track score, with cheaper models reaching near-leader performance. Multimodal understanding of space and camera motion separates agents more than coding ability, while all models handle common staging requests but turn challenging requests into typical choices. Agents frequently inspect their own renders yet cannot reliably detect errors, indicating that explicit item-by-item verification against the brief is needed rather than more image viewing.
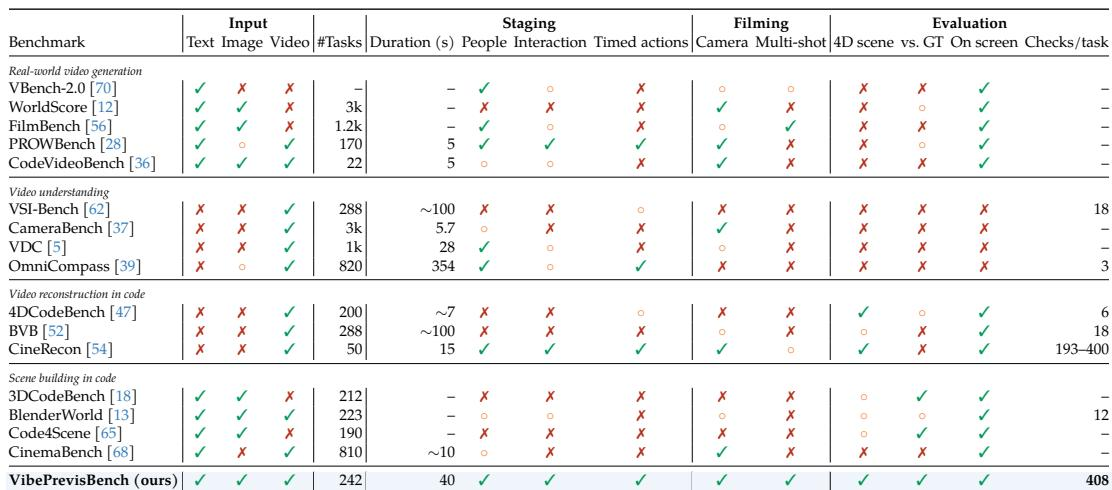
The comparison shows that existing benchmarks are partial across input, staging, filming, and evaluation dimensions. Many support rendered-frame scoring but do not require staged people, timed actions, multi-shot filming, or checks of the reconstructed 4D scene against ground truth. Only VibePrevisBench satisfies all listed criteria. Several related benchmarks score rendered frames on screen, but most do not verify the underlying 4D scene against ground truth. Only VibePrevisBench has full coverage across the listed dimensions, while related benchmarks cover staging and filming only partially.
On the 242-task benchmark, GPT-6 Astra leads overall, narrowly ahead of GPT-6.1 Sol, Gemini 4 Argon, and Opus 5.5. These top four models cluster closely and outperform the next agents by at least 3.9 overall points, but no agent approaches a solved benchmark. Vision-heavy inputs widen model differences, while cost and rank are not tightly connected. GPT-6 Astra attains the highest overall score, followed by GPT-6.1 Sol, Gemini 4 Argon, and Opus 5.5. The top four agents lead the next best group by at least 3.9 overall points. GPT-6 Astra leads rule-based scene check on script, continuation, and video inputs, while Opus 5.5 leads on photo inputs. The best-to-worst rule-based scene check gap increases from 12.0 points on text-only scripts to 19.9 points on photos, with space and camera errors accounting for much of the photo gap. No agent solves the benchmark: only 35 of 242 tasks have any agent achieving a rule-based scene check score of 90. Cost and score diverge; some much cheaper agents reach close to the leader's overall score, and a high-cost model can rank below lower-cost competitors. Agents inspect many rendered frames but do not reliably correct errors, and more inspection is not associated with substantially better scores.
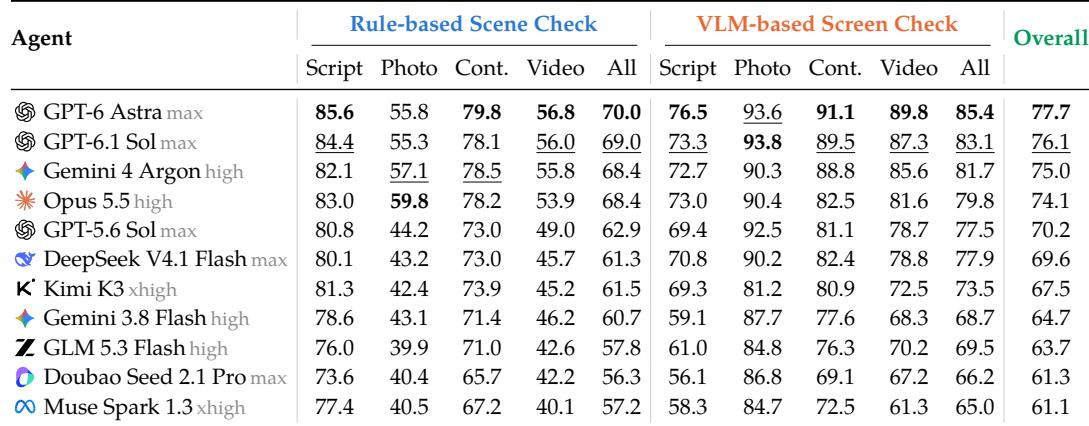
The evaluation comparison indicates that existing benchmarks are partial across input, staging, filming, and evaluation dimensions, while only VibePrevisBench covers all criteria and verifies the reconstructed 4D scene against ground truth. On the 242-task benchmark, GPT-6 Astra leads narrowly over GPT-6.1 Sol, Gemini 4 Argon, and Opus 5.5, but no agent approaches a solved benchmark, and vision-heavy inputs widen model differences. Cost and rank are not tightly connected, and agents inspect many rendered frames without reliably correcting errors.