Command Palette
Search for a command to run...
توليد الفيديو المتدفق بخطوات قليلة عبر إزاحة الشرط
توليد الفيديو المتدفق بخطوات قليلة عبر إزاحة الشرط
الملخص
يقلل أخذ العينات بخطوات قليلة من تكلفة توليد الفيديو المتدفق. تشرف تقنية تقطير مطابقة التوزيع (DMD) على المولدات قليلة الخطوات باستخدام شبكة درجات زائفة (fake-score) منفصلة، مما يضيف ذاكرةً وحسابًا تدريبيين ويستلزم تتبع المولد المتطور. نوسع APEX إلى الفيديو المتدفق باستخدام إزاحة الشرط لتقدير حقل سرعة التوزيع المولد داخل المولد نفسه. يحدد شرط النص الأصلي التوليد، بينما يحدد شرط مُزاح تقدير العينات الزائفة باستخدام المعلمات نفسها. يزيل هذا الشبكة الزائفة المستقلة مع الإبقاء على المعلم المرجعي المجمد الخاص بـ S2-Avatar وتقنية Self-Replay Forcing والتنظيم الإدراكي. نقيّم APEX على مقاطع فيديو مدتها 180 ثانية باستخدام ثلاثة تقييمات للعمود الفقري لكل كتلة ومُحسِّن مكاني أحادي الخطوة (Refiner)، مع دراسة بشرية من 70 حالة ومقارنة على StreamAV-Bench من 320 حالة. بالمقارنة مع S2-Avatar، يحقق APEX استيفاءً أعلى لتعليمات الفيديو على المسار التقدمي (Progressive) (3.856 مقابل 3.831) وجماليات بصرية أعلى عبر المسارين (0.641898 مقابل 0.632606). يفضل المقيّمون البشريون APEX بقوة أكبر في اتباع التعليمات، بتفضيل صافٍ قدره +30.0%، يليه الاتساق وجودة الفيديو بنسبة +4.3% لكل منهما. تميل جودة الحركة لصالح S2-Avatar، ويكون التزامن السمعي البصري متعادلًا في الغالب، وتبقى قابلية الاستخدام دون تغيير. تُظهر قياسات منفصلة تحت إعدادات تدريب متطابقة انخفاضًا بنسبة 4.4% في ذروة ذاكرة GPU المخصصة لكل وحدة معالجة رسوميات، وقصرًا بنسبة 9.2% في متوسط زمن التكرار مقارنةً بـ DMD.
One-sentence Summary
Researchers from Tsinghua University, Shengshu Technology, and Westlake University extend APEX to few-step streaming video generation by using condition shifting to estimate the generated distribution's velocity field within the generator and thereby eliminate DMD's separate fake-score network while retaining S2-Avatar's frozen reference teacher, Self-Replay Forcing, and perceptual regularization; evaluated on 180-second videos with three backbone evaluations per block, a one-step spatial Refiner, a 70-case human study, and a 320-case StreamAV-Bench comparison, APEX achieves higher video instruction fulfillment on the Progressive track (3.856 versus 3.831) and higher visual aesthetics across both tracks (0.641898 versus 0.632606), with human raters favoring APEX most on instruction following (+30.0% net preference), followed by consistency and video quality (+4.3% each), whereas motion quality favors S2-Avatar, audiovisual synchronization is predominantly tied, and usability is unchanged; under matched training settings, APEX also shows 4.4% lower peak allocated GPU memory per GPU and 9.2% shorter mean iteration time than DMD.
Key Contributions
- APEX integrates condition-shifted fake estimation into S2-Avatar's streaming video framework, estimating the generated distribution's velocity field within the same generator and eliminating the separate fake-score network.
- The method retains S2-Avatar's frozen reference teacher, Self-Replay Forcing, and perceptual regularization while sharing generator and fake estimator parameters, enabling few-step sampling for 180-second videos without the DMD fake network overhead.
- In a 320-case StreamAV-Bench comparison and a 70-case human study, APEX achieves higher progressive-track instruction fulfillment (3.856 versus 3.831) and higher visual aesthetics across both tracks (0.641898 versus 0.632606) than S2-Avatar, with human raters favoring APEX most strongly on instruction following at +30.0% net preference; matched training also shows 4.4% lower peak allocated GPU memory per GPU and 9.2% shorter mean iteration time than DMD.
Introduction
Streaming video generation with diffusion or flow models requires repeated network evaluations for each new block, so few-step sampling is especially valuable for long sequences. Distribution Matching Distillation can reduce this cost, but it typically uses an auxiliary fake-score network that adds training memory and computation and must remain synchronized with the changing generator. The authors introduce APEX, which integrates condition-shifted fake estimation into S2-Avatar’s Self-Replay Forcing framework. This shares parameters between the generator and fake estimator, removes the independent fake network, and retains a frozen pretrained teacher. APEX improves instruction following and visual aesthetics while reducing peak GPU memory and average iteration time.
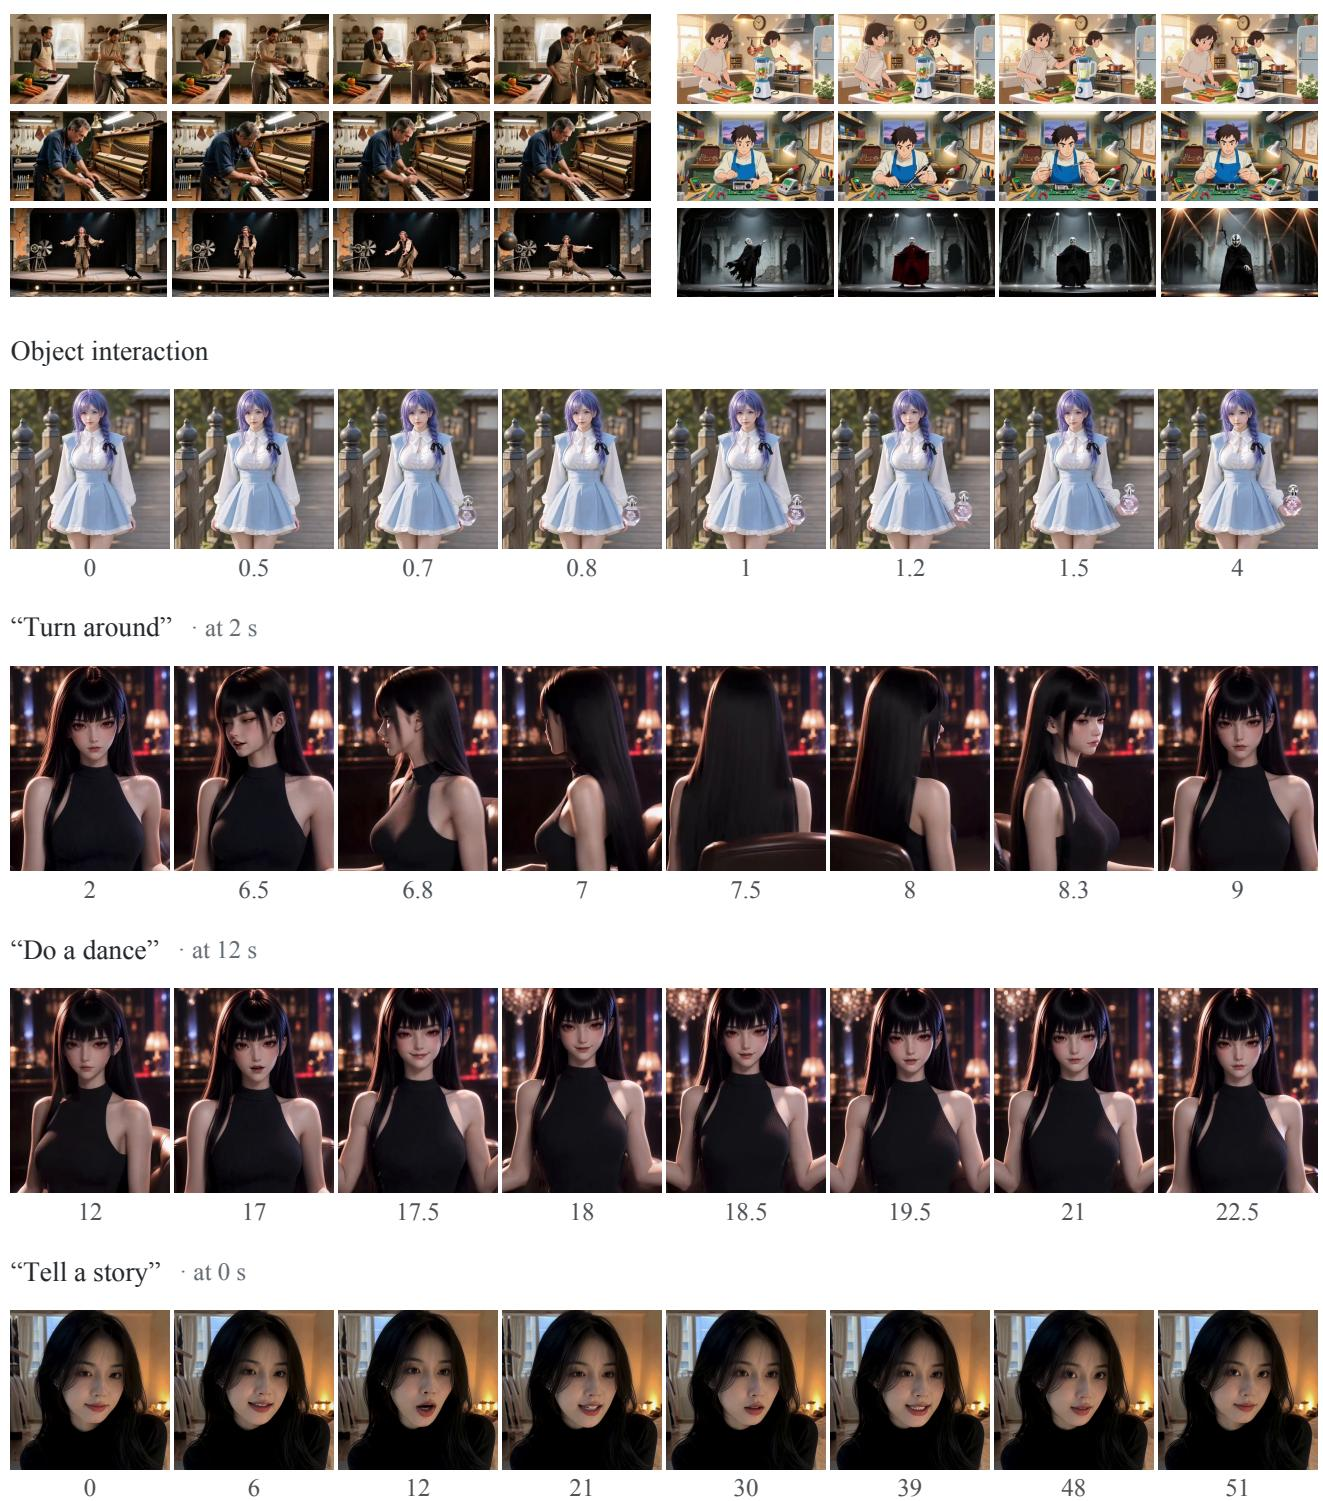
Method
The authors leverage APEX's condition shifting mechanism within the Self-Replay Forcing framework to optimize streaming video generation. In this architecture, the generator and the fake estimator share the same parameters θ, while a frozen teacher model Fϕ provides the reference prediction and guidance. This shared-parameter design contrasts with traditional distribution matching distillation approaches that utilize independent parameters for the fake estimator.
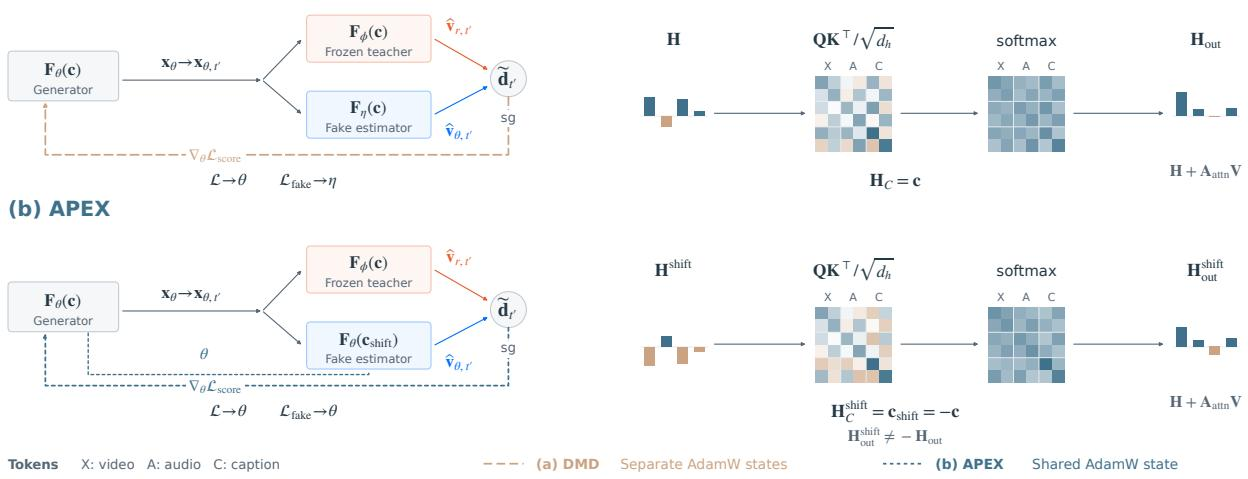
As shown in the figure below, the training process involves generating video sequences under a specific condition ci and subsequently estimating the fake velocity from these outputs using a shifted condition cshifti=−ci. The projected text is negated before the transformer blocks, while positive diffusion times are maintained in both forward passes. The evaluated blocks include replay outputs and any detached prefix. These blocks are detached and re-noised at a scoring time t′∈(0,1) using fresh Gaussian noise ϵ′∼pz:
xθ1:N,sg:=sg(xθ1:N),xθ,t′1:N,sg:=(1−t′)xθ1:N,sg+t′ϵ′.A single scoring time t′ is drawn for all generated blocks in a sequence, distinct from the replay times used for clean predictions. The shifted-condition network then predicts the fake velocity from the re-noised video latents:
vθ,t′1:N:=Fθ(xθ,t′1:N,sg,t′,cshift1:N).To learn the velocity field of the generated samples, the authors employ a flow-matching loss with causal attention over the current and preceding noisy blocks:
Lfake(θ)=E[MSE(vθ,t′1:N,ϵ′−xθ1:N,sg)].Detaching the generated sequence and the regression target ensures that this update strictly refines the shifted-condition prediction.
To form the generator correction, the framework computes the difference between the frozen teacher's clean-latent prediction x0,r1:N and the fake clean-latent prediction at the same noisy video and scoring time. The clean-latent difference is proportional to the velocity difference:
x0,ri−x0,θi=t′dt′i,dt′i:=vθ,t′i−vr,t′i.This difference is normalized to obtain dt′1:N and added to the current output, providing the generator with a detached regression target for the replay predictions:
Lscore(θ)=E[MSE(xθ1:N,sg(xθ1:N+dt′1:N))].The target remains fixed during this step, meaning gradients only pass through the replay outputs and their connected causal representations within the active segment.
Finally, the generator objective combines this distribution matching loss with perceptual regularization:
L(θ)=Lscore(θ)+Lperc(θ).Generator updates alternate with the fake estimation loss on the shared parameters θ. By default, these updates share AdamW states, ensuring efficient optimization while retaining the perceptual regularization and keeping the teacher parameters ϕ frozen. At inference, the original projected text selects the generation using a chosen few-step schedule, followed by a standard one-step spatial Refiner.
Experiment
The evaluation assesses 180-second streaming generation on StreamAV-Bench across ten metrics and five human-preference dimensions, with additional training-cost and sampling comparisons against S2-Avatar. APEX shows clear gains in instruction following and aesthetic quality, ranking highly among twelve models, while visual quality, audiovisual alignment, and motion quality involve trade-offs or favor the baseline. Human evaluators strongly prefer APEX for instruction following, find synchronization and usability largely comparable, and observe weaker motion quality. Training is more efficient in memory and iteration time, and default replay-time sampling with shared optimizer states helps preserve strong instruction preference at reduced sampling budgets.
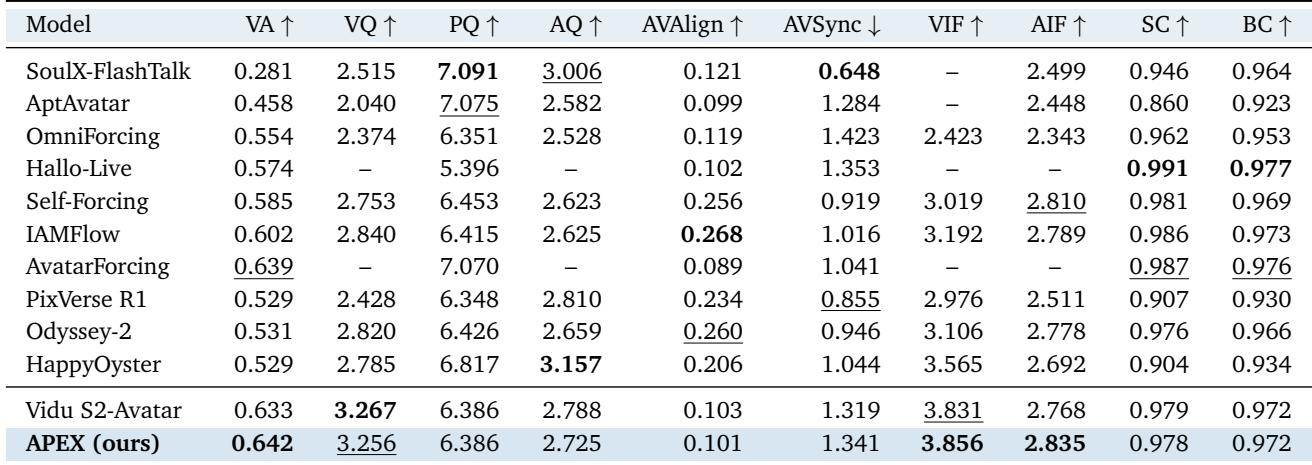
Across the reported StreamAV-Bench metrics, APEX ranks first on VA, VIF, and AIF and second on VQ among the models with available results. Among other listed baselines, IAMFlow and Self-Forcing are competitive on VIF, AIF, and AVAlign, while AvatarForcing and Hallo-Live lead or tie near the top on BC and SC. The cited comparisons also indicate that instruction-following and aesthetic gains are accompanied by lower AQ, AVAlign, and SC and slightly higher AVSync error. APEX ranks first on VA, VIF, and AIF and second on VQ among models with available results. Instruction-following and aesthetic improvements coincide with drops in AQ, AVAlign, and SC and a small rise in AVSync error.
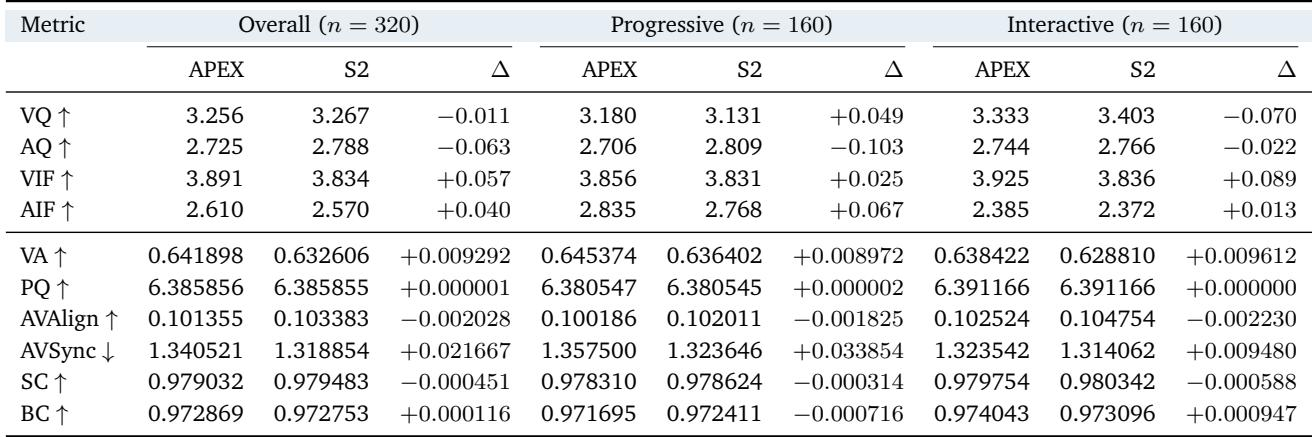
APEX improves instruction-following and aesthetic alignment on both Progressive and Interactive tracks, with positive deltas for VIF, AIF, and VA. Visual quality improves only on Progressive, while audiovisual alignment and synchronization show small trade-offs, including a slightly higher pooled AVSync error and essentially unchanged PQ. VIF, AIF, and VA improve for APEX on both tracks, with pooled VIF up 0.057 and pooled AIF up 0.040. Visual quality rises on Progressive (+0.049) but falls on Interactive (-0.070), leaving pooled VQ slightly lower (-0.011). Aesthetic quality and audiovisual alignment decline on both tracks, and pooled AVSync error increases from 1.319 to 1.341 seconds. Pooled PQ is effectively unchanged, indicating that the model's instruction and aesthetic gains come with visual and audiovisual trade-offs.
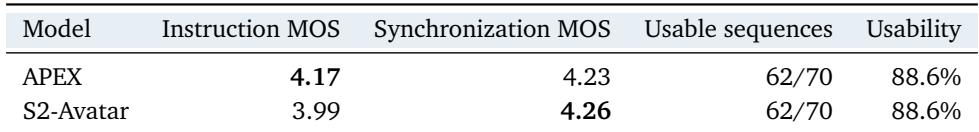
APEX shows a clear advantage in instruction following over S2-Avatar, with higher instruction MOS and a strong paired preference margin. Audiovisual synchronization is nearly indistinguishable between the models, while motion quality favors S2-Avatar. Both models meet the usability criterion in the same majority of evaluated sequences. Instruction following is APEX's clearest edge: its MOS is higher and paired preferences show a substantial net win. Synchronization ratings are almost tied, and all but one paired synchronization judgment is a tie. Both models reach the usability threshold in 62 of 70 sequences, an identical 88.6% usability rate.
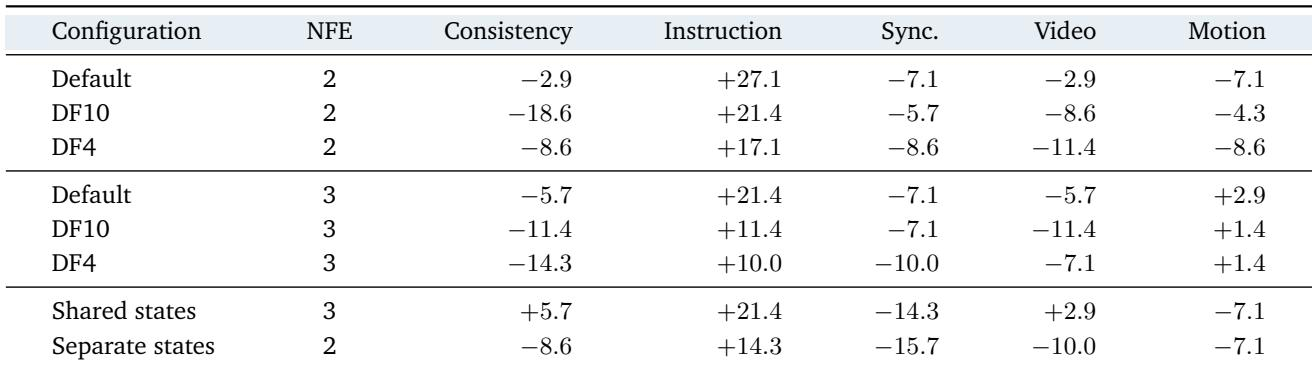
Instruction following is the strongest positive preference relative to S2-Avatar across the evaluated sampling and optimizer settings, while consistency, synchronization, video quality, and motion quality are mostly neutral or negative. Default equal-weight timestep sampling gives the best instruction preference at both 2 and 3 NFE, and shared optimizer states at 3 NFE are the only listed configuration that also improves consistency and video quality. Biasing replay sampling toward lower noise does not provide a consistent advantage. Default sampling achieves the highest instruction preference at both inference budgets, with a larger advantage at 2 NFE than at 3 NFE. Shared optimizer states at 3 NFE are the only listed setting with positive consistency and video quality, although synchronization and motion quality remain negative. DF4 and DF10 timestep variants reduce instruction preference relative to default sampling and do not consistently improve other quality dimensions.
Experiments assess APEX on StreamAV-Bench and through comparisons with S2-Avatar, covering instruction following, visual and audiovisual quality, synchronization, and usability, as well as ablations over inference sampling and optimizer settings. APEX consistently improves instruction following and visual-aesthetic alignment, with strong rankings on VIF, AIF, and visual aesthetics, but these gains are accompanied by modest trade-offs in visual quality on the interactive track, aesthetic quality, audiovisual alignment, synchronization, and motion quality. Relative to S2-Avatar, APEX's clearest advantage is instruction following while synchronization is nearly tied and motion quality favors the baseline, yet both models meet usability equally; ablations further show default equal-weight timestep sampling is best for instruction preference and shared optimizer states at 3 NFE are the only listed variant that also improves consistency and video quality.