Command Palette
Search for a command to run...
SteerDistill: تكميم وكلاء النماذج اللغوية الكبيرة عبر توجيه المعلّم بحلقة مغلقة
SteerDistill: تكميم وكلاء النماذج اللغوية الكبيرة عبر توجيه المعلّم بحلقة مغلقة
Genming Cui Xiangyu Li Zixu Hao Xin Ding Yunxin Liu Ting Cao
الملخص
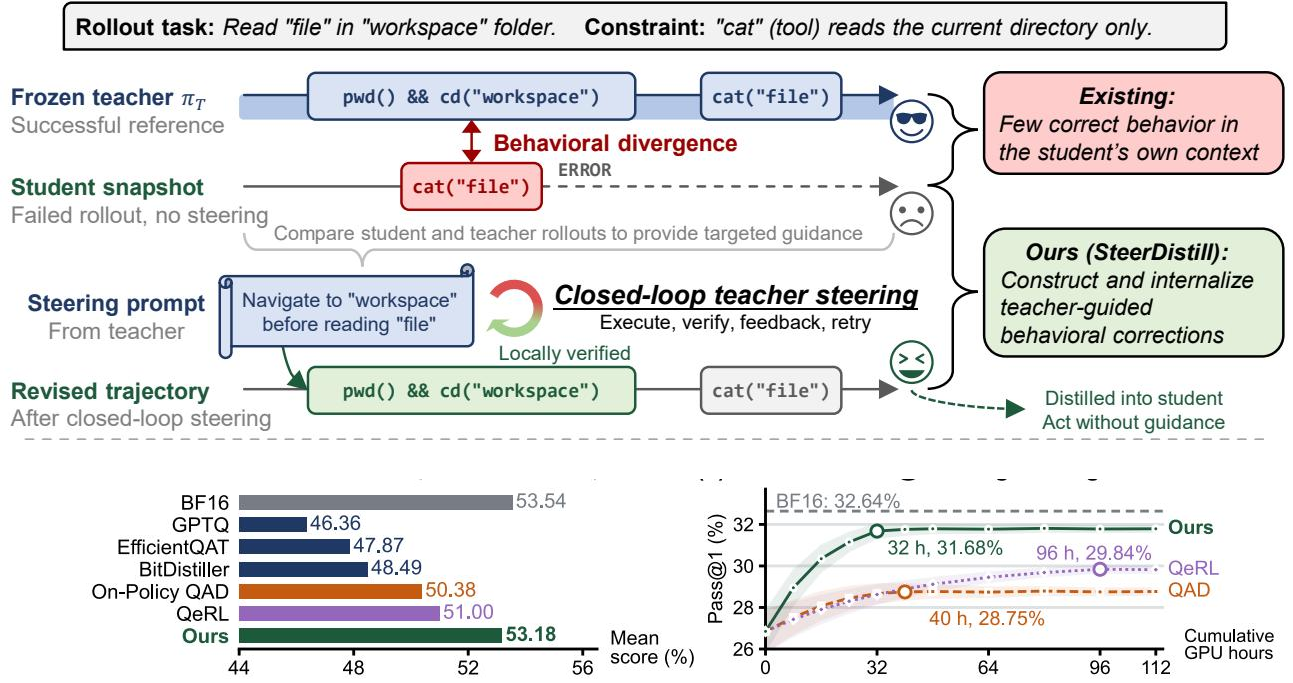
يقلل التكميم منخفض البتات من تكلفة الاستدلال لوكلاء النماذج اللغوية الكبيرة، لكنه قد يضر بنجاح المهام. عند فحص المسارات الفاشلة، نجد أن الوكلاء المكمَّمين يتجاهلون متطلبات المهمة أو شروط البيئة، فينتجون انتقالات بيئية تنحرف عن المراجع الناجحة ذات الدقة الكاملة. ويظل تصحيح هذه الانحرافات السلوكية صعبًا: فقد تفتقد البيانات غير المتصلة سياقات فشل الطالب، بينما قد تقدم مساراته الخاصة استجابات صحيحة قليلة في تلك السياقات. نقدم SteerDistill، وهي طريقة تقطير واعية بالتكميم يوجه فيها معلم بدقة كاملة الطالبَ لمراجعة الاستجابات الفاشلة، ويحسّن توجيهه بشكل متكرر باستخدام التغذية الراجعة من تنفيذ الطالب. وينتج عن هذا التوجيه المغلق للمعلم تصحيحات سلوكية مُتحقق منها محليًا. ونستبطن هذه التصحيحات بتدريب الطالب دون توجيه ليطابق تنبؤات الطالب الموجَّه عند المنعطفات المصححة وتنبؤات المعلم بدقة كاملة عند المنعطفات الأخرى، مما يتيح استدلالًا دون مساعدة. عبر خمسة معايير للوكلاء وثلاثة نماذج، يتفوق SteerDistill على أقوى خط أساس مكمَّم بمقدار 1.67–2.18 نقطة في متوسط الدرجة تحت W4A16، ويبقى ضمن نقطة واحدة من BF16. وفي معيار ??2-Bench، يتفوق على QeRL بمقدار 1.84 نقطة مئوية في معدل النجاح مستخدمًا ساعات تدريب على وحدات معالجة الرسوميات أقل بنسبة 67%، وينتج مسارات ناجحة أقصر من الخطوط الأساسية المكمَّمة.
One-sentence Summary
Researchers from Tsinghua University's Institute for AI Industry Research (AIR) and University of Science and Technology of China propose SteerDistill, a quantization-aware distillation method in which a full-precision teacher steers a quantized LLM agent to revise failed responses through closed-loop feedback, yielding locally verified corrections for unassisted inference and improving average scores by 1.67–2.18 points under W4A16 while staying within one point of BF16.
Key Contributions
- SteerDistill is a quantization-aware distillation method in which a full-precision teacher uses closed-loop execution feedback to guide a quantized student to revise failed responses, producing locally verified behavioral corrections.
- The corrections are internalized by training the student without guidance to match the steered student’s predictions at corrected turns and the full-precision teacher’s predictions at other turns, enabling unassisted inference.
- Across five agentic benchmarks and three models under W4A16, SteerDistill outperforms the strongest quantized baseline by 1.67 to 2.18 average score points, stays within one point of BF16, and on τ²-Bench exceeds QeRL by 1.84 percentage points in success rate using 67% fewer training GPU hours while producing shorter successful trajectories than quantized baselines.
Introduction
Large language model (LLM) agents call tools over multiple turns, making inference cost a central deployment concern and low-bit quantization a practical mitigation. However, quantized agents often underperform their full-precision counterparts because they overlook task requirements or environmental conditions, leading to behavioral divergence from successful references. Prior recovery methods face a coverage/correction gap: offline data and distillation may miss the contexts where a student diverges, while on-policy rollouts can contain too few correct responses in those contexts. The authors introduce SteerDistill, a quantization-aware distillation approach that uses a full-precision teacher to generate and refine targeted behavioral corrections through closed-loop steering, then distills locally verified corrections so the quantized student can act appropriately without teacher guidance at inference.
Method
The authors propose SteerDistill, a framework that constructs and internalizes behavioral corrections in each training cycle. Let πT denote the frozen full-precision teacher and πθ≡πQ(θ) the trainable quantized student, where θ represents the master weights and Q is a fixed quantization operator. During cycle k, a frozen snapshot πθk generates initial rollouts and steered revisions. Distillation then updates the learner πθ on the retained trajectories to obtain θk+1 for the next cycle.
As shown in the figure below, the training pipeline consists of two primary modules: teacher-steered trajectory revision and the internalization of steered behavior.
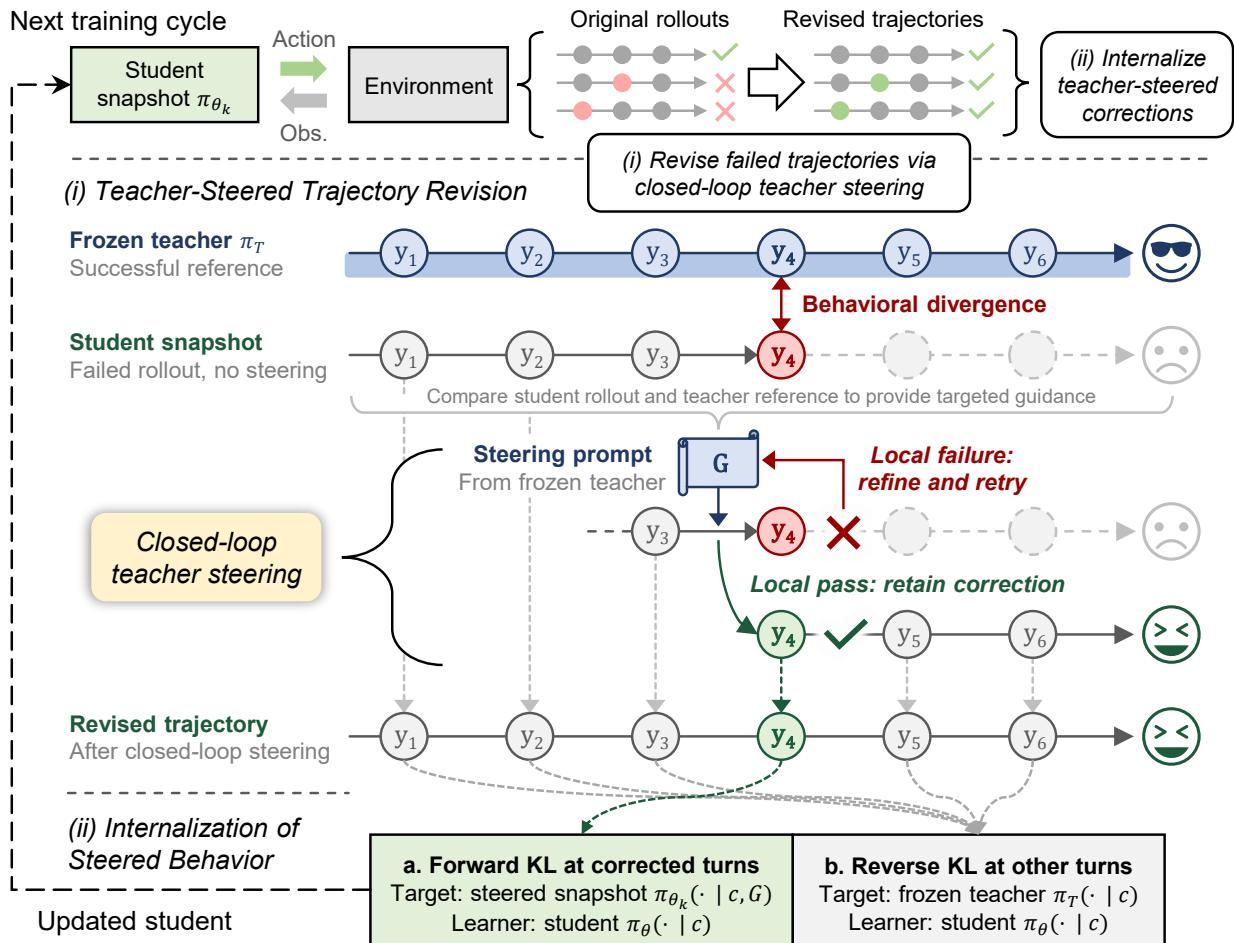
In the teacher-steered trajectory revision phase, the system addresses failed student rollouts by seeking a successful teacher reference for the same task and initial environment state. The authors align the student and reference trajectories by their environment transitions to localize the first behavioral divergence at turn t∗. To revise this decision within its original context, the history and environment state prior to t∗ are restored. The teacher then analyzes the failed response alongside the successful reference to identify overlooked task requirements or environmental conditions. It generates a steering prompt Gt∗ that explains the discrepancy, specifies the applicable conditions, and provides a corrective rule. Conditioned on this prompt, the frozen student generates a revised response yt∗∼πθk(⋅∣ht∗,Gt∗) and executes the corresponding action.
Following the revision, the system performs local verification by comparing the resulting environment states and returned information against the reference. If verification fails, the teacher refines its guidance using feedback from the attempt, and the student retries from the same pre-error history and state. This closed-loop process continues until a correction is locally verified or the per-turn attempt budget is exhausted. Once verified, the corrected response replaces the failed turn, and the student generates a new continuation without guidance. If the task still fails, the revised rollout is realigned with the fixed reference to locate the next behavioral divergence. The trajectory and its verified corrections are retained for distillation regardless of terminal success.
During the internalization of steered behavior phase, the authors train the student on the retained trajectories using two distinct sources of supervision, without providing any steering prompts to the learner. At corrected turns, the system leverages the steered student snapshot. Let c denote the interaction history and response prefix with all steering prompts removed. The frozen student snapshot πθk predicts tokens from (c,G), while the learner πθ predicts from c alone. The authors minimize the forward KL divergence to match the steered student predictions:
ℓFKL(c,G;θ)=DKL(πθk(⋅∣c,G)∥πθ(⋅∣c))At all other turns, including continuations that receive no further correction, the system retains full-precision teacher supervision on the student-generated responses. Both the teacher and the learner receive the same context c without guidance. The authors minimize the reverse KL divergence:
ℓRKL(c;θ)=DKL(πθ(⋅∣c)∥πT(⋅∣c))The overall training objective assigns the loss by turn and averages over all retained assistant-response tokens. For a trajectory i, let Ii denote its retained corrected turns, each associated with a steering prompt Gi,t. For turn t and token j, the context is defined as ci,t,j=(hi,t,yi,t,<j). Let Ak contain all retained assistant-token positions in cycle k. The final objective is formulated as:
L(k)(θ)=∣Ak∣1(i,t,j)∈Ak∑{ℓFKL(ci,t,j,Gi,t;θ),ℓRKL(ci,t,j;θ),t∈Ii,t∈/Ii.Experiment
The evaluation covers five agentic benchmarks across three models under several low-bit settings, comparing SteerDistill with post-training quantization, quantization-aware training, offline and on-policy quantization-aware distillation, and reinforcement-learning baselines. Main results show that SteerDistill consistently outperforms quantized baselines and remains close to the full-precision reference across benchmarks, models, and precisions. Efficiency experiments indicate it reaches higher success rates with fewer GPU hours and fewer output tokens and interaction steps. Ablations confirm that intervening at behavioral divergence, steering through structured teacher-generated prompts, retaining locally verified corrections, and using forward KL at corrected turns with reverse KL elsewhere are important design choices.
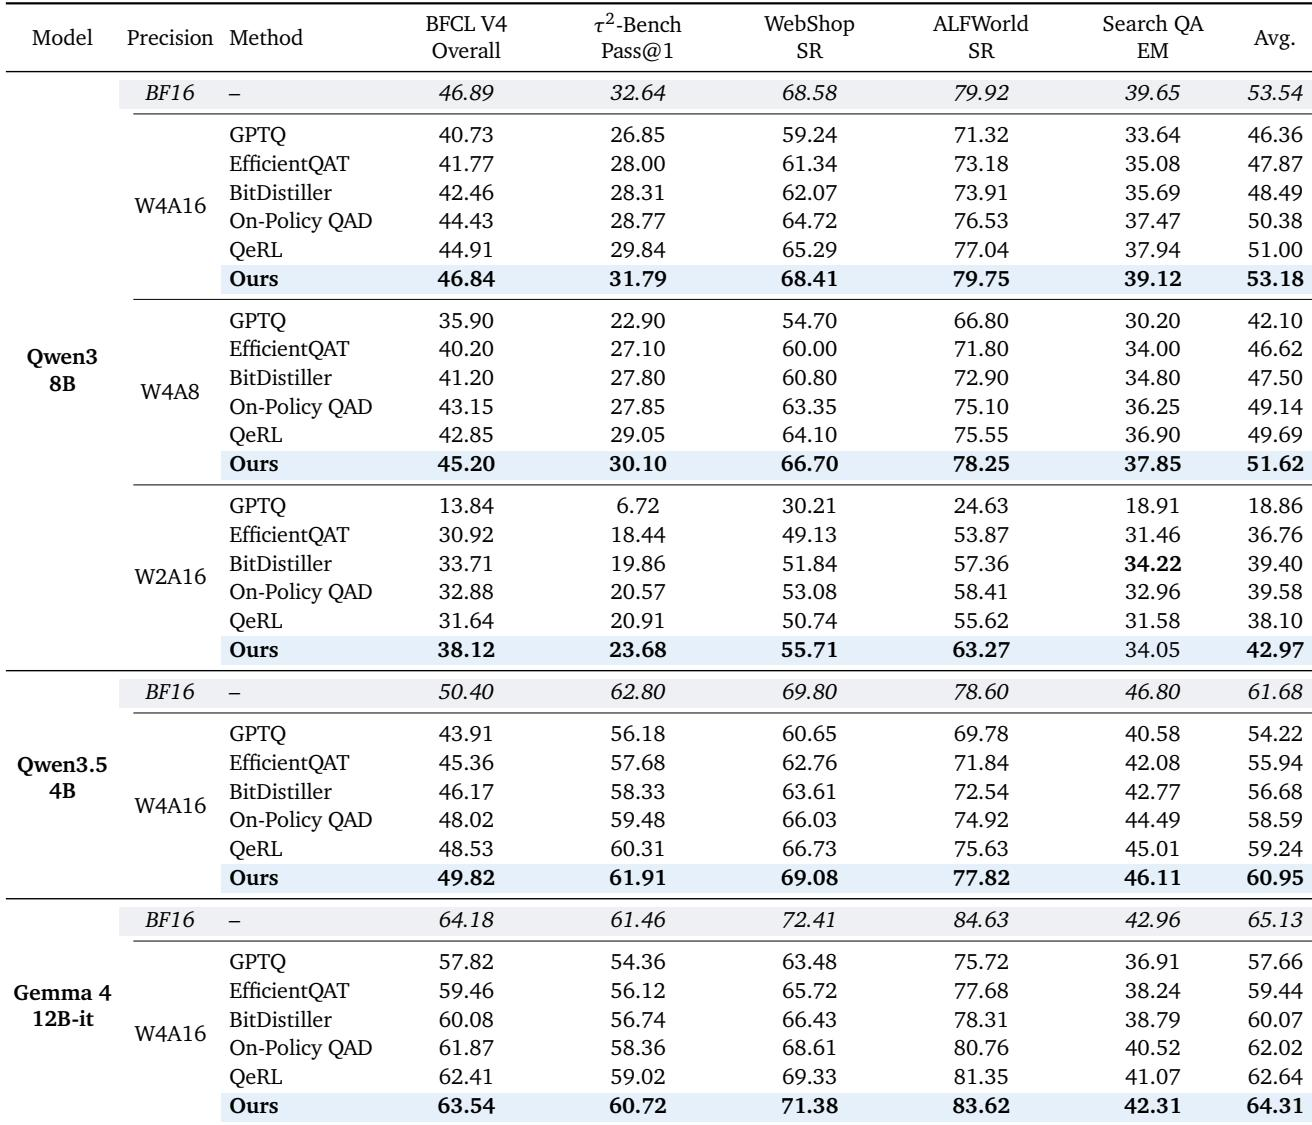
SteerDistill achieves the strongest quantized results among evaluated methods and nearly recovers BF16 reference performance on Qwen3-8B under W4A16. Gains over the best quantized baselines appear across benchmarks and persist across models and lower precision settings. One exception is Search QA under W2A16, where BitDistiller scores slightly higher. Under W4A16 on Qwen3-8B, SteerDistill improves the average score over the strongest quantized baseline QeRL by 2.18 points and trails the BF16 reference by only 0.36 points. SteerDistill outperforms all quantized baselines on every individual benchmark in the Qwen3-8B W4A16 comparison. Across additional models and lower precisions, SteerDistill remains the highest-average quantized method, with only a slight Search QA deficit under W2A16 relative to BitDistiller.
The ablation evaluates design choices for constructing and internalizing behavioral corrections for a quantized agent. Intervening at the first behavioral divergence, steering the student with teacher guidance, and using structured teacher-generated steering prompts each improve BFCL V4 overall scores. Distillation internalizes corrections with forward KL at corrected turns and reverse KL elsewhere. Intervening at behavioral divergence rather than action mismatch improves overall performance, while random intervention falls below the on-policy QAD reference. Teacher-guided steering outperforms unguided retries and direct teacher takeover from the same restored state. Structured steering prompts outperform free-form prompts, and using the full-precision teacher as the steering source outperforms the student and an external model. The final success only variant adds terminal-success filtering after local verification.
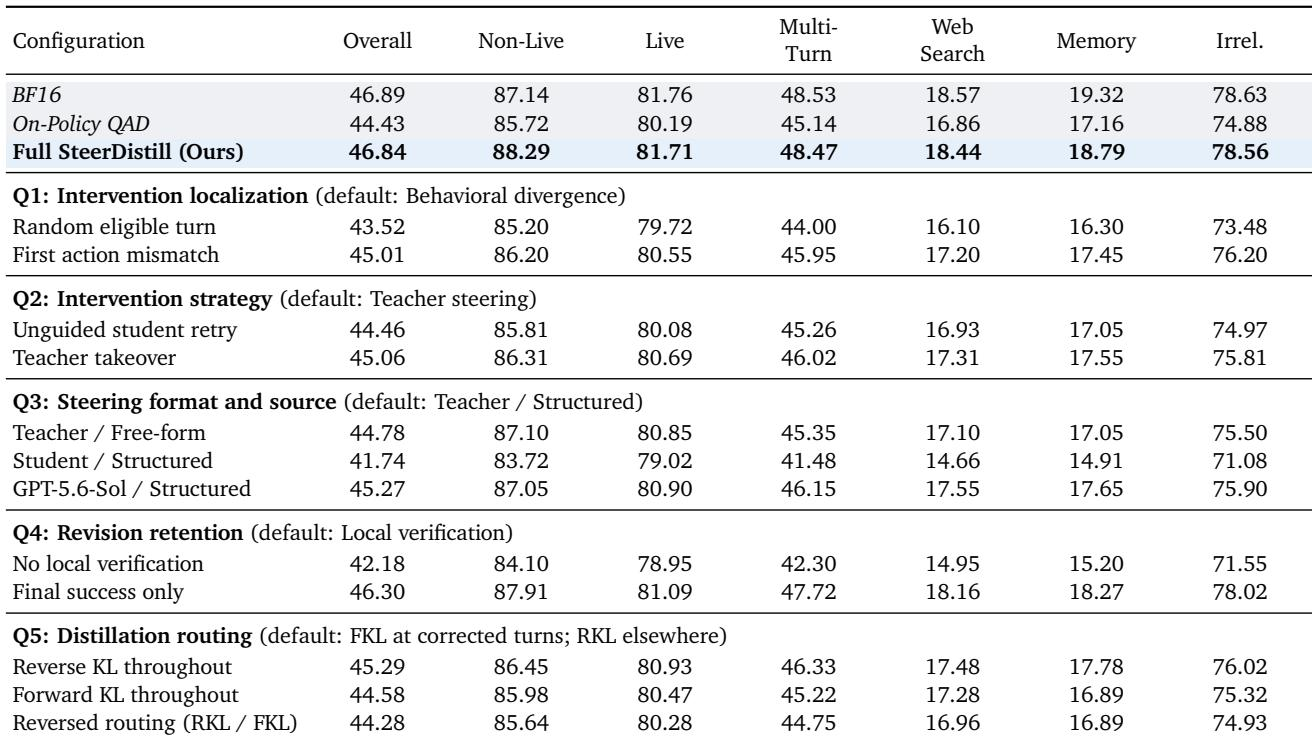
The main evaluation compares SteerDistill with quantized baselines and a BF16 reference, showing that SteerDistill nearly recovers reference performance and achieves the highest average scores across benchmarks, models, and precision settings, with only a minor Search QA deficit under W2A16 relative to BitDistiller. Ablations validate the correction pipeline: intervening at the first behavioral divergence, steering with teacher guidance, using structured teacher-generated prompts, and selecting the full-precision teacher as the steering source all improve overall performance. Distillation internalizes these corrections by applying forward KL at corrected turns and reverse KL elsewhere, and terminal-success filtering further improves the final variant.