Command Palette
Search for a command to run...
الأدوار مهمة: تطوير التعلم المعزز للفيديو المتدفق عبر إسناد الفضل على مستوى الدور
الأدوار مهمة: تطوير التعلم المعزز للفيديو المتدفق عبر إسناد الفضل على مستوى الدور
الملخص
يتطلب فهم الفيديو المتدفق من النماذج أن تقرر مرارًا ما إذا كانت ستستجيب أم ستواصل الملاحظة. طُبّق مؤخرًا أسلوب تحسين السياسة النسبي الجماعي (GRPO) في هذا السياق، وركزت المقاربات القائمة على تصميم المكافآت مع الإبقاء على ميزة نسبية واحدة على مستوى المسار عبر الأدوار. ويمكن لهذا الإسناد المشترك للفضل أن يعزز الردود المتكررة بعد نجاحات سابقة، ويثبط المتابعات المفيدة بعد إخفاقات سابقة. نقترح TurnWise، وهو إطار عمل GRPO على مستوى الدور يواءم التعلم مع قرارات التدفق الفردية. يعالج TurnWise عدم التطابق بين التغذية الراجعة على مستوى المسار والتفاعل على مستوى الدور، مما يعزز الاستجابات المفيدة ويحد من التكرار. على وجه التحديد، يستخدم إسناد الفضل على مستوى الدور تقييم البادئة المكتملة بالصمت لبناء ميزات نسبية جماعية انطلاقًا من العائد المتبقي لكل قرار، مما يفصل إشارة تعلمه عن المكافآت السابقة. يعمل تحسين السياسة بمتوسط الدور على حساب متوسط خسائر الرموز داخل كل دور ثم عبر الأدوار، مما يمنح قرارات الاستجابة والانتظار وزنًا متساويًا بغض النظر عن طول المخرجات. وتحسن هذه التصميمات المتكاملة تعلم سياسة التدفق دون الحاجة إلى ناقد متعلم أو عمليات rollout إضافية. تظهر التجارب الموسعة أن طريقتنا تتفوق على مناهج التعلم المعزز السابقة في فهم الفيديو المتدفق.
One-sentence Summary
Researchers from Fudan University, Shanghai Innovation Institute, JD.com, and other institutions propose TurnWise, a turn-level GRPO framework for streaming video understanding that combines silence-completed prefix scoring for credit assignment with turn-mean policy optimization to separate each decision's learning signal from earlier rewards, promote informative responses, reduce redundancy, and outperform prior RL approaches without a learned critic or additional rollouts.
Key Contributions
- The paper identifies a granularity mismatch in streaming video RL: shared trajectory advantages can obscure the value of later decisions, while token-mean loss aggregation makes turn weights depend on response length.
- TurnWise combines silence-completed prefix scoring for turn-specific remaining-return advantages with turn-mean loss aggregation, without a learned critic or additional rollouts.
- TurnWise achieves the best aggregate scores on ProactiveVQA, OVO-Timing, and StreamingBench with both Qwen backbones, and turn-mean aggregation improves response timing while reducing repetition relative to credit-only optimization.
Introduction
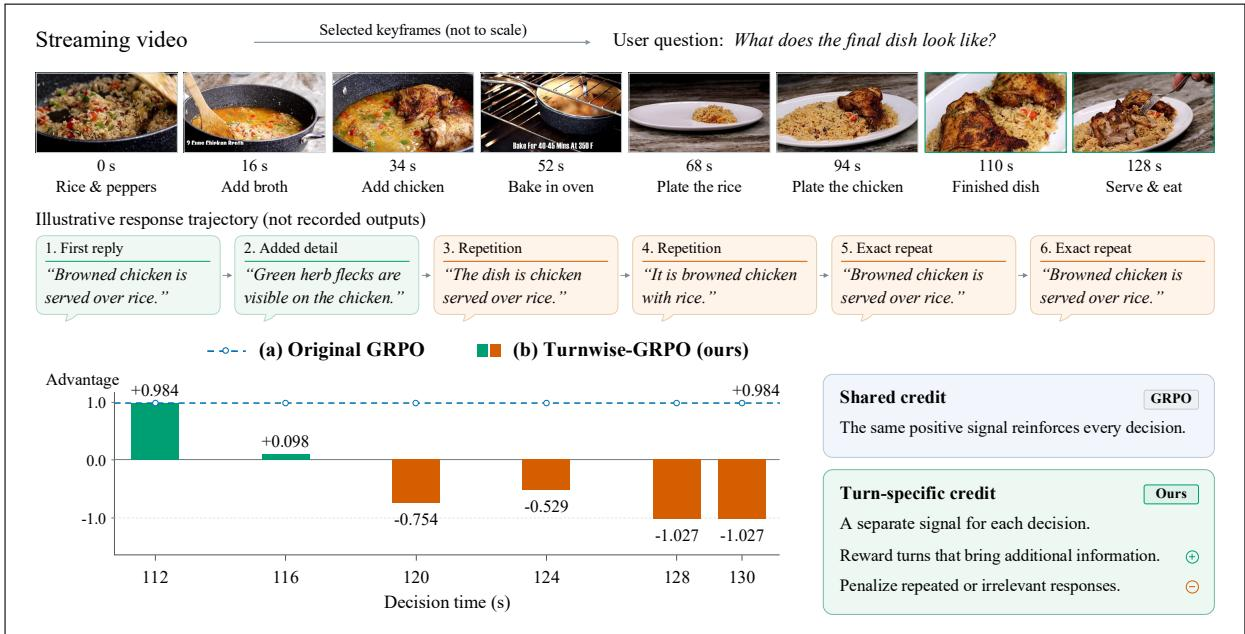
Streaming video understanding requires models to decide, while observations are still arriving, whether to answer or keep observing, so the value of each response or wait depends on both current evidence and prior communication. Prior reinforcement learning methods such as GRPO-based approaches use trajectory-level rewards and shared advantages, which can assign positive credit to redundant later replies or negative credit to useful follow-ups after earlier mistakes; token-mean aggregation further makes turn weighting depend on response length. The authors introduce TurnWise, a turn-level GRPO framework that scores trajectory prefixes with all remaining turns set to silence, converts full trajectory rewards into turn-specific remaining-return advantages, and uses turn-mean loss aggregation to weight response and waiting decisions equally. TurnWise needs no learned critic or additional rollouts and reports the best aggregate results on ProactiveVQA, OVO-Timing, and StreamingBench with two Qwen backbones.
Method
The authors introduce TurnWise, a framework designed to align policy optimization with streaming decisions in video dialogue systems. TurnWise achieves this through two coupled mechanisms: group-relative remaining-return advantages for precise temporal credit assignment, and turn-mean policy optimization to ensure length-independent decision weighting.
As shown in the figure below:
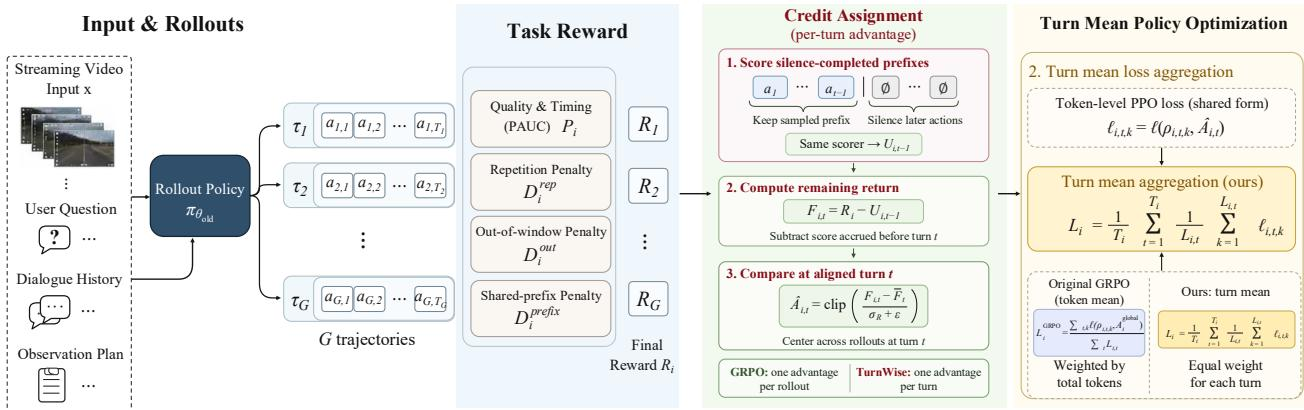
The framework processes a streaming instance comprising video input x, user queries, initial dialogue history h0, and an observation plan. At each decision turn t, the policy πθ generates either a textual response or an explicit waiting action denoted as ∅. To learn these sequential decisions, the authors sample G trajectories τi from the rollout policy. Each complete trajectory is evaluated using a PAUC-based reward Ri that measures response quality and timeliness while penalizing repetition, out-of-window responses, and shared-prefix violations.
Standard Group Relative Policy Optimization (GRPO) converts this trajectory score into a single global advantage, which fails to distinguish rewards earned before a turn from gains obtained afterward. To resolve this temporal mismatch, TurnWise introduces turn-level credit assignment without requiring a critic model. The authors exploit the sequential observation stream by scoring what a trajectory prefix achieves if all subsequent actions are set to silence. Specifically, they compute a silence-completed prefix score Ui,t by retaining the first t sampled actions and replacing later actions with ∅. The turn-level reward increment is derived from the remaining return Fi,t=Ri−Ui,t−1, which excludes earlier accrued rewards from the current decision's credit. These remaining returns are compared within each rollout group to compute the turn-specific advantage:
A^i,t=[σR+ϵFi,t−Fˉt]−amaxamaxwhere Fˉt is the group mean of the remaining returns, σR is the standard deviation of terminal rewards, and the operator clips the normalized advantage to [−amax,amax]. To smoothly transition from shared to turn-specific credit during training, an interpolation parameter α scales the accrued-reward correction, linearly increasing from 0 to 1 over the initial training updates.
While turn-level advantages assign credit to individual decisions, standard token-mean loss aggregation still weights these decisions by response length, causing long responses to outweigh short waiting actions. The authors introduce turn-mean policy optimization to give each streaming decision equal aggregation weight regardless of its output length. They apply the corrected group-relative advantage to each token within its turn using a clipped probability-ratio surrogate ℓi,t,k(θ). The final trajectory loss is computed by first averaging token losses within each turn and then averaging across all turns:
Li(θ)=Ti1t=1∑TiLi,t1k=1∑Li,tℓi,t,k(θ)where Ti is the number of decision turns and Li,t is the number of generated tokens at turn t.
The unified TurnWise objective couples these turn-specific remaining-return advantages with length-independent decision weights. The training pipeline begins with supervised fine-tuning on a diverse corpus of video instruction examples, freezing the vision tower. This is followed by GRPO-style reinforcement learning optimization, where the policy is updated using the unified objective, turn-mean aggregation, and the PAUC-based reward judged by a large language model.
Experiment
The experiments fine-tune Qwen2.5-VL-3B and Qwen3-VL-4B on streaming instruction data and then optimize them with GRPO-style RL using a PAUC-based reward, evaluating on ProactiveVQA, OVO-Timing, and StreamingBench to cover proactive answer quality, event-triggered timing, and real-time visual understanding. Compared with SFT and GRPO baselines, TurnWise achieves the best aggregate scores on all three benchmarks with both backbones. Ablations and trajectory analyses show that turn-level credit assignment and turn-mean aggregation are complementary: credit assignment provides distinct per-turn learning signals, including negative signals for redundant replies, while turn-mean aggregation weights those signals to produce more selective responses, higher reward, lower repetition, and fewer outside-window replies.
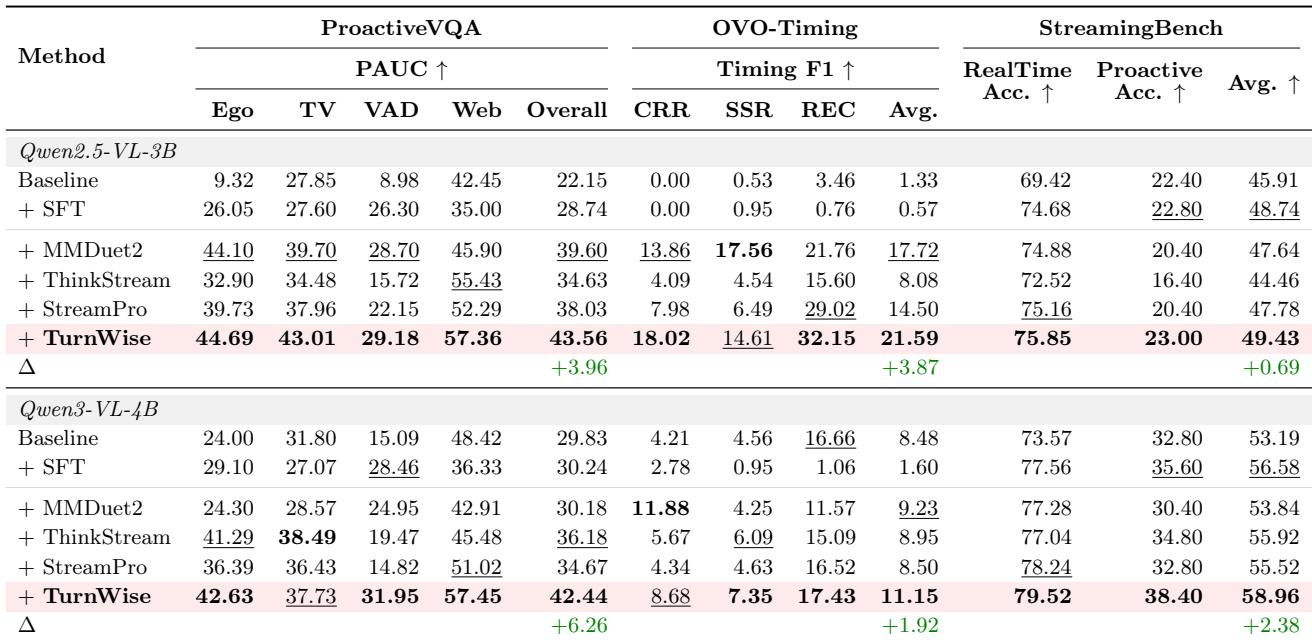
TurnWise attains the best aggregate results on ProactiveVQA, OVO-Timing, and StreamingBench with both tested backbones. The gains over the strongest non-TurnWise methods are consistent across proactive interaction, response timing, and real-time visual understanding. Per-category results show broad advantages, especially on ProactiveVQA and StreamingBench. TurnWise outperforms all SFT and GRPO-based RL baselines on the three aggregate metrics for both Qwen2.5-VL-3B and Qwen3-VL-4B. On ProactiveVQA, TurnWise leads all four categories with the 3B backbone and three of four with the 4B backbone, with clear gains in VAD and Web for the 4B model. TurnWise achieves the highest real-time and proactive accuracy on StreamingBench for both backbones, improving the 4B proactive accuracy from 35.60 to 38.40 relative to the strongest baseline.
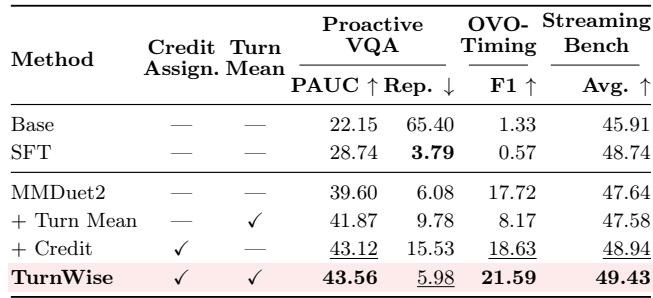
On Qwen2.5-VL-3B, combining turn-level credit with turn-mean aggregation yields the highest ProactiveVQA, OVO-Timing, and StreamingBench scores among the evaluated configurations. The combination improves timing F1 and task accuracy while substantially reducing repetition compared with credit-only and aggregation-only variants. Turn-level credit sets the learning direction for each decision, while turn-mean aggregation controls its policy update weight, making the full configuration stronger than either component alone. Adding turn-mean aggregation to credit-only optimization sharply reduces repetition while improving Timing F1 and StreamingBench average accuracy. Relative to turn-mean aggregation alone, adding turn-level credit substantially improves Timing F1 and further reduces repetition. The full TurnWise configuration achieves the highest ProactiveVQA PAUC, OVO-Timing F1, and StreamingBench average accuracy in the component comparison.
Under turn-mean aggregation, the full correction setting achieves the best results among the tested correction strengths on Qwen2.5-VL-3B. It ranks first on ProactiveVQA PAUC, OVO-Timing F1, StreamingBench accuracy, and repetition. This supports full accrued-reward correction as the operating point for the framework. Full correction outperforms partial correction strengths across all four evaluated metrics when turn-mean aggregation is used. Lower correction strengths do not surpass full correction on any metric in this configuration. The full accrued-reward correction is identified as the preferred operating point.
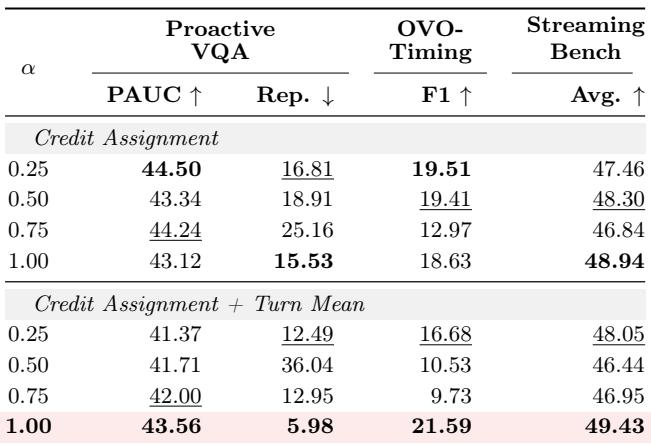
The experiments evaluate TurnWise against SFT and GRPO-based RL baselines on ProactiveVQA, OVO-Timing, and StreamingBench using Qwen2.5-VL-3B and Qwen3-VL-4B, covering proactive interaction, response timing, and real-time visual understanding. TurnWise achieves the best aggregate results with both backbones and shows broad per-category gains. Ablations show that combining turn-level credit with turn-mean aggregation yields the highest scores while substantially reducing repetition, and correction-strength experiments identify full accrued-reward correction as the preferred operating point.