Command Palette
Search for a command to run...
Route Anything: دراسة لتوجيه النماذج والسياسات في أنظمة الذكاء الاصطناعي للأغراض العامة
Route Anything: دراسة لتوجيه النماذج والسياسات في أنظمة الذكاء الاصطناعي للأغراض العامة
Pengfei Zhou Yixing Ma Hexin Wang Weidong Tang Zhenglin Wan Wangbo Zhao Yang You
الملخص
يتطلب الذكاء الاصطناعي العام (AGI) منهجيةً قادرةً على الفهم والتوليد والاستدلال والفعل عبر مجالات وطرائق متنوعة. وبدلاً من الاعتماد على نموذج واحد لإتقان كل قدرة، يتمثل أحد المسارات الواعدة نحو الذكاء الاصطناعي العام اليوم في تنسيق منظومة غير متجانسة من النماذج والأدوات والسياسات المتخصصة (المرشحين) داخل نظام ذكاء اصطناعي موحد. وفي قلب هذه الرؤية يكمن سؤال جوهري: كيف يمكن لنظام ذكاء اصطناعي أن يختار وينسق ديناميكياً المرشح الأكفأ لكل مهمة مع الموازنة بين الأداء والتكلفة الحسابية؟ في هذا العمل، نقدم Route Anything، وهو إطار موحد لدراسة توجيه النماذج والسياسات عبر أنظمة الذكاء الاصطناعي للأغراض العامة. نطور أساساً نظرياً موحداً يصف التوجيه الأمثل في ظل مقايضات الجودة والتكلفة، ويوضح كيف تحدد المعلومات المتاحة للموجِّه الأداء الذي يمكن بلوغه. ولدراسة التوجيه منهجياً عبر قدرات متنوعة، نبني أولاً مصفوفة مسارات متعددة الوسائط تغطي 25 معياراً تشمل فهم اللغة، وتوليد الصور والفيديو والكلام، ووكلاء البرمجة وأماكن العمل، والمعالجة الروبوتية، وتضم 374,401 تجربة مُقيَّمة من 452 إعداداً للمرشحين. وبالاستناد إلى هذا الإطار، ندرّب ونختبر موجِّهات مختلفة لاستكشاف إمكانات توجيه النماذج متعدد الوسائط، وقدرات الموجِّهات المتعلَّمة، والظروف التي يحسِّن فيها التوجيه الكفاءة. تكشف نتائجنا عن فرص كبيرة لتنسيق القدرات: يتفوق التوجيه الأوراكلي لكل مُدخل على أفضل مرشح ثابت بمقدار 5.4 نقاط، وتتفوق الموجِّهات المتعلَّمة عليه بمقدار 0.3 نقطة عبر 16 معياراً، وبمقدار 2.1 نقطة في توليد الفيديو، وبمقدار 1.1 نقطة في المعالجة الروبوتية، مع استخدام زمن تنفيذ سياسات أقل بنسبة 24%. والأهم من ذلك أن التوجيه يرفع الكفاءة بمعدل 8.82 مرة في المتوسط مقارنةً بالنموذج المرجعي، منها 25.5 مرة في مهام البرمجة و7.1 مرة في الإجابة عن الأسئلة النصية.
One-sentence Summary
Researchers from the National University of Singapore, University of California, Berkeley, and Hong Kong University of Science and Technology propose Route Anything, a unified model and policy routing framework for general-purpose AI that pairs quality-cost optimal routing theory with an omni-modal trajectory matrix of 374,401 runs across 25 benchmarks, and show that learned routers improve video generation by 2.1 points, robot manipulation by 1.1 points while using 24% less policy time, and efficiency by 8.82× on average relative to the reference model.
Key Contributions
- Route Anything is a unified framework for studying model and policy routing across general-purpose AI systems, with a theoretical foundation characterizing optimal routing under quality–cost trade-offs and linking router information to attainable performance.
- An omni-modal trajectory matrix spans 25 benchmarks across text and image understanding, image, video, and speech generation, coding and workplace agents, and robot manipulation, comprising 374,401 scored runs from 452 candidate configurations.
- Per-input oracle routing outperforms the best fixed candidate by 5.4 points, and learned routers outperform it by 0.3 points across 16 benchmarks, by 2.1 points on video generation, and by 1.1 points on robot manipulation with 24% less policy time. Routing also raises efficiency by 8.82× on average over the reference model, including 25.5× on coding and 7.1× on text question answering.
Introduction
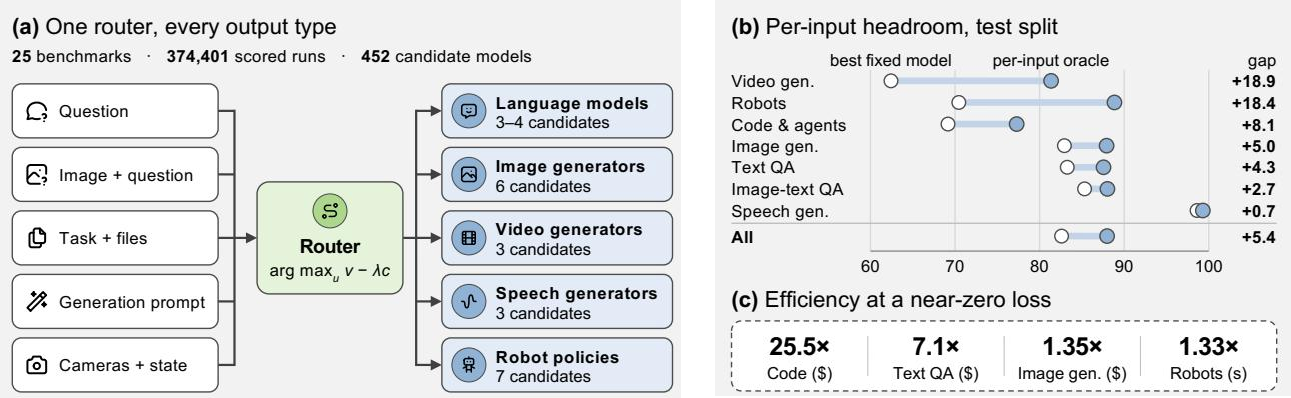
Agentic AI systems increasingly orchestrate many specialized models, tools, and policies, such as language models, image or video generators, speech models, and robot policies, rather than relying on one model for every capability. Because the best candidate for a given input varies, routing can match a strong fixed candidate at lower cost or exceed it by sending each input to the most suitable module. Prior routing research has focused mainly on language models, leaving the value of routing across modalities largely open. The authors introduce Route Anything, a unified framework for studying model and policy routing across text, images, video, speech, code, agents, and robot manipulation. They build an omni-modal trajectory matrix that evaluates 452 candidate configurations on the same inputs across 25 benchmarks, totaling 374,401 scored runs, and connect routing decisions to priced costs and quality constraints.
Method
The authors formulate the routing problem as selecting an optimal candidate from a finite menu for a given input. Each candidate yields an expected value and consumes a specific amount of resources. The router observes a state and selects a candidate to maximize a value-cost objective.
Jλ(g)=E[Vg]−λE[Dg]At a given resource price λ, the router balances quality and cost. To ensure reliability, the framework introduces a quality floor constraint relative to a reference policy, requiring the quality change to remain above a negative tolerance threshold.
For the learned routing models, the authors leverage a fine-tuned Qwen3.5-4B backbone, processing task text, output requirements, and optional multimodal inputs like camera frames or robot states. They propose two primary routing architectures. The outcome router scores each input and candidate pair using a sigmoid head. This module is trained via cross-entropy against the normalized outcome of the candidate, directly optimizing for expected value. The type router alternatively classifies the input into a specific capability type and selects the best candidate from a pre-fitted table. The authors explicitly prefer outcome regression over winner-label classification, as the latter discards valuable information from ties and failures and can suffer from significant value loss.
To guarantee the quality floor on unseen test inputs, the system employs a sequential certification workflow along a price path. As the price parameter increases from zero to the fitted maximum efficiency, a sequence of routers is evaluated.
As shown in the figure below:
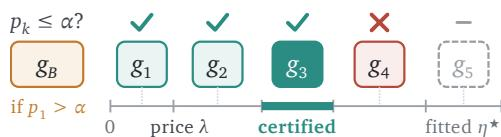
The certification process tests routers in order, computing valid p-values for the null hypothesis that the quality change falls below the negative tolerance. The workflow stops at the first router that fails the statistical test, returning the last certified router. If the very first router fails the test, the system defaults to the baseline reference policy, thereby ensuring a certified quality floor without requiring multiplicity corrections.
Experiment
These experiments evaluate model routing across multimodal benchmarks, robot manipulation, and cost-sensitive code and router testbeds, comparing fixed best candidates, oracles, and learned routers on matched inputs. The findings show that most routing headroom lies within task types rather than between them, and learned routers provide only modest quality gains, with clearer benefits when an outcome-based robot router reads the scene and saves inference time. Cost-aware studies further indicate that cheaper routes are often good enough, while retries, verifiers, and finer states are worthwhile only if their added value exceeds their full cost, and matched comparisons on identical inputs are essential to avoid artificial gains from missing-score fallbacks.
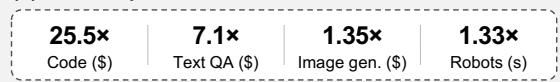
Routing improves efficiency over a reference model across modalities while keeping quality loss small, with the largest gains in code and text question answering and more modest gains in image generation and robot policy inference. Per-input candidate selection provides clear headroom over any fixed candidate, and image generation routing can trade a small quality loss for meaningful cost savings. However, fitted zero-loss guarantees can be brittle unless certified, and richer candidates or finer states are worthwhile only when their net value beats what they replace. Code and text QA see the largest routing efficiency gains, while image generation and robot policy routing show comparatively small improvements. Oracle candidate selection outperforms the best fixed candidate per benchmark, and image routing can cut cost with minimal quality loss, but fitted guarantees need certification to hold reliably.
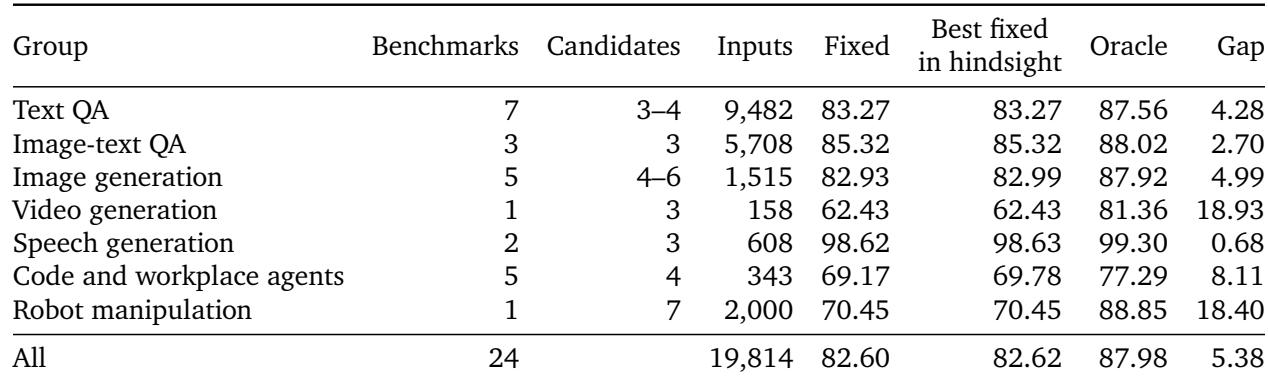
A per-input oracle scores clearly above the best fixed candidate on the test split, but the size of this gap varies widely across task groups. The largest potential gains are in video generation and robot manipulation, while speech generation has almost no headroom. Choosing the best fixed candidate in hindsight adds little over the training-selected fixed candidate, so most opportunity lies within task types. The largest oracle-to-fixed gaps occur in video generation and robot manipulation, where no candidate dominates and the gaps are roughly 18 to 19 points. Speech generation candidates are nearly perfect, leaving a gap well under one point between the fixed and oracle scores.
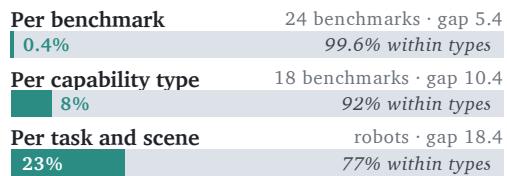
Finer grouping reveals larger potential gains from selecting the best candidate. The gap is smallest at benchmark level, grows at capability-type level, and is largest for task-and-scene splits, especially robots. Most of the gain lies within types at coarser levels, but the within-type share declines for task and scene splits. Potential routing gain increases as grouping moves from benchmark-level to capability-type-level to task-and-scene-level. Robots show the largest gap and the lowest within-type share, indicating more potential gain outside type-level selection. Router overhead remains small relative to image and video generation costs.
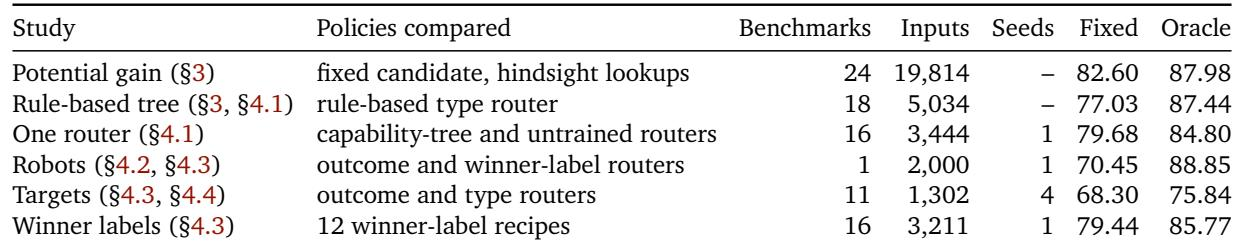
Across the reported panels, oracle policies consistently outperform the fixed candidate, but both fixed-candidate scores and the size of the gain vary by setting; the robot panel shows the largest headroom. Absolute scores are comparable only within each row, so these gaps are the key within-study signal. Related routing experiments show cost-quality tradeoffs, including image routes that cut test cost substantially at a small score loss and robot routing that saves time without lower success. Oracle scores exceed fixed-candidate scores in every listed study, showing consistent potential gains from better candidate selection. The robot panel has the largest fixed-to-oracle gap, indicating more headroom for learned routers in that setting. Some multi-benchmark panels show relatively small fixed-to-oracle gaps, while the robot and rule-based tree panels show larger absolute gains. Image routing experiments show a modest quality loss can cut test cost by roughly a quarter, while robot routing saves time without reducing success.
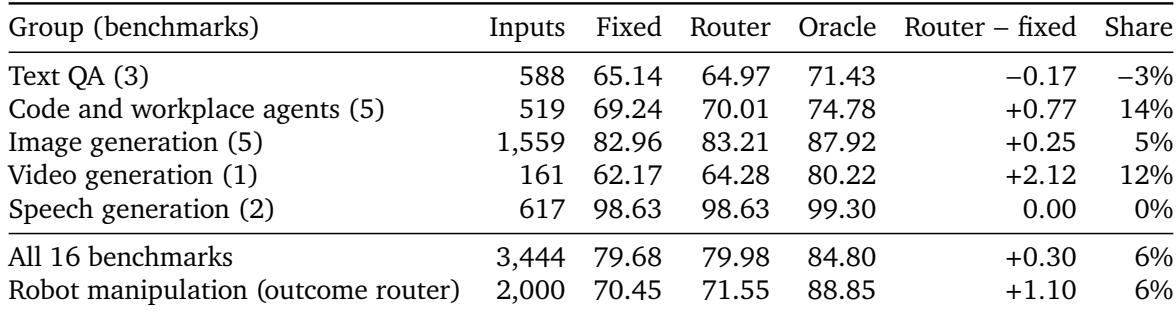
Across the 16 benchmarks, the learned router improves the average score only slightly over the fixed candidate and captures a small share of the oracle headroom. Gains are uneven: code and workplace agents and video generation benefit most, text QA declines slightly, speech generation is unchanged, and image generation shows only a modest lift. The robot manipulation outcome router also improves over its fixed candidate but leaves most of the oracle gap unclaimed. Code and workplace agents and video generation show the largest improvements over the fixed candidate, while text QA is the only group where the router scores below it. Speech generation shows no change, image generation captures only a small fraction of the possible oracle gain, and robot manipulation improves but with a similarly modest share of the oracle gap.
These experiments compare learned per-input routing against fixed and oracle candidate selection across benchmarks, modalities, and grouping granularities. Routing improves efficiency with generally small quality loss, with the largest gains in code, text question answering, video generation, and robot manipulation, while speech and image generation show limited headroom or modest improvements. Finer task-and-scene grouping increases potential routing gain, especially for robots, but learned routers capture only a small share of the oracle gap, and fitted zero-loss guarantees need certification to be reliable.