Command Palette
Search for a command to run...
تحفيز التعلم الذاتي في نماذج اللغة الكبيرة عبر التعلم المعزز
تحفيز التعلم الذاتي في نماذج اللغة الكبيرة عبر التعلم المعزز
Lingkai Kong Yuzhe Gu Haiteng Zhao Zijian Wu Youqing Fang Zhouqi Hua Yanan Sun Kai Chen Wenwei Zhang
الملخص
تعتمد نماذج اللغة الكبيرة على المعرفة البارامترية والتوليد المعزز بالاسترجاع لحل المهام كثيفة المعرفة. غير أن حل المشكلات في مجالات غير مألوفة يتطلب اكتسابًا للمعرفة واستدلالًا مترابطين بإحكام، بما يتجاوز مجرد استرجاع الحقائق وتجميعها أو التعلم من سياق مُعد مسبقًا. ندرس التعلم الذاتي، أي استرجاع المواد المرجعية الطويلة ودراستها وتطبيقها ذاتيًا في أثناء العمل. ولاستقصاء هذه القدرة، نصوغ مهمة لحل مسائل رياضية قائمة على الكتب الدراسية، حيث يتعين على النماذج التنقل في عرض الكتاب، وتعلم المبادئ ذات الصلة وتطبيقها، وبناء براهين للتمارين مع حجب الحلول المرجعية. ونقدم واجهة BookNavigator لدعم هذه العملية الدراسية المستوحاة من البشر، ونحفز التعلم الذاتي عبر التعلم المعزز بمكافآت دقيقة الحبيبات. وتبين التجارب أن طريقتنا تحسن الأداء عبر كتب دراسية وموضوعات داخل النطاق وخارجه، إذ ترفع الدقة الإجمالية للبراهين لنموذج Intern-S2-Preview-35B من 51.5% إلى 79.5%، وتتفوق على خطوط الأساس المدربة بالتعلم المعزز دون كتب دراسية وذات الاسترجاع الثابت. وتمتد هذه المكاسب إلى معايير تقييم معقدة ذات سياقات طويلة تشمل أنواع مهام مختلفة، مع تحسينات عن النموذج الأساسي قدرها 1.7 و2.3 نقطة مئوية على BrowseComp-Plus وCL-bench على التوالي. وتشير هذه النتائج مجتمعة إلى أن التعلم المعزز يمكن أن ينمي استراتيجية تعلم ذاتي غير مرتبطة بمجال محدد، مما يبرز إمكانات التعلم الذاتي من المدونات الطويلة في تعزيز قدرات أوسع لحل المشكلات في المهام المعقدة ذات السياقات الطويلة.
One-sentence Summary
Researchers from Shanghai AI Laboratory and collaborators propose the BookNavigator interface, which uses reinforcement learning with fine-grained rewards to incentivize self-learning in LLMs, enabling Intern-S2-Preview-35B to study long-form textbooks on the fly, raising its proof accuracy from 51.5% to 79.5% and improving performance on BrowseComp-Plus and CL-bench.
Key Contributions
- The paper defines a textbook-based mathematical problem-solving task in which models must navigate long-form textbook exposition, learn relevant definitions and theorems, and construct proofs for exercises without access to reference solutions.
- It introduces the BookNavigator interface and a fine-grained reinforcement learning reward scheme that credits study and navigation actions, encouraging autonomous knowledge acquisition and application within a single problem-solving episode.
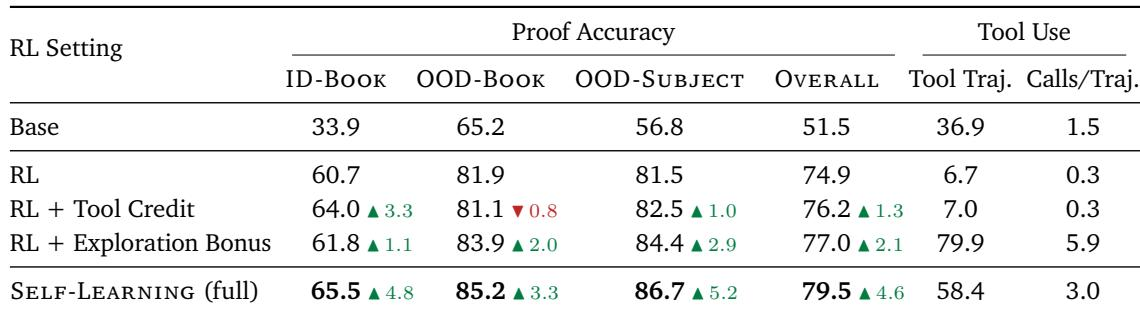
- Experiments show the method improves Intern-S2-Preview-35B’s overall proof accuracy from 51.5% to 79.5% across in-domain and out-of-domain textbooks and subjects, outperforms RL-trained textbook-free and fixed-retrieval baselines, and transfers to long-context benchmarks with gains of 1.7 points on BrowseComp-Plus and 2.3 points on CL-bench.
Introduction
Large language models acquire broad parametric knowledge during pretraining, and retrieval-augmented generation or search tools extend their access to external information at inference time, but solving unfamiliar problems also requires understanding new principles and integrating them into a developing solution. Prior work addresses related pieces through retrieval-trained agents, context-learning studies, and meta-RL or test-time adaptation, yet sustained autonomous study of long-form reference materials remains underexplored. The authors formulate a textbook-based mathematical problem-solving task in which models must study definitions, theorems, and proofs while constructing exercise solutions. Their main contribution is a training framework using the BookNavigator interface and fine-grained reinforcement learning with an annealed exploration bonus and round-level tool credit, which yields transferable self-learning improvements across unseen textbooks, unseen subjects, and non-mathematical complex-context tasks.
Dataset
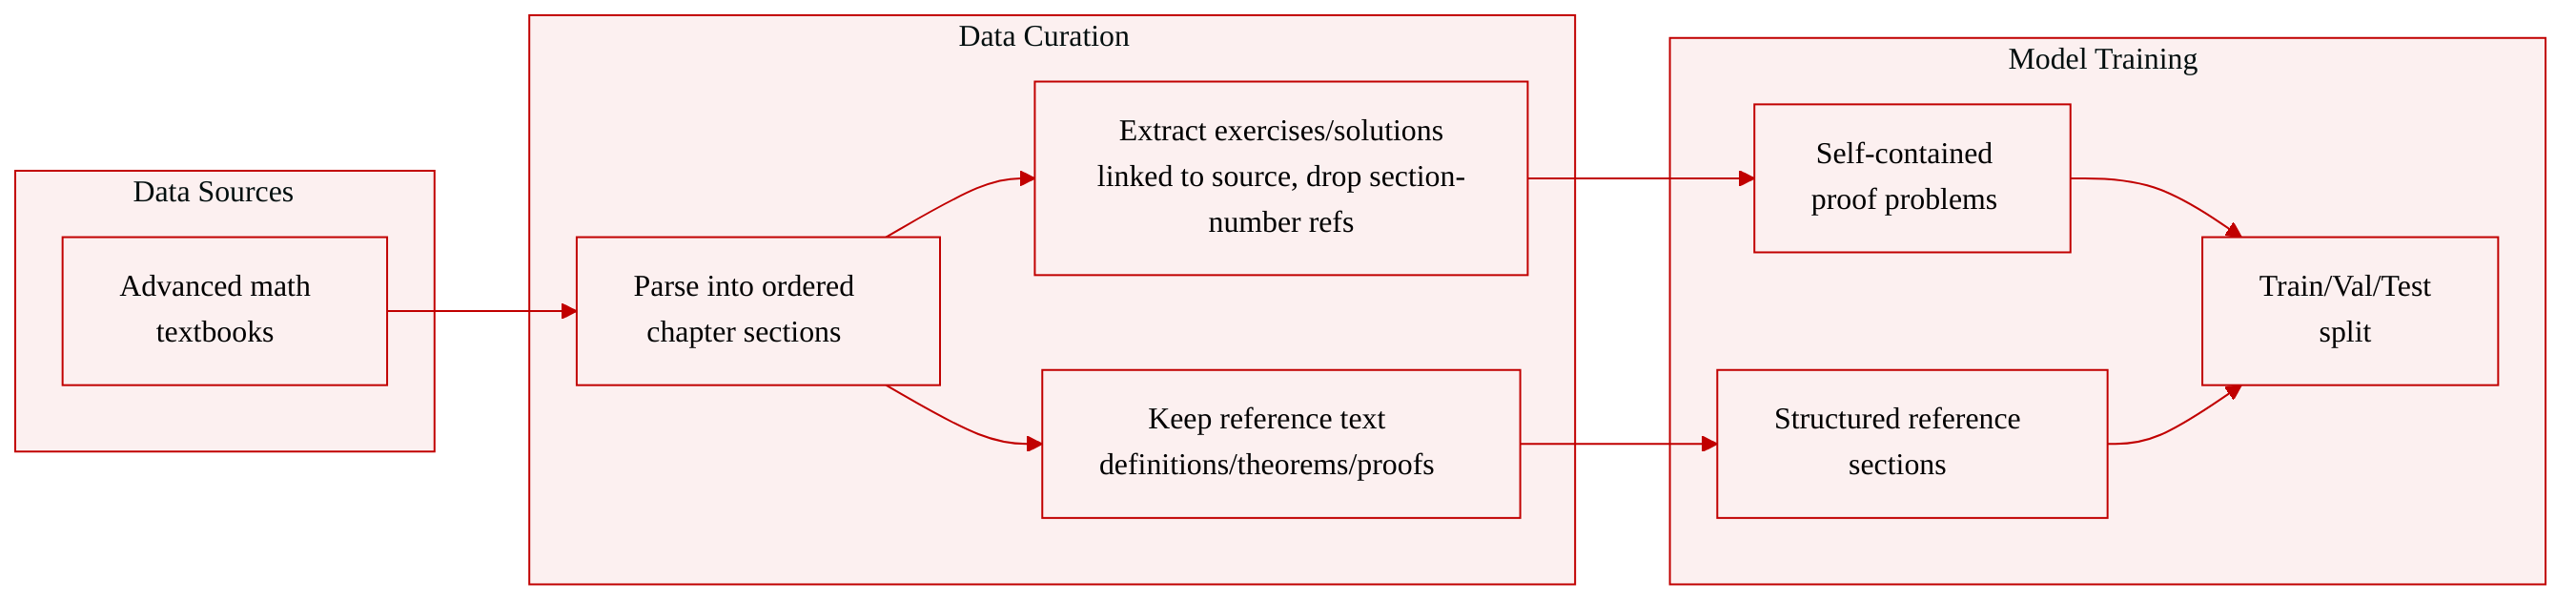
The authors build a proof-problem dataset from advanced mathematics textbooks.
-
Sources and composition
- The dataset is constructed from advanced mathematics textbooks.
- It contains two main parts:
- Proof problems extracted from exercises, paired with their solutions.
- Structured reference material retained from expository textbook content, including definitions, theorems, explanatory passages, and proofs of general results.
-
Processing and filtering
- Each textbook is parsed into chapter-indexed text sequences.
- The hierarchical organization is preserved so that sections can be navigated and read in order.
- Exercises and solutions are extracted separately from the expository content and linked to their source textbooks.
- Exercises that explicitly refer to textbook section numbers are excluded.
- This filtering is intended to make problem statements self-contained.
-
Schema and structure
- The model-visible textbook is represented as an ordered sequence of sections.
- Each section is stored as a triple: section identifier, title, and retained text.
- Formally, the textbook is written as an ordered list of sections, where each section includes an identifier, a title, and the section text.
-
Usage in the model
- The retained textbook sections serve as structured reference material available during problem solving.
- The proof problems are designed to require deliberate, self-directed study rather than simple answer retrieval.
- The paper does not provide explicit mixture ratios or split sizes in this section.
Method
The authors formalize self-learning within a textbook-based mathematical problem-solving framework, where a model constructs self-contained proofs through multi-round reasoning and structured textbook study. The overall pipeline and training loop are illustrated in the framework diagram.
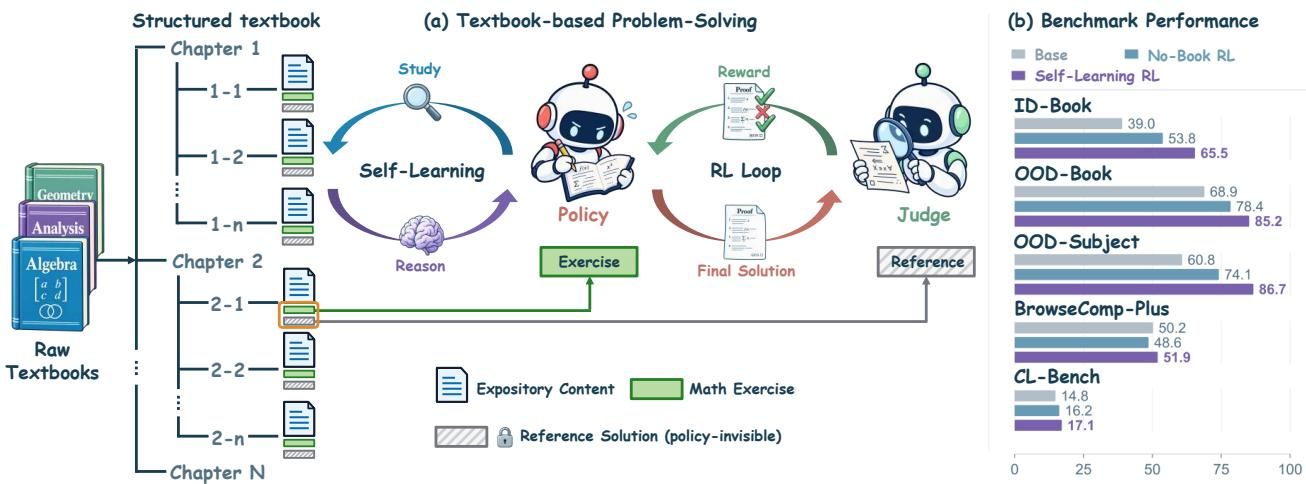
To establish the learning environment, the authors employ an end-to-end pipeline to curate problem-textbook pairs from raw textbooks. Each textbook is parsed into a hierarchical sequence of sections, retaining definitions, theorems, and explanatory passages while separating exercises and their solutions. The model-visible textbook B is represented as an ordered sequence of sections sk=(ιk,ℓk,xk), where ιk, ℓk, and xk denote the section identifier, title, and text, respectively. This structured format ensures that tasks require deliberate, self-directed study rather than simple answer retrieval.
Given a problem q and the structured textbook B, the policy πθ interacts with the environment over multiple rounds. At each non-terminal round t, the model generates reasoning zt and executes an action at from a textbook-access action space A, receiving an observation ot. The interaction trajectory concludes at round T with the final proof y^. The correctness of y^ is evaluated by an LLM-as-judge against a withheld reference solution y⋆, yielding a binary reward r(τ)∈{−1,1}.
To facilitate effective textbook navigation, the authors design BookNavigator, which serves as the sole interface between the policy and the textbook. It supports three distinct operations: global orientation via get_toc to retrieve the table of contents, keyword-based retrieval via search_index to locate relevant sections, and detailed reading via read_section to access the full text of a specific section. This allows the model to seamlessly interleave mathematical reasoning with targeted information retrieval.
To optimize the policy, the authors refine the reinforcement learning process using fine-grained rewards that encourage productive exploration and penalize redundant access. They introduce an annealed exploration bonus b(τ) for trajectories with correct solutions, added to the trajectory-level reward Rn(τ)=r(τ)+βnb(τ)I[r(τ)=1], where βn follows a cosine schedule to sustain exploration throughout training. Furthermore, to distinguish useful textbook study from unproductive interactions, a tool judge evaluates each round and assigns a credit label ct∈{useful, neutral, harmful}. This round-level credit is used to redistribute the trajectory-level advantage A, computing a refined advantage At=A+α∣A∣(ct−cˉ) for each round. The policy is then optimized using a GRPO objective that incorporates these redistributed advantages, ensuring that the learning signal accurately reflects the quality of individual textbook access decisions.
Experiment
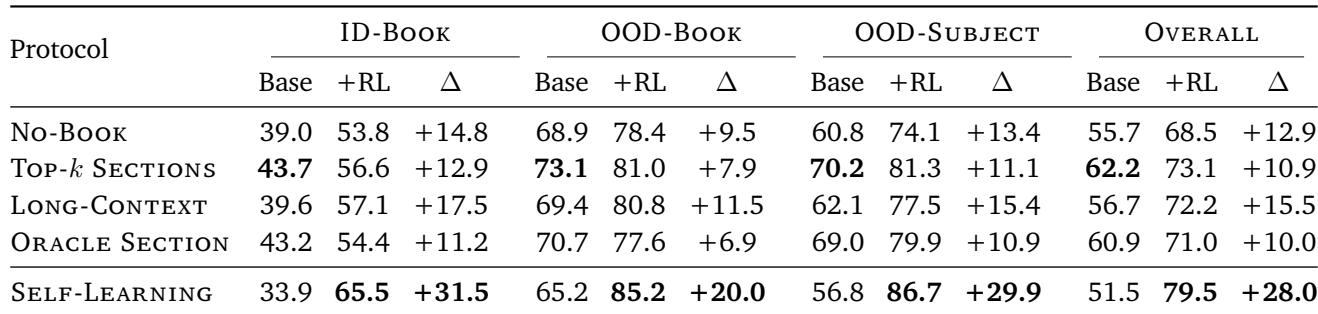
The experiments train and evaluate a 35B model with GRPO on 5,183 problems from 158 mathematics textbooks, comparing an interactive Self-Learning protocol that interleaves reasoning and BookNavigator access against no-book and fixed-retrieval baselines across held-out book, subject, and cross-task benchmarks. The main results show that reinforcement learning reverses the initial weakness of Self-Learning, making it the best protocol overall and on out-of-domain books and subjects, while attribution analyses indicate the gains reflect stronger unaided reasoning plus robust knowledge acquisition rather than memorization of specific source sections. Cross-task evaluations find transfer to BrowseComp-Plus and CL-bench, though improvements are selective, and RL ablations show that round-level tool credit improves in-domain learning while an annealed exploration bonus preserves tool use and improves cross-domain transfer.
Before RL, self-learning had the lowest overall proof accuracy among the evaluated protocols. After RL, it achieved the highest overall accuracy and the largest absolute gain, surpassing fixed-retrieval baselines and no-book retrieval. On out-of-distribution books and subjects, self-learning also remained the most accurate protocol, showing transfer beyond training-specific textbooks and subjects. Self-learning shifts from the weakest overall protocol before RL to the strongest after RL, with the largest improvement among all protocols. On out-of-distribution book and subject splits, RL-trained self-learning outperforms the best fixed-retrieval baseline by a clear margin.
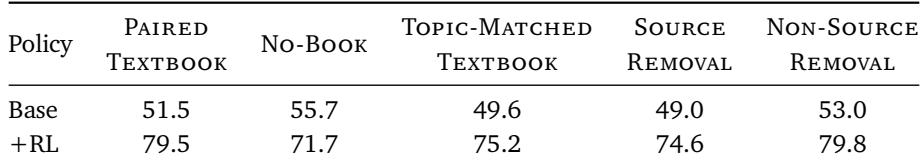
Self-Learning RL improves proof accuracy across all tested reference conditions, including a substantial gain when no textbook is available, indicating stronger unaided reasoning. The trained policy still performs better with textbook access than without it, and it maintains above-no-book accuracy when the book is swapped or source sections are removed. Removing source sections reduces accuracy more than removing comparable non-source sections, suggesting that performance depends on which content is available rather than simply on whether content is missing. RL improves accuracy in every reference condition, including the no-book setting. The trained policy performs better with the paired textbook than without it, so reference access continues to help beyond unaided reasoning. Accuracy remains above the no-book level with a topic-matched textbook or after source removal, pointing to flexible knowledge acquisition. Source removal causes a larger drop than removing non-source sections, indicating the location of removed material matters.
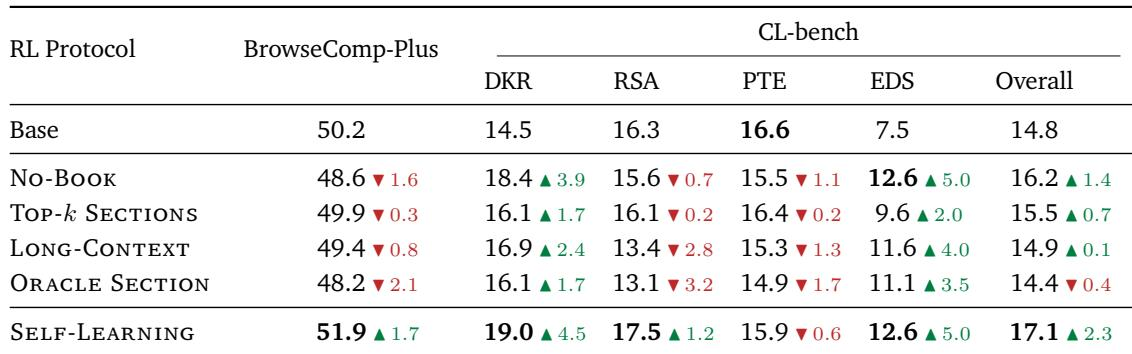
Self-Learning is the only evaluated protocol that improves over Base on both BrowseComp-Plus and overall CL-bench, with the largest overall CL-bench gain. Its advantage is selective, concentrated in Domain Knowledge Reasoning and Rule System Application, and it matches No-Book in Empirical Discovery and Simulation. However, all RL-trained policies underperform Base on Procedural Task Execution, and fixed-retrieval protocols tend to fall below Base on BrowseComp-Plus and below No-Book on CL-bench overall. Self-Learning achieves the highest BrowseComp-Plus and overall CL-bench scores among evaluated policies, improving over Base on both benchmarks. Fixed-retrieval protocols remain below Base on BrowseComp-Plus and below No-Book on CL-bench overall, suggesting limited cross-task generalization. Within CL-bench, Self-Learning leads in Domain Knowledge Reasoning and Rule System Application and ties No-Book in Empirical Discovery and Simulation. All RL-trained policies underperform Base in Procedural Task Execution, showing that transfer gains are selective.
Correctness-only reinforcement learning improves proof accuracy but sharply reduces tool use, and adding tool credit alone does not reverse that decline. Adding an annealed exploration bonus substantially increases tool-use trajectories and improves out-of-domain accuracy, while combining tool credit with the exploration bonus yields the strongest accuracy on every split. The results indicate process-level credit and exploration incentives play complementary roles in improving generalization. Correctness-only reinforcement learning raises overall proof accuracy but sharply reduces the proportion of tool-using trajectories and average tool calls. Adding tool credit improves in-domain book accuracy without requiring a stronger tool judge, yet leaves out-of-domain accuracy nearly unchanged. An exploration bonus markedly increases tool-use trajectories and improves out-of-domain accuracy, and combining it with tool credit achieves the best performance across all splits.
The experiments evaluate a self-learning RL protocol against fixed-retrieval and no-book baselines across proof accuracy, reference-condition perturbations, cross-task benchmarks, and reward-design ablations. Self-learning shifts from the weakest protocol before RL to the strongest after RL, improves accuracy in every reference condition including no-book and source-removal settings, and transfers best to out-of-distribution books and subjects. On broader benchmarks it achieves the highest BrowseComp-Plus and overall CL-bench scores with selective gains, though procedural task execution remains a weakness. Correctness-only RL raises accuracy but suppresses tool use, while combining tool credit with an annealed exploration bonus restores tool-using behavior and yields the strongest generalization.