Command Palette
Search for a command to run...
The Trinity: تحسين ذاتي تكراري مدفوع بالقدرات للوكلاء متعددي الوسائط
The Trinity: تحسين ذاتي تكراري مدفوع بالقدرات للوكلاء متعددي الوسائط
الملخص
يمكن النظر إلى الذكاء متعدد الوسائط بوصفه تطوراً مشتركاً موجهاً بشرياً بين العوالم والوكلاء عبر التفاعل. غير أن توسيع نطاق هذه العملية يواجه عائقين: بناء بيئات غير متجانسة وقابلة للتحقق مكلف، والتكرار اليدوي لمنظومات Harness لا يستطيع مجاراة التنوع والتعقيد المتزايدين للمهام. تتمثل إحدى الرؤى الأساسية في أن المهام ذات الوسائط والأشكال السطحية المختلفة قد تتقاسم المتطلبات الأساسية نفسها على مستوى القدرات. لذلك نقدم The Trinity، وهو إطار تحسين ذاتي تكراري يزاوج بين توليد العوالم وتطوير Harness عبر ثلاثة أدوار: Creator وExplorer وEvolver. وبالاعتماد على مسارات تنفيذ مُتحقق منها، ينقل Evolver أساس تنظيم المهام من الفئات السطحية إلى المتطلبات المشتركة، معيداً تنظيم شجرة المهام الأصلية إلى شجرة قدرات هرمية. نقدم Capability-Driven Real2Sim2Real؛ فبالنسبة إلى المهام غير المتجانسة في العقدة نفسها، يجرد Creator متطلباتها المشتركة في عوالم محاكاة مبسطة وقابلة للتحقق لتعلم القدرات، بينما يقيس التقييم على المهام الأصلية مدى انتقال التعلم. وعلى امتداد شجرة القدرات هذه، يطوّر Explorer تدريجياً وحدات قدرات قابلة لإعادة الاستخدام من خلال توريث انتقائي، مشكلاً شجرة Harness تتراكم تحديثاتها المُتحقق منها عبر التكرارات ضمن طوبولوجيا ثابتة. تتخصص منظومات Harness الناتجة في قدرات مختلفة، مما يحفز موجّه Harness واعياً بالقدرات (Capability-Aware Harness Router) يستخدم المعلومات العامة للمهمة لاختيار تكوينات وحدات متوافقة من الشجرة. وتحسّن منظومات Harness المطورة متوسط الأداء بمقدار 34 نقطة عبر 28 معياراً تدريبياً و26 نقطة عبر 18 معياراً غير مرئي، من بينها مهمتان واقعيتان مجسدتان.
One-sentence Summary
Researchers from Xidian University, Tongji University, National University of Singapore, UC Berkeley, and other institutions propose The Trinity, a recursive self-improvement framework that couples world generation with Harness evolution through the Creator, Explorer, and Evolver roles, reorganizing tasks into a hierarchical capability tree and applying Capability-Driven Real2Sim2Real with a Capability-Aware Harness Router to achieve 34-point mean gains on 28 training benchmarks and 26-point mean gains on 18 unseen benchmarks.
Key Contributions
- The paper introduces The Trinity, a recursive self-improvement framework that couples world generation with Harness evolution through Creator, Explorer, and Evolver roles and reorganizes heterogeneous tasks into a hierarchical capability tree based on shared requirements.
- The framework contributes Capability-Driven Real2Sim2Real, in which Creator abstracts common task requirements into simplified verifiable simulated worlds for capability learning while Explorer progressively evolves reusable capability modules through selective inheritance, forming a Harness tree with a Capability-Aware Harness Router for module selection.
- Experiments demonstrate that the evolved Harnesses improve mean performance by 34 points across 28 training benchmarks and 26 points across 18 unseen benchmarks, including transfer to two real-world embodied tasks.
Introduction
Multimodal foundation models now support agents that perceive, reason, and act across text, images, video, and audio, but scaling them to complex open-world tasks is limited by costly manual environment construction and hand-designed coordination logic. Prior recursive self-improvement largely targets text-only tasks and evolves task-specific harnesses, which can overfit and generalize poorly across heterogeneous multimodal tasks, while a single global harness often cannot satisfy conflicting capability demands. The authors argue for shifting from task-driven to capability-driven self-improvement, where tasks are grouped by shared underlying requirements such as perception and state tracking. They introduce The Trinity, a framework that couples environment generation with agent evolution through Creator, Explorer, and Evolver, building a hierarchical capability tree, generating simplified verifiable training worlds, and using capability-aware routing to select specialized harnesses for heterogeneous tasks and real-world transfer.
Dataset

The authors describe Evolver’s dataset and trajectory collection setup as follows:
- Sources and composition: Evolver normalizes public multimodal benchmarks into a common specification of goals, observations, actions, feedback, task-completion criteria, and budgets. Each normalized benchmark is independently checked against its original source. Benchmarks are grouped into five requirement domains: rule discovery, constrained problem solving, perception and control, multi-agent interaction, and long-horizon environments.
- Common interface: A shared observation-action interface preserves information access and scoring rules across different benchmarks.
- Split design: The training/unseen split is fixed before capability induction. Only training records support capability-tree construction, world generation, module learning, and Router training. Unseen capability requirements are used only for evaluation after the tree is fixed.
- Trajectory collection: Explorer collects trajectories from sampled training instances using the initial policy H0 under fixed settings. Instance selectors and initial-state hashes are fixed in advance.
- Run filtering and validation: Completed runs are retained. Diagnostic reruns reset memory. Infrastructure failures are marked invalid and retried. Hash-chain checks verify execution records.
- The provided excerpt does not include dataset sizes, mixture ratios, or cropping details.
Method
The authors introduce The Trinity, a framework that couples environment generation and Harness evolution with a frozen backbone. As shown in the figure below:
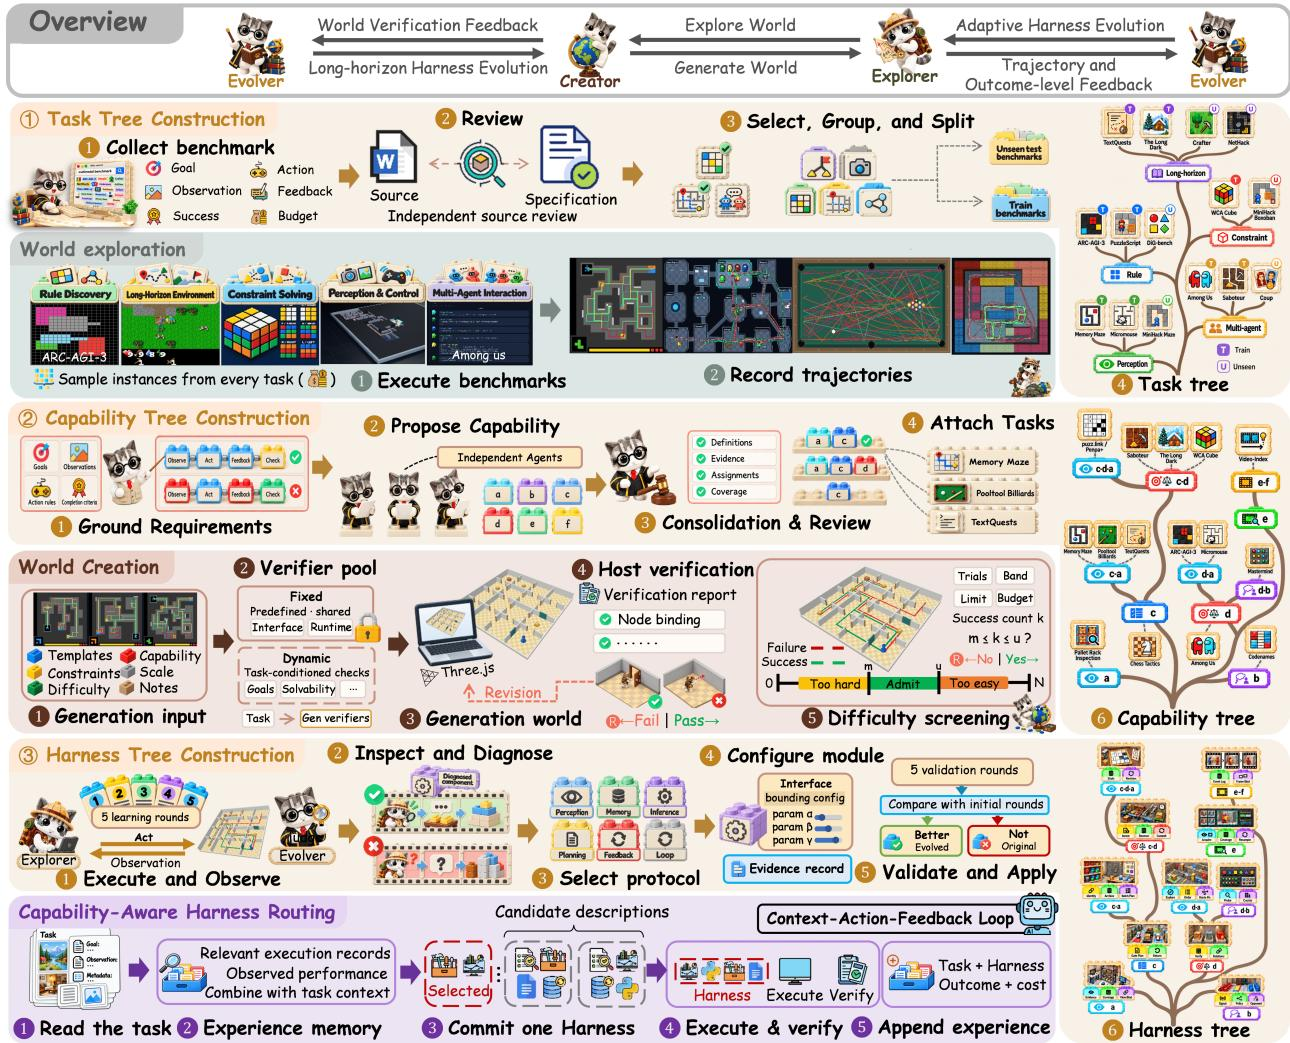
The system operates through three primary stages: Task Tree Construction, Capability Tree Construction, and Harness Tree Construction. Explorer collects trajectories, while Evolver organizes requirements from specifications and verified trajectories into a capability tree. Through Capability-Driven Real2Sim2Real, Creator builds simplified and verifiable worlds. Explorer selectively inherits and refines reusable modules, accumulating validated updates in a fixed-topology Harness tree. Finally, the Capability-Aware Harness Router selects a compatible branch using public task information and verified experience.
A Harness configuration ϕ coordinates a frozen model fθ through six control-flow protocols:
Hϕ=(Πer,M,I,P,F,L)Given a task τ, observation ot, public history ξ<t, controller state st, and available resources Cτ, the protocols function as follows. Perception extracts facts ft. Memory builds a history-conditioned view νt. Inference maintains compatible candidates. Planning ranks or prunes options into a directive dt. Orchestration identifies applicable resources. Loop resolves execution et and commitment ct. Modules are pure functions of supplied public records without hidden-state access.
Evolver normalizes public multimodal benchmarks into specifications of goals, observations, actions, feedback, and task-completion criteria. Explorer collects trajectories from sampled training instances using the base Harness H0. Evolver then derives requirements from task goals and links them to rules and trajectory steps. A deterministic capability order ≺ defines the paths and the tree structure:
pτ=sort≺(Kτ),T=Trie({pτ:τ∈Btr})The Trie merges common prefixes across domains. Once the capability tree is built, Creator designs simplified training levels from node requirements. Refer to the world creation examples:
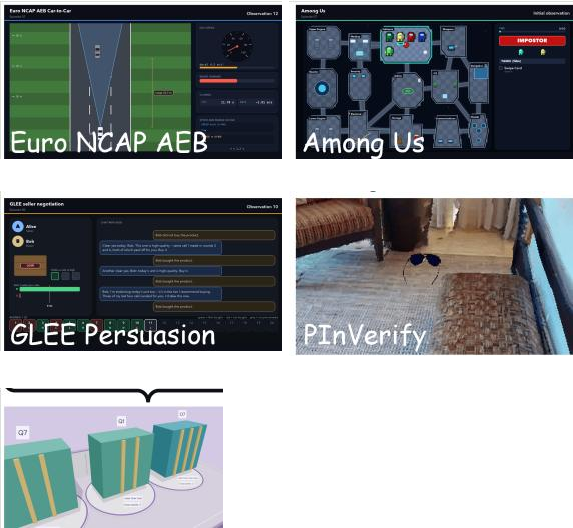
These generated worlds preserve core decision processes while excluding target-task layouts and private proofs. Evolver's host-executed verifier pool checks node binding, execution, state transitions, and completion.
For Explorer, capability-driven Recursive Self-Improvement builds a Harness tree aligned with the capability tree. At each node, Explorer executes admitted worlds with inherited and local modules. Evolver compares successful and failed trajectories to identify node-specific improvements. Selective inheritance is applied at non-root nodes. The Harness module configuration is defined as HE,ν(i)=Pν(i)⊕Lν(i), where registries use host-registered binding IDs and right-biased union:
(P⊕L)[m]={L[m],P[m],m∈dom(L),m∈dom(P)∖dom(L).Continual refinement updates the local modules based on Explorer's trajectories Zν(i+1):
Lν(i+1)=Evolve(Lν(i),Zν(i+1),Fν(i))At each iteration's end, Creator deduplicates and merges complementary updates into its next Base Harness. Validated revisions replace predecessors, distinct capabilities are retained, and partial overlaps are merged.
Routing follows a context-action-feedback loop. Let xn contain the public goal, initial observation, metadata, and images, and C⊆H(i) be the fixed Harness pool. Memory M0 is initialized by importing verified training-side categorization trajectories. For each task, candidate descriptions, retrieved experience, and observed performance-cost summaries guide selection:
hn=π(xn,C,R(xn,Mn),S(Mn))The agent commits hn with an evidence-based rationale before execution. After terminal receipts are verified, outcome and cost fn update memory for later tasks:
Mn+1=Append(Mn,(xn,hn,fn))Experiment
The evaluation uses 28 training and 18 unseen benchmarks with a frozen Claude Opus 5 backbone, preparing skills over five trials per benchmark-harness pair and holding those skills fixed for evaluation. Experiments show that capability-driven organization improves over flat and task-domain groupings, especially when simulated worlds preserve task decision processes. Recursive self-improvement yields sustained gains across iterations, capability-aware routing lets an agent select suitable harnesses, and capability-module analyses confirm that relevant module additions help while removals hurt. Embodied transfer tests further show that capability-evolved harnesses improve simulated and real-robot performance on SOON and CaP-X tasks.
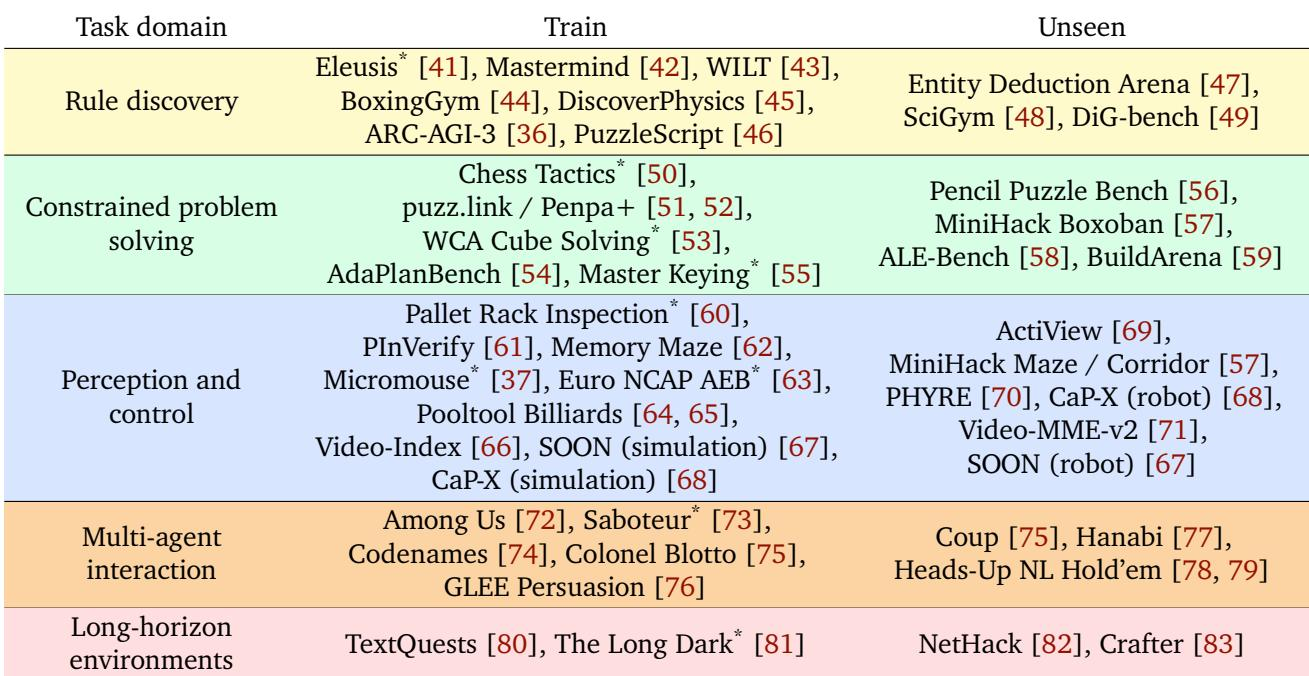
The benchmark suite spans five task domains: rule discovery, constrained problem solving, perception and control, multi-agent interaction, and long-horizon environments. It includes 28 training benchmarks and 18 unseen benchmarks, where training uses fixed representative instances over multiple episodes and unseen uses official or fixed official evaluation sets. Several training tasks are agent-built from web-searched sources. Training and unseen benchmarks both cover all five task domains, from rule discovery to long-horizon environments. Unseen evaluation includes diverse tasks such as NetHack, Crafter, MiniHack Maze, PHYRE, and Heads-Up NL Hold'em. Several training benchmarks are agent-built from web-searched sources, including tasks in rule discovery, constrained problem solving, and perception and control.
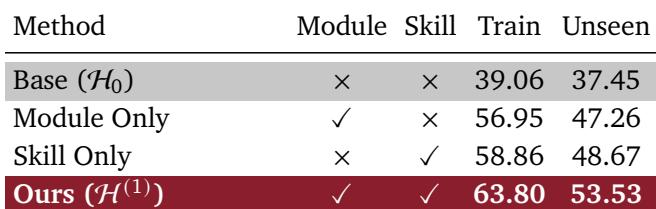
Adding evolved modules or skills alone improves over a base harness on both training and unseen evaluations. Combining evolved modules with skills yields the strongest results, indicating that the two contributions are complementary. Evolving modules alone and adding skills alone each outperform the base harness on train and unseen settings. Combining evolved modules with skills achieves the best train and unseen performance, outperforming either intervention alone.
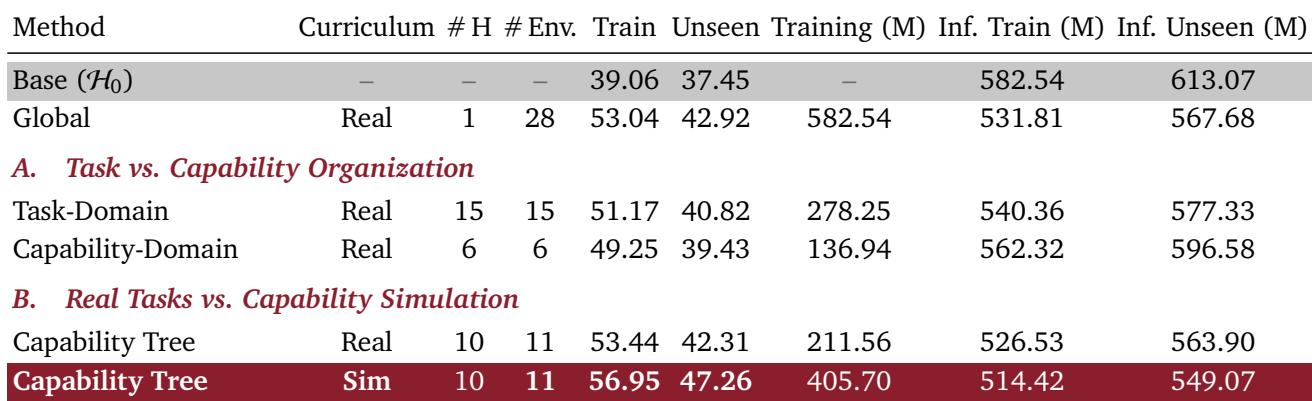
Across module-only evaluations, sharing experience through a global harness improves over task-domain and flat capability-domain organizations, while the real capability tree adds gains over flat grouping via selective inheritance. The simulated capability tree reaches the strongest train and unseen performance and the lowest inference token cost, though its first-iteration training cost is higher than the real tree and task-domain alternatives. Flat capability grouping has the lowest training cost but underperforms global experience sharing on both train and unseen evaluations. The real capability tree improves over flat capability grouping by using shared capability prefixes and selective parent inheritance. The simulated capability tree achieves the best module-only train and unseen scores and the lowest inference token counts, while requiring more first-iteration training tokens than the real tree and task-domain organization.
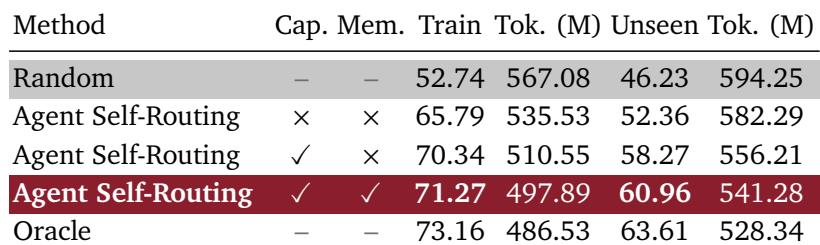
Self-routing improves over random routing on both train and unseen splits, and adding capability definitions and retrieved execution experience further improves performance while lowering estimated inference tokens. The full self-routing configuration approaches oracle performance. Random routing produces the lowest scores and highest token estimates. Adding capability definitions and retrieved execution experience to agent self-routing improves both splits and reduces token costs. The full self-routing configuration approaches oracle performance.
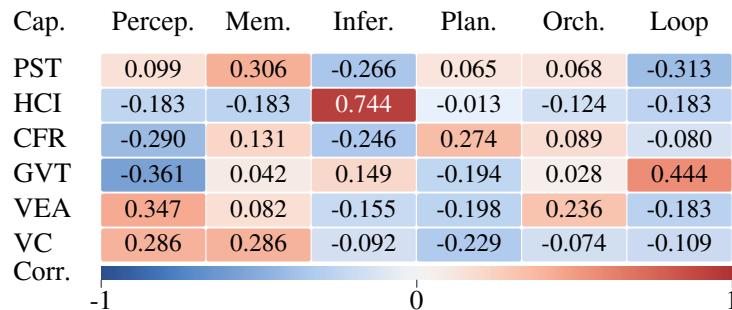
Across the six protocols, capability associations are uneven: inference is strongly positively associated with HCI, loop coordination with GVT, and perception with VEA and VC, while PST shows positive memory and negative inference and loop correlations. Controlled module edits show relevant additions yield much larger performance gains than irrelevant additions, and removing a relevant module lowers performance while increasing token usage. HCI has a strong positive correlation with inference and negative correlations with perception, memory, and loop capabilities. GVT is associated with loop coordination, while VEA and VC are more associated with perception. Relevant module additions raise performance far more than irrelevant additions; removing a relevant module lowers performance and increases token usage.
The evaluation uses a benchmark suite spanning five task domains with 28 training and 18 unseen benchmarks to test modular skill evolution and routing. Combining evolved modules with skills yields the strongest results, and module-only performance benefits from global experience sharing and capability-tree organization, with a simulated capability tree lowering inference token costs despite higher initial training cost. Self-routing with capability definitions and retrieved execution experience further improves scores while reducing token estimates, approaching oracle performance. Analyses also show uneven but meaningful capability-task associations, where adding relevant modules produces much larger gains than irrelevant additions and removing a relevant module lowers performance and increases token usage.