Command Palette
Search for a command to run...
InteractiveWorld: بيئة قابلة للتحقق محورها الإنسان لبناء مساعدين تفاعليين أفضل قائمين على نماذج اللغة الكبيرة متعددة الوسائط (MLLMs)
InteractiveWorld: بيئة قابلة للتحقق محورها الإنسان لبناء مساعدين تفاعليين أفضل قائمين على نماذج اللغة الكبيرة متعددة الوسائط (MLLMs)
Qinsi Wang Wei Wen Chong Zhou Saksham Suri Zechun Liu Lemeng Wu Hai Helen Li Yiran Chen Raghuraman Krishnamoorthi Qi Qian
الملخص
لطالما حلم الناس بمساعدٍ يكون حاضرًا دائمًا لإرشادهم وتذكيرهم بما ينسونه، من أطباق جديدة إلى مفاتيح ضائعة. وبفضل نماذج اللغة الكبيرة متعددة الوسائط (MLLMs)، أصبحت المساعدات الذكية المتمركزة حول الذات على الأجهزة القابلة للارتداء تقرّب هذا الحلم من التحقق: فهي ترى ما يراه المستخدم وتقدم تعليمات للعمل البدني للمستخدم عند الحاجة. غير أن اختبار هذا النوع من المساعدة ما يزال صعبًا ويتطلب عادةً أشخاصًا حقيقيين. كما أن بيانات التفاعل الحقيقي الباهظة والنادرة تترك سؤالًا جوهريًا دون إجابة: هل تستطيع نماذج MLLM الحالية مساعدة الناس فعلًا في العالم المادي؟ للإجابة عن هذا السؤال، نقترح InteractiveWorld، أول بيئة قابلة للتحقق للتفاعل ذي الحلقة المغلقة بين الإنسان والمساعد الذكي. وخلافًا للمحاكيات الحالية المتمركزة حول الروبوت، تتيح InteractiveWorld للمساعد توجيه وكيل بشري يلاحظ المشهد ويفهم التعليمات ويتصرف بشكل مستقل. وهي بذلك تحاكي واقعيًا كيفية تعاون المساعد الذكي مع الإنسان: المساعد يوجّه، والإنسان ينفّذ، والبيئة تنفّذ الأفعال وتحدّث ما يرونه بعد ذلك. وبناءً عليها، نقدم InteractiveBench، أول معيار ديناميكي للمساعدات الذكية المتمركزة حول الذات، ويتضمن 120 مهمة متعددة الأدوار عبر ست فئات. في كل مهمة، يوجه المساعد الإنسان في الزمن الفعلي، وكل تعليمة تؤثر في النتيجة التي تُقيَّم بمكافآت قابلة للتحقق ومبنية على الحالة. تُظهر التجارب على 12 نموذجًا رائدًا من نماذج MLLM أنها ما تزال بعيدة عن أن تكون مساعدات موثوقة. فحتى أقوى نموذج، Claude Fable 5.1، لا يحقق سوى 20% و25% على الترتيب في مهمتي التوجيه والتخطيط طويلتي الأفق. إجمالًا، يقدم عملنا منصة قابلة للتحقق ومجموعة تقييم صارمة، ما يرسي أساسًا متينًا للبحث في مساعدين تفاعليين قائمين على نماذج MLLM يساعدون الناس فعلًا في العالم المادي.
One-sentence Summary
Researchers from Meta and Duke University propose InteractiveWorld, the first verifiable closed-loop environment for human-AI assistant interaction in which, unlike robot-centric simulators, the assistant guides a human agent and the environment executes actions, and InteractiveBench, a dynamic 120-task benchmark with state-based rewards; experiments show that 12 frontier MLLMs, including Claude Fable 5.1, achieve at most 20% and 25% on long-horizon Guidance and Planning tasks, respectively.
Key Contributions
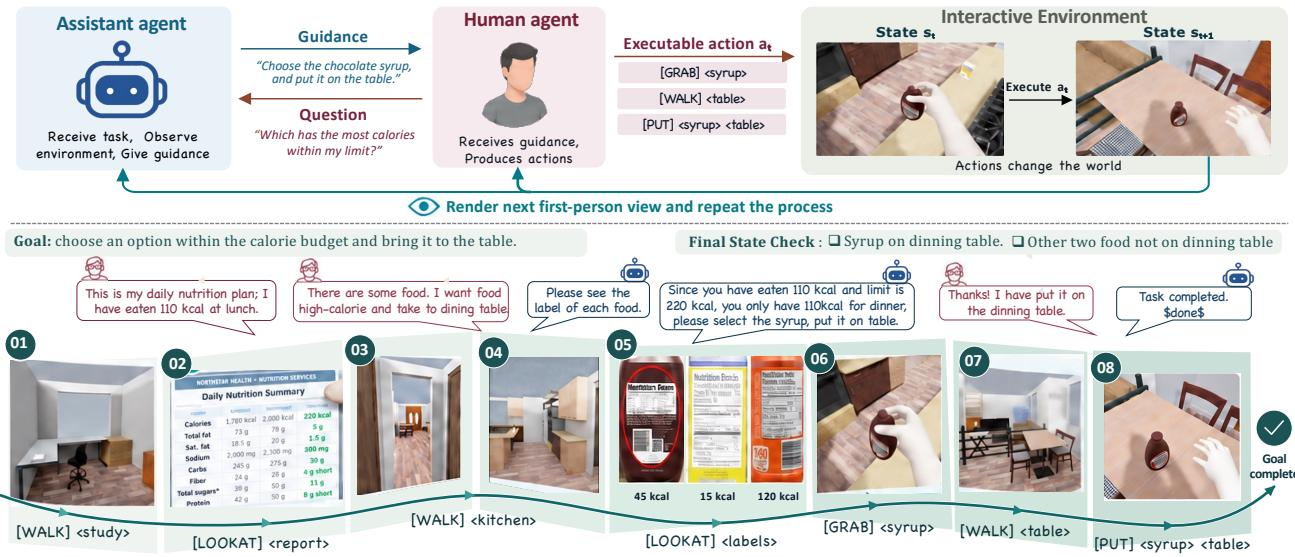
- The paper presents InteractiveWorld, the first verifiable human-centric closed-loop interaction environment, built on Isaac Sim with over 8,000 objects and 50 scenes. In this environment, an assistant’s natural-language guidance drives a human agent’s actions and updates the egocentric view, enabling realistic simulation of human-assistant collaboration.
- The paper introduces InteractiveBench, the first closed-loop dynamic benchmark for egocentric AI assistants, comprising 120 human-reviewed multi-turn tasks across six categories. Assistant outputs shape task outcomes, and success is measured by verifiable state-based rewards.
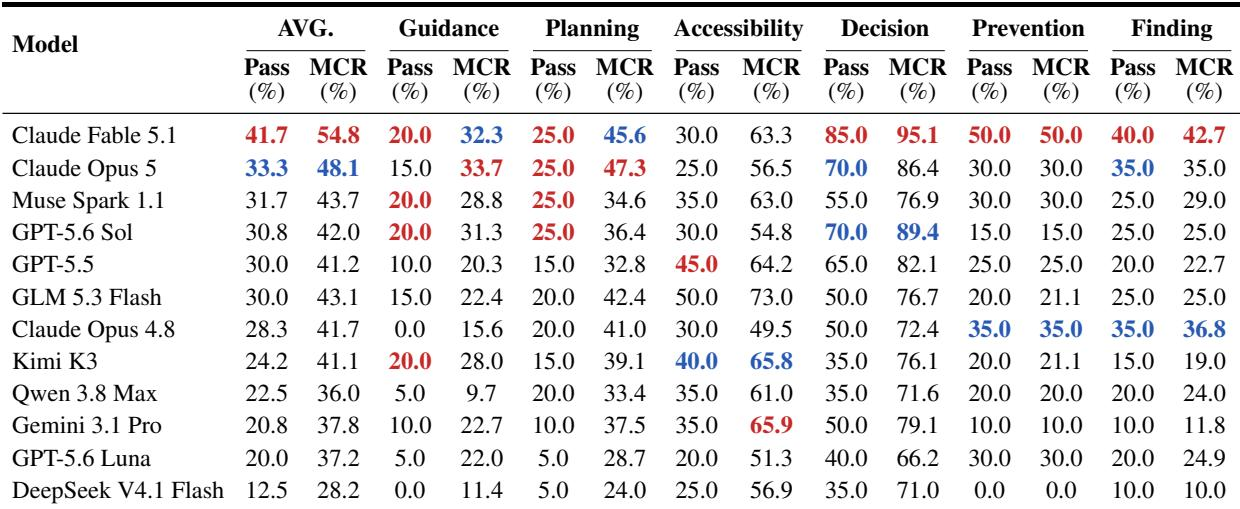
- Experiments with 12 frontier MLLMs show current models remain far from reliable assistants. The strongest model, Claude Fable 5.1, succeeds on 41.7% of tasks while all others stay at or below 33.3%; the best Guidance and Planning scores are 20.0% and 25.0%, and analyses identify perception, memory, and communication as key bottlenecks.
Introduction
Egocentric AI assistants running on wearable devices share a user’s first-person view and guide actions through natural language, and advances in multimodal large language models make this a practical approach for helping people with physical tasks. However, evaluation has been limited by costly real-world studies and by static benchmarks where models watch pre-recorded video without changing it, which cannot test closed-loop adaptation or compositional interaction skills. The authors propose InteractiveWorld, a verifiable closed-loop environment built on Isaac Sim with over 8,000 objects and 50 scenes, where assistant guidance changes a simulated human agent’s actions and the resulting first-person view. They also introduce InteractiveBench, a benchmark of 120 human-reviewed multi-turn tasks across six categories with state-based success checks, and show that frontier MLLMs still succeed on at most 41.7% of tasks, with major gaps in long-horizon guidance and planning.
Dataset

Dataset composition and sources
- InteractiveBench is built on InteractiveWorld and is described as the first closed-loop interactive benchmark for egocentric AI assistants.
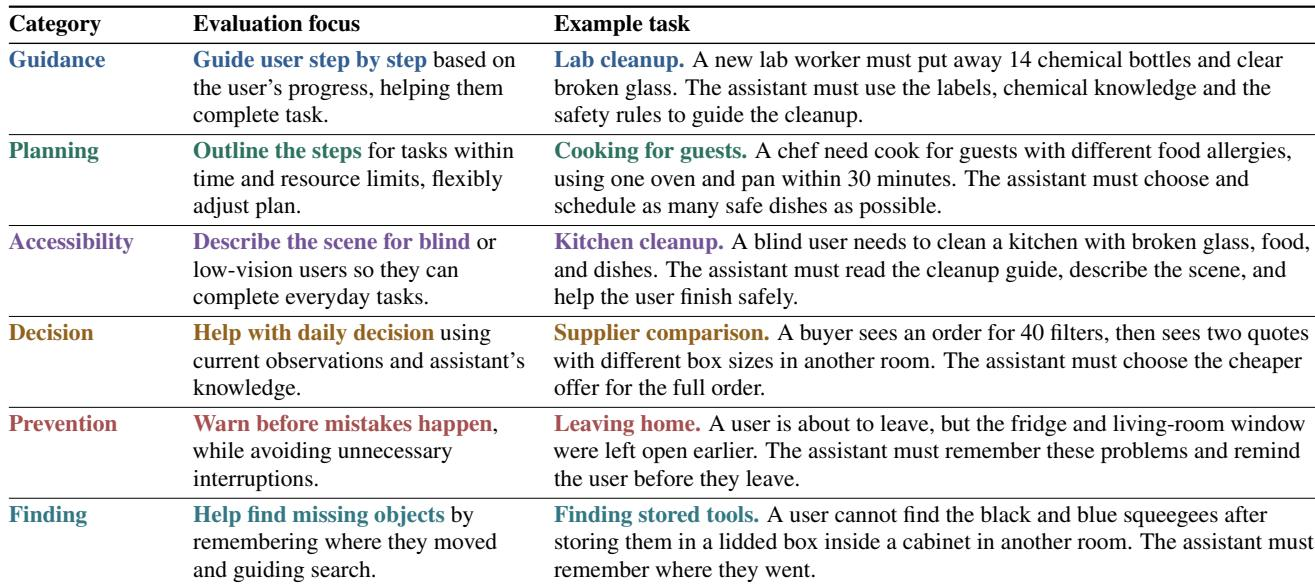
- It contains 120 tasks across six categories: Guidance, Planning, Accessibility, Decision, Prevention, and Finding.
- All tasks are human-reviewed and filtered by three rules: the task targets a realistic assistance need, the Assistant must use first-person information for multi-turn observation, memory, reasoning, or planning, and outcomes must be verifiable from defined environment states.
Subset details
- The benchmark has six task categories, but the text reports only the total of 120 tasks rather than per-category sizes or separate source-specific splits.
- Each task includes an initial scene with scene layout, human starting position, and locations/states of target and distractor objects.
- Each task also defines a pre-interaction warmup with predefined human actions and opening context.
- Scoring relies on predefined core states, such as "the pizza is in the oven" or "the fridge is closed"; success requires all core states to be met.
How the data is used
- The target model acts as the Assistant agent, and an auxiliary model acts as the Human agent.
- The Human agent has access to valid commands and can perform actions, but is instructed to follow the Assistant's guidance.
- The Assistant uses the egocentric view and conversation history and may stay silent, provide guidance, or end the task.
- During closed-loop interaction, keyframes sampled during actions are added to visual input.
- The benchmark is used for evaluation rather than training. No training split, mixture ratio, cropping strategy, or extra metadata construction is described.
Method
The authors introduce InteractiveWorld, a human-centric interaction environment designed to simulate realistic collaboration between a human and an AI assistant. To address the paradigm shift from robot-centric control to natural language guidance, the system is structured into three distinct layers: the Physical Layer, the Human Action Layer, and the Semantic Layer.
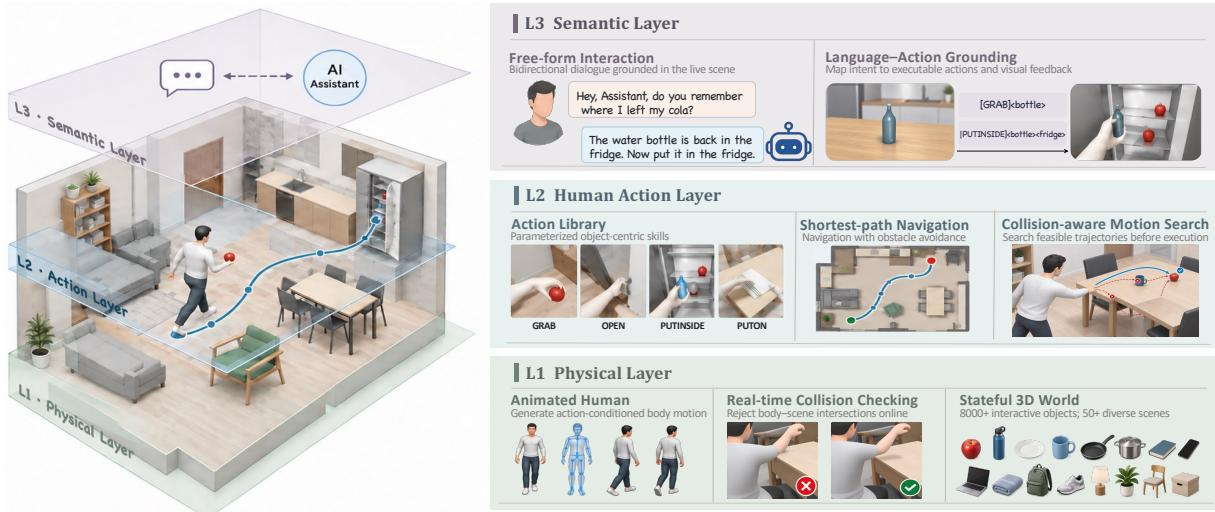
The Physical Layer serves as the foundational 3D environment, providing realistic human models, diverse assets, and a physics engine. The authors utilize the SMPL+H model to represent the full body and hands, placing a camera on the head to capture a first-person visual perspective. To ensure stable and deterministic execution, the human model is driven kinematically. The system also incorporates real-time collision checking to prevent severe intersections between the human model and the environment, automatically correcting minor collisions or rejecting unsafe actions. Furthermore, the layer supports a rich and scalable asset library, including thousands of interactive objects and diverse scene layouts.
Building upon this physical foundation, the Human Action Layer enables the human model to perform high-level daily actions autonomously. The execution process is divided into two main stages. First, the system performs collision-aware auto-navigation by identifying a reachable standing position and planning a safe path using A* search to avoid obstacles. Second, it executes target-driven adaptive manipulation, where the system adapts the human posture and plans a collision-free arm trajectory based on the object shape and functional parts. If a feasible trajectory is not found, the system automatically replans the standing position.
The Semantic Layer connects natural language guidance to executable human behaviors, enabling the AI assistant to guide the human via dialogue rather than direct simulator control. The authors define a unified action interface comprising 36 executable action primitives that cover navigation, observation, and manipulation. Commands specify only the actions and targets, which are then translated into goals for the Human Action Layer. During interaction, the system forms a continuous observe-guide-execute loop. The assistant provides natural-language guidance based on the human first-person view, the human interprets this guidance to execute actions, and the simulator updates the environment state. By tracking actual object positions and states throughout the interaction, the system can automatically verify task success based on final object relationships.
Experiment
The evaluation benchmarks twelve frontier multimodal models as assistants on InteractiveBench with a fixed simulated human agent, assessing task success, efficiency, capability, failure modes, and sensitivity to task length. The results indicate that closed-loop egocentric assistance is far from solved, as even the strongest model helps complete fewer than half of the tasks, with perception and memory errors, weak long-horizon tracking and replanning, and unclear communication being major failure sources. Models also cause considerable action redundancy compared to an oracle assistant, and performance degrades on longer tasks. Ablations show that inference-time memory augmentation produces mixed improvements, while assistant rankings remain relatively stable across different human agents, though the human model choice can affect performance.
InteractiveBench defines six egocentric assistance task categories: Guidance, Planning, Accessibility, Decision, Prevention, and Finding, each connected to realistic multi-turn scenarios and verifiable outcomes. Evaluations show that assistant efficiency varies strongly by category, simple memory augmentation helps primarily in Prevention and Finding but is mixed elsewhere, and performance depends on the human agent model. Proactive information-seeking behaviors also emerge as assistants ask humans to move, inspect, or look around to reveal missing information. The benchmark spans six categories that emphasize step-by-step guidance, planning under constraints, accessibility without visual input for the human, decision support, mistake prevention, and memory-based finding. Efficiency and reliability are uneven across categories: an assistant can be highly efficient on Prevention but least efficient on Accessibility, while another can match oracle-level efficiency on Finding but incur the highest cost on Guidance.
Across the six evaluated task categories, no current multimodal assistant completes a majority of tasks: the strongest model falls below one-half average pass rate and all others remain at or below one-third. Decision tasks show comparatively strong completion and mean completion rates, whereas Guidance and Planning tasks are consistently weak, with low pass rates and partial objective completion. This pattern supports the finding that current models can make effective one-shot decisions but struggle to sustain progress tracking and re-planning over longer interactions. Decision is the strongest task category across most models, while Guidance and Planning show the lowest pass rates and mean completion rates. Mean completion rate often exceeds pass rate, particularly in Accessibility and Planning, indicating partial objective completion is common even when tasks are not fully solved. All models remain far below the verified oracle-assisted human baseline of full task completion, with the best assistant still failing to finish more than half of tasks.
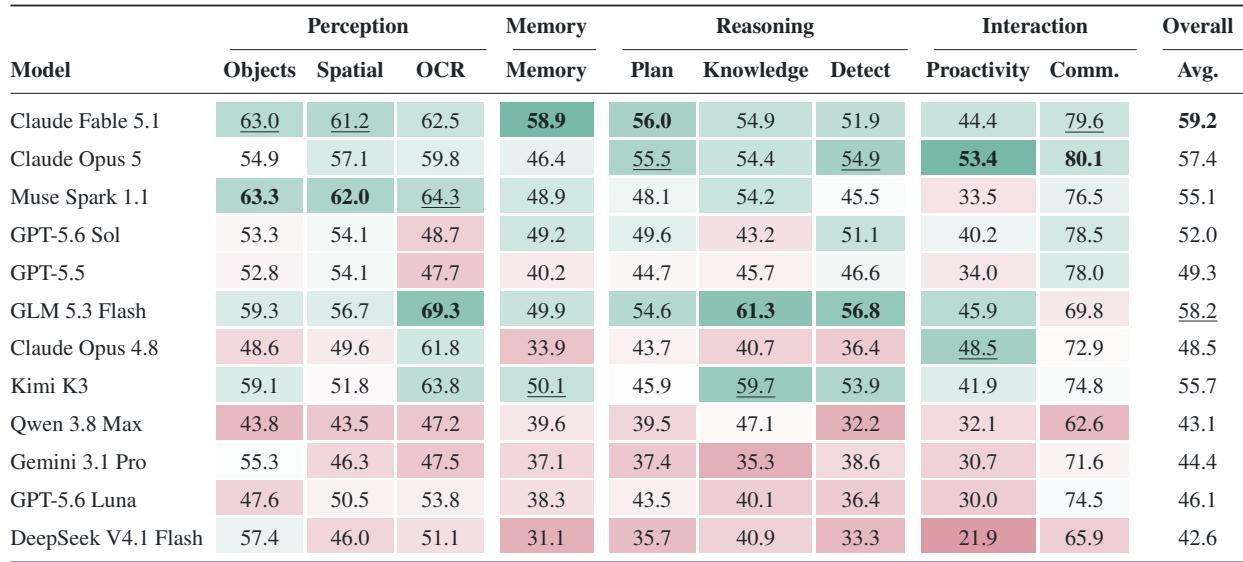
Across the nine capability checks, communication is the strongest area for every evaluated model, while long-horizon memory and proactivity are weaker and more inconsistent. Claude Fable 5.1 achieves the highest average capability score, though relative strengths vary by model. These patterns are consistent with the broader observation that sustained tracking and re-planning remain difficult. Communication is the highest-scoring capability for all models, whereas long-horizon memory and proactivity are generally lower and more variable. Claude Fable 5.1 leads the average capability score and is comparatively strong in long-horizon memory and planning. GLM 5.3 Flash shows notable strength in OCR, knowledge, and error detection, but its communication score is the lowest among the compared models.
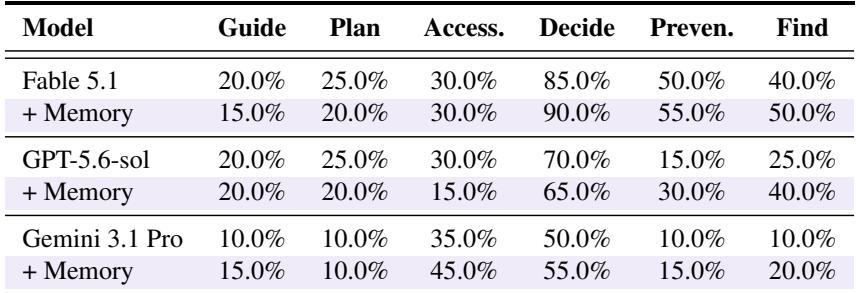
Memory augmentation consistently improves Prevention and Finding, but its benefits are uneven across other skills and Planning declines for two models. Human-agent pairing results show stable assistant rankings, with Fable 5.1 leading and GPT-5.6 trailing, while Gemini 3.1 Pro as the human agent yields the strongest observed performance for all assistants. Memory augmentation improves Prevention and Finding across all three models, but Planning drops for two models and other tasks show model-dependent changes. Fable 5.1 is the strongest assistant across human pairings, GPT-5.6 is the weakest, and all assistants achieve their highest observed MCR when Gemini 3.1 Pro acts as the human agent. Simple inference-time memory is insufficient for reliable long-horizon assistance because its gains are concentrated in a subset of tasks.
InteractiveBench evaluates multimodal assistants across six egocentric assistance categories using multi-turn tasks and human-agent pairings. The experiments show that no assistant completes a majority of tasks, with performance uneven by category: decision support is strongest, guidance and planning are weakest, and partial completion is common. Capability checks indicate communication is consistently strong while long-horizon memory and proactivity are weak, and simple memory augmentation mainly helps prevention and finding rather than providing reliable long-horizon assistance. Assistant rankings remain stable across human agents, with the strongest model still far below oracle-assisted human completion.