Command Palette
Search for a command to run...
RSIHub: إطار عمل قابل للتركيب لأساليب تطور الوكلاء
RSIHub: إطار عمل قابل للتركيب لأساليب تطور الوكلاء
الملخص
تستخدم أساليب تطور الوكلاء التغذية الراجعة من التنفيذ لتحسين التلقينات والمهارات والأدوات والتنسيق، لكن تنفيذاتها غالبًا ما تعيد بناء البنية التجريبية نفسها. نقدم RSIHub، وهو إطار عمل مفتوح المصدر لبناء هذه الأساليب ومقارنتها وتوسيعها على بنية تحتية مشتركة. تركّب الوصفات مشغّلات قابلة لإعادة الاستخدام وتصرّح بموارد قابلة للتعديل؛ ويوفر RSIHub التنفيذ والتقييم والتعافي وتتبع النسب. يمكن للباحثين التركيز على سياسة التطور بينما يبقى التقييم خارج النطاق القابل للتعديل وتبقى النتائج مرتبطة بالمرشحين وشروط التقييم. ننشئ AHE وHyperagents وA-Evolve وGEPA دون تعديل نواة إطار العمل، مع إبقاء المنطق الخاص بكل أسلوب في الوصفات والمشغّلات. نقيّمها باستخدام MiniSWE وCodex على Terminal Bench 2 وτ³ Banking تحت إعدادات نموذج ومقيّم ثابتة. أكبر تحسن إجمالي ملحوظ في pass@1 هو 13.5 نقطة مئوية، بينما تتباين ترتيبات الأساليب عبر الإعدادات ولا تنتقل مكاسب التحسين دائمًا إلى المهام المحجوزة. يوفر RSIHub بروتوكولًا مشتركًا لمقارنة سياسات التطور، وسجلات مرشحين قابلة للفحص، ومكونات قابلة لإعادة الاستخدام لتطوير أساليب جديدة.
One-sentence Summary
Researchers from University of California, Berkeley and collaborators present RSIHub, an open-source composable framework for agent-evolution methods in which recipes compose reusable operators and shared infrastructure handles execution, evaluation, recovery, and lineage, allowing AHE, Hyperagents, A-Evolve, and GEPA to be instantiated without modifying the framework core and yielding up to a 13.5 percentage-point pass@1 gain on Terminal Bench 2 and τ³ Banking, though rankings vary and gains may not transfer.
Key Contributions
- The paper introduces RSIHub, an open-source framework that provides shared execution, evaluation, recovery, and lineage for agent-evolution methods while keeping evaluation outside the mutable optimization surface.
- The framework represents methods as recipes of reusable operators and mutable resources, and the paper demonstrates its generality by instantiating AHE, Hyperagents, A-Evolve, and GEPA without modifying the core framework.
- Experiments with MiniSWE and Codex on Terminal Bench 2 and τ³ Banking under fixed model and evaluator configurations show a largest overall pass@1 gain of 13.5 percentage points, with method rankings varying across settings and gains not always transferring to held-out tasks.
Introduction
Language-model agent development is commonly driven by an empirical loop in which developers inspect executions, revise prompts, skills, tools, or orchestration, and reevaluate behavior. Agent-evolution and program-optimization systems automate parts of this loop, but prior implementations often bundle method policy with recurring infrastructure such as candidate workspaces, task execution, evaluation, artifact retention, recovery, and lineage. As a result, implementing a new method can require building another end-to-end system, and comparing methods requires reconciling runners, configurations, and evaluator interfaces. The authors introduce RSIHub, a composable framework that separates method policy from this shared infrastructure via recipes binding lifecycle operators, declaring the mutable surface, and specifying run configuration, while a protected runtime and verified archive keep evaluation and record keeping under framework control. They express AHE, Hyperagents, A-Evolve, and GEPA as recipes and compare them across two seed agents and two benchmarks under fixed model and evaluator configurations.
Method
The authors introduce RSIHub, a composable framework designed to decouple method-specific policy from the recurring infrastructure of candidate execution, evaluation, and record keeping. By fixing the slots of the evolution lifecycle and leaving their contents open, researchers can assemble evolution methods from interchangeable parts. A recipe specifies the operator implementation for each slot and configures it, while explicitly declaring the mutable surface, which defines the resources a candidate is permitted to change. This separation ensures that framework-managed services, such as workspace construction and lineage bookkeeping, are implemented once and reused across different methods.
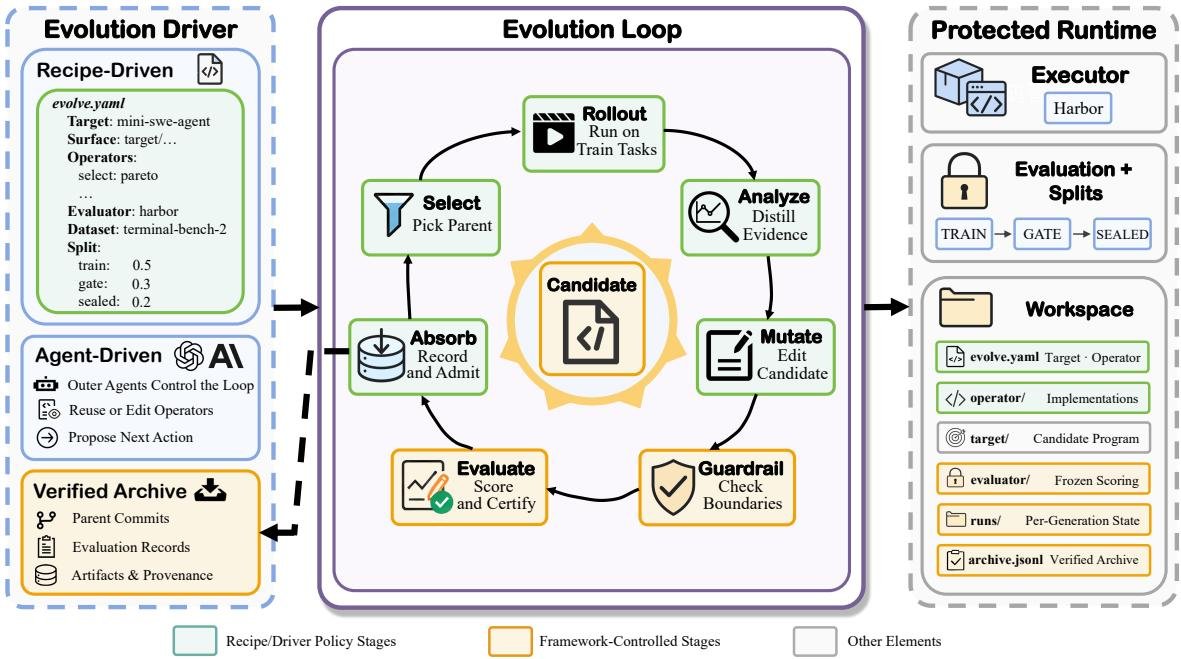
As shown in the framework diagram, the system architecture is divided into three primary components: the Evolution Driver, the Evolution Loop, and the Protected Runtime.
The Evolution Driver manages the recipe configuration, which can be either researcher-authored and fixed, or dynamically revised by an outer agent. The Protected Runtime provides the underlying substrate for container execution via Harbor, manages evaluation splits, and enforces the mutable surface boundaries. Crucially, the framework retains strict control over evaluation and scoring to prevent method-controlled changes from altering measurement conditions.
The core of the framework is the composable candidate lifecycle, which progresses through seven distinct phases. Across these phases, recipes bind five required operator interfaces: Select, Rollout, Mutate, Gate, and Record, along with four optional interfaces: Analyze, Validate, Novelty, and Reflect.
The lifecycle begins with the Select phase, where an eligible parent is chosen from the verified archive. Next, the Rollout phase executes the parent on training tasks to gather execution evidence. The optional Analyze phase then distills this evidence into bounded mutation data. In the Mutate phase, an operator, typically an agent, proposes edits strictly within the declared mutable surface. Following this, the Guardrail phase checks the proposed changes against the mutable surface boundaries and may apply optional validation or novelty checks to filter out near-duplicates.
The Evaluate phase is entirely framework-managed. It commits the reviewed candidate, scores it on gate tasks, and certifies the result, ensuring that sealed tasks remain reserved for held-out reporting. Finally, the Absorb phase determines whether the child becomes a parent based on the certified score, records method-specific annotations, and optionally reflects on archive history for future generations.
To maintain experimental integrity, the framework operates in either a recipe-driven mode, where the recipe remains fixed, or an agent-driven mode, where an outer agent adapts operator bindings and policy settings between iterations. In both modes, the target, evaluator, runtime, and data splits remain fixed. The system generates a certified evaluation event that cryptographically ties the committed candidate, its parent, and the active recipe snapshot to evaluator fingerprints and trial outcomes. This provenance model allows researchers to isolate specific policy components and investigate stalled progress without rebuilding the underlying experimental infrastructure.
Experiment
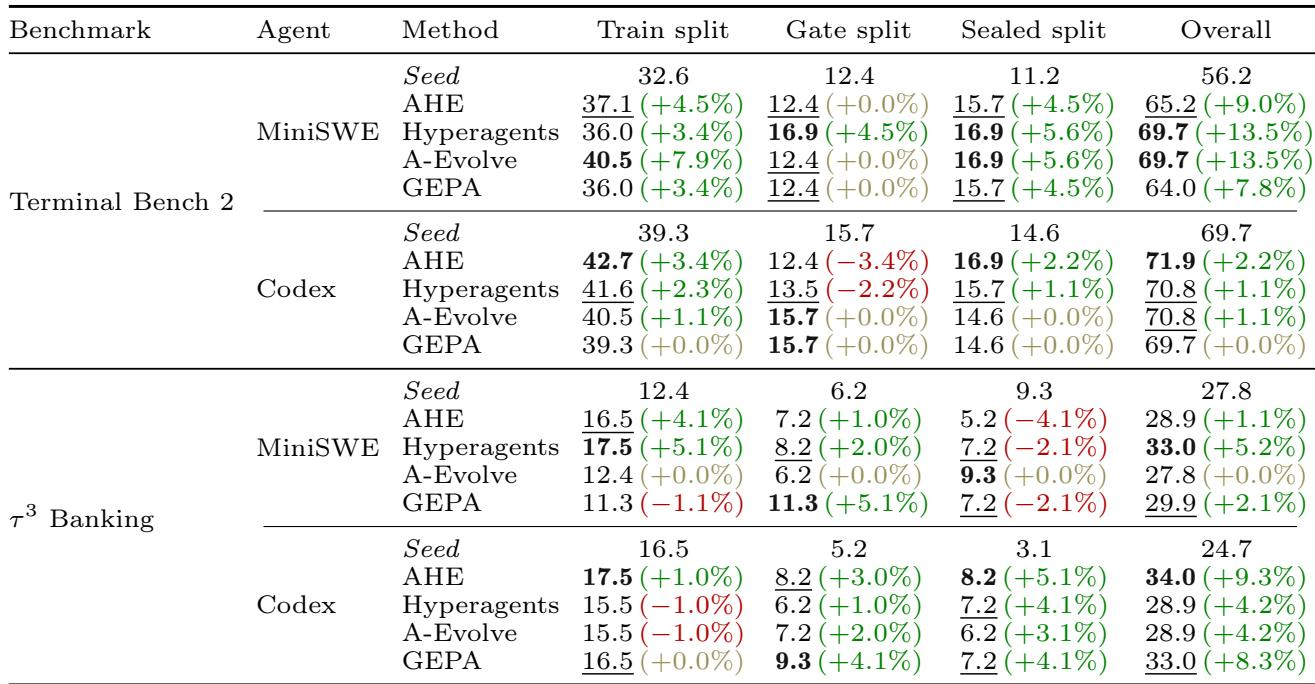
The evaluation addresses three questions: whether RSIHub supports effective agent evolution, preserves executed agents' capabilities, and maintains experiment integrity. It compares four adapted recipes and a hill-climbing baseline across MiniSWE and Codex on Terminal Bench 2 and τ³ Banking, finding setting-dependent gains with some held-out regressions despite overall improvements. Framework-mediated execution shows score changes within direct-execution variability, and recovery and fault-injection trials all reached valid, attributable states without admitting corrupted results.
On Terminal Bench 2, evolution improved MiniSWE pass@1 over its seed across all reported methods, mainly through train and sealed split contributions. Codex showed a smaller overall improvement for the reported AHE variant, with train and sealed gains partly offset by a lower gate contribution. Improvements varied across methods and splits, indicating gains did not transfer uniformly. For MiniSWE, all reported evolution methods improved overall pass@1 over the seed, with Hyperagents and A-Evolve reaching the highest overall scores among evolved MiniSWE variants. For MiniSWE, train and sealed split contributions drove most gains, with the gate split improving only for Hyperagents among the reported evolution methods. For Codex, the reported AHE variant improved train and sealed split contributions but reduced the gate split contribution, yielding only a modest overall gain.
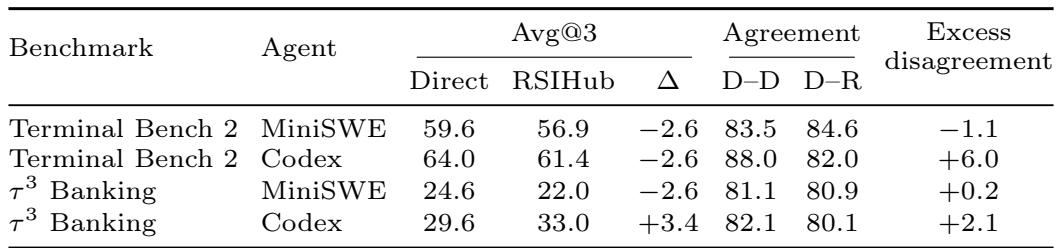
Across three repetitions, RSIHub execution changed mean pass@1 by only a few points relative to direct execution, with both agents declining on Terminal Bench 2 and mixed direction on τ^3 Banking. Repeated direct runs also showed task-level disagreement, and excess disagreement with RSIHub varied by agent and benchmark, with Codex showing the largest increase on Terminal Bench 2. These results describe execution variability and do not establish execution-mode equivalence. On Terminal Bench 2, both MiniSWE and Codex scored 2.6 points lower under RSIHub than in direct execution. On τ^3 Banking, MiniSWE declined slightly under RSIHub, while Codex improved, so the direction was not uniform. Repeated direct executions disagreed on 12.0 to 18.9 percent of tasks, indicating baseline variability separate from RSIHub. Codex showed larger excess disagreement under RSIHub than MiniSWE, especially on Terminal Bench 2.
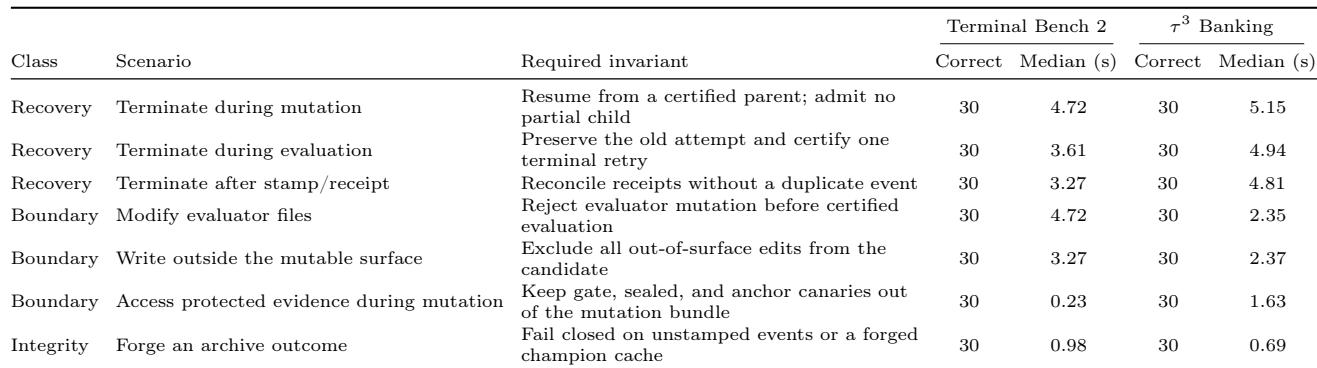
Across all reported fault-injection and boundary-enforcement runs, every scenario achieved a perfect correct-outcome record and no trial admitted corrupted state. Recovery scenarios showed substantial median latencies, while boundary scenarios varied, with protected-evidence access during mutation being the fastest in both benchmark campaigns. These results support integrity only within the tested lifecycle boundaries and attack cases. Every fault-injection and boundary scenario achieved perfect correct outcomes across both benchmark campaigns. No trial admitted corrupted state in any reported recovery or boundary-enforcement run. Protected-evidence access during mutation had the lowest median latency in both benchmarks, while banking boundary scenarios were generally faster than recovery scenarios.
The experiments evaluate evolved agent variants on Terminal Bench 2, execution variability under RSIHub on Terminal Bench 2 and τ^3 Banking, and correctness under fault-injection and boundary-enforcement scenarios. Evolution reliably improved MiniSWE pass@1, mainly through train and sealed split contributions, while Codex gains were more modest and uneven across splits. RSIHub execution changed scores by only a few points and revealed task-level disagreement, but the direction varied by agent and benchmark, so execution-mode equivalence was not established. All fault-injection and boundary-enforcement runs achieved perfect correct outcomes with no corrupted state, supporting integrity within the tested lifecycle boundaries.