Command Palette
Search for a command to run...
أتمتة التعلم الآلي من أجل العلم: هل تستطيع الوكلاء الحدودية تسلّق التلال العلمية في البيئات الواقعية؟
أتمتة التعلم الآلي من أجل العلم: هل تستطيع الوكلاء الحدودية تسلّق التلال العلمية في البيئات الواقعية؟
Ming Zhong Stacy Li Nicholas Carlini Matthew Jagielski
الملخص
يُنظر إلى وكلاء البرمجة الحدودية على نحو متزايد بوصفها باحثين مؤتمتين من البداية إلى النهاية، ويشكّل التعلم الآلي من أجل العلم اختبارًا صعبًا لهذا الوعد: فإدخال تحسين على نموذج علمي غالبًا ما يتطلب فهمًا متخصصًا يتجاوز الهندسة الروتينية للتعلم الآلي. نقدّم AGENT4SCI، وهو بيئة اختبار طويلة المدى لقياس مدى قدرة وكلاء اليوم على تحسين أفضل النماذج المنشورة في معايير تقييم التعلم الآلي العلمية، والتي تضم 20 معيارًا موزّعة على 11 مجالًا. وبدلًا من ترتيب الوكلاء في لوحة صدارة، يسأل AGENT4SCI عن أنواع التقدم التي يمكن أن يحققها الوكلاء في هذه المهام تحت الظروف الواقعية غير المضبوطة، وأين يقصّرون. تجريبيًا، تتفوق وكلاء اليوم الحدودية على أفضل النتائج المنشورة في كل معيار، إذ يحقق Claude Opus تحسينًا نسبيًا متوسطه 10.4% دون أن تُوسم أي تجربة بوصفها حالة سوء سلوك أكاديمي. غير أن هذه المكاسب تأتي في الغالب العظم من مجموعة حيل في هندسة التعلم الآلي لا من بصيرة بحثية. وتكشف تحليلات المسار ثلاث قيود متكررة في هذا السياق: معايرة خاطئة لمدى الجدة، وعدم استغلال كافٍ للموارد، والانهيار السريع في عمليات مسح هندسية محلية. وترفع مهارات إضافية خفيفة لابتكار أفكار بحثية، وإدارة التجارب، وقوائم التحقق المجدولة Claude Opus من 10.4% إلى 20.1%، وCodex من 4.4% إلى 8.1%، مع توليد تدخلات أكثر تنوعًا وملاءمة للمجال. ويمنح AGENT4SCI المجتمع وسيلة لتتبّع الوكلاء الحدودية ودفعها من هندسة التعلم الآلي نحو البصيرة المتخصصة في المشكلات الواقعية للتعلم الآلي من أجل العلم. الشيفرة والبيانات متاحة على GitHub وHugging Face.
One-sentence Summary
Anthropic Fellows Program and Anthropic introduce AGENT4SCI, a long-horizon, in-the-wild testbed spanning 20 benchmarks across 11 domains to measure how frontier coding agents improve published best scientific ML models, finding that gains arise mostly from ML-engineering tricks, while lightweight research-ideation, experiment-management, and checklist skills raise Claude Opus from 10.4% to 20.1% and Codex from 4.4% to 8.1% with more diverse domain-relevant interventions.
Key Contributions
-
AGENT4SCI is a human-verified long-horizon testbed of 20 scientific ML benchmarks across 11 domains that evaluates automated scientific hill-climbing from published best baselines while auditing trajectories to reduce evaluation gaming.
-
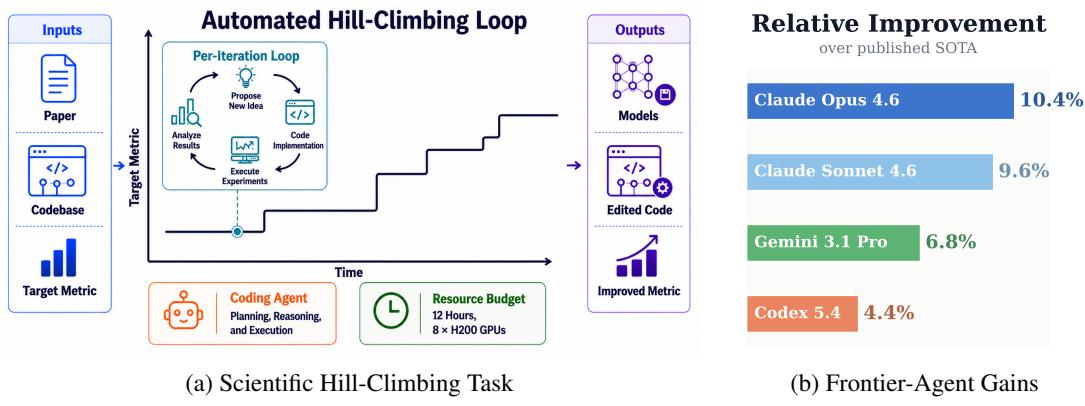
Experiments show that frontier coding agents improve every AGENT4SCI benchmark, with Claude Opus reaching 10.4 percent mean relative improvement, while trajectory analysis reveals novelty miscalibration, resource under-utilization, and rapid collapse into local engineering sweeps.
-
Lightweight plug-in skills for research ideation, experiment management, and scheduled checklists increase Claude Opus mean improvement from 10.4 percent to 20.1 percent and Codex from 4.4 percent to 8.1 percent, yielding more diverse and domain relevant interventions.
Introduction
Frontier coding agents increasingly turn automated research into an executable loop: they read papers and code, run experiments, interpret metrics, and iterate. This matters for machine learning for science because many scientific ML tasks rely on real research repositories, diverse modalities, and fixed metric objectives where automated improvement could accelerate experimentation. Prior demonstrations, however, mostly target well structured computer science tasks, single-task settings, and polished benchmarks, while real scientific code often enables evaluation gaming such as test-set contamination, metric manipulation, or hardcoded outputs. The authors contribute AGENT4SCI, a human-verified testbed for automated scientific hill climbing across 20 benchmarks, 25 tasks, and 11 scientific domains, with standardized reproduction, isolated held-out evaluation, and trajectory auditing. Their evaluation shows frontier agents can improve published baselines, but the gains mostly reflect ML engineering rather than deeper scientific insight.
Method
The authors modify the default coding agent through an external behavior layer called plugin skills. Rather than changing the underlying model, the method inserts carefully written skill documents into the agent workflow at specific stages. Each skill is a short markdown instruction file that shapes the agent’s planning, implementation, and self-evaluation behavior. The skill set is primarily tuned for Claude Code and also adapted to work with Codex.
The plugin framework targets three recurring failure modes in frontier coding agents. The first is novelty miscalibration, where the agent mistakes standard techniques for creative contributions. The second is resource underutilization, where GPUs remain idle or poorly allocated during experiment execution. The third is exploration collapse, where the agent initially generates diverse ideas but later narrows its strategy to hyperparameter tuning, ensembling, or repeated small variations.
The first module is research ideation, invoked at the start of a run. This skill grounds the agent in parallel literature review across both the target scientific domain and broader AI or ML methods. It also assigns the agent an exaggerated research scientist persona that strongly disfavors routine hyperparameter adjustment and prioritizes genuinely new methodological directions. After reviewing the literature, the agent produces a plan that separates bold ideas from safer fallbacks and places ambitious interventions above conventional defaults. This module is designed to correct novelty miscalibration by steering the agent away from well known techniques and toward more research-like hypothesis formation.
The second module is experiment management, applied during implementation and execution. This skill contains operational instructions for efficient use of computational resources. It directs the agent to monitor running jobs in real time, allocate priority resources to more ambitious experiments, and avoid CPU or GPU contention between concurrent tasks. It also encourages runtime optimizations such as faster data loading and mixed precision execution. The purpose of this module is to keep GPU utilization high and prevent inefficient experiment scheduling from limiting progress.
The third module is scheduled checklists, triggered periodically through a tool-call hook. Once per hour, the agent performs a structured self-assessment using diagnostic questions such as whether it is designing creative experiments, whether it is merely adjusting hyperparameters, and whether a domain expert would find the current strategy interesting. This mechanism forces the agent to reconsider its trajectory when its behavior begins to drift toward low-risk local refinement. The module is intended to prevent exploration collapse by repeatedly reintroducing the need for substantive research ideas instead of incremental tuning.
Experiment
The experiments evaluate frontier agents under a controlled, fully automated hill-climbing protocol on scientific benchmarks, testing whether they can improve published baselines without human intervention. The results show that every benchmark can be improved by at least one agent, although most gains come from standard engineering moves such as tuning, architecture changes, augmentation, and loss adjustments, with clearly different working styles and no evidence of evaluation gaming. Further analysis identifies recurring weaknesses in novelty, resource use, and exploration, while plug-in skills substantially improve performance and sometimes elicit task-specific scientific reasoning, though most gains remain practical rather than research-like.
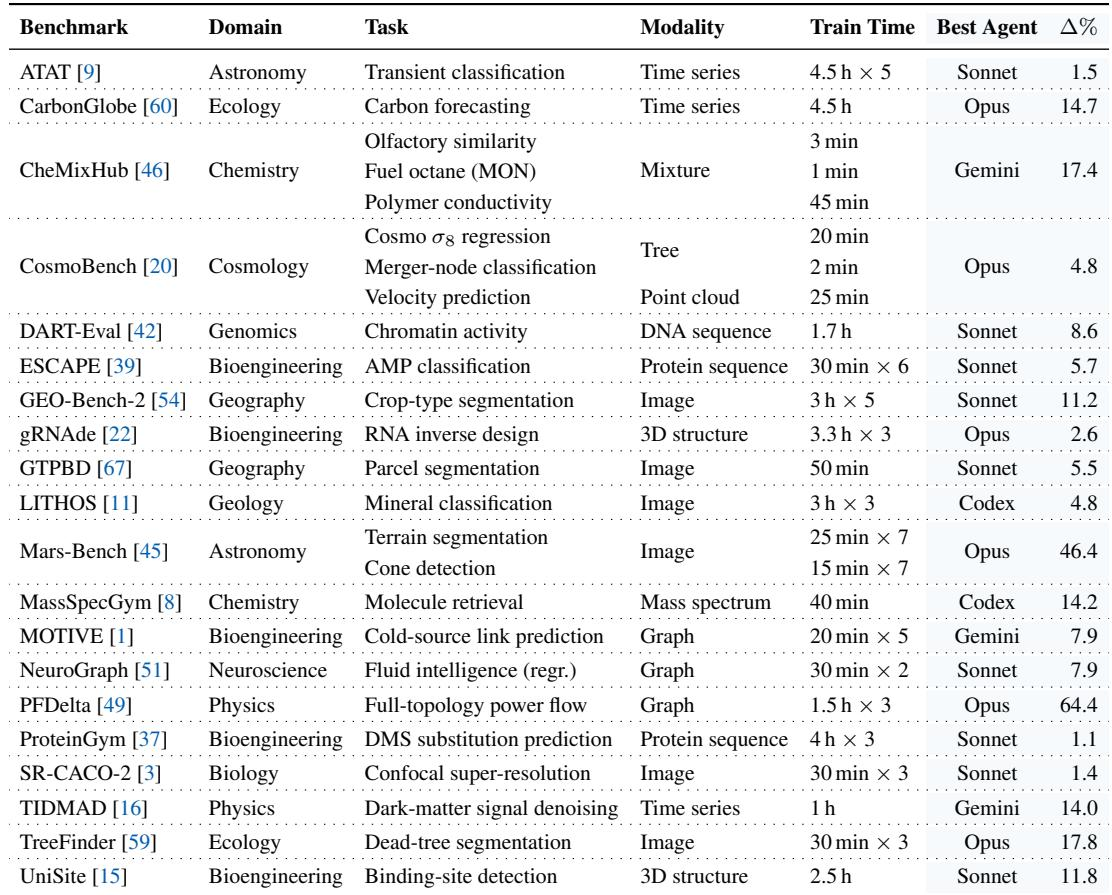
AGENT4SCI covers 25 tasks across 20 benchmarks, with the strongest benchmark representation from bioengineering and additional coverage from astronomy, chemistry, ecology, geography, physics, and several other scientific domains. The tasks span classification, segmentation, detection, regression, link prediction, and retrieval, while training costs range from minute-scale runs to hours on a single accelerator. Some evaluations also average over multiple seeds or folds, reflecting diverse benchmark protocols. The suite is intentionally broad across scientific domains, ML task types, modalities, and training budgets. Every benchmark can be improved by at least one frontier agent without human intervention. Improvement sizes vary widely, from modest gains to major loss reductions, and the best agent changes across benchmarks.
Plug-in skills improve hill-climbing performance for both agents and nearly double their mean relative improvement. The benefit is broad for Claude Opus, while Codex shows more concentrated gains, with the strongest lifts on benchmarks such as PFDelta, Mars-Bench, GEO-Bench-2, TIDMAD, MOTIVE, and CarbonGlobe. Skills are especially helpful when they lead agents to use domain-specific reasoning, although gains on many benchmarks remain modest. Plug-in skills nearly double average hill-climbing improvements for both agents. Opus gains are broad across benchmarks, while Codex gains are more concentrated. PFDelta shows especially large skill-driven gains from physics-informed reasoning.
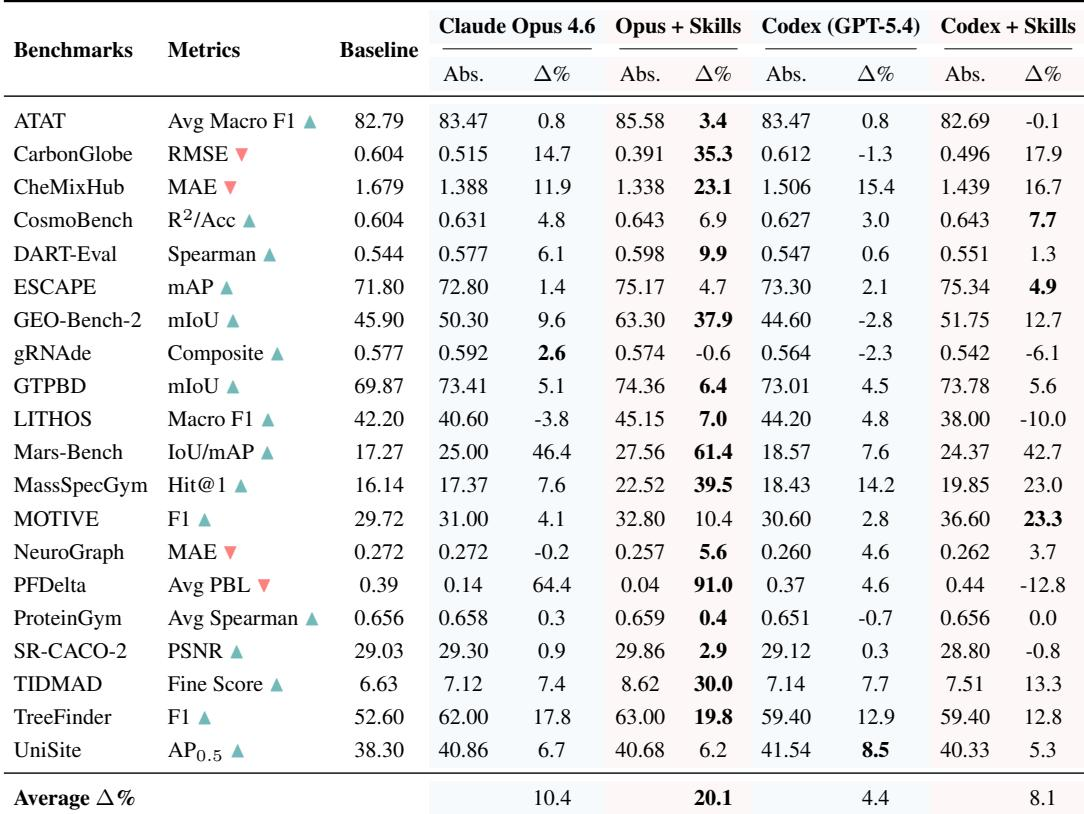
The evaluation introduces AGENT4SCI, a broad benchmark suite of 25 tasks across 20 scientific benchmarks that spans diverse domains, task types, modalities, and training budgets. Experiments validate that frontier agents can improve every benchmark without human intervention, though the amount of improvement and the best-performing agent vary widely. A second set of experiments shows that plug-in skills substantially strengthen hill-climbing performance, nearly doubling average relative improvements, with broader gains for Claude Opus and more concentrated but sometimes large gains for Codex, especially on benchmarks benefiting from domain-specific reasoning.