Command Palette
Search for a command to run...
ALODLM: نماذج لغة انتشارية ذات تكرار حلقي تكيفي
ALODLM: نماذج لغة انتشارية ذات تكرار حلقي تكيفي
الملخص
تتيح نماذج اللغة الانتشارية (DLMs) توليدًا سريعًا عبر التنبؤ بعدة رموز بالتوازي، غير أن اعتمادها العملي ما يزال محدودًا بفجوة جودة مستمرة مقارنةً بنماذج الانحدار الذاتي (AR) ذات الحجم المماثل. ونعزو هذه الفجوة إلى عدم تطابق بين مقدار الحساب وصعوبة المهمة: ففي تسلسل مُراقَب جزئيًا، تكون بعض الرموز غير المعروفة سهلة التنبؤ، في حين تتطلب رموز أخرى قدرًا أكبر من الحساب لحسمها. غير أن النماذج الانتشارية الحالية تطبّق عمقًا حسابيًا موحدًا على كل موضع غير معروف عند كل خطوة إزالة ضجيج. نقدم ALoDLM، الذي يستبدل هذا الحساب الموحد بتكرار كامن متكيف مع الرمز. ففي كل خطوة إزالة ضجيج، يصقل ALoDLM التمثيلات في الفضاء الكامن عبر التكرار، ويوزع الحساب وفقًا لصعوبة الرمز. أما الرموز الجاهزة للحسم فتُعاد تغذيتها بوصفها سياقًا رمزيًا متقطعًا، في حين تحتفظ الرموز غير المحسومة بحالاتها الكامنة وتصقلها عبر تمريرات تكرارية إضافية. ولتعلم التنبؤ بالرموز وتوزيع الحساب معًا من البداية إلى النهاية، نصوغ جداول الحساب على مستوى الرمز بوصفها متغيرات كامنة ونشتق حدًا أدنى شرطيًا للدليل السلبي (NELBO). وندرب ALoDLM بمقياسَي 1.7 مليار و8 مليارات معلمة. وعبر أحد عشر معيارًا تقييميًا، يتفوق ALoDLM على جميع نماذج اللغة الانتشارية المقيَّمة وخطوط الأساس المقابلة من نماذج الانحدار الذاتي في متوسط درجات المعايير عند كلا المقياسين. والأهم من ذلك أن ALoDLM يجمع بين جودة توليد فائقة وفك ترميز متوازٍ سريع، محققًا مقايضة قوية بين الجودة والكفاءة بين جميع النماذج ذاتية الانحدار والانتشارية المقيَّمة في ظل محركات استدلال محسَّنة.
One-sentence Summary
University of Illinois Chicago, Amazon AGI, and Korea University introduce ALoDLM, a diffusion language model that uses token-adaptive latent recurrence and token-wise computation schedules formulated as latent variables with a conditional negative evidence lower bound (NELBO) to allocate computation by token difficulty, and, trained at 1.7B and 8B parameters, it outperforms all evaluated diffusion language models and corresponding autoregressive (AR) baselines across eleven benchmarks while enabling fast parallel decoding.
Key Contributions
- Introduces a token-adaptive looped architecture for diffusion language models that replaces uniform denoising depth with dynamic latent recurrence, letting easy tokens commit early as discrete context while difficult tokens continue refining their latent states through additional recurrent passes.
- Formulates token-wise computation schedules as latent variables and derives a conditional negative evidence lower bound to jointly optimize token prediction and computation allocation, with an unbiased single-trajectory gradient estimator and variance reduction techniques for training stability.
- Scales ALoDLM to 1.7B and 8B parameters and evaluates it across eleven benchmarks. ALoDLM achieves higher average benchmark scores than all evaluated diffusion language models and the corresponding Qwen3 autoregressive baselines at both scales, and ALoDLM-8B reaches about 2.7× the throughput of vLLM-served Qwen3-8B at comparable accuracy on GSM8K.
Introduction
Autoregressive large language models deliver strong generation quality, but their token-by-token decoding creates a latency bottleneck. Diffusion language models can resolve multiple masked positions in parallel and thus offer faster generation, yet they still suffer a practical quality gap relative to similarly sized autoregressive models. Prior work mitigates this gap by reintroducing autoregressive structure via block diffusion, using diffusion models only as drafters for autoregressive verification, or applying confidence-based deferral that still recomputes deferred tokens from scratch. The authors attribute the core issue to a computation-difficulty mismatch: standard diffusion models apply the same fixed-depth denoiser to all masked positions, wasting compute on easy tokens and under-computing hard ones. They introduce ALoDLM, a looped diffusion language model with token-adaptive recurrent depth, where easy tokens commit early to provide resolved context while difficult tokens keep refining persistent latent states, supported by a principled training objective over latent token-wise exit schedules.
Method
The authors introduce ALoDLM, a family of discrete language models featuring token-adaptive recurrent computation. The architecture partitions a standard Transformer into three distinct components: a Prelude comprising the token embedding layer and optional prefix blocks, a Recurrent Core consisting of intermediate Transformer blocks, and a Coda containing the remaining suffix blocks. Refer to the framework diagram for an overview of the decoding process.
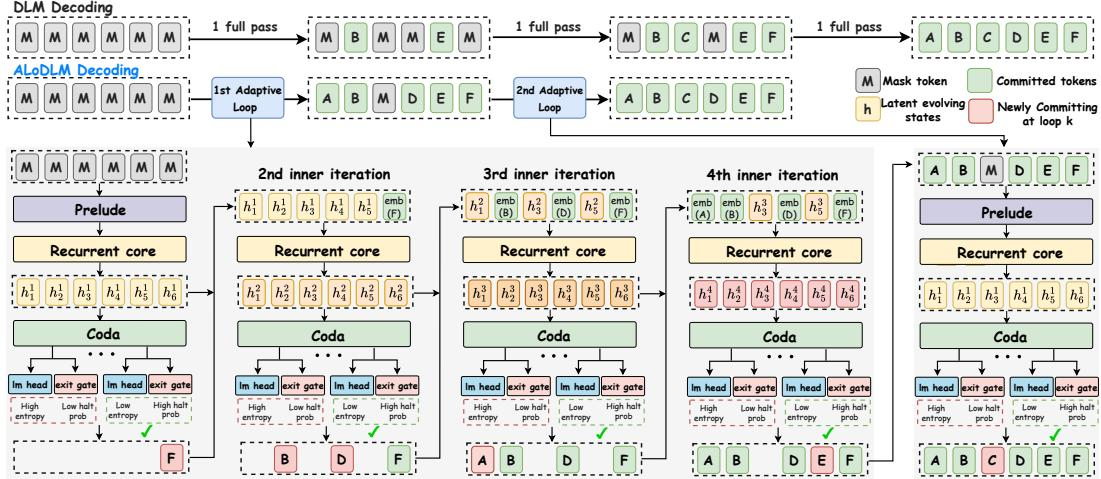
During inference, the model operates through an outer denoising loop augmented by an inner adaptive loop. At each denoising step, the corrupted input is processed by the Prelude to initialize the recurrent state. The Recurrent Core and Coda then update this state across multiple passes. At each recurrent pass s, the intermediate state and readout state are computed as:
h(s)=Recurrent Core(h(s−1)),r(s)=Coda(h(s)),s=1,…,Kwhere K is the maximum recurrent depth. The readout state is processed by two parallel heads. The unembedding head produces the vocabulary distribution, while an additional ExitGate generates a scalar logit whose sigmoid defines the per-pass halting probability. This probability determines whether a token commits to a discrete prediction or retains its latent state for further refinement. Committed tokens supply discrete context for subsequent passes, while unresolved positions build upon their accumulated latent states. The inner loop terminates when all tokens are committed or when the mean cumulative halt probability over unresolved positions reaches a predefined threshold.
To train the model, the authors jointly learn the denoiser and the halting policy by treating exit depths as latent variables. They define an exit schedule as a discrete random vector indicating the recurrent pass at which each masked token commits. Because marginalizing over all possible exit schedules is computationally intractable, they derive a negative evidence lower bound to optimize both components. The training objective combines a trajectory loss, which measures the prediction accuracy of the denoiser, and a KL divergence term that regularizes the learned exit distribution toward a truncated geometric prior.
Since the discrete exit decisions preclude standard backpropagation through the halting policy, the authors employ a score-function estimator to compute unbiased gradients. The surrogate loss function incorporates the trajectory loss and a detached cost term that provides an outcome signal for the sampled schedule, encouraging the policy to favor configurations that achieve high prediction accuracy while remaining close to the prior.
To further stabilize training, the authors introduce practical regularization and variance reduction techniques. They relax the joint KL penalty by regularizing the average depth distribution across the minibatch toward the geometric prior while applying a weaker penalty to individual token depth variations. Additionally, they implement intermediate supervision to reduce conditional gradient variance. As shown in the figure below, this approach effectively lowers the relative gradient variance across sampled exit trajectories.
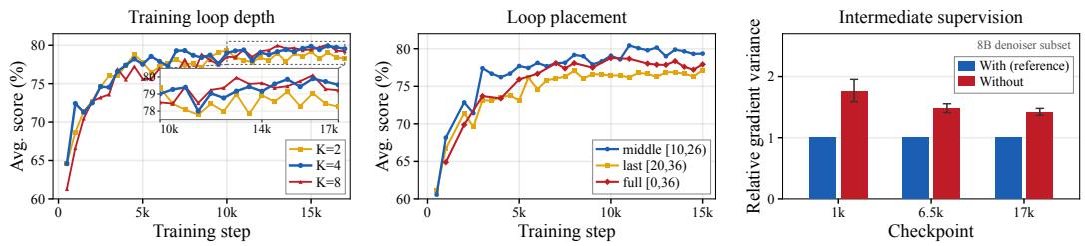
By reusing predictions from preceding recurrent passes and averaging the per-depth cross-entropy losses, the model provides direct learning signals to earlier passes even when a token exits at a later depth. This mechanism, combined with a control variate based on the first-pass prediction cost, significantly improves the stability of the denoiser gradients during the optimization process.
Experiment
ALoDLM is evaluated on Qwen3-derived 1.7B and 8B models across knowledge, math, and coding benchmarks, using direct supervised fine-tuning instead of continued pretraining and comparing against autoregressive and diffusion language models. The main performance evaluation shows that ALoDLM surpasses prior diffusion language models and strong autoregressive baselines, while the quality-efficiency experiments demonstrate that adaptive latent recurrence improves the trade-off between accuracy and throughput or per-token compute. Analyses and ablations further validate test-time scaling through recurrent depth, token-adaptive halting that allocates more refinement to numerical tokens, middle-layer loop placement, and reduced gradient variance from intermediate denoiser supervision.
ALoDLM consistently outperforms the evaluated diffusion language models at both the 1.7B and 8B scales, while also improving over the corresponding Qwen3 autoregressive baselines on average. The largest model exceeds the strongest diffusion baseline on most benchmarks and shows especially broad gains in code generation. This is achieved through direct supervised fine-tuning without the continued pretraining required by several prior diffusion models. ALoDLM surpasses all evaluated diffusion language models at both model scales and edges out the Qwen3 autoregressive baselines on average. The 8B model leads the strongest diffusion baseline on a majority of tasks, with especially consistent gains on code generation benchmarks. Direct supervised fine-tuning on a modest corpus is sufficient for ALoDLM to outperform baselines that rely on continued pretraining.
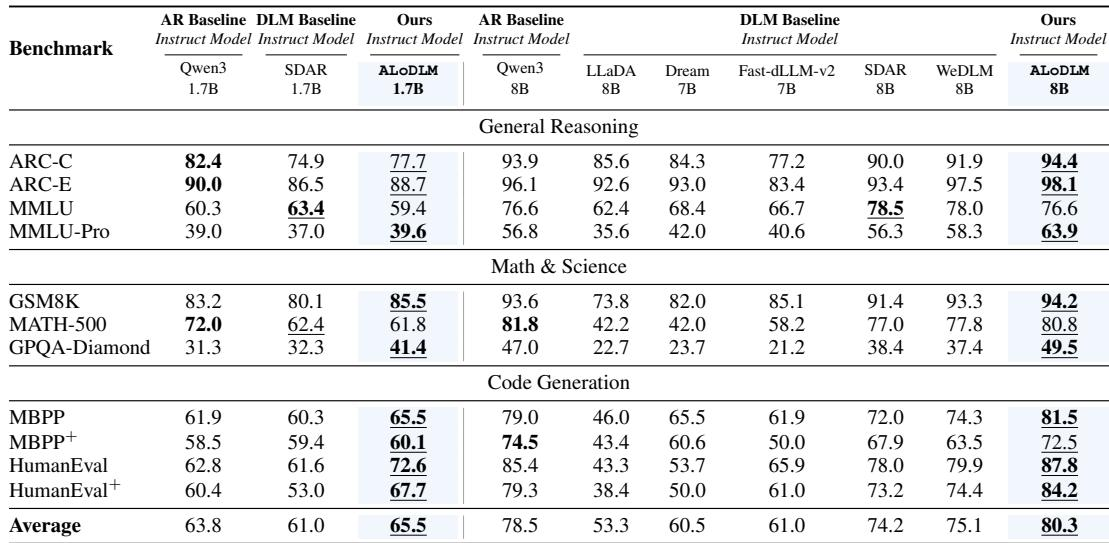
ALoDLM consistently outperforms all evaluated diffusion language models at both the 1.7B and 8B scales and edges out the Qwen3 autoregressive baselines on average. The 8B model exceeds the strongest diffusion baseline on most benchmarks, with especially consistent gains in code generation. These results are achieved through direct supervised fine-tuning on a modest corpus, without the continued pretraining required by several prior diffusion models.