Command Palette
Search for a command to run...
WING: تعلُّم الفعل العالمي عبر التوجيه الكامن الطيفي المتمركز حول التفاعل
WING: تعلُّم الفعل العالمي عبر التوجيه الكامن الطيفي المتمركز حول التفاعل
Zhiming Liu Yikun Miao Ying Chen Hongrui Yin Fangqi Zhu Xiaoyi Pang Quanxin Shou Zhengyang Yan Haodong Wang Song Guo
الملخص
يتطلب تعلُّم سياسات روبوتات عامة الأغراض بيانات تفاعل واقعية واسعة النطاق، غير أن جمع العروض التوضيحية للروبوتات عبر التحكم عن بُعد يظل مكلفًا ويصعب توسيع نطاقه. توفر مقاطع الفيديو المأخوذة من منظور الشخص الأول مصدرًا غنيًا بخبرة التفاعل البشري التي تتقاسم دلالات ذات صلة بالمهمة مع المعالجة الروبوتية، مما يتيح فرصة لمواءمة أفعال البشر والروبوتات في فضاء أفعال كامن مشترك لنقل المعرفة عبر التجسيدات. ومع ذلك، فإن الطرائق الحالية للأفعال الكامنة تستدل عادةً على الأفعال من خلال إعادة البناء بين إطارات متتالية، وهي ليست متمركزة حول التفاعل بطبيعتها ويمكن أن تطغى عليها تغيرات مزعجة، مثل حركة الكاميرا الذاتية. علاوة على ذلك، ورغم أن تفاعلات البشر وأفعال الروبوتات تتشارك دلالات التفاعل، فإنها غالبًا ما تُظهر ديناميكيات زمنية مختلفة اختلافًا كبيرًا، مما يجعل النقل المباشر إلى سياسات الروبوتات أمرًا صعبًا. لمعالجة هذه التحديات، نقترح WING (تعلُّم الفعل العالمي عبر التوجيه الكامن الطيفي المتمركز حول التفاعل)، وهو إطار عمل لنقل معرفة التفاعل من مقاطع الفيديو الذاتية إلى سياسات الروبوتات. أولًا، نقدم آلية لفصل التفاعل عن الحركة تفصل الإشارات ذات الصلة بالتفاعل عن الحركة غير المرتبطة بالمهمة وتقطر المكونات المتمركزة حول التفاعل انتقائيًا إلى أفعال كامنة. ثانيًا، انطلاقًا من ملاحظة أن دلالات المهمة عبر التجسيدات تُرمَّز أساسًا في بنى زمنية تتغير ببطء، نحدد المكونات المشتركة بين الأفعال الكامنة المستخرجة من الفيديو الذاتي وسلوكيات الروبوت في المجال الطيفي ونستخدمها كتوجيه لتوليد الأفعال في وقت الاستدلال. بفضل هذه التصميمات، يحقق WING متوسط معدلات نجاح قدرها 99.20% على LIBERO و93.80% على RoboTwin 2.0 و57.7% على RoboCasa–GR1، كما يُظهر أداءً قويًا عبر أربع مهام واقعية في ظل إعدادات تعميم متنوعة. تُظهر هذه النتائج أن WING يمكنه تقطير معرفة التفاعل المتجسدة من مقاطع فيديو ذاتية واسعة النطاق ونقلها إلى التحكم في الروبوتات بفعالية، مما يوفر مسارًا قابلًا للتوسع لاكتساب معرفة التفاعل الفيزيائي من الخبرة البشرية.
One-sentence Summary
Researchers at The Hong Kong University of Science and Technology propose WING, a framework that transfers egocentric human interaction knowledge to robot policies by decoupling interaction-relevant signals from task-irrelevant motion and aligning cross-embodiment latent actions in the spectral domain, achieving average success rates of 99.20% on LIBERO, 93.80% on RoboTwin 2.0, and 57.7% on RoboCasa-GR1, while also demonstrating strong performance across four real-world tasks.
Key Contributions
- Analysis shows that egocentric latent actions entangle observer-induced camera motion with interaction-relevant dynamics, and that low-frequency latent temporal structures correspond more consistently across human and robot interactions.
- WING is introduced as a framework combining interaction-motion decoupling, which separates interaction-relevant signals from task-irrelevant motion, with spectral latent guidance that transfers shared low-frequency components into robot action generation.
- In simulation, WING achieves average success rates of 99.20% on LIBERO, 93.80% on RoboTwin 2.0, and 57.7% on RoboCasa-GR1; real-world tests across four bimanual manipulation tasks show strong performance under standard and diverse generalization settings.
Introduction
Generalist robot policies require large and diverse manipulation data, but collecting robot demonstrations through teleoperation is costly and hard to scale. Egocentric human videos offer a promising alternative because they capture first-person human-object interactions that resemble robot observations, yet transferring them to robot control is difficult. Existing latent action models typically learn by reconstructing future observations, so they can absorb task-irrelevant observer motion and fail to isolate interaction-relevant dynamics that transfer across different embodiments. The authors introduce WING, a framework that learns interaction-centric latent actions by suppressing observer-induced variation and preserving local interaction-related changes, then uses low-frequency spectral latent guidance from discrete cosine transform components to condition robot action generation. The method is validated on simulated and real-world bimanual manipulation tasks, where it outperforms representative robot policies and egocentric pretraining baselines.
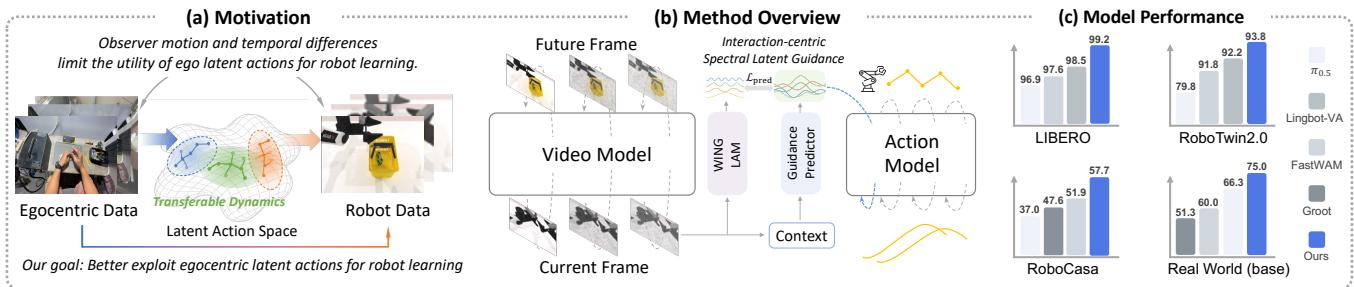
Method
The authors introduce WING, a framework that extracts structured interaction priors from large-scale egocentric videos and transfers them to robot manipulation policies. The target policy maps a language instruction l, visual observation ot, and robot proprioception st to an executable action chunk at:t+m. WING transfers knowledge through two main components: WING-LAM, an interaction-centric latent action model, and a spectral latent guidance module. The former encodes egocentric visual transitions into latent actions while suppressing observer-induced motion, and the latter distills slow, low-frequency temporal structure from those latent actions as guidance for downstream action generation.
Interaction-centric latent action learning
WING-LAM is designed to isolate hand-object interaction dynamics from camera motion. Since observer motion induces coherent image-wide changes while interaction motion is more localized, the authors exploit this distinction with an explicit motion-routing formulation. Given two frames ot and ot+δ, an offline point tracker produces corresponding points pt,i and pt+δ,i. Region masks separate background tracks from hand-object interaction tracks. Using background tracks, an invertible global warp Wt→t+δ is estimated as the observer-motion target. After compensating this global warp, the residual displacement
rt,i=Wt→t+δ−1(pt+δ,i)−pt,irepresents motion that is not explained by observer movement and therefore serves as the interaction-motion target.
These decomposed motion signals provide privileged supervision for a two-branch teacher. One branch produces a camera latent zt,camT and predicts the global warp, while the other produces an interaction latent zt,intT and predicts residual displacements. The decoded motions jointly reconstruct tracked locations in the second frame, encouraging factorization of observer motion and interaction dynamics. Camera interventions are additionally applied to preserve interaction dynamics and enforce latent consistency.
Because privileged motion cues are unavailable at deployment, the teacher interaction representation is distilled into an RGB-only student Sϕ. For each frame pair (otego,ot+δego), the authors construct a camera-perturbed view o~t+δego by applying a camera-like global warp to the second frame. The original pair and the augmented pair share the same interaction target zt,intT but differ in observer-induced motion. The student encodes both pairs, yielding ztnat and ztaug, and is optimized with
Ldistill=2Di1v∈{nat,aug}∑ztv−zt,intT22+Diλviewztnat−ztaug22.The first term transfers the teacher interaction representation, while the second encourages the student to remain consistent under camera-like image warps.
Spectral latent action guidance
Although WING-LAM yields interaction-centric latents, semantically matched human and robot executions can still differ in temporal dynamics. To address this, the spectral guidance module operates on a latent trajectory
Zt=[zt,…,zt+H−1]⊤∈RH×Di,where each latent is extracted from successive observations. An orthonormal discrete cosine transform is applied along the temporal dimension, and the lowest K frequency components are retained as the guidance target gtlow. This truncation suppresses rapidly varying components that are less consistent across embodiments while preserving slowly varying interaction structure.
Since computing gtlow requires future observations, a lightweight predictor Pψ estimates the guidance from the current language instruction, visual observation, and proprioception, denoted collectively as ct. The predictor minimizes
gtlow=Pψ(ct),Lpred=KDi1gtlow−gtlowF2.The predicted guidance is projected into guidance tokens Ut∈RK×Dhid, where Dhid is the action model hidden dimension. Each frequency coefficient vector is projected, normalized with LayerNorm, and given a learned embedding identifying its frequency mode. The action model attends to these tokens through a gated residual update
Ha(l)←Ha(l)+γlAttn(Q=LayerNorm(Ha(l)),K=Ut,V=Ut),where Ha(l) is the action hidden sequence at layer l and the learned scalar γl controls the magnitude of latent guidance. In this way, robot actions are conditioned on a high-level spectral prior rather than on full human latent trajectories.
Training strategy
The world action model is trained in two stages. In egocentric pretraining, the authors adopt Wan2.2 and train a video expert for future-frame generation together with the guidance predictor Pψ for low-frequency spectral guidance prediction. This stage learns visual and interaction dynamics from egocentric videos through the generation objective and the latent guidance prediction objective.
In robot policy learning, the pretrained visual backbone and guidance predictor are transferred to the robot policy and jointly trained with the action expert on robot demonstrations. The guidance predictor is supervised on robot data, while the WING-LAM encoder remains frozen. The predicted low-frequency guidance conditions downstream action generation during both training and inference, allowing the policy to combine interaction priors from egocentric video with embodiment-specific executable actions learned from robot demonstrations.
Experiment
The evaluation examines WING from representation and policy perspectives across several simulation benchmarks and a real-world dual-arm platform. Representation experiments show that WING-LAM suppresses observer-related camera variation while retaining action semantics, and that low-frequency latent dynamics carry the most transferable human-robot interaction structure. Policy and ablation results indicate that combining observer-debiased latent actions with spectral low-frequency guidance improves manipulation across single-arm, bimanual, and humanoid settings, with a moderate number of DCT components giving the best balance. Pretraining analyses further show that ego-derived latent actions are more effective as auxiliary spectral guidance than as direct action targets, and that video exposure alone does not explain the gains.
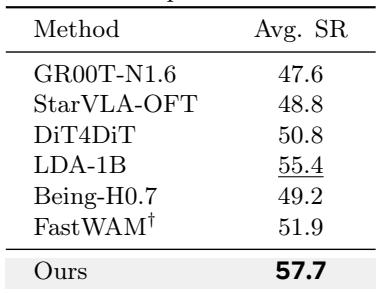
On the RoboCasa-GR1 tabletop benchmark, the proposed WING method achieves the highest average success rate and surpasses the strongest reported baseline by a modest margin. Most other approaches cluster in the high 40s to low 50s, with the reproduced FastWAM baseline performing below the top entry. This indicates a consistent advantage for WING over prior and reproduced baselines in this humanoid manipulation setting. WING leads RoboCasa-GR1 with the highest average success rate, ahead of LDA-1B as the second-best method. Most baselines are tightly grouped in the high 40s to low 50s, while the top two methods separate from the remainder.
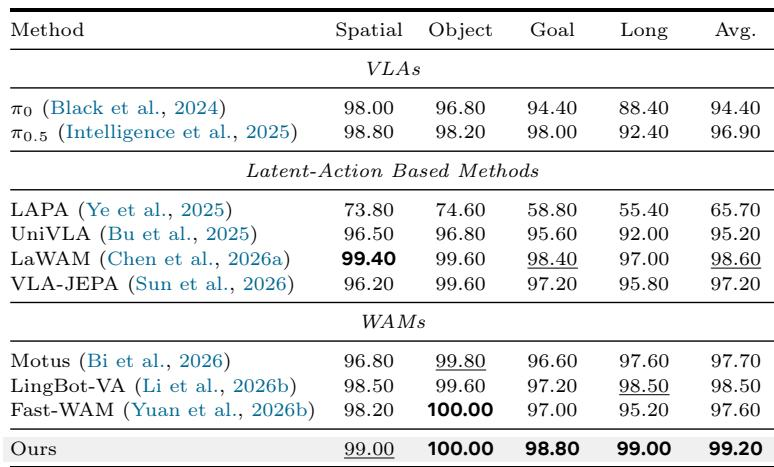
The results show WING leading on both LIBERO and RoboTwin 2.0, outperforming the strongest baselines in average success rate. On LIBERO, WING surpasses all listed VLA and latent-action methods, with LaWAM as the strongest listed baseline and LAPA trailing substantially. The reported advantage extends to long-horizon and randomized scenes, supporting generalization beyond clean short-horizon tasks. WING attains the top average success rate on LIBERO and RoboTwin 2.0, ahead of both VLA and latent-action baselines. Latent-action methods show a wide performance range, with LAPA trailing substantially and LaWAM strongest among them but still below WING. WING's lead persists in long-horizon LIBERO splits and RoboTwin randomized scenes, indicating robustness beyond short clean tasks.
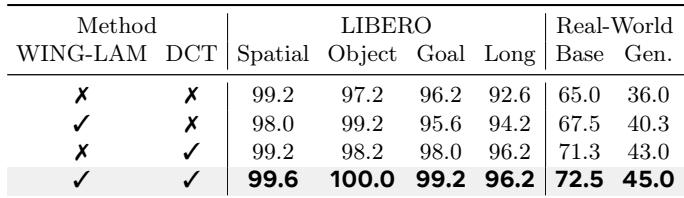
The full configuration with both WING-LAM and the DCT spectral guidance module achieves the highest success rates across LIBERO and real-world evaluations. Removing either component lowers performance, with the clearest declines in real-world settings. Frequency-domain decomposition and reduced observer-induced variation each contribute to more useful latent guidance for robot control. The full model with WING-LAM and DCT consistently achieves the highest success rates, especially in real-world base and generalization tasks. Ablating WING-LAM while retaining DCT reduces real-world performance, indicating that observer-debiased latent actions improve control guidance. Bypassing DCT and using the full time-domain latent trajectory weakens real-world performance, supporting low-frequency spectral retention as more effective guidance. Removing both components yields the lowest real-world success rates, with performance gaps widening from base to generalization settings.
The experiments evaluate WING across humanoid tabletop manipulation, standard robot learning benchmarks, and ablation settings. WING achieves the highest average success rates on RoboCasa-GR1, LIBERO, and RoboTwin 2.0, outperforming both VLA and latent-action baselines, with gains persisting on long-horizon and randomized scenes. Ablations show that combining observer-debiased latent actions with frequency-domain spectral guidance yields the strongest performance, especially in real-world base and generalization tasks, while removing either component leads to clear declines.