Command Palette
Search for a command to run...
DuoMatching: مطابقة التوزيع المشترك-الهامشي لتوليد الفيديو بخطوات قليلة
DuoMatching: مطابقة التوزيع المشترك-الهامشي لتوليد الفيديو بخطوات قليلة
Jiahao Zhan Yan Wang Yongrui Ma Qunliang Xing Ruchang Yao Runtao Liu Shijie Zhao Tianfan Xue
الملخص
استفاد توليد الفيديو التدفقي من تقطير مطابقة التوزيع (DMD)، الذي يطابق التوزيع المشترك لإطارات الفيديو مع تقريب معلم الفيديو لتوزيع الفيديو الحقيقي. وعلى الرغم من أن هذه المطابقة المشتركة تخفف من الانجراف أثناء عمليات التوليد الذاتي الانحداري، فلا تزال هناك قيود على الجودة البصرية والمطابقة الدلالية. ولمعالجة هذه القيود، نقترح DuoMatching، وهو إطار لمطابقة التوزيع يقرّب توزيع الفيديو الحقيقي عبر صياغة موحَّدة تجمع بين المطابقة المشتركة والهامشية. وإضافةً إلى صيغ المطابقة المشتركة القائمة، يوفّر هدف المطابقة الهامشية الإضافي إشرافًا مخصصًا على مستوى الإطار من مولّد صور، ناقلًا منه معارف بصرية ودلالية مكمّلة. ولتطبيق هذا الإشراف على مستوى الإطار في توليد الفيديو، نقدم LatentBridge لمعالجة عدم التطابق في التمثيل الكامن بين طالب الفيديو ومعلم الصور. ويعمل Latent Variation Sampling على توزيع هذا الإشراف على مستوى الإطار عبر مقاطع زمنية متميزة، مما يقلل من التكرار. وتُظهر التجارب أن DuoMatching يحسّن الجودة البصرية والتكوين والمطابقة الدلالية مع الحفاظ إلى حد كبير على ديناميكيات الحركة. وتُظهر التقييمات البشرية معدلات تفضيل إجمالية تتجاوز 80% مقابل جميع خطوط الأساس المقيّمة.
One-sentence Summary
Researchers from MMLab, CUHK, ByteDance Inc., HKUST, and CPII under InnoHK propose DuoMatching, a joint-marginal distribution matching framework for few-step video generation that adds frame-level image-teacher supervision via LatentBridge to resolve latent representation mismatches and via Latent Variation Sampling to reduce temporal redundancy, thereby improving visual quality, composition, and semantic alignment while preserving motion dynamics and achieving over 80% human preference against evaluated baselines.
Key Contributions
- DuoMatching is a unified joint-marginal distribution matching framework for few-step video generation that adds frame-level supervision from an image teacher to existing joint video distribution matching.
- Within DuoMatching, LatentBridge resolves the latent representation mismatch between the video student and image teacher, while Latent Variation Sampling distributes marginal supervision across distinct temporal segments to reduce redundancy.
- Experiments demonstrate improvements in fine-grained visual quality, visual composition, and semantic alignment in causal and bidirectional generation while largely preserving temporal quality, with human evaluations reporting overall preference rates above 80% against all evaluated baselines.
Introduction
Recent video generation models achieve strong visual quality and temporal coherence but require many sequential denoising steps, limiting real-time applications such as interactive world simulation and digital entertainment. Distribution matching distillation compresses multi-step diffusion or flow models into few-step generators, but existing joint DMD methods mainly match the full video distribution and do not explicitly supervise individual frame distributions. This leaves weaknesses in fine-grained appearance and semantic alignment. The authors propose DuoMatching, a unified joint-marginal distribution matching framework that combines joint DMD with a video teacher and marginal DMD with an image teacher to strengthen frame-level supervision. They further introduce LatentBridge to resolve latent space mismatches for temporally compressed video latents and Latent Variation Sampling to reduce redundant supervision. Experiments show improved visual quality, composition, and semantic alignment while largely preserving temporal dynamics.
Method
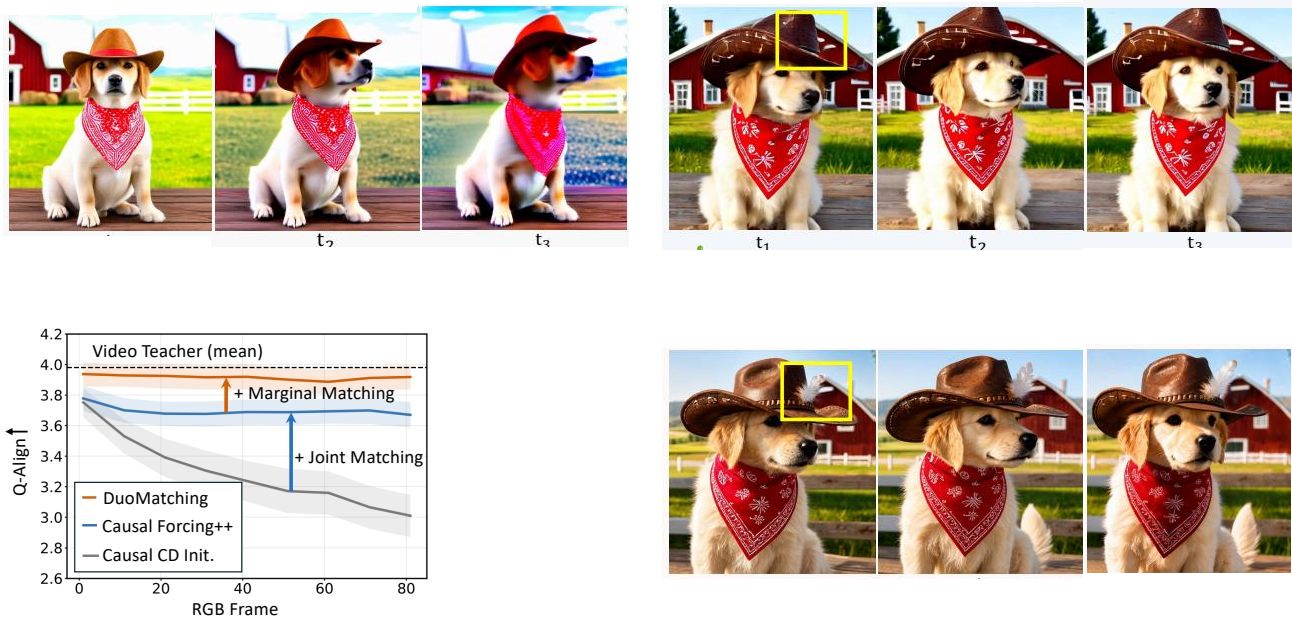
The authors formulate video generation as a distribution matching problem, aiming to align the generator's output distribution with the real data distribution. Since the score of the real distribution is unavailable, prior work approximates it using a pretrained video teacher, resulting in a joint distribution matching objective. In this setup, the score for each latent slice is conditioned on all other slices. Consequently, improvements to an individual frame might be suppressed if they introduce inconsistencies with surrounding frames. As shown in the figure below, relying solely on joint matching leads to limitations in visual quality and semantic alignment, such as missing fine-grained details in generated frames.
To overcome these limitations, the authors propose DuoMatching, a unified framework that reformulates distribution matching through both joint and marginal perspectives. The framework retains the video teacher to constrain cross-frame dependencies via joint matching, while introducing an image teacher to provide direct frame-level marginal supervision. The combined objective balances the joint distribution estimate from the video teacher and the complementary marginal estimate from the image teacher.
A significant challenge in leveraging image teachers is the structural mismatch between video and image latent spaces. Video VAEs typically employ temporal compression, mapping a single latent slice to multiple RGB frames, whereas image VAEs map one latent to a single frame. To resolve this, the authors introduce LatentBridge, a lightweight differentiable module. As illustrated in the framework diagram, LatentBridge maps a video latent slice, conditioned on the preceding slice and a specific local frame index, to a frame-specific representation within the image teacher's latent space. The module is pretrained using paired video and image latents with an L1 reconstruction loss, enabling gradients from the marginal matching objective to propagate efficiently to the student generator.
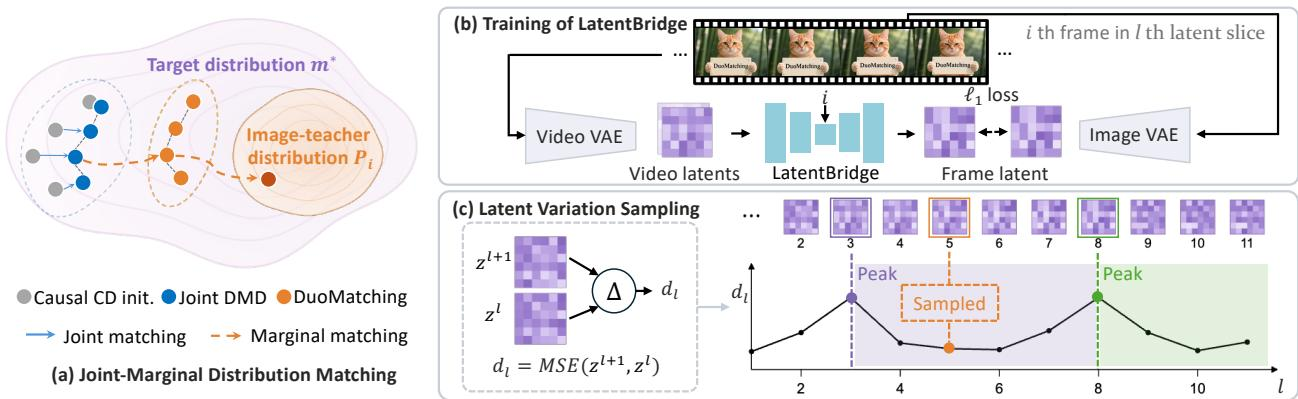
To further optimize the marginal matching process, the authors design Latent Variation Sampling. Supervising randomly sampled frames can lead to redundant computations in slowly changing regions, potentially suppressing motion dynamics. Instead, this sampling strategy computes the mean squared difference between adjacent clean video latent slices to measure temporal variation. The sequence is partitioned into contiguous segments based on the positions with the highest variation. By uniformly sampling one latent slice from each segment, the method ensures that the limited supervision budget is distributed across diverse temporal regions, thereby improving temporal coverage and reducing redundancy in frame-level supervision.
Experiment
The experiments evaluate causal and bidirectional video generation models trained with DMD, comparing DuoMatching against autoregressive and bidirectional baselines under matched inference budgets. Results on VBench and human preference tests show DuoMatching improves visual quality, semantic alignment, and composition while preserving motion quality, with no additional inference cost. Ablations confirm that explicit marginal matching, stronger image teacher priors such as Qwen-Image, and LatentBridge contribute to these gains, and that latent variation sampling allocates frame-level supervision more effectively than uniform or stratified sampling.
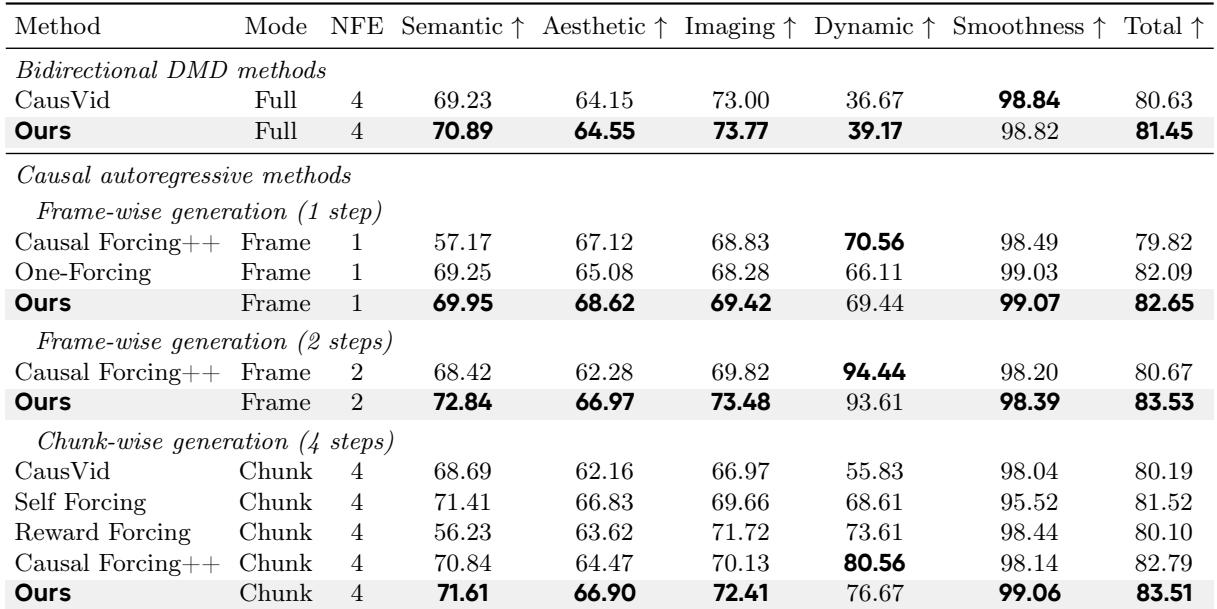
DuoMatching improves overall VBench performance over matched baselines in both bidirectional full-video generation and causal autoregressive generation. In bidirectional mode, gains appear in semantic, aesthetic, imaging, and dynamic scores while smoothness remains nearly unchanged. In causal mode, it improves visual quality and semantic alignment while largely preserving motion quality, without additional inference computation. In bidirectional full-video generation with matched NFE, DuoMatching outperforms CausVid in total score and shows gains in semantic, aesthetic, imaging, and dynamic metrics, with smoothness similar. In causal autoregressive generation, DuoMatching achieves higher video generation quality across one-step, two-step, and four-step settings, with notable gains in visual quality and semantic alignment while motion quality is largely preserved. All reported gains are obtained without increasing inference computation, preserving the real-time generation capability of the causal baseline.
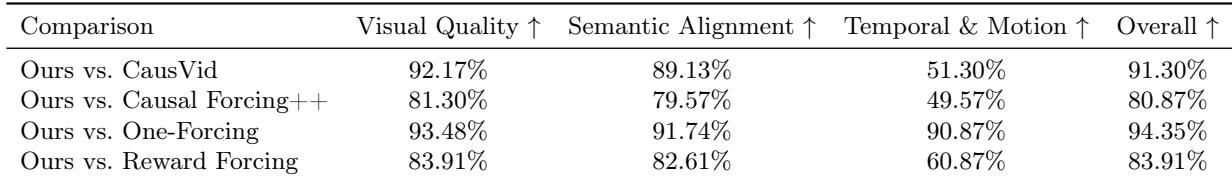
DuoMatching was preferred over all baselines in overall quality, with overall preference rates above 80 percent in every pairing. Its advantages were concentrated in visual quality and semantic alignment, while temporal and motion preferences were near or above parity, indicating that motion quality was largely preserved. Overall preference rates favored DuoMatching against every baseline by a clear margin. Visual quality and semantic alignment preferences consistently favored DuoMatching, whereas temporal and motion preferences remained near or above parity.
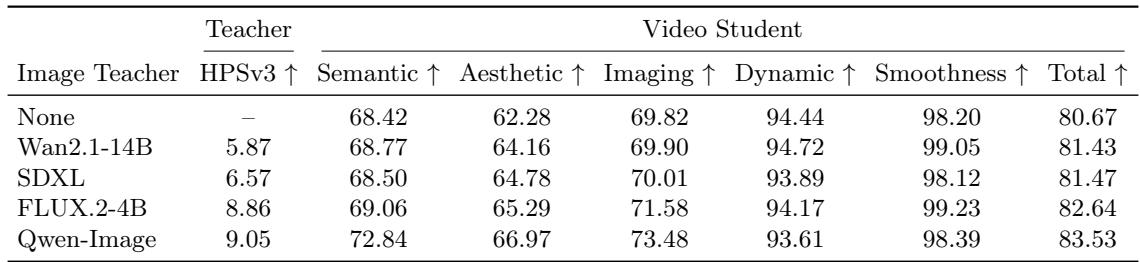
Using Wan2.1-14B as an image teacher improves all reported video student metrics over the no-teacher baseline. Across SDXL, FLUX.2-4B, and Qwen-Image, higher teacher HPSv3 scores correspond to consistent gains in semantic, aesthetic, and imaging scores, while dynamic degree and motion smoothness remain relatively stable. Qwen-Image achieves the strongest semantic, aesthetic, imaging, and total results among the compared image teachers. Wan2.1-14B as an image teacher improves performance across all reported metrics compared with the no-teacher baseline. For SDXL, FLUX.2-4B, and Qwen-Image, higher teacher HPSv3 scores align with consistent improvements in semantic, aesthetic, and imaging scores, while dynamic degree and motion smoothness stay relatively stable.
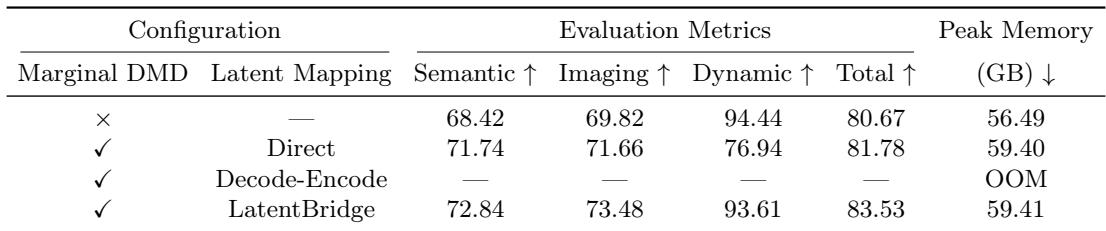
Enabling marginal DMD with direct latent mapping improves semantic and visual quality but substantially lowers dynamic quality. LatentBridge restores dynamic quality while improving semantic and imaging scores further, with only a small memory increase over the direct baseline. Decode-Encode was infeasible under the training configuration due to out-of-memory. Applying marginal DMD directly to temporally compressed video latents improves semantic and imaging scores but reduces Dynamic score compared with the no-marginal-DMD baseline. LatentBridge yields the best semantic and imaging results among feasible configurations while largely retaining dynamic quality. Decode-Encode runs out of memory, whereas LatentBridge adds only a small peak memory overhead over the Direct baseline.
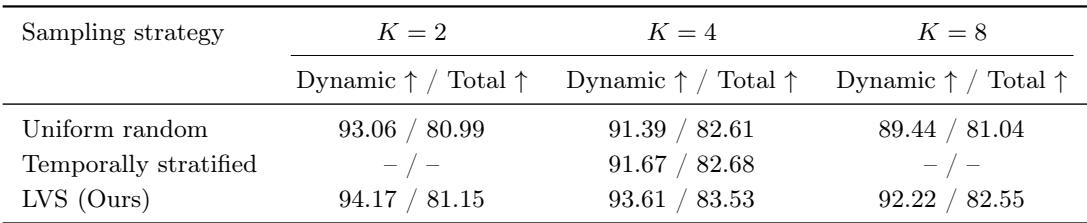
Increasing the number of sampled latent slices from 2 to 4 improves total scores for uniform random sampling and Latent Variation Sampling, but further increasing to 8 reduces both dynamic and total scores. Latent Variation Sampling consistently outperforms uniform random sampling across all tested slice counts and also exceeds temporally stratified sampling at four slices. The results indicate that a moderate slice count with Latent Variation Sampling better balances temporal quality and overall performance while limiting computational cost. Latent Variation Sampling achieves the highest dynamic and total scores at K=4 among all tested sampling strategies. Raising K from 2 to 4 improves total scores, whereas raising K to 8 lowers both dynamic and total scores. Uniform random sampling trails Latent Variation Sampling at every tested K. At K=4, temporally stratified sampling scores between uniform random sampling and Latent Variation Sampling on dynamic and total metrics.
The experiments evaluate DuoMatching in bidirectional full-video and causal autoregressive generation, showing consistent gains in visual quality and semantic alignment while preserving temporal smoothness and inference cost, with human evaluations confirming clear overall preference and motion parity. Additional ablations validate that using Wan2.1-14B as an image teacher improves student metrics across baselines, and that replacing direct marginal DMD with LatentBridge restores dynamic quality while improving semantic and imaging scores with only modest memory overhead. Finally, a moderate number of latent slices under Latent Variation Sampling, especially four slices, provides the best balance between temporal quality and overall performance compared with uniform or stratified sampling.