Command Palette
Search for a command to run...
حدود زائفة: تشخيص الغش المشترك وتخفيفه في وكلاء البحث المتطورة ذاتيًا
حدود زائفة: تشخيص الغش المشترك وتخفيفه في وكلاء البحث المتطورة ذاتيًا
الملخص
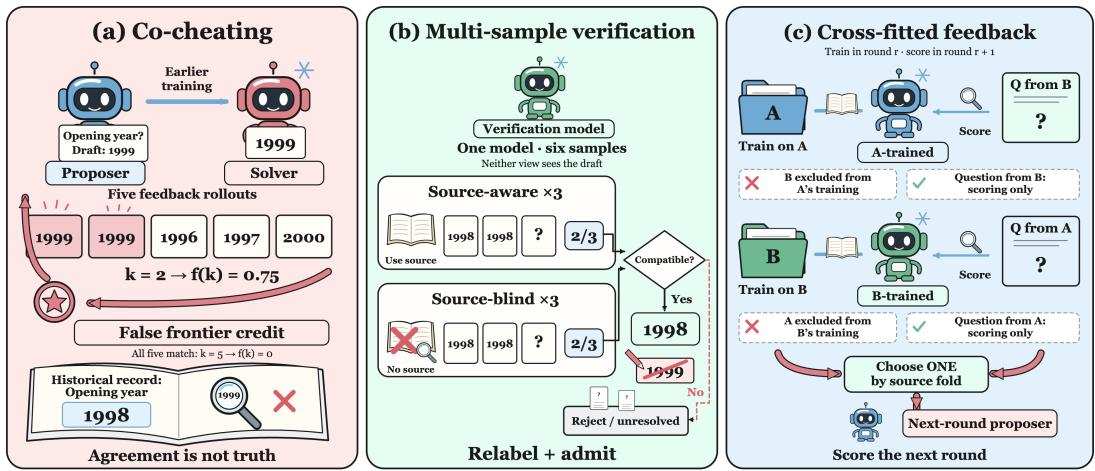
يمكن لوكلاء البحث المتطورة ذاتيًا بناء مناهجهم التدريبية الخاصة عبر التحسين المشترك لمولّد أسئلة ومُحِلّ يجيب عنها. تُدخل هذه الحلقة المغلقة نمط فشل نسميه الغش المشترك (co-cheating): إذ يزداد توافق المولّد والمُحِلّ على أخطاء مشتركة، فيتحسن المكافأة الداخلية دون تحسن مقابل في الصحة الخارجية. يُظهر تدقيق مرجعي لاحق مقابل أدلة المصدر أن الغش المشترك يزداد حدة عبر الجولات المتعاقبة من التطور الذاتي، حيث تركد صحة التسميات الزائفة أو تتراجع حتى مع تحسن إشارة التدريب داخل الحلقة. يتمثل التخفيف الأكثر مباشرة في التحقق من كل مقترح قبل التدريب. لذلك نقدم التحقق متعدد العينات (MSV)، الذي يستعلم النموذج نفسه المستخدم في التطور الذاتي ثلاث مرات مع المصدر وثلاث مرات بدونه لتحديد قبول المهمة واستبدال التسميات الزائفة غير الموثوقة. يقلل MSV الاتفاق الخاطئ جزئيًا لكنه يترك غشًا مشتركًا متبقيًا كبيرًا ويتطلب ست توليدات تسمية إضافية لكل مرشح. تدفع هذه القيود إلى ابتكار CrossFit، طريقتنا الرئيسة. تقسم هذه الطريقة مستندات المصدر الخاصة بالمولّد إلى مجموعتين A وB: فالأسئلة المولدة من A تُقيَّم بواسطة مُحِلّ مساعد مدرَّب على B فقط، والعكس صحيح. يحدد الاتفاق الناتج عن التقدير المتقاطع مكافأة المولّد، مما يمنع إعادة إنتاج تسمية زائفة من المصدر نفسه مباشرة عبر مُحِلّ التغذية الراجعة مع إبقاء قاعدة تحديث المُحِلّ الأصلي دون تغيير. نقيّم التدخلين بإعادة تشغيل حلقة التطور الذاتي الكاملة مع Qwen3.5-4B وQwen3.5-9B. بعد التطور الذاتي، يخفض MSV كتلة الاتفاق الخاطئ من 6.1% إلى 5.7% على Qwen3.5-4B ومن 8.8% إلى 7.2% على Qwen3.5-9B، بينما يخفضها CrossFit إلى 3.0% و3.7% على التوالي. كما تؤدي إعادة تشغيل المقترحات نفسها مع تغذية راجعة تستبعد المصدر إلى خفض الاتفاق الخاطئ إلى 0.4% و0.1%، مما يعزل أثر أصل التغذية الراجعة عن التغيرات في المنهاج المولد. عبر سبع معايير بحث لاحقة، يحسن CrossFit متوسط الأداء مقارنة بالتطور الذاتي المقرون القياسي بمقدار 8.8 و8.4 نقطة، ومقارنةً بـSearch-R1 بمقدار 8.7 و7.8 نقطة عند 4B و9B على التوالي.
One-sentence Summary
Researchers from Rutgers University; University of California, San Diego; University of Michigan; McGill University; and King Fahd University of Petroleum and Minerals diagnose co-cheating in self-evolving search agents and propose CrossFit, a cross-fitted verification scheme that scores proposals with an auxiliary solver trained on disjoint source partitions, reducing false-agreement mass to 3.0% on Qwen3.5-4B and 3.7% on Qwen3.5-9B while improving average performance over standard coupled self-evolution on seven downstream search benchmarks by 8.8 and 8.4 points, respectively.
Key Contributions
- The paper identifies and empirically characterizes a failure mode called co-cheating in self-evolving search agents, where the proposer and solver increasingly agree on shared errors so internal reward improves while source-audited pseudo-label correctness stagnates or declines over successive rounds.
- It proposes multi-sample verification (MSV), which queries the same model three times with source evidence and three times without it to decide task admission and replace unreliable pseudo-labels; MSV lowers false-agreement mass from 6.1% and 8.8% to 5.7% and 7.2% on Qwen3.5-4B and Qwen3.5-9B but leaves substantial residual co-cheating and requires six labeler generations per candidate.
- It proposes CrossFit as the main method, partitioning source documents into groups A and B so questions generated from A are scored by an auxiliary solver trained only on B, and vice versa; CrossFit reduces false-agreement mass to 3.0% and 3.7% and improves seven-benchmark average performance over coupled self-evolution by 8.8 and 8.4 points and over Search-R1 by 8.7 and 7.8 points at 4B and 9B.
Introduction
Search-augmented language models improve answering by interleaving reasoning with retrieval or browser actions, but self-evolving proposer-solver systems create their own training questions and pseudo-labels, using solver agreement as a reward signal. The authors show that this setup can produce “co-cheating”: an incorrect pseudo-label teaches the solver to repeat the same error, and the proposer is then rewarded for generating questions that reinforce that false agreement. Multi-sample verification reduces this problem only partially and adds inference cost. The authors’ main contribution is CrossFit, which splits proposer source documents into groups A and B, trains auxiliary scoring solvers on complementary groups, and uses cross-fitted agreement to shape proposer rewards, preventing a same-source error from directly reinforcing itself. In experiments with Qwen3.5-4B and Qwen3.5-9B, CrossFit lowers false-agreement mass and improves seven-benchmark question-answering accuracy over coupled self-evolution and Search-R1.
Method
The authors introduce two key interventions within the self-evolution loop to mitigate error reinforcement: Multi-Sample Verification (MSV) and Cross-Fitted Proposer Feedback (CrossFit).
First, MSV acts as an admission-time test to ensure a proposed question yields a stable answer independent of the proposer's draft. Given a source document x and a question q, the model M generates three source-aware answers aisrc∼M(⋅∣x,q) and three source-blind answers aiblind∼M(⋅∣q) for i∈{1,2,3}. A majority function Maj returns an answer if at least two samples agree under an answer matcher ≃, and ∅ otherwise. Defining yv=Maj(a1:3v) for v∈{src,blind}, the admission criterion is formulated as:
IMSV=1[ysrc=∅∧yblind=∅∧ysrc≃yblind].When IMSV=1, the compatible majority replaces the draft as the training label; otherwise, the task is rejected. This step improves the quality of supervision entering the training phase.
While MSV refines the training labels, CrossFit prevents this supervision from being directly recycled into the proposer's reward. The overall pipeline for this cross-fitted feedback mechanism is detailed in the framework diagram below.
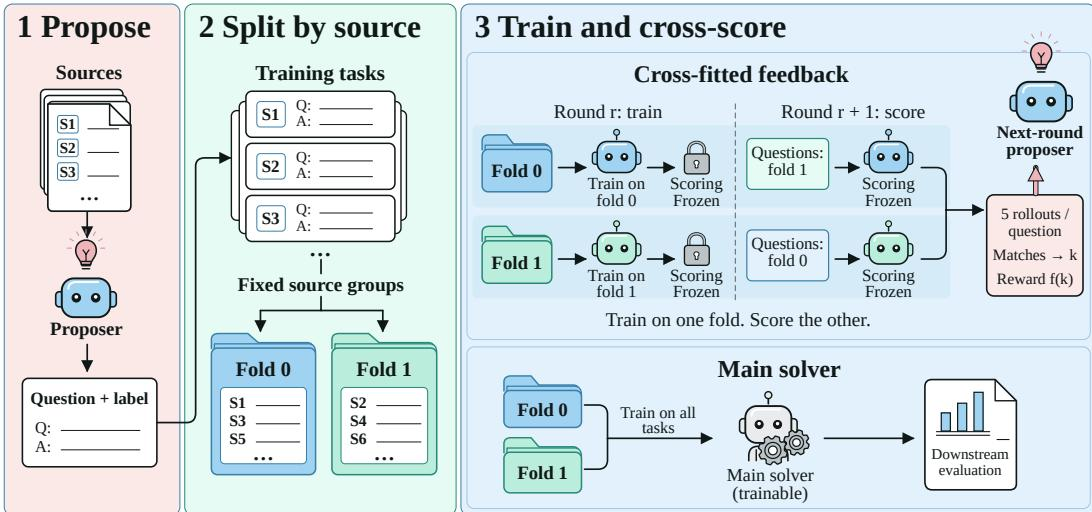
In this architecture, the proposer first generates questions and pseudo-labels from source documents. The authors then partition the source documents into two distinct groups, fold 0 and fold 1. This split is performed at the source level to prevent related examples from the same document from being placed on both sides, which would preserve the data reuse path they aim to eliminate.
The system maintains two auxiliary feedback solvers corresponding to these folds. During round r, one auxiliary solver trains exclusively on admitted questions from fold 0, while the other trains only on fold 1. In the subsequent round r+1, their evaluation roles are crossed: questions originating from fold 0 are scored by the solver trained on fold 1, and questions from fold 1 are scored by the solver trained on fold 0. This ensures that the solver evaluating a specific question has not been trained on pseudo-labels derived from that question's source.
The feedback rule calculates the reward based on the complementary solver's responses. Let h denote the source fold, Sr,1−h the auxiliary solver trained on the complementary fold, and y~ the adopted label. The proposer receives a reward based on five rollouts z1,…,z5:
RP(q)=f(j=1∑51[zj≃y~]),zj∼Sr,1−h(⋅∣q).Here, the function f(k)=(5−k)/4 for 0<k<5 (and zero otherwise) serves as the frontier reward. Consequently, the original training objective is preserved, as questions still receive credit based on their perceived difficulty to the solver, but the direct self-reinforcing error path is broken.
Distinct from the auxiliary solvers, the main solver is not split. It continues to train on all admitted questions from both folds, utilizing the refined feedback to shape the proposer's curriculum for the next round without inheriting the localized source-derived errors.
Experiment
The experiments evaluate self-evolution on seven open-domain question answering benchmarks using Qwen3.5-4B and Qwen3.5-9B, comparing the coupled Dr. Zero loop with multi-sample verification and source-excluded CrossFit feedback over three rounds. Audits of the coupled loop show that proposer-solver agreement becomes increasingly optimistic as false agreement accumulates while correctness does not, revealing a co-cheating dynamic. CrossFit markedly improves downstream search over Dr. Zero and Search-R1, especially on multi-hop tasks, whereas verification alone adds little, indicating that feedback provenance matters more than pseudo-label quality alone. Ablations with fixed question banks and source-level splits confirm that excluding the evaluated source from the feedback solver, rather than evaluator duplication, partitioning, or extra updates, prevents shared same-source errors and accounts for most of the learned search improvement.
Cross-fitted feedback improves downstream search performance at both Qwen3.5 scales, with every evaluated benchmark gaining over the comparison methods. Gains are largest on multi-hop tasks, while verification alone provides only a small average improvement and adds little beyond cross-fitting alone. The results point to feedback provenance as the main factor in the improved search policy. CrossFit improves over Dr. Zero and Search-R1 at both 4B and 9B scales, with all benchmarks gaining. Multi-hop benchmarks show larger average gains than single-hop datasets. MSV alone adds less than one point over Dr. Zero, and combining MSV with CrossFit yields only a small additional improvement.
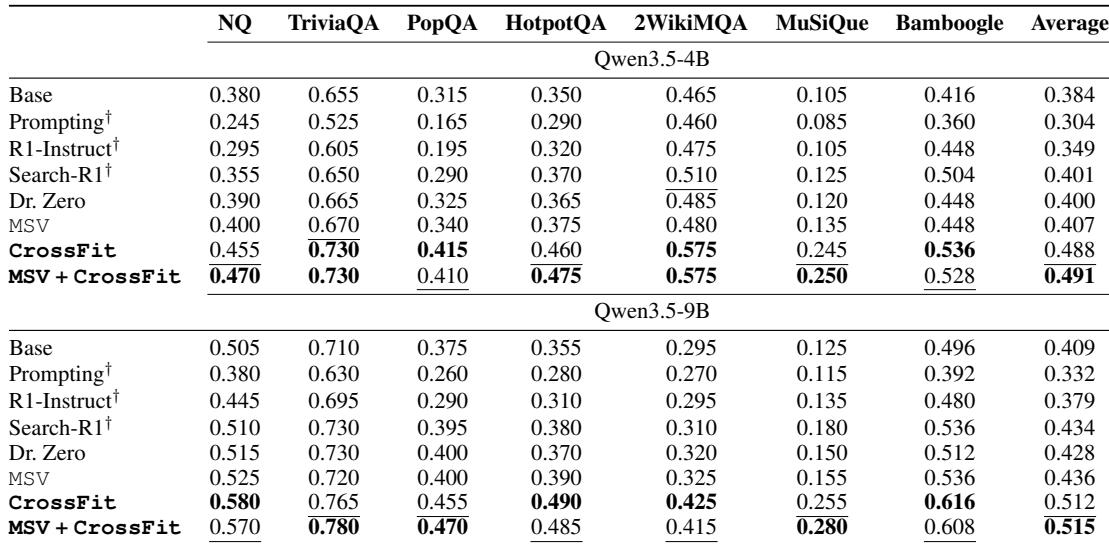
The experiments assess cross-fitted feedback in downstream search using Qwen3.5 at 4B and 9B scales, comparing CrossFit against Dr. Zero and Search-R1. CrossFit consistently improves performance on all benchmarks at both scales, with the largest gains on multi-hop tasks, indicating that feedback provenance is the main driver of the improved search policy. Verification alone provides only marginal average improvement over Dr. Zero and adds little beyond cross-fitting alone, suggesting its contribution is limited.