Command Palette
Search for a command to run...
STEPQuant: متى وأين يهم تأثير الأخطاء في تكميم الحالة المتكررة بقاعدة دلتا
STEPQuant: متى وأين يهم تأثير الأخطاء في تكميم الحالة المتكررة بقاعدة دلتا
Bingchen Yao Haobo Xu Haokun Lin Yichen Wu Ziyu Guo Renrui Zhang Zhichao Lu Zhenan Sun Ying Wei
الملخص
يستبدل الانتباه الخطي ذاكرة KV الوسيطة المتنامية بحالات متكررة ثابتة الحجم، غير أن هذه الحالات الدائمة قد تصبح عنق زجاجة ملحوظًا في الذاكرة عند التقديم المتزامن. وكثيرًا ما يؤدي تكميم الحالات المتكررة بدقة منخفضة مباشرةً إلى تدهور شديد في الدقة، إذ تنتشر أخطاء التكميم عبر تحديثات الحالة المتعاقبة. نكتشف أن تأثير هذه الأخطاء يعتمد على بُعدين متكاملين: زمانيًا، يمكن أن تستمر الأخطاء في الذاكرة طويلة العمر عبر خطوات فك ترميز عديدة؛ ومكانيًا، تؤثر الأخطاء في صفوف المفاتيح المختلفة على مخرجات النموذج بطرق مختلفة، بينما تتباين مقادير الحالة بشكل كبير على امتداد الصفوف والأعمدة. وانطلاقًا من هذه الملاحظات، نقترح STEPQuant، وهو إطار تكميم زماني-مكاني بعد التدريب للحالات المتكررة بقاعدة دلتا. يخصص STEPQuant الدقة وفقًا لمقدار الخطأ وعمر الذاكرة، ويعاير مقاييس صفوف المفاتيح وأعمدة القيم معًا استنادًا إلى توزيعات الحالة وتأثير صفوف المفاتيح على خطأ المخرجات. تُظهر التجارب على Qwen3.8-27B وKimi-Linear-48B-A3B-Instruct عبر معايير توليد طويلة وقصيرة أن STEPQuant يضاهي عن قرب دقة الحالة بمعيار FP32 في ظل ميزانية اسمية قدرها 6 بتات، ويتفوق على تكميم INT8 المنتظم في تكوينه ذي 4 بتات. وعند دمجه في SGLang مع نوى GPU محسّنة، يحقق STEPQuant بتكميم 6 بتات ضغطًا للحالة المتكررة يتجاوز 5 أضعاف ويقلل إجمالي ذاكرة التقديم بنسبة تصل إلى 68.7%.
One-sentence Summary
Researchers from Zhejiang University, CAS, Tsinghua University, et al. propose STEPQuant, a spatial-temporal post-training quantization framework for Delta-rule recurrent states that allocates precision according to error magnitude and memory lifetime while jointly fitting key-row and value-column scales, and it matches FP32-state accuracy at 6 bits on Qwen3.8-27B and Kimi-Linear-48B-A3B-Instruct, achieves over 5× recurrent-state compression, and cuts total serving memory by up to 68.7%.
Key Contributions
- Quantization error impact in Delta-rule recurrent states depends on two complementary dimensions: temporal persistence, where errors in long-lived memory can persist across many decoding steps, and spatial structure, where different key rows affect outputs differently while state magnitudes vary along rows and columns.
- STEPQuant is introduced as a spatial-temporal post-training quantization framework for Delta-rule recurrent states that allocates precision according to error magnitude and memory lifetime, and jointly fits key-row and value-column scales based on state distributions and key-row impact on output error.
- Experiments on Qwen3.8-27B and Kimi-Linear-48B-A3B-Instruct across long- and short-generation benchmarks show that 6-bit STEPQuant closely matches FP32-state accuracy under a nominal 6-bit budget, and its 4-bit configuration outperforms uniform INT8. Integrated into SGLang with optimized GPU kernels, 6-bit STEPQuant achieves over 5× recurrent-state compression and reduces total serving memory by up to 68.7%.
Introduction
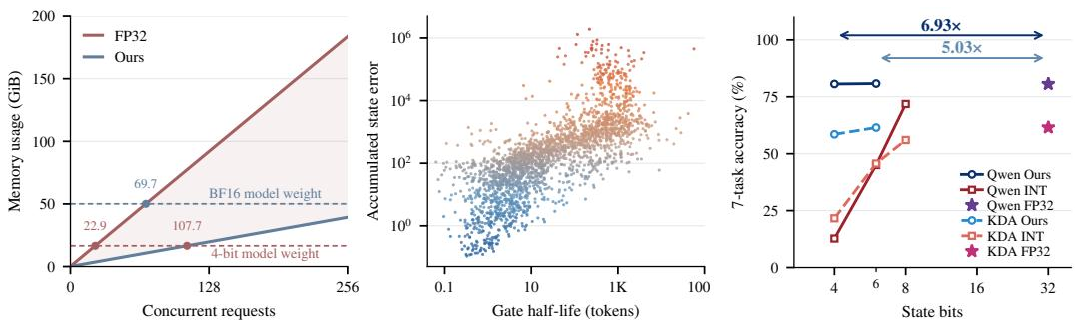
Hybrid linear-attention models such as Qwen3.8-27B and Kimi-Linear-48B-A3B-Instruct replace the growing softmax KV cache with a fixed-size gated Delta-rule recurrent state, but during concurrent serving each request needs its own persistent state, so state-pool memory grows with concurrency and can exceed weight memory even for short contexts. Direct uniform quantization is attractive for reducing this footprint but severely degrades accuracy because errors accumulate temporally through repeated state updates and also depend on spatial location within the state. The authors analyze these error patterns and propose STEPQuant, which combines lifetime-aware mixed-precision bit allocation with key-row-aware dual-axis scaling. Under a nominal 6-bit budget, STEPQuant closely matches FP32-state accuracy on both models, and its 4-bit setting outperforms uniform INT8 while achieving over 5x recurrent-state compression and faster state updates in SGLang.
Method
The authors leverage symmetric uniform quantization to map floating-point recurrent states to a finite set of discrete levels, reducing storage requirements. At each decoding step, the model updates the reconstructed state in floating point and computes the output, after which the updated state is quantized for storage. However, this process recursively feeds quantization error back through the state update. The accumulated error at step t is characterized by the transition matrix, which attenuates existing error through the retention gate and the Delta update. When retention is close to one, errors can persist for many decoding steps. Consequently, recurrent heads with longer gate half-lives tend to accumulate larger state errors, and directly applying uniform quantization severely degrades model performance at low bit widths.
To mitigate temporal error accumulation, the authors propose Lifetime-Aware Bit Allocation, a mixed-precision quantization method that assigns precision under a fixed bit budget based on the persistence of quantization errors. For each recurrent-state unit, they estimate the reconstruction distortion at various bit widths and compute the mean log retention to determine the memory lifetime. The error retention factor after j updates is approximated exponentially, yielding a lifetime weight that accounts for how long the error persists. Given an average bit budget, the method selects bit widths from a candidate set to minimize the lifetime-weighted reconstruction distortion. This objective ensures that units with larger quantization errors and longer memory lifetimes receive higher precision, while the highest-risk units are retained in FP16 as sparse pivots.
Beyond temporal propagation, the authors analyze the spatial distribution of quantization errors within the state matrix. Errors of equal magnitude in different key rows affect the readout differently, depending on the weighting factor derived from the transition matrix and the query vector. To capture this, they define a row-impact score as the expected squared weighting factor over calibration tokens. Quantizing key rows with higher impact scores results in greater perplexity degradation. Furthermore, the recurrent state matrix exhibits large-magnitude outliers along both key rows and value columns, a dual-axis geometry that persists throughout decoding. Unlike conventional quantization that targets a single dominant axis, this two-axis structure necessitates a more flexible scaling approach.
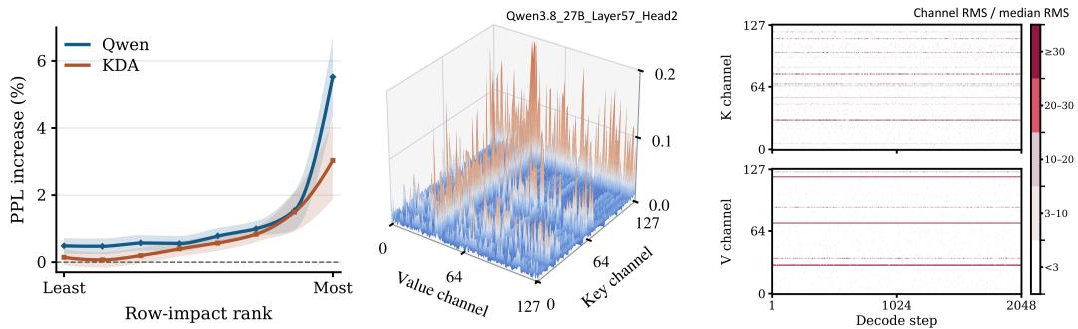
To address the spatial properties of recurrent states, the authors introduce Key-Row-Aware Dual-Axis Fitting, which combines calibrated row-impact scores with separate row and column scales. The updated state is represented as the product of row factors, column factors, and low-bit integers. The row factor for each key row accounts for both its current magnitude and its impact on readout error, utilizing square-root scaling to provide a wider quantization range for larger-magnitude rows and finer resolution for higher-impact rows. Given these row factors, the column scales are fitted by minimizing the impact-weighted reconstruction error, which assigns larger penalties to errors on high-impact key rows. Finally, each scaled entry is quantized to the nearest representable level at its assigned precision.
The authors implement the proposed quantization scheme as packed-state kernels integrated with the SGLang recurrent-state pool. Lifetime-Aware Bit Allocation and FP16 pivot selection are performed offline, ensuring no per-token allocation overhead. During decoding, a fused kernel handles tilewise state reconstruction, the Delta update, and the current readout to reduce memory traffic. Once the head output is available, Key-Row-Aware Dual-Axis Fitting and packed writeback execute on a separate CUDA stream, overlapping scale updates with model computation and keeping the state compressed between tokens.
Experiment
The evaluation uses two linear attention models on SGLang with BF16 and AWQ-quantized weights, covering seven long-generation reasoning benchmarks and six short language understanding tasks. STEPQuant shows that recurrent states can be quantized to 4 to 6 bits with limited accuracy loss, outperforming uniform integer quantization and remaining effective alongside 4-bit AWQ weight quantization. Ablations confirm that spatial key-row-aware fitting and FP16 pivot protection are complementary, while generation-length and efficiency results indicate STEPQuant avoids excessive outputs and substantially reduces memory and state-update costs.
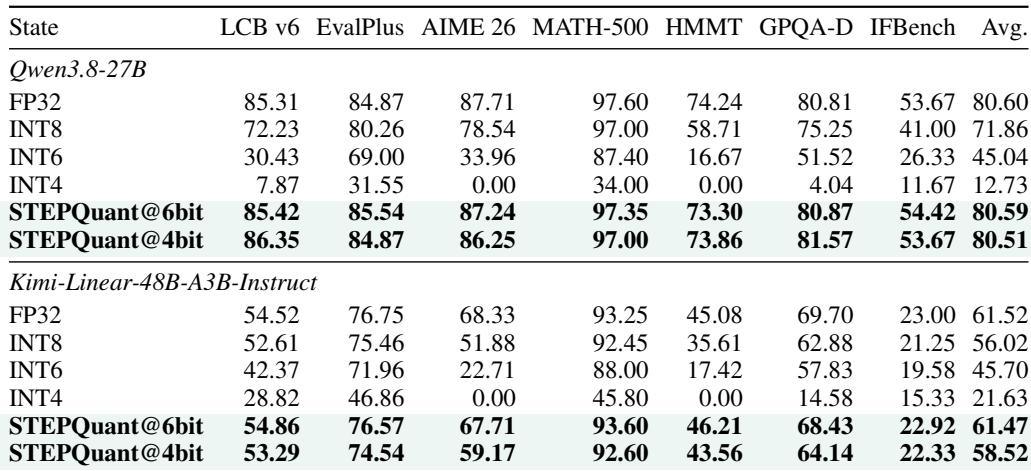
On long-generation reasoning tasks, STEPQuant at both 6-bit and 4-bit closely tracks the FP32-state baseline, while uniform quantization degrades substantially as bit width decreases. Uniform INT4 in particular collapses to near-zero accuracy on several tasks, whereas STEPQuant remains competitive across the seven-task set. These results indicate low-bit recurrent-state quantization can retain long-reasoning accuracy when using STEPQuant. STEPQuant@6bit and STEPQuant@4bit average accuracies are nearly identical to FP32, while uniform INT6 and INT4 fall far below. Uniform 4-bit accuracy drops to zero on tasks such as AIME and HMMT, while STEPQuant@4bit stays close to FP32.
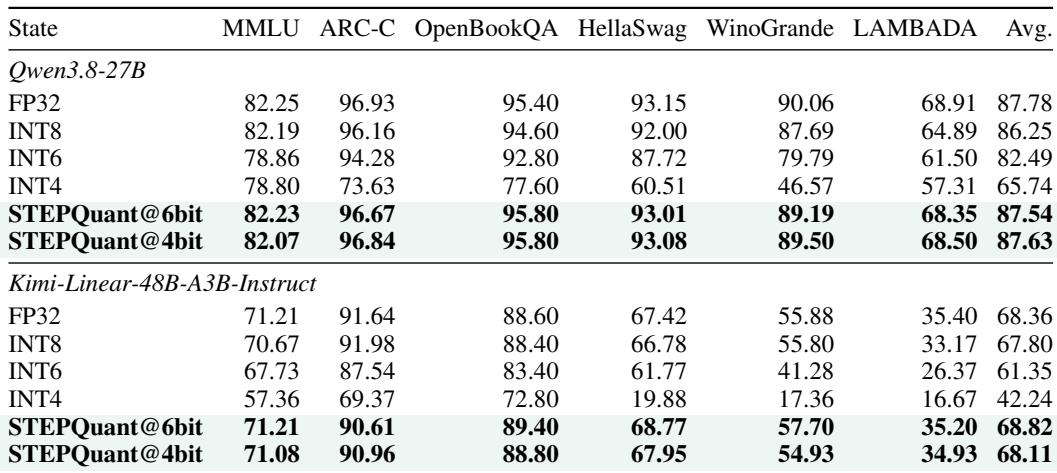
For Qwen short-generation benchmarks, STEPQuant at 6-bit and 4-bit recurrent-state precision closely matches the FP32 baseline. Uniform quantization degrades more as bit width decreases, with uniform INT4 showing severe average and per-task drops. STEPQuant at 4 bits also exceeds the INT8 average while remaining near FP32. STEPQuant at 4 bits trails the FP32 baseline by only 0.15 average points, while uniform INT4 falls from 87.78 to 65.74. On WinoGrande, uniform INT4 drops from 90.06 to 46.57, whereas STEPQuant at 4 bits retains 89.50.
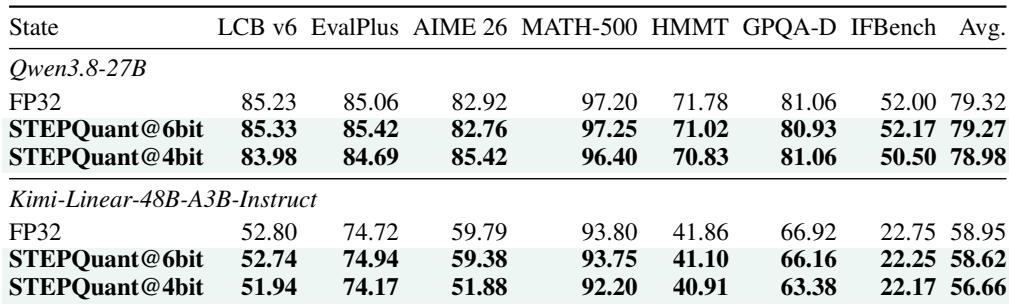
With 4-bit AWQ-quantized weights, 6-bit STEPQuant state compression nearly matches FP32-state reasoning accuracy on both Qwen and Kimi. The Qwen 4-bit state configuration also remains close to its FP32-state baseline. This indicates that STEPQuant stays effective when combined with weight quantization. 6-bit STEPQuant has seven-task average accuracy within a fraction of a point of the FP32-state baseline on Qwen and Kimi. On Qwen, the 4-bit state configuration remains competitive with FP32-state accuracy and even improves on some individual tasks. Combining STEPQuant with AWQ weight quantization preserves reasoning performance, supporting memory-efficient deployment.
Ablation on Qwen long-reasoning tasks shows that spatial key-row-aware fitting and temporal mixed-precision allocation with FP16 pivots both improve accuracy over uniform and baseline quantization. The full STEPQuant combination substantially outperforms each component alone and closely tracks FP32 accuracy at 6 bits. Removing pivot protection or using uniform quantization causes large accuracy declines. Spatial-only quantization outperforms the Q-Mamba baseline, indicating that key-row-aware dual-axis fitting improves long-reasoning accuracy. Protecting a small fraction of heads with FP16 pivots yields substantial gains over temporal allocation without pivot protection. Combining spatial and temporal components produces the best quantized accuracy, closely matching FP32 under the 6-bit budget. Uniform INT6 quantization falls far behind FP32 and the component variants, confirming the need for the proposed protections.
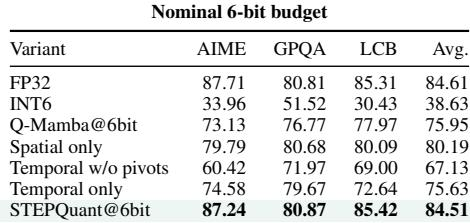
The evaluation covers long-generation reasoning tasks, short-generation benchmarks, combined weight quantization, and an ablation of STEPQuant's components. STEPQuant at 6-bit and 4-bit recurrent-state precision closely tracks the FP32-state baseline on long-generation tasks, while uniform quantization degrades sharply and uniform INT4 often collapses to near-zero accuracy. Short-generation results similarly show 4-bit STEPQuant staying near FP32 and even outperforming uniform INT8, and the method remains effective when combined with AWQ weight quantization. Ablations confirm that spatial key-row-aware fitting and temporal mixed-precision allocation with FP16 pivots both contribute, and their combination yields quantized accuracy close to FP32 under low-bit budgets.