Command Palette
Search for a command to run...
MaLiang-Harness: مسار قابل للبرمجة لتوليد الصور والفيديو
MaLiang-Harness: مسار قابل للبرمجة لتوليد الصور والفيديو
Haoyu Zhao Zihao Zhang Xudong Wang Jiaxi Gu Zuxuan Wu Yu-Gang Jiang Shuicheng Yan
الملخص
تقدم البرامج القابلة للتنفيذ تحكمًا صريحًا في كيفية بناء الصور والفيديو، غير أن توليد كود قابل للتشغيل لا يمثل سوى بداية الإنشاء البصري. فقد ينفذ البرنامج تنفيذًا صحيحًا بينما يخل بالتركيب أو المظهر أو الحركة المطلوبة. نعرّف هذا التباين بأنه فجوة «من البرنامج إلى المرئي» (P2V)، ونقدم MaLiang-Harness، وهو إطار عمل موحد لتنظيم التوليد البصري الموجّه بنماذج MLLM في عملية مستمرة من البناء والفحص والمراجعة. يتمثل تصميمه المحوري في جعل البرنامج البصري المتطور وسجل بنائه والتحقق منه تتقاسم مرجعًا موحدًا للمراجعة. نعرّف حالة «التوليد التنفيذي المستمر» (PEG) بأنها تحافظ على البرامج وسياق المهمة. وتربط «عملية التوليد القابلة للتتبع» (TGP) التعديلات بالأدلة المُصيَّرة، بينما يدعم «التحرير والتحقق المدركان للمراجعة» (REV) الاستعادة ويتحقق من المراجعة الحالية قبل الإكمال. وتعمل هذه الآليات معًا على تنسيق التخطيط والتنفيذ والتغذية الراجعة البصرية عبر خلفيات عرض مختلفة. نقيم 11 نموذجًا قويًا مغلق المصدر من نماذج MLLM على MaLiang-IBench وأربعة نماذج على MaLiang-VBench، مع قياس نجاح التوليد والجودة البصرية والتكلفة الحسابية. يحقق GPT-6-Astra نجاحًا في التوليد بنسبة 100% على كلا المعيارين، حيث استوفت 96.0% من مهام الصور و76.9% من مهام الفيديو جميع عتبات الجودة. وتكشف المقارنة أيضًا عن عدم تطابق بين درجات القدرة العامة وأداء التوليد البصري؛ إذ تختلف النماذج الحاصلة على درجات متشابهة اختلافًا كبيرًا في قدرتها على تلبية المتطلبات البصرية. يوفر MaLiang-Harness أساسًا منهجيًا لدراسة كيفية ترجمة نماذج MLLM للكود القابل للتنفيذ إلى نتائج بصرية، مما يكشف عن إمكانات التوليد القابل للبرمجة وعن قيود المعايير العامة بوصفها مؤشرات على هذه القدرة. المشروع متاح على الرابط https://github.com/gulucaptain/MaLiang-Harness.
One-sentence Summary
Researchers from the National University of Singapore, Fudan University, and Tencent propose MaLiang-Harness, a unified framework that addresses the Program-to-Visual gap in MLLM-driven image and video generation through Persistent Executable Generation, Traceable Generation Process, and Revision-aware Editing and Verification, and evaluate it on MaLiang-IBench and MaLiang-VBench, where GPT-6-Astra achieves 100% generation success.
Key Contributions
- Introduces and defines the Program-to-Visual (P2V) gap as the discrepancy between program-level correctness and visual requirement satisfaction, framing visual program generation as a stateful process of construction, inspection, and revision.
- Presents MaLiang-Harness, a unified framework for programmable image and video generation whose Persistent Executable Generation state, Traceable Generation Process, and Revision-aware Editing and Verification support continued refinement, inspection of construction histories, and verification of current outputs across rendering backends.
- Evaluates 11 MLLMs on MaLiang-IBench and four on MaLiang-VBench for generation success, visual quality, and computational cost. GPT-6-Astra achieves 100% generation success on both benchmarks, and models with similar general capability scores show substantially different visual generation outcomes.
Introduction
Recent high-quality image and video generation has largely followed direct visual synthesis, where models learn visual data distributions and produce pixels or latent representations, but this process remains implicit. At the same time, multimodal large language models have made programmable generation more practical by expressing creative intent as executable visual programs that a renderer converts into output. A key challenge is the Program-to-Visual (P2V) gap: a program can run correctly while still producing an image or video that misses the user's visual requirements, and prior work lacks a unified stateful mechanism for inspection and revision across image and video backends. The authors introduce MaLiang-Harness, a framework that maintains persistent executable state, records a traceable generation process, and ties revision-aware verification to each update, letting models refine visual programs through rendered feedback. Evaluation on MaLiang-IBench and MaLiang-VBench shows that generation success and visual quality can vary widely across MLLMs, even among models with similar general capability scores.
Method
The authors leverage MaLiang-Harness to explore an alternative path to image and video generation. Instead of relying on diffusion or flow-matching processes, the framework uses a Multimodal Large Language Model (MLLM) to translate a prompt into executable visual programs through a unified generation interface.
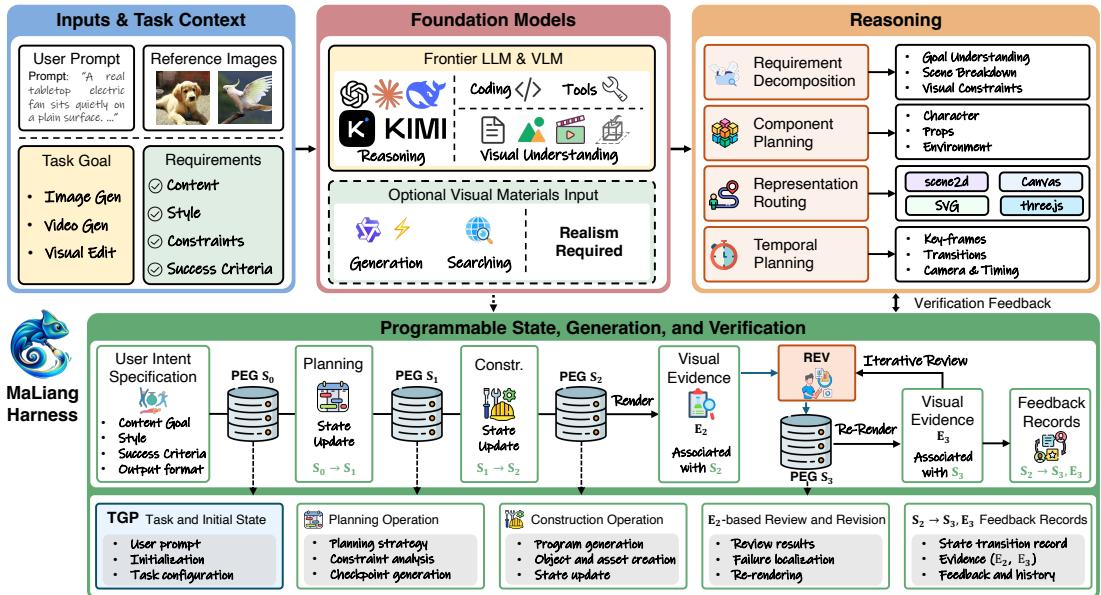
The framework employs MLLM planning and code generation to construct expressive visual compositions, which renderers then turn into images and videos. Visual feedback guides the iterative refinement of the generation under explicit spatial and temporal control. The system is built upon three core components: a persistent executable generation state, a traceable generation process, and revision-aware editing and verification.
MaLiang-Harness provides a shared interaction protocol across various rendering backends, such as Canvas, SVG, Scene2d, or Three.js. Given a prompt p and output specification ω, the system plans the appearance, spatial composition, and temporal dynamics, selects an executable representation and compatible backend b, and generates drawing and animation code. The backend renders the resulting representation into an image or video that the MLLM evaluates against task requirements.
To manage this process, the harness maintains a Persistent Executable Generation (PEG) state. At revision k, the state is defined as Sk=(Pk,Ak,Zk,Ck,k), where Pk denotes the visual program with its backend identifier, Ak contains associated assets, Zk describes spatial composition and temporal dynamics, and Ck retains the generation context including the prompt and requirements. State updates are distinguished from visual rendering. An edit ak commits a new state Sk+1=E(Sk,ak), while the renderer evaluates the visual program at content time t to produce Ik(t)=Rb(Sk,t;ω).
While the PEG state preserves the executable visual representation, the Traceable Generation Process (TGP) records how this representation is constructed. For the j-th recorded operation, the harness maintains τj=(oj,xj,yj,kj−,kj+), where oj is the executed operation, xj and yj are its input arguments and execution result, and kj− and kj+ identify the source and resulting PEG revisions. This traceability connects recorded program changes with revision-specific visual evidence, allowing the system to diagnose discrepancies between the intended visual result and the executed code.
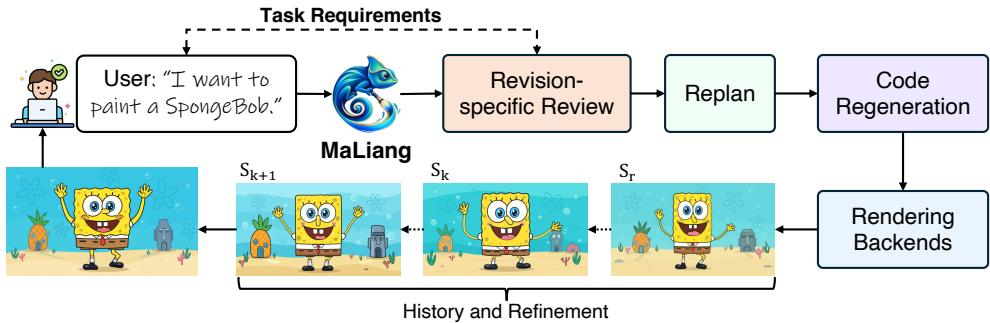
Finally, Revision-aware Editing and Verification (REV) closes the generation loop. For each visual requirement hi in Ck, REV maintains a review qi=(ki,Ei,vi), where Ei contains requirement-specific visual evidence from revision ki and vi represents the verification status. A review applies to the current state only when ki=k. The current revision is ready for delivery only when Ready(Sk)=ExportOK(Sk)∧CheckpointOK(k)∧⋀hi∈Hk[ki=k∧Ei=∅∧vi=pass]. This criterion ensures that visual verification is strictly tied to the delivered revision, grounding subsequent code revisions in observed visual discrepancies rather than execution success alone.
Experiment
The experiments evaluate MaLiang-Harness on MaLiang-IBench and MaLiang-VBench using text-to-image and text-to-video prompts across multiple DeepSeek, Kimi, and GPT models, measuring both computational cost and generation quality. Comparisons show a notable gap between successful generation and meeting all visual quality criteria, with GPT-6 models generally stronger and motion coherence emerging as the main limiting factor for video outputs. Qualitative and discussion results further indicate that richer rendering backends can improve realism, general benchmark scores only partially predict visual program generation performance, and the harness supports inspection of construction and revision processes while still facing refinement stalls and token-limit failures.
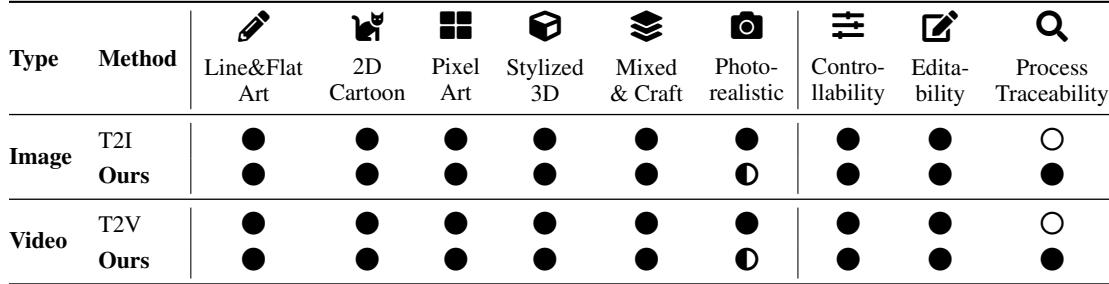
Existing image and video generation models cover a broad range of creative styles and offer controllability and editability, but their process traceability is not established. MaLiang-Harness supports the same style coverage except for partial photorealism, while adding an inspectable creation process. This aligns with its use of executable visual programs for explicit control, targeted editing, and traceable construction. Existing T2I and T2V models support all listed creative styles, whereas MaLiang-Harness has partial support for photorealism. MaLiang-Harness matches existing models on controllability and editability and adds process traceability. Its executable visual program approach provides explicit control, targeted editing, and an inspectable creation process.
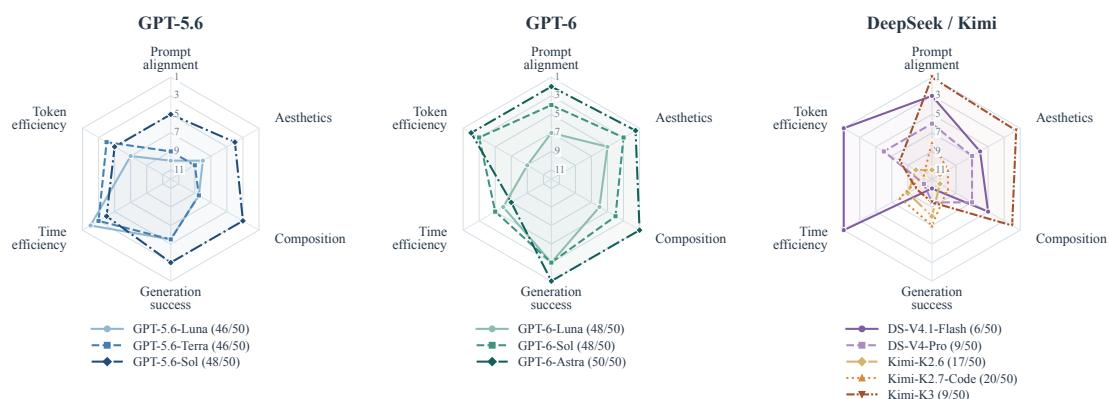
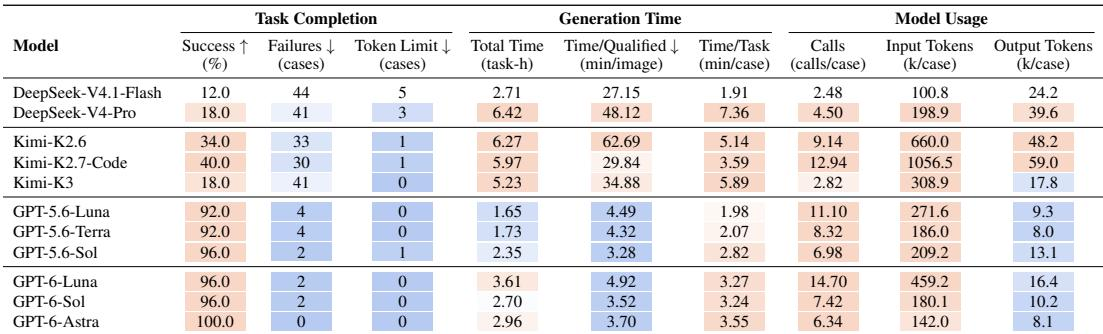
Generation success and computational cost vary widely across the evaluated models: GPT-5.6-Luna reaches much higher success and fewer token-limit failures than the DeepSeek and Kimi models shown, while requiring less total time and less time per qualifying image. Success alone does not guarantee visual quality, since many GPT-5.6 generations complete but only about half satisfy all three quality criteria, whereas GPT-6-Astra combines near-perfect generation success with high quality pass rates. Lower-success models tend to spend more time per usable image, so their quality scores must be interpreted with their smaller number of successful outputs. GPT-5.6-Luna achieves substantially higher generation success and no token-limit failures, with lower total time and time per qualifying image than the DeepSeek and Kimi models shown. Higher completion rates do not always mean higher visual quality: GPT-5.6-Luna and Terra generate most images, but only about half meet all three quality thresholds, while GPT-6-Astra meets them on nearly all tasks.
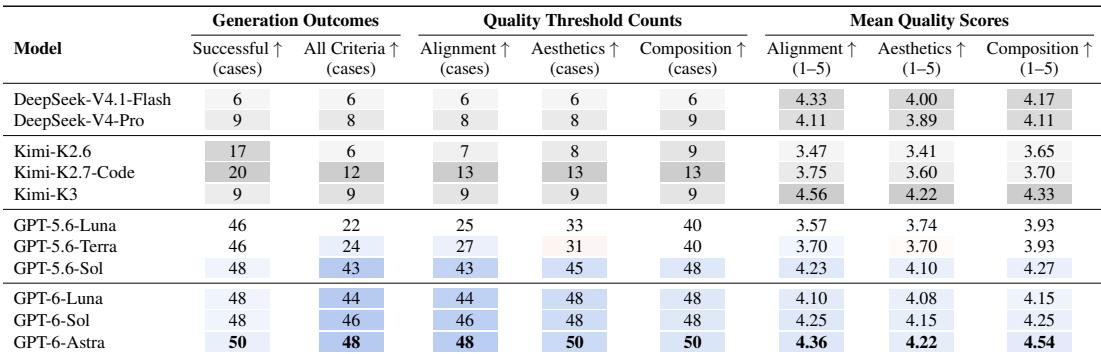
On MaLiang-IBench, generation success is distinct from meeting all visual quality thresholds. GPT-6 models, especially GPT-6-Astra, achieve broad generation success and stronger quality outcomes, with aesthetics and composition largely satisfied and prompt adherence accounting for most remaining failures. DeepSeek and Kimi models generate far fewer successful images, so their mean quality scores reflect limited subsets and are less comparable. Generation success is consistently higher than the share of outputs meeting all three quality thresholds. GPT-6-Astra achieves the highest generation success and the highest mean quality scores among GPT models, with all successful images meeting aesthetics and composition thresholds. For GPT-6 models, remaining quality failures concentrate on prompt adherence rather than aesthetics or composition. DeepSeek and Kimi models have low generation success, so their mean quality scores describe only a small subset of tasks and should be interpreted cautiously. Some DeepSeek and Kimi models post high mean scores on limited successful samples, but this does not establish superior performance across the full benchmark.
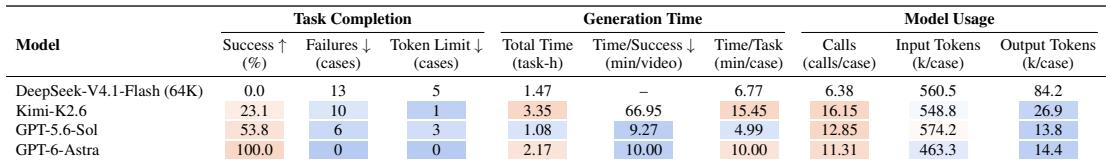
MaLiang-VBench reveals a clear gap between generating a video and meeting all quality thresholds. GPT-6-Astra achieves complete generation success with no failure or token-limit cases, while GPT-5.6-Sol is faster per successful video and per case but completes fewer tasks and yields fewer fully qualifying outputs. Kimi-K2.6 completes some tasks but none meet all criteria, and its time per successful generation is the highest among the listed models. GPT-6-Astra is the only listed model with complete task success and zero failure or token-limit cases, and it produces the most outputs satisfying all quality thresholds. GPT-5.6-Sol has lower time per successful video and per case than GPT-6-Astra, but its completion rate and fully qualifying output count are lower, showing a speed-quality trade-off. Kimi-K2.6 shows no fully qualifying videos and has the highest time per successful generation among models with successful generations.
On MaLiang-VBench, GPT-6-Astra achieves the strongest visual quality outcomes among the listed models, with the most successful generations and the most cases satisfying all quality thresholds. GPT-5.6-Sol shows lower but substantial quality, with a majority of its successful generations meeting all criteria. Kimi-K2.6 completes a small number of tasks without any all-criteria case, and DeepSeek-V4.1-Flash produces no evaluated or quality-passing cases. GPT-6-Astra leads the listed models in successful generations, all-criteria cases, and alignment, aesthetics, composition, and motion counts. GPT-5.6-Sol clears all quality thresholds in a majority of its successful generations, whereas Kimi-K2.6 completes a few tasks with no all-criteria case and DeepSeek-V4.1-Flash produces no evaluated cases.
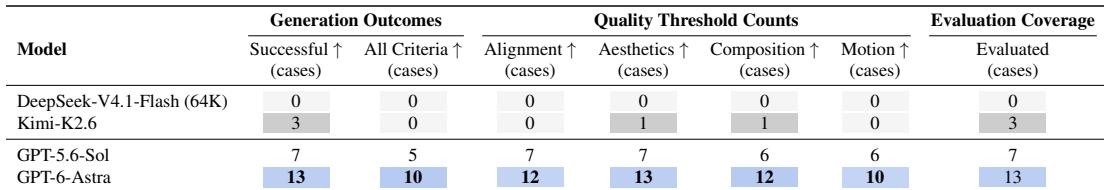
These experiments evaluate MaLiang-Harness against existing text-to-image and text-to-video models on style coverage, controllability, editability, process traceability, generation success, visual quality, and computational cost. MaLiang-Harness matches existing models on control and editing while adding an inspectable executable visual program process, with only partial photorealism. On MaLiang-IBench and MaLiang-VBench, completing a generation is consistently distinct from satisfying all quality thresholds, and GPT-6-Astra shows the strongest overall results by combining high completion rates with near-universal quality, while its remaining image failures concentrate on prompt adherence. Lower-success models such as DeepSeek, Kimi, and some GPT-5.6 variants either produce too few usable outputs for comparable quality scores or trade speed for fewer fully qualifying videos.