Command Palette
Search for a command to run...
SPEAKERMEM-R1: ذاكرة ثنائية المسار متمركزة حول المتحدث للحوار متعدد الأطراف
SPEAKERMEM-R1: ذاكرة ثنائية المسار متمركزة حول المتحدث للحوار متعدد الأطراف
Haobo Zheng Tan Tang Yan Chen Weijie Wang Yingcai Wu
الملخص
تتطلب الذاكرة المحادثية طويلة الأمد في السياقات متعددة الأطراف أكثر من مجرد استرجاع محتوى ذي صلة من المحادثات الطويلة: إذ يجب أن تميّز من قال ماذا، وبمن يتعلق كل تصريح، وكيف ينظر الأفراد إلى بعضهم بعضًا، وما المعلومات التي تتقاسمها المجموعة، وكيف تتغير الحالات بمرور الوقت. وتُظهر دراسات حديثة على معايير الحوار متعدد الأطراف أن أنظمة الذاكرة القائمة على نماذج اللغة الكبيرة ذات الأغراض العامة تميل إلى فقدان علاقات الأشخاص والمجموعات أو تواجه صعوبة في دمج الأدلة الموزعة عبر الأعضاء والمجموعات والزمن. وتكشف هذه القضايا مجتمعةً عن اختناقين أساسيين: إسناد الرسائل والفهم العلائقي في الحوار متعدد الأطراف، وإعادة بناء الحالة من سجلات متداخلة. ولمعالجة كليهما، نقترح SPEAKERMEM-R1: تخزن ذاكرته ثنائية المسار رسائل حرفية موسومة بالمتحدث وحالات مشتقة منظمة في عروض على مستوى الشخص ومستوى المجموعة، ثم تدمج الأدلة من المسارين حسب الكيان والحدث والزمن وقت الاستعلام. ولتقليل أخطاء الإسناد والتحديث أثناء بناء الذاكرة المنظمة مع تمكين النشر المحلي، ندرّب Writer-R1 باستخدام SpeakerLevenshtein وGRPO المشروط بالمتحدث. وعلى Group-MemBench وSocialMemBench وEverMemBench، يحقق SPEAKERMEM-R1 دقة ثنائية قدرها 47.9% و69.2% و61.9% على التوالي. وتفوق هذه النتائج أفضل نتائج الأطر السائدة المقيَّمة على كل معيار بمقدار 3.3 و12.4 و9.4 نقطة مئوية على التوالي. وعلى لوحة صدارة EverMemBench المنشورة علنًا من EverMind-AI، يحقق SPEAKERMEM-R1 دقة 62.33%، وهي أفضل نتيجة منشورة بين أحدث الأطر المتطورة. كما يحقق 70.85% على جميع أسئلة LoCoMo البالغ عددها 1,986 سؤالًا، والتي نستخدمها اختبارًا حدوديًا للمحادثة طويلة الأمد بين شخصين. وفي تقييم مضبوط على 305 أسئلة، يرفع التعلم المعزز متوسط دقة SFT Writer من 57.38% إلى 68.20% في ظل خط أنابيب استعلام/إجابة مجمَّد. ونورد كلًا من الدقة الثنائية وtoken-F1، وتُظهر دراسات الاستئصال أن المسار الحرفي والمسار المنظم، وكذلك عروض مستوى الشخص ومستوى المجموعة، متكاملة في ظل واجهة التقييم الموحدة.
One-sentence Summary
Researchers from State Key Lab of CAD&CG, Zhejiang University propose SPEAKERMEM-R1, a dual-track memory system that stores speaker-labeled verbatim messages and structured person-level and group-level states, is trained with SpeakerLevenshtein and speaker-conditioned GRPO, improves multi-party dialogue memory benchmarks by up to 12.4 points, and achieves 62.33% on EverMemBench.
Key Contributions
- Introduces SPEAKERMEM-R1, a dual-track memory system that stores speaker-labeled verbatim messages and derived states in person-level and group-level views, then combines evidence from both tracks by entity, event, and time for multi-party conversational recall.
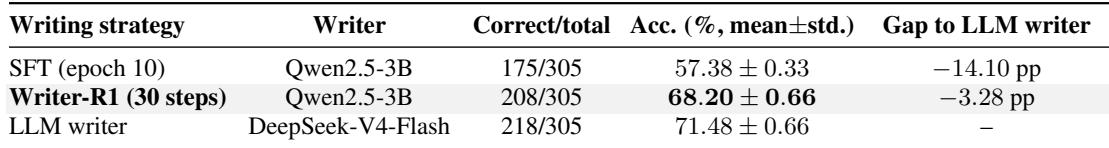
- Trains a Writer component with SpeakerLevenshtein and speaker-conditioned GRPO to reduce attribution and update errors while enabling local deployment; in a controlled 305-question evaluation, RL raises the SFT Writer’s mean accuracy from 57.38% to 68.20% under a frozen query/answer pipeline.
- Reports binary accuracy of 47.9%, 69.2%, and 61.9% on Group-MemBench, SocialMemBench, and EverMemBench, exceeding the best results of mainstream frameworks evaluated on each benchmark by 3.3, 12.4, and 9.4 percentage points, plus 62.33% on the EverMemBench leaderboard as the best reported result among latest state-of-the-art frameworks and 70.85% on all 1,986 LoCoMo questions. Ablations show the verbatim and structured tracks and the person-level and group-level views are complementary.
Introduction
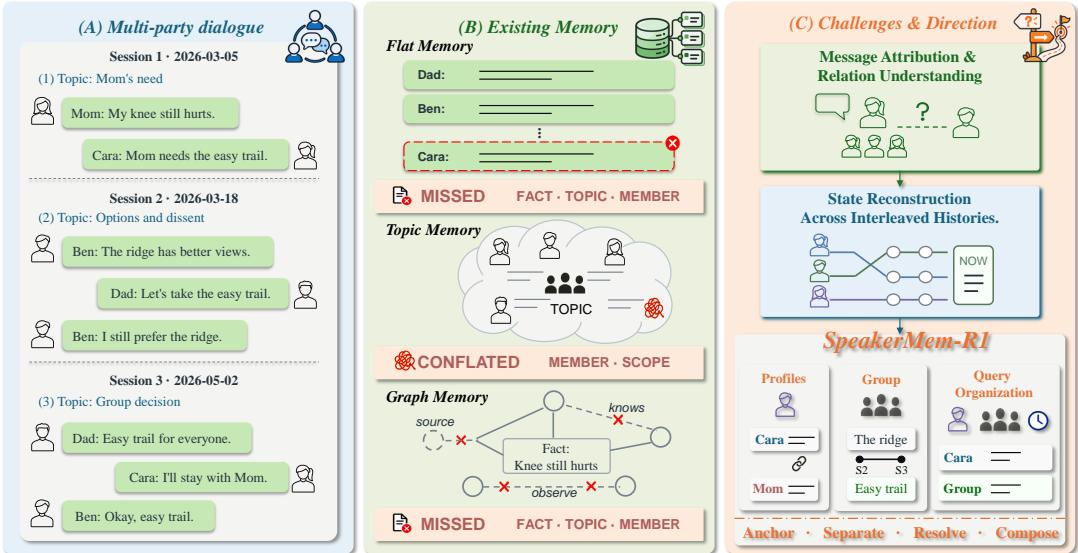
Long-term conversational memory helps language agents retain facts, preferences, and social relations across sessions, but most prior systems target single-user or two-person histories and compress conversations into flat message streams. Multi-party group chats add speaker relations, reply structure, cross-topic branches, and state revisions, so general-purpose memory frameworks degrade even when lexical or dense retrieval remains competitive. The core challenges are message attribution, such as who said what and whether information is shared or personal, and state reconstruction, which requires recovering current or historical states from clues distributed across members and time. The authors propose SPEAKERMEM-R1, a dual-track memory system that preserves traceable speaker-labeled messages alongside provenance-linked person- and group-level structured views, then uses Anchor-Separate-Resolve-Compose query-time organization and a locally deployable Qwen2.5-3B Writer trained with SpeakerLevenshtein and speaker-conditioned GRPO to reduce attribution and update errors.
Method
The authors propose SPEAKERMEM-R1, a system designed to process multi-party message streams by constructing a traceable dual-track memory and retrieving query-specific evidence for a frozen answerer. Given a dialogue stream D={ut}t=1T where each utterance ut contains text, speaker, time, and channel information, the system first writes the messages into memory M, then retrieves evidence Eq and generates an answer y^.
As shown in the figure below:
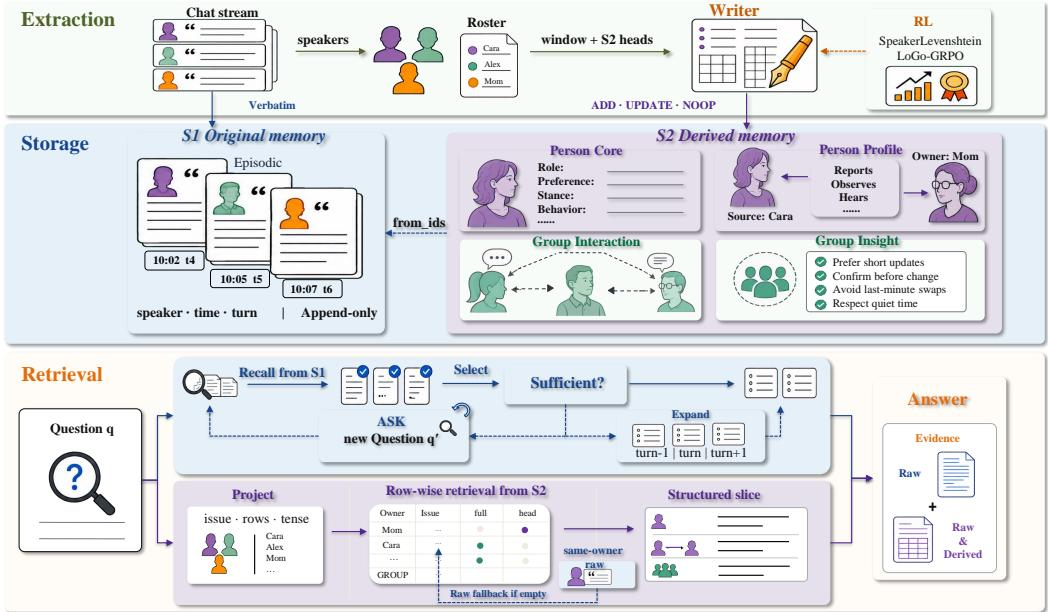
The overall architecture operates through extraction, storage, retrieval, and answering stages. The Writer is the core component responsible for converting local messages into structured memory actions, while the retrieval and answering stages operate on the resulting memory.
The storage module maintains a five-layer traceable dual-track memory. System 1 serves as the only verbatim layer, storing each message with its exact text, speaker, time, and channel in an append-only manner. System 2 is a four-layer derived structure comprising PERSON-scoped Core and Profile layers, along with GROUP-scoped Interaction and Insight layers. The PERSON layers capture stable identity, facts, stances, and cross-person cognition, while the GROUP layers track cross-speaker events, relations, and group norms. Every derived record is represented as a structured tuple containing content, source, owner, scope, event, time, state, and source reference. This design explicitly separates who provides the information from whom the content concerns, and links every derived record to its supporting messages in System 1.
During the retrieval phase, the system generates query-conditioned evidence. A Project module compiles the query and deterministic roster into common query constraints, specifying the target persons or groups, issue constraints, temporal mode, and source-owner constraints. Retrieval proceeds along two independent paths. System 1 retrieves exact wording and local context, optionally expanding neighboring messages. System 2 expands the relevant PERSON or GROUP rows and selects records matching the issue, relation, event, and time constraints. If a derived row is empty, the system falls back to the corresponding verbatim messages. Finally, a Compose operation organizes the evidence from both tracks along persons, relations, and update chains before passing it to the frozen answerer.
To enable efficient local deployment, the authors leverage reinforcement learning to train a small model to replace an expensive prompt-based Writer. The RL process trains the ADD, UPDATE, and NOOP decisions of the Writer, while System 1 writing, query organization, and answering remain frozen. The training utilizes a local-to-global return mechanism. Local structural signals evaluate owner-level writing errors using SpeakerLevenshtein, which combines token-level F1 with a normalized sequence-matching rate to perform coordinate-consistent matching within owner buckets. The local structural potential is defined as:
ΦSL(M,M⋆)=w1∣P∣1p∈P∑Fp+w2p∈PminFpwhere P is the owner set and Fp is the matching result for owner p. This macro-average term measures the overall state, while the worst-owner term prevents frequent participants from masking infrequent ones.
The global signal measures the downstream QA gain of System 1 plus System 2 over System 1 alone. The return at writing position t on trajectory g combines validity, memory structure, and QA gain:
rg,t=wvalidRg,tvalid+wmemRg,tmem+Pg,t+wQAγT−1−tRgQAThe authors sample multiple trajectories for the same network, compute group-relative advantages only at the same writing positions, and update the Writer using clipped GRPO.
Experiment
The evaluation uses GroupMemBench, SocialMemBench, and EverMemBench, with LoCoMo as a two-person boundary test, comparing the proposed system against retrieval and memory baselines. Results show that the dual-track memory method improves multi-party question answering across benchmarks, with ablations confirming that per-speaker and group tracks contribute complementarily and that the hierarchical design matters. The full R1 objective substantially improves a small writer model over supervised fine-tuning, though the gain is not evidence of broad cross-domain generalization. Remaining weaknesses concentrate on multi-hop, open-domain, cross-evidence, preference, and role-attribution questions.
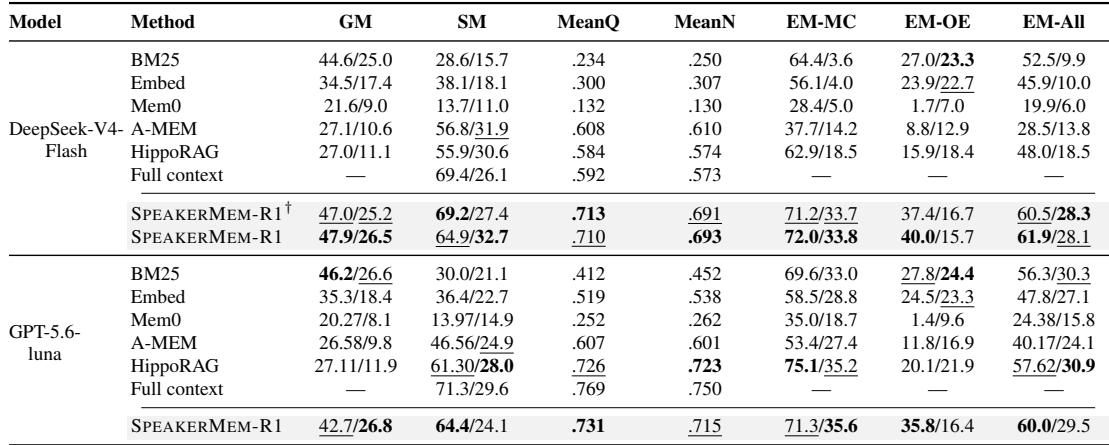
SPEAKERMEM-R1 achieves the best non-full-context accuracy across the reported multi-party memory benchmarks, with the strongest relative improvements on SocialMem and EverMem over the top mainstream baselines. Full context is only feasible on SocialMem, where the method nearly matches full-context accuracy; accuracy and token-F1 are not always aligned because overlapping answers can still be invalidated by scope or extra-person errors. The proposed method outperforms the strongest retrieval and memory baselines on all three benchmarks, with larger gains on SocialMem and EverMem. On SocialMem, the method approaches full-context accuracy while full context is unavailable for the other benchmarks.
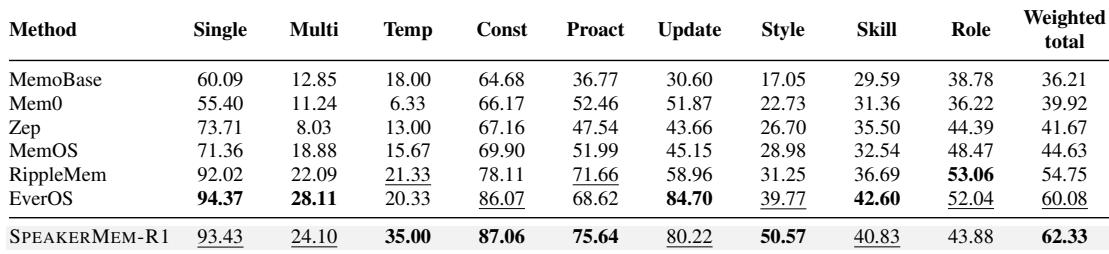
Under the public EverMemBench configuration using GPT-4.1-mini for answering and Gemini-3-Flash for judging, SPEAKERMEM-R1 achieves the highest question-weighted accuracy at 62.33%, ahead of EverOS and RippleMem. Its category-level strengths include single, constraint, proactive, update, temporal, and style, while multi, skill, and role are weaker. EverOS leads several individual categories but falls behind overall due to lower style and temporal scores. SPEAKERMEM-R1 leads the weighted total at 62.33% and is the top method in temporal, constraint, proactive, and style categories. EverOS has the best single, multi, update, and skill category scores, but its lower temporal and style results leave it second overall. Multi is the lowest-scoring category across all methods, with the best result only 28.11%. Role accuracy remains a shared bottleneck, with the best result just above 53% from RippleMem.
Reinforcement learning substantially improves the small writer over supervised fine-tuning on held-out SocialMem networks. It closes most of the accuracy gap to the LLM writer reference under the same frozen query and answer protocol, though the reference remains slightly ahead. The RL-trained writer gains about 11 percentage points over the SFT writer and answers 33 additional questions correctly. The gap to the LLM writer narrows from about 14 points for SFT to about 3 points for the RL-trained writer, reaching over 95% of the reference accuracy.
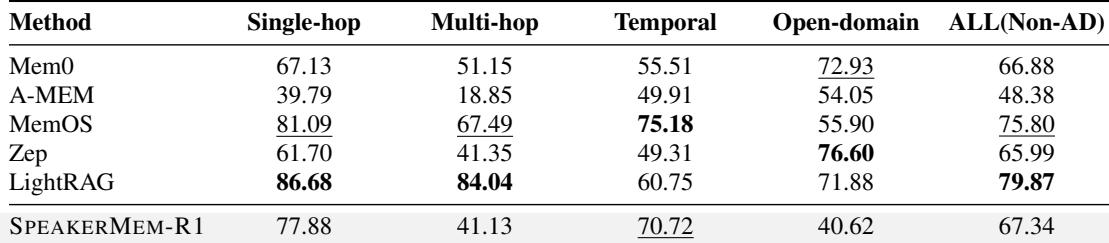
On the LoCoMo non-AD categories, LightRAG and MemOS lead overall, with LightRAG strongest on single-hop and multi-hop questions. SPEAKERMEM-R1 is competitive on temporal and single-hop categories but ranks near the bottom on multi-hop and open-domain questions, leaving its aggregate non-AD accuracy below the top two methods. Multi-hop and open-domain questions remain notable weak spots for SPEAKERMEM-R1. LightRAG records the highest overall non-AD accuracy and leads the single-hop and multi-hop categories, while MemOS is the strongest temporal method and second overall. SPEAKERMEM-R1 places second on temporal questions but is among the weakest methods on multi-hop and open-domain questions, with aggregate accuracy below LightRAG and MemOS.
The experiments evaluate SPEAKERMEM-R1 on multi-party memory benchmarks, the EverMemBench configuration, a reinforcement learning writer on held-out SocialMem networks, and LoCoMo non-AD categories. The method achieves the strongest non-full-context results on multi-party benchmarks and leads EverMemBench overall, with particular strengths in temporal, constraint, proactive, and style categories, while multi and role questions remain shared bottlenecks. Reinforcement learning substantially improves the small writer over supervised fine-tuning, narrowing most of the gap to the LLM writer reference. On LoCoMo non-AD questions, LightRAG and MemOS lead overall, with SPEAKERMEM-R1 competitive on temporal queries but weaker on multi-hop and open-domain questions.