Command Palette
Search for a command to run...
كسر سقف الرموز: تقطير نماذج بايت أصغر وأقوى
كسر سقف الرموز: تقطير نماذج بايت أصغر وأقوى
Kalyani Marathe Artidoro Pagnoni Tomasz Limisiewicz Margaret Li Mike Lewis Luke Zettlemoyer Srinivasan Iyer
الملخص
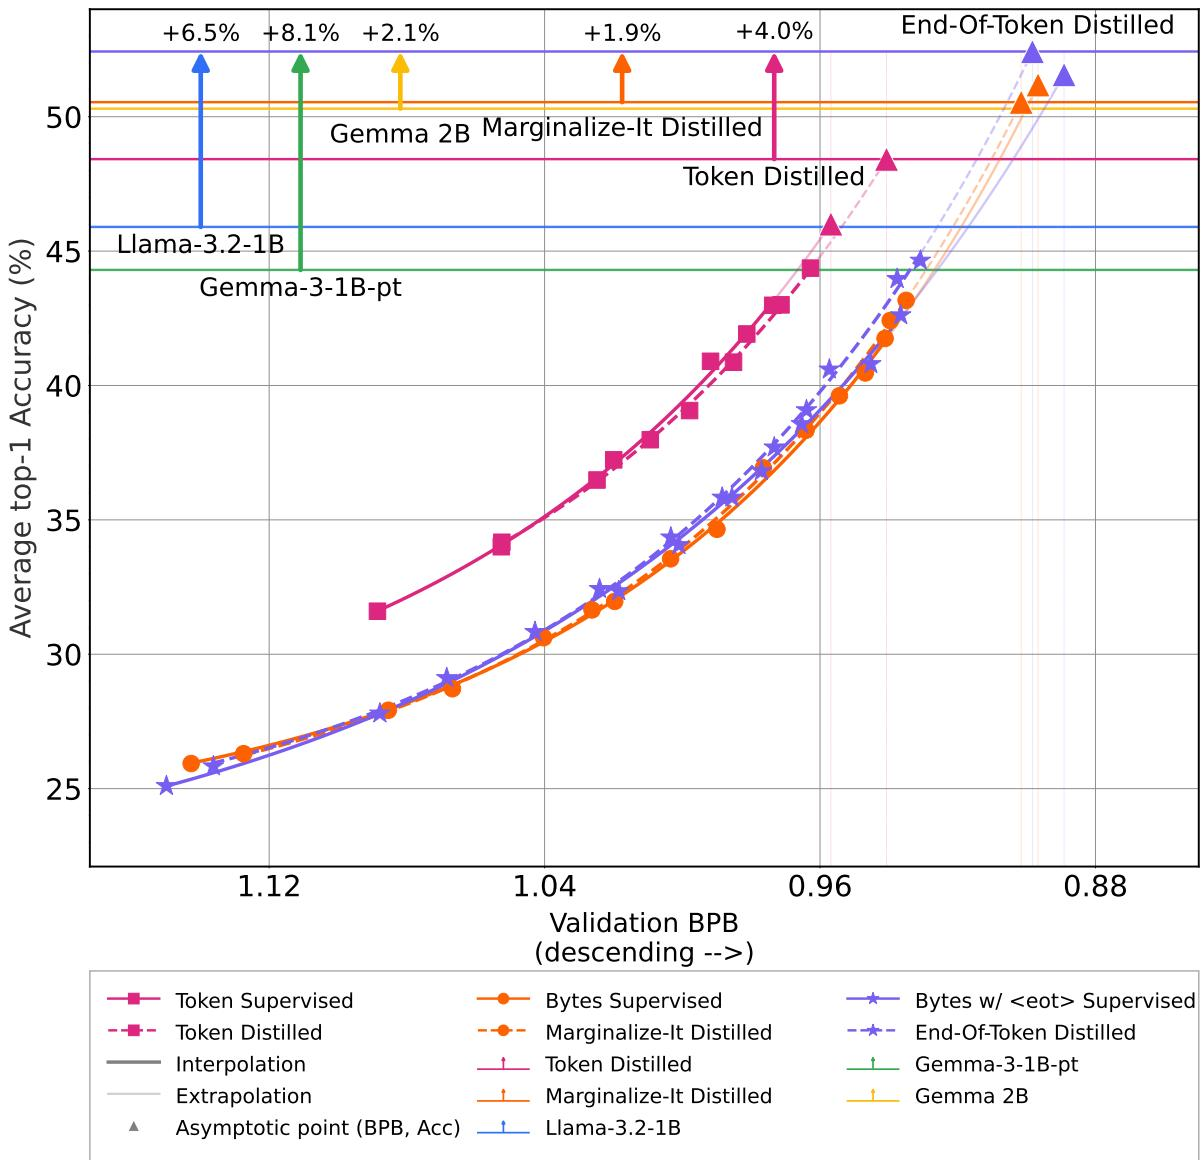
تُعزز قدرات النماذج الصغيرة من خلال التقطير من نموذج أكبر يتشارك معها في مخطط الترميز. ومع ذلك، هل تتصرف نماذج البايت والنماذج الرمزية المقطرة بشكل مشابه من حيث اتجاهات التوسع مع زيادة الحوسبة والبيانات؟ لتمكين هذه المقارنة، نقدم متغيرين لتحويل لوجيتات الرموز إلى لوجيتات بايت بكفاءة: 1) تقريبي: Marginalize-It، و2) دقيق: End-Of-Token. ثم نقدم أول دراسة واسعة النطاق للتدريب المفرط لنماذج المحولات الكثيفة التي تتبع بنية الترميز فقط (decoder-only)، مع تغيير بُعدين في وقت واحد: مخطط الترميز (الرموز، البايتات، البايتات مع ) وهدف التدريب (التقطير مقابل الإنتروبيا المتقاطعة)، مع مسح نماذج متطابقة في عدد الطبقات والمعلمات بحوالي مليار معلمة حتى تريليون بايت من البيانات. عبر ثمانية معايير تغطي ثلاث فئات: الاختيار من متعدد لفهم القراءة، وتوليد اللغة، والترجمة الآلية، نجد أن نماذج Token-1B تتفوق على نماذج البايت (End-Of-Token-1B وBytes-1B) في نطاق الحوسبة المنخفضة (FLOPs) لكنها تصل في النهاية إلى مرحلة استقرار؛ بينما تبدأ نماذج البايت بأداء أسوأ لكنها تتجاوز نماذج Token-1B مع زيادة الحوسبة، لتصل إلى سقف أعلى في أداء المهام النهائية. استقراء قوانين التوسع لمتوسط الخطأ من النوع الأول مقابل BPB للتحقق يتنبأ بأنه، بشكل مقارب، يتفوق نموذج End-Of-Token-1B المقطر على نموذج Token-1B المقطر بنسبة تصل إلى 4% في متوسط أداء المهام النهائية. كما أنها أكثر كفاءة في استخدام البيانات بكثير، حيث تحقق أداءً يعادل نموذج Token-1B المقطر باستخدام سدس كمية بيانات التدريب فقط. علاوة على ذلك، من خلال العمل على مفردات صغيرة تبلغ حوالي 256 بايت بدلاً من حوالي 100 ألف رمز، فإنها تتجاوز الحاجة إلى اقتطاع أعلى k أثناء تفريغ اللوجيتات، مع تقليل تكاليف تخزين اللوجيتات إلى حوالي الخمس. أخيرًا، تتنبأ قوانين التوسع الخاصة بأداء المهام النهائية بأن نماذج End-Of-Token-1B المقطرة لدينا تتجاوز بشكل مقارب نماذج Llama 3.2-1B (Meta AI، 2024) وGemma-3-1B-pt (Kamath et al.، 2025) وGemma 2B (Team et al.، 2024) في متوسط المهام النهائية بنسب تصل إلى 6.5% و8.1% و2.1% على التوالي.
One-sentence Summary
Researchers from the University of Washington and Meta FAIR introduce Marginalize-It and End-Of-Token to distill token logits into byte logits, showing that overtraining 1B-parameter dense transformers reveals byte models surpass token models with more compute, achieving up to 4% higher downstream performance and 6× data efficiency, while reducing logit storage to 51.
Key Contributions
- Introduces two methods for converting token-level logits into byte-level logits: Marginalize-It, an approximate approach that marginalizes prefix-matched token distributions, and End-Of-Token, an exact approach that adds an
<eot>token to preserve the teacher distribution, avoiding the computational cost of multiple inference passes. - Presents the first large-scale scaling study of decoder-only dense transformer models with about 1.28 billion layer parameters, sweeping tokenization schemes (Tokens, Bytes, Bytes with
<eot>) and training objectives (distillation vs. cross-entropy) across up to 1 trillion bytes, showing that byte models start worse but surpass token models in downstream performance with more compute, while matching token-model performance with one-sixth of the training data. - Across eight benchmarks and extrapolated scaling laws, distilled End-Of-Token-1B models asymptotically outperform distilled Token-1B by up to 4% on averaged downstream tasks, reduce logit storage costs to roughly one-fifth by operating over a 256-byte vocabulary instead of about 100K tokens, and are predicted to surpass Llama 3.2-1B, Gemma-3-1B-pt, and Gemma 2B by up to 6.5%, 8.1%, and 2.1%, respectively.
Introduction
Scaling has become the dominant strategy for improving language model performance, but real-world deployment also demands cost efficiency. Models are often distilled into smaller, capable versions or overtrained to amortize inference costs, yet it remains unclear how the choice of student tokenization interacts with these techniques as compute scales. Prior work on converting token logits to byte logits for distillation required multiple forward passes, which is prohibitively expensive when teacher inference is costly. The authors address this by introducing two single-pass logit conversion methods: Marginalize-It (approximate) and End-Of-Token (exact), which preserve the teacher distribution without top-k truncation. They conduct a large-scale scaling study across training objectives and tokenization schemes, fitting power laws for validation bits-per-byte and downstream task performance. Their findings show that distilled byte models, particularly the End-Of-Token variant, improve at a steeper rate with compute and asymptotically surpass token-based distillation, while also offering data and storage efficiency gains.
Dataset
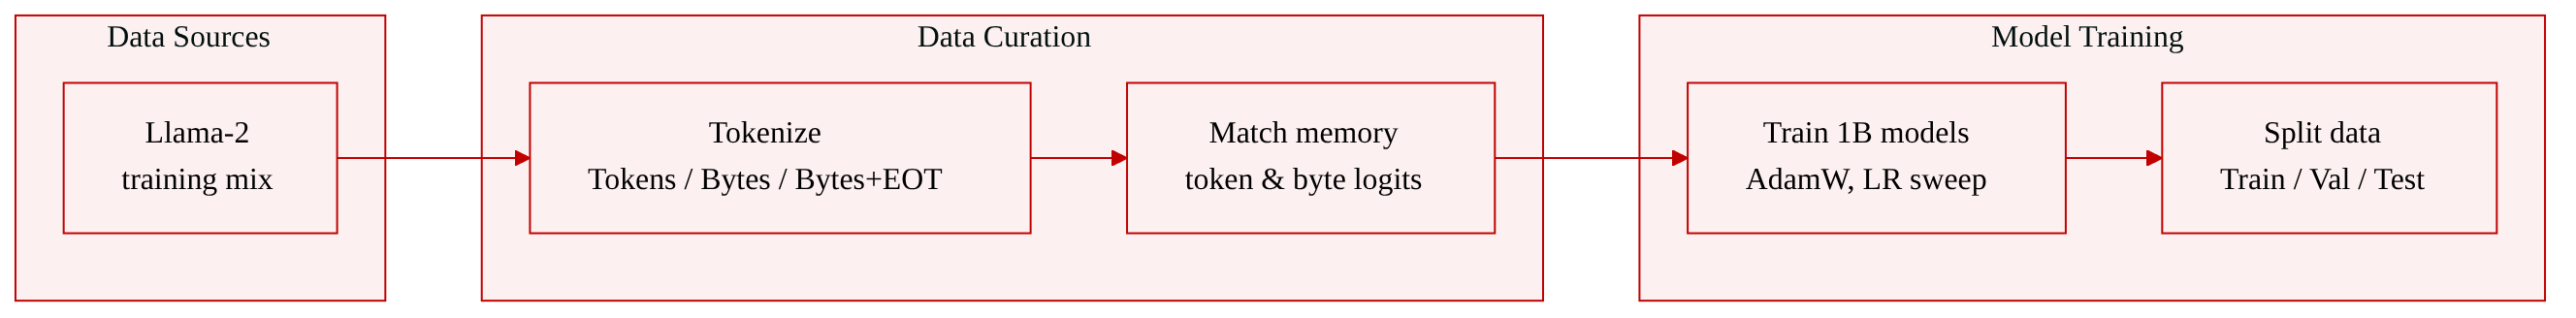
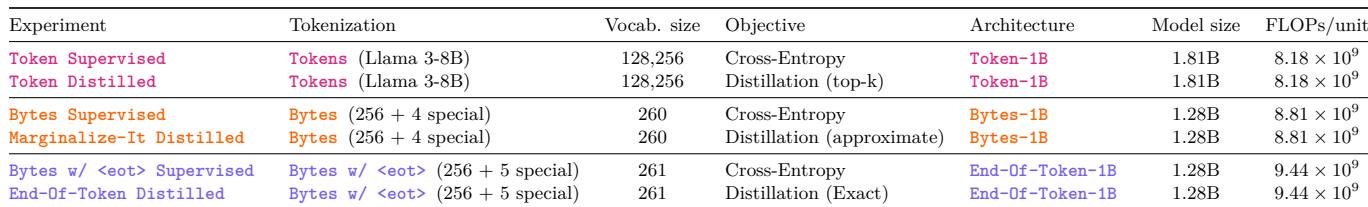
The authors design their experiments around three model variants, all with approximately 1 billion parameters and matched layer parameters: Token-1B, Bytes-1B, and End-Of-Token-1B. While the total layer parameters are equal (1.28B), Token-1B is larger overall (1.81B) due to its bigger vocabulary size. All models use the Llama-3 transformer implementation.
For training data, the authors use the Llama-2 training mixture for both supervised and distillation experiments. The study is structured so that token logits and byte logits occupy the same memory footprint for the same amount of data, with a full storage cost breakdown provided in Appendix A.6.
The experimental setup includes six distinct settings that explore scaling along two axes: tokenization schemes (Tokens, Bytes, Bytes with <eot>) and training objectives (Supervised Cross-Entropy Loss and Distillation). These settings are detailed in Table 1, with model sizes and FLOPs per unit values sourced from Table 9. For the Marginalize-It and End-Of-Token distillation variants, the authors apply a logit conversion process described in Section 2.
Training uses the AdamW optimizer with a learning rate sweep over three values (1e-3, 4e-3, 8e-3) and 10% warmup steps for each data scale. Additional loss function details are provided in Appendix A.3.
Method
The authors leverage two methods, Marginalize-It and End-Of-Token, to efficiently convert token logits to Byte Logits during their scaling study.
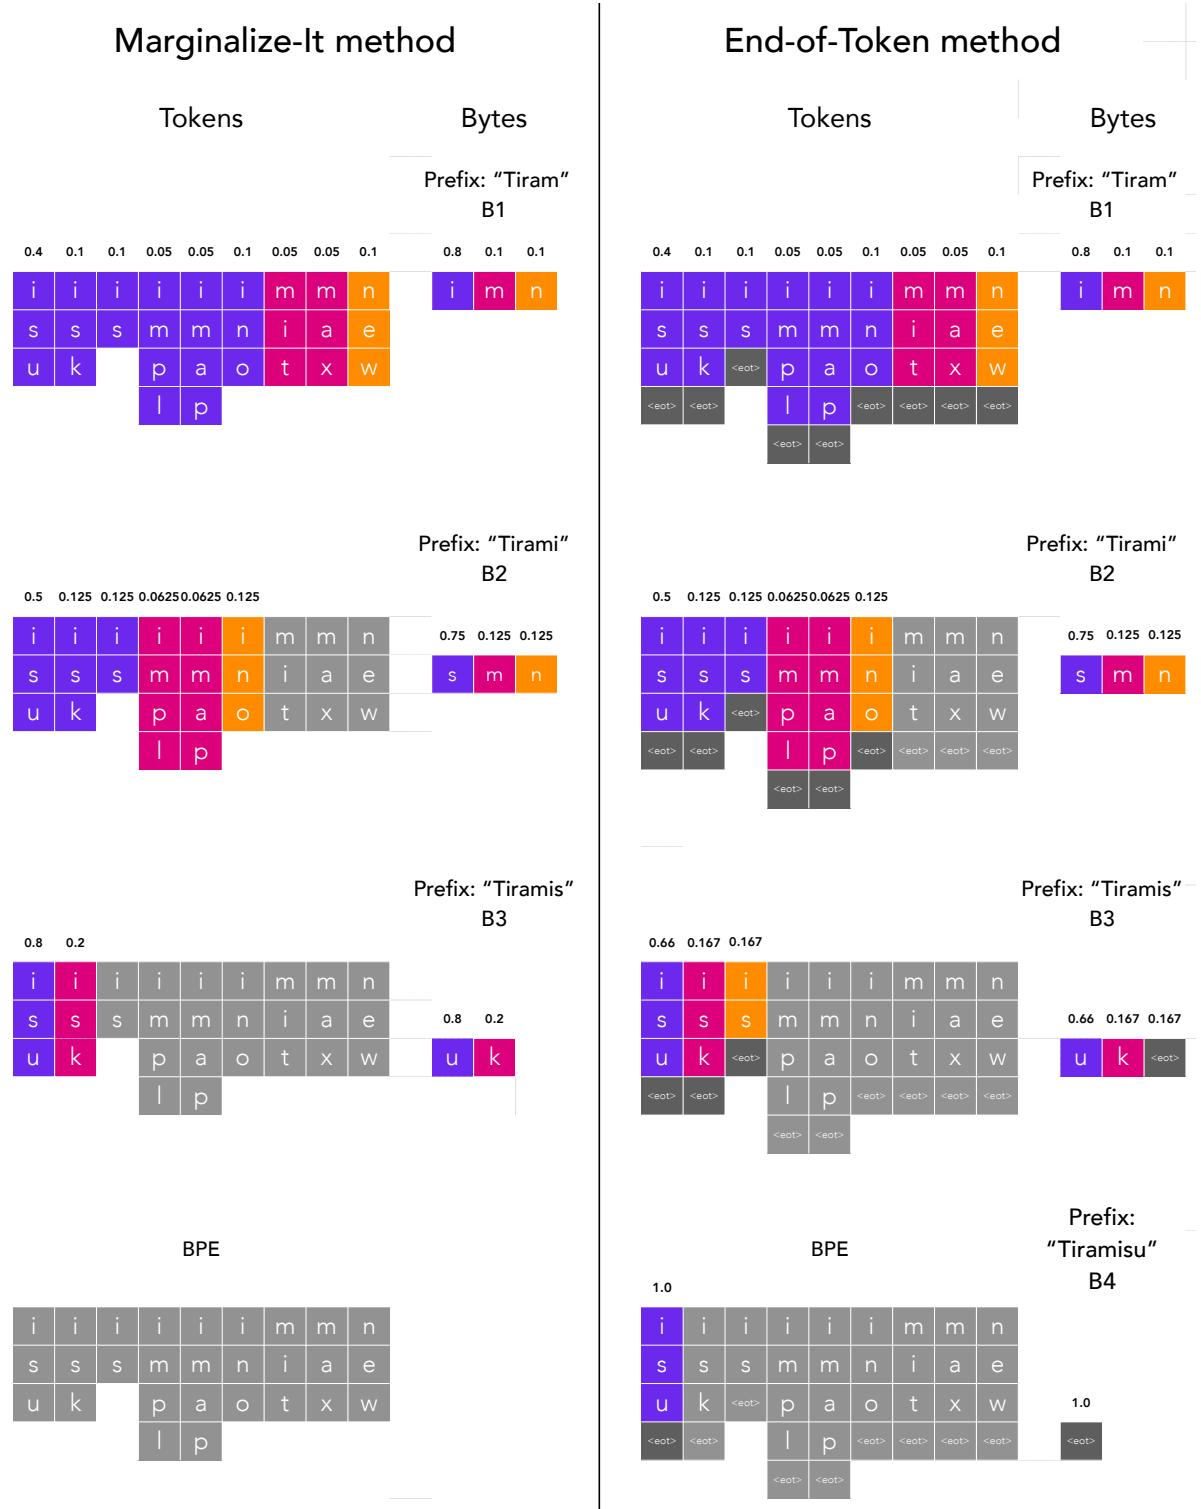
For the Marginalize-It method, the authors start with a ∣V∣-sized logit tensor from the teacher inference, where V is the vocabulary of the BPE tokenizer. To compute the first byte distribution of each BPE token, they marginalize over the full vocabulary V based on the first byte. For subsequent bytes, they restrict the vocabulary to tokens whose prefixes match the ground-truth bytes and compute the byte distribution conditioned on this subset. While this yields an exact distribution for the first byte, subsequent byte distributions are approximate. For instance, when predicting the distribution for the third byte, continuations of a token might be silently dropped, and the remaining probability is redistributed among the surviving tokens. For example, the probabilities are recalculated as:
P(isu)=0.5+0.1250.5=0.8,P(isk)=0.5+0.1250.125=0.2.To address the missing-probability problem inherent in the Marginalize-It approach, the authors introduce the End-Of-Token method. This method appends an <eot> token to mark the end of each BPE token and expands the byte vocabulary by one to store the <eot> probabilities. Marginalization is then applied over byte positions to form the byte logits. During training, an <eot> token is appended after every BPE token in the pretraining dataset. This approach is exact and absorbs the probability mass of possible continuations into the <eot> token without requiring additional teacher inferences. For the same third byte prediction, the probabilities become:
As shown in the figure below:
The authors utilize a transformer architecture to train layer-parameter-matched models with approximately 1 billion parameters, specifically Token-1B, Bytes-1B, and End-Of-Token-1B variants. While the three architectures have equal total layer parameters (1.28B), the Token-1B model is larger overall due to its larger vocabulary size. The design choices follow the Llama-3 implementation. For training, they employ the Llama-2 training mixture for supervised and distillation experiments, ensuring that token logits and byte logits occupy the same amount of memory for the same amount of data. The models are trained using the AdamW optimizer, with a sweep over three learning rates ∈{1e-3,4e-3,8e-3} and 10% warmup steps for each data scale.
Experiment
The study evaluates token and byte-level models, with and without distillation, across multiple choice QA, language generation, and machine translation benchmarks. Distilled models consistently outperform their supervised counterparts in both validation bits-per-byte (BPB) and downstream task performance, though token models start stronger at lower compute budgets while byte models improve faster and eventually catch up. A key finding is that lower BPB does not always imply better downstream performance across different tokenization schemes and training objectives, as byte models can achieve better BPB yet worse task accuracy. The End-Of-Token distilled method shows the best asymptotic downstream performance, requiring less text data and reducing storage costs by up to one-fifth compared to token distillation.
The study compares six model configurations that vary by tokenization scheme and training objective, all matched in layer parameters but differing in vocabulary size and FLOPs per unit. Distilled models, especially those using end-of-token tokenization, show distinct scaling behaviors, with end-of-token distillation achieving better asymptotic downstream performance and efficiency in data and storage costs compared to token-based distillation. End-of-token distilled models outperform token-distilled models in asymptotic downstream performance while requiring less text data and reducing storage costs. Bytes-based and end-of-token models can surpass token-supervised models in bits-per-byte but perform worse on downstream tasks, highlighting the importance of calibration. At low compute budgets, token-distilled models lead in performance, but end-of-token distilled models overtake bytes-based models as compute increases and eventually match or exceed them.
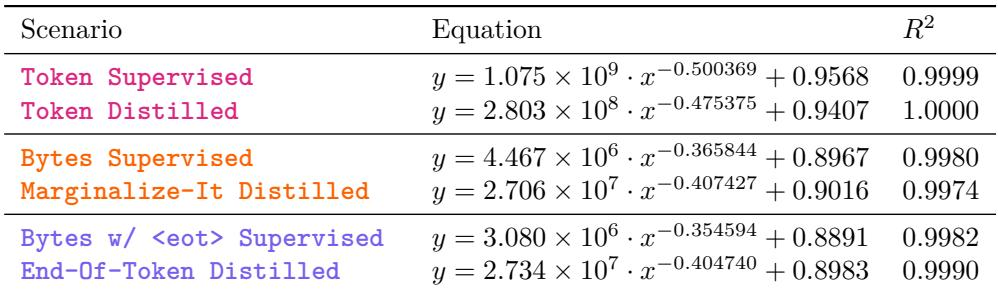
Power-law fits to validation BPB versus training FLOPs show that distilled methods achieve lower asymptotic BPB than their supervised counterparts across token and byte-based training. The fits are highly accurate, with R-squared values near 1.0, and byte-based supervised training reaches the lowest asymptotic BPB. Distilled methods consistently outperform supervised counterparts in asymptotic BPB. Byte-based supervised training has the lowest asymptotic BPB among all scenarios. All fitted power laws exhibit very high R-squared values, indicating strong fit quality.
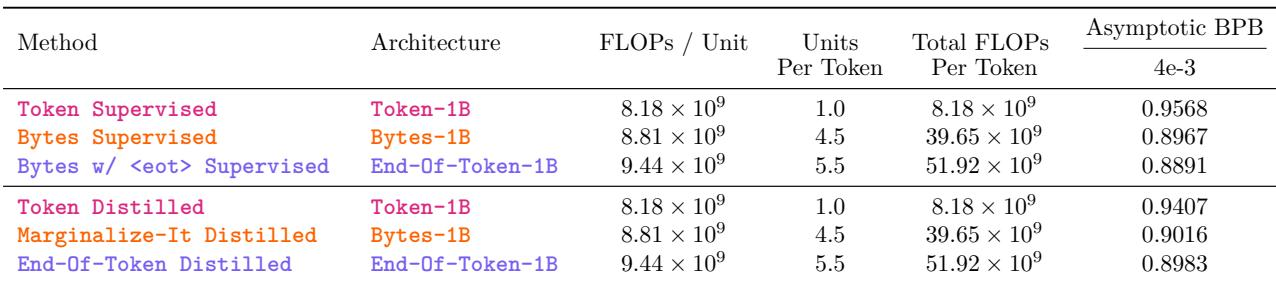
Increasing total FLOPs per token consistently lowers asymptotic BPB for both supervised and distilled models, with distilled variants outperforming their supervised counterparts. The End-Of-Token architecture spends about 31% more FLOPs per token than the Bytes-1B model, yet achieves the lowest asymptotic BPB among the compared setups. Distilled models achieve lower asymptotic BPB than their supervised counterparts across all architectures. End-Of-Token-1B uses approximately 30.94% more FLOPs per token than Bytes-1B, but attains the best asymptotic BPB. Higher total FLOPs per token correlates with lower asymptotic BPB for both supervised and distilled models.
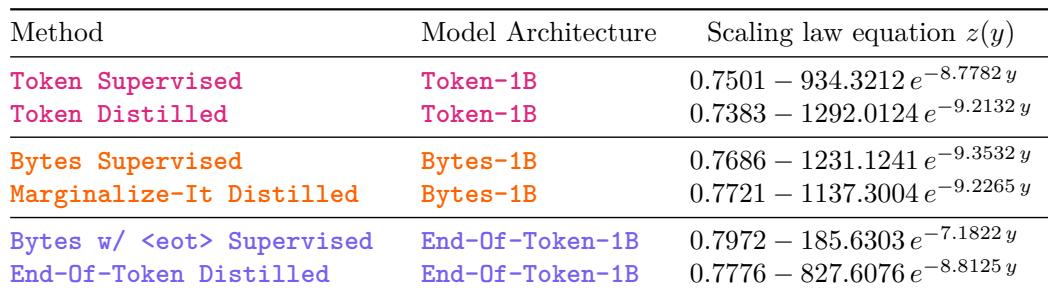
The fitted scaling laws show that distilled variants generally achieve lower asymptotic downstream task errors than their supervised counterparts, with the End-Of-Token Distilled model reaching the best asymptotic performance among all six variants. The Bytes-based models, despite improving validation BPB, do not translate that gain into better downstream task accuracy compared to the Token-based models. End-Of-Token Distilled achieves the lowest asymptotic downstream error among all variants, outperforming both Token Distilled and Bytes w/ Supervised. Token Distilled has a lower asymptotic error than Token Supervised, indicating distillation improves downstream task performance for the same architecture. Bytes Supervised and Marginalize-It Distilled show higher asymptotic errors than the Token-based distilled models, despite having better validation BPB curves. The scaling law fits show that the asymptotic error is approached at different rates, with the Bytes w/ Supervised model having the slowest decay (smallest gamma), implying it reaches its upper bound more gradually.
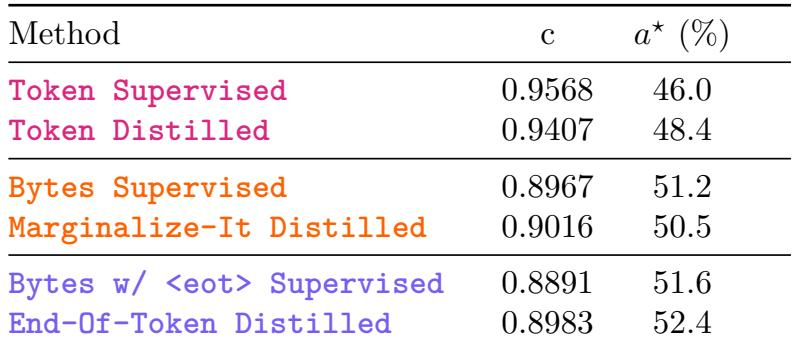
Under asymptotic validation, models using byte-level and end-of-token distillation achieve higher downstream accuracy than token-supervised or token-distilled models, despite having lower bits-per-byte values. The end-of-token distilled variant shows the best asymptotic accuracy, while supervised byte models also outperform token-based approaches. End-of-token distilled models achieve the highest asymptotic downstream accuracy among all variants. Byte-supervised and byte-with-eot supervised models outperform token-supervised and token-distilled models in downstream accuracy. Token-distilled models show lower asymptotic accuracy than byte-based variants, despite having a higher bits-per-byte value.
The evaluation compares six model configurations varying in tokenization and training objective, matched in layer parameters but differing in vocabulary size and compute per unit. Distilled models, especially those using end-of-token tokenization, show distinct scaling behaviors: they achieve lower asymptotic bits-per-byte and better downstream accuracy than token-based supervised counterparts, while also reducing data and storage costs. However, bytes-based and end-of-token models can surpass token-supervised models in bits-per-byte yet perform worse on downstream tasks, highlighting a calibration gap. At low compute budgets, token-distilled models lead, but end-of-token distilled models overtake them as compute increases, eventually matching or exceeding bytes-based variants, with the end-of-token distilled model reaching the best asymptotic downstream performance overall.