Command Palette
Search for a command to run...
الحدود النظرية لمواءمة نماذج اللغة
الحدود النظرية لمواءمة نماذج اللغة
Lucas Monteiro Paes Natalie Mackraz Barry-John Theobald Federico Danieli
الملخص
تعمل مواءمة نماذج اللغة على تحسين مخرجات النموذج لتعكس التفضيلات البشرية مع الحفاظ على قدرات النموذج الأساسي. وتتمثل أكثر أساليب المواءمة شيوعًا في (1) التعلم المعزز، الذي يعظم المكافأة المتوقعة تحت قيد تباعد كولباك-لايبلر، و(2) مواءمة الأفضل من بين N، التي تختار المخرجات الأعلى مكافأة من بين N عينة مستقلة. ورغم انتشار استخدامهما، لا تزال الحدود الأساسية لتحسين المكافأة في ظل ميزانية تباعد كولباك-لايبلر غير مفهومة جيدًا. نحدد الحدود النظرية المعلوماتية للمواءمة المنتظمة بتباعد كولباك-لايبلر من خلال اشتقاق أقصى كسب متوقع قابل للتحقيق في المكافأة لميزانية تباعد كولباك-لايبلر ثابتة. تقدم نتيجتنا الأولى صيغة مغلقة للتحسين الأمثل للمكافأة، تحكمها حد تباعد جيفريز بدلًا من KL المستخدم في التحليلات السابقة. كما نعيد صياغة هذا التعبير كتغاير تحت النموذج الأساسي، مما يوفر مُقدِّرًا عمليًا يتنبأ بمكاسب المواءمة القابلة للتحقيق من عينات النموذج الأساسي وحده. ونوسع تحليلنا ليشمل إعداد المكافأة الوكيلة، موضحين أن الفجوة بين المواءمة المثالية والمواءمة الوكيلة (اختراق المكافأة) تنمو مع حجم خطأ المكافأة وعندما ينخفض عامل جزاء تباعد كولباك-لايبلر. ثم نثبت أن تجميع المكافآت يخفف من اختراق المكافأة، مما يوفر مبررًا نظريًا لهذه التقنية المستخدمة عمليًا. تجريبيًا، نحسب جبهة باريتو لتباعد كولباك-لايبلر والمكافأة لمهمتين لنماذج اللغة، هما السلامة والتلخيص، ونبين أن الأفضل من بين N يقترب كثيرًا من الحد النظري، بينما تظل خوارزميتا PPO وGRPO دون المستوى الأمثل بشكل كبير. تسلط نتائجنا النظرية الضوء على عدة ظواهر مرصودة تجريبيًا في أدبيات المواءمة، وتشير إلى الحاجة إلى تحسينات خوارزمية لتحقيق مواءمة مثالية دون تكاليف استدلال عالية.
One-sentence Summary
Apple researchers characterize the information-theoretic limits of KL-regularized language model alignment by deriving a closed-form optimal expected reward gain governed by Jeffreys divergence rather than KL along with a covariance-based estimator from base-model samples, and they prove that reward ensembling mitigates proxy reward hacking while best-of-N nears the theoretical Pareto frontier for safety and summarization, unlike PPO and GRPO.
Key Contributions
- The work derives a closed-form expression for optimal reward improvement under KL-regularized alignment, showing that it is governed by a Jeffreys divergence term instead of the previously conjectured square-root KL scaling.
- It reformulates the Jeffreys divergence as a covariance under the base model, yielding convergent estimators that recover the full KL-reward Pareto frontier from base model samples alone. Empirical results on safety and summarization show best-of-N sampling closely tracks this frontier while PPO and GRPO remain suboptimal.
- The work extends the analysis to proxy rewards, proving that the gap between gold-reward and proxy-reward alignment grows with the mean squared reward error and the inverse KL penalty, and shows that reward ensembling provably mitigates reward hacking with convergence rate O(n^{-1/2}).
Introduction
Large language models are typically aligned through KL-regularized reinforcement learning or related preference-based methods to reduce harmful outputs, but the theoretical maximum reward achievable for a fixed KL divergence budget has remained unclear. Prior work provided only non-achievable upper bounds or relied on restrictive assumptions about the language or reward model. The authors characterize the exact fundamental limit of alignment, showing that optimal reward gain equals the KL penalty times a Jeffreys divergence, and they reformulate this quantity as a covariance that can be estimated from the base model alone before alignment. This gives a principled way to benchmark alignment methods against a true reward-KL Pareto frontier and also supports theoretical analysis of proxy rewards and reward ensembling.
Method
The authors establish a comprehensive theoretical framework to compute the fundamental limits of large language model alignment under a KL divergence penalty. Rather than relying on empirical training to evaluate alignment performance, they derive closed-form information-theoretic bounds and develop computable estimators that require only samples from the unaligned base model. This approach allows practitioners to map the theoretical Pareto frontier of reward gain versus KL divergence without executing any alignment training.
To characterize the optimal reward improvement, the authors first demonstrate that the reward gain after alignment is fully determined by the Jefreys divergence, which is the sum of the forward and reverse KL divergence between the base and aligned policies. The optimal reward improvement is characterized by λJD(πbase∣∣πr,λ). Moving beyond non-computable upper bounds, they prove that the expected reward gain can be expressed as a covariance under the base policy:
Δ(r,r′)=Covπbase(⋅∣x)(r′,Eπbase(⋅∣x)[er(x,y)/λ]er(x,y)/λ)This covariance formulation is pivotal because it shifts the computation from the optimally aligned model to the accessible base model and the reward model.
Building on this theoretical foundation, the authors operationalize the covariance characterization by introducing Monte Carlo estimators for both the expected reward gain and the corresponding KL divergence. By drawing independent and identically distributed samples from the base policy, these estimators compute the partition function and joint reward terms to approximate the theoretical limits. The authors formally prove that these estimators are consistent and converge in probability to the true theoretical values as the number of base model samples increases. This convergence guarantee ensures that the entire Pareto frontier can be reliably estimated using a finite set of base model generations.
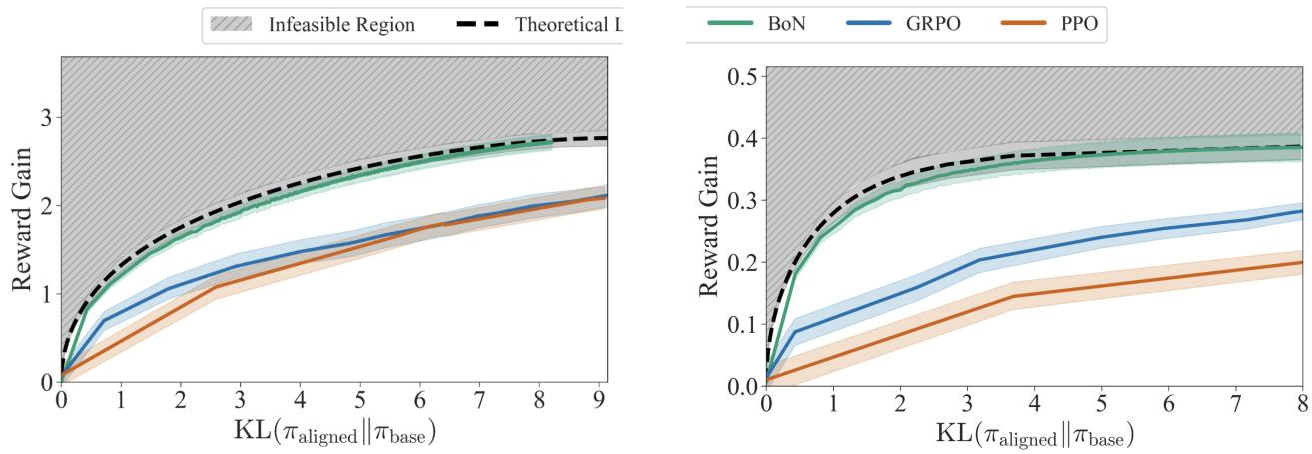
Refer to the framework diagram below to visualize how the theoretical limits compare against empirical alignment algorithms.
As illustrated, the theoretical Pareto frontier defines the absolute maximum achievable reward for any given KL budget. The authors use this framework to benchmark existing alignment methods such as Best-of-N, GRPO, and PPO, revealing that Best-of-N closely tracks the theoretical limits across the entire trade-off curve, while other methods remain sub-optimal.
Furthermore, the authors extend their framework to analyze the practical challenges of using imperfect proxy rewards instead of gold rewards. They formalize the concept of a preference residual to quantify the discrepancy between proxy and gold rewards. Through this formulation, they prove that the performance degradation caused by reward hacking is governed by an exponential term of the preference residual. This theoretical insight explicitly demonstrates why aggressive alignment against proxy rewards leads to severe reward hacking, particularly when the KL penalty is small.
To address this vulnerability, the authors provide a formal justification for reward ensembling. They establish a deterministic Lipschitz bound that connects the difference in expected reward between two aligned models to the distance between their underlying reward functions. By applying this bound to an ensemble average, they prove that ensembling multiple proxy rewards mitigates reward hacking. Specifically, they show that the expected reward of a model aligned to an ensemble of proxy rewards converges to the optimal gold reward expectation at a rate of O(n−1/2) in expectation. This theoretical guarantee explains the empirical success of reward ensembling and provides a principled strategy to counter the exponential degradation caused by proxy reward residuals.
Experiment
The experiments assess theoretical KL versus reward limits on Reddit TL;DR summarization and BeaverTails safety tasks, using Pythia-1B and Zephyr-7B models, and compare GRPO, PPO, and best-of-N. The proposed reward gain and KL estimators converge reliably within a few thousand base model samples, confirming that the Pareto frontier can be estimated before alignment training. Best-of-N remains close to the theoretical frontier across different KL budgets, while GRPO and PPO stay substantially below it, indicating that current KL-regularized RL methods leave considerable reward gains on the table.