Command Palette
Search for a command to run...
الإوزة الذهبية: خدعة بسيطة لتوليد مهام تعلم تعزيزي لا نهائية بمكافآت قابلة للتحقق من نصوص الإنترنت غير القابلة للتحقق
الإوزة الذهبية: خدعة بسيطة لتوليد مهام تعلم تعزيزي لا نهائية بمكافآت قابلة للتحقق من نصوص الإنترنت غير القابلة للتحقق
GooseReason-0.7M مجموعة بيانات التحقق من الاستدلال بتعزيز التعلم
الملخص
أصبح التعلم التعزيزي بالمكافآت القابلة للتحقق (RLVR) حجر الزاوية لإطلاق العنان للاستدلال المعقد في نماذج اللغة الكبيرة (LLMs). ومع ذلك، فإن توسيع نطاق التعلم التعزيزي يواجه عنق زجاجة بسبب محدودية البيانات القابلة للتحقق الموجودة، حيث تصل التحسينات إلى حالة من التشبع بشكل متزايد مع التدريب المطول. للتغلب على هذا، نقترح الإوزة الذهبية، وهي خدعة بسيطة لتوليد مهام تعلم تعزيزي غير محدودة بمكافآت قابلة للتحقق من نصوص الإنترنت غير القابلة للتحقق، من خلال بناء نسخة من مهام الإجابة على الأسئلة متعددة الخيارات من مهمة ملء الفراغات. بالنظر إلى نص مصدر، نطلب من نموذج لغوي كبير تحديد خطوات الاستدلال الرئيسية وإخفاءها، ثم توليد مجموعة من الإجابات البديلة المتنوعة والمعقولة. هذا يمكننا من الاستفادة من المجموعات النصية الغنية بالاستدلال وغير القابلة للتحقق والتي عادة ما تكون مستبعدة من البناء السابق لبيانات التعلم التعزيزي بالمكافآت القابلة للتحقق (مثل الكتب المدرسية العلمية) لتوليد مجموعة بيانات gooseReason-0.7M، وهي مجموعة بيانات تعلم تعزيزي واسعة النطاق تحوي أكثر من 0.7 مليون مهمة تغطي مجالات الرياضيات والبرمجة والعلوم العامة. تجريبيًا، تعمل الإوزة الذهبية على إحياء النماذج المشبعة على بيانات التعلم التعزيزي الموجودة، مما يحقق تحسينات قوية ومستمرة تحت التعلم التعزيزي المتواصل ويحقق نتائج حديثة جديدة لنماذج بحجم 1.5B و 4B-Instruct عبر 15 معيارًا متنوعًا. أخيرًا، ننشر الإوزة الذهبية في بيئة واقعية، من خلال توليد مهام تعلم تعزيزي من مسح FineWeb الخام لمجال الأمن السيبراني، حيث لا توجد بيانات سابقة للتعلم التعزيزي. تدريب نموذج Qwen3-4B-Instruct على البيانات الناتجة gooseReason-Cyber يحقق أحدث النتائج في مجال الأمن السيبراني، متجاوزًا نموذجًا متخصصًا في المجال بحجم 7B مع تدريب مسبق ولاحق واسع النطاق خاص بالمجال. وهذا يسلط الضوء على إمكانية التوسع التلقائي في بيانات التعلم التعزيزي من خلال استغلال النصوص الإنترنتية الغنية بالاستدلال وغير القابلة للتحقق.
One-sentence Summary
Researchers from the University of Washington and Microsoft propose Golden Goose, a simple trick that synthesizes unlimited RLVR tasks from unverifiable internet text by masking key reasoning steps and generating diverse distractors, yielding the 0.7M-task GooseReason dataset that revives RL saturation and achieves state-of-the-art results for 1.5B and 4B-Instruct models across 15 benchmarks, including new cybersecurity SOTA with GooseReason-Cyber over a 7B domain-specialized model.
Key Contributions
- Introduces Golden Goose, a pipeline that converts unverifiable internet text into verifiable multiple-choice fill-in-the-middle RLVR tasks by prompting an LLM to mask key reasoning steps and generate diverse distractors, enabling use of reasoning-rich corpora such as free-form textbooks that prior RLVR data construction excluded.
- Releases GooseReason-0.7M, a large-scale RLVR dataset with over 0.7 million synthesized tasks spanning mathematics, programming, and general scientific domains, built entirely from unverifiable sources without domain experts or handcrafted environments.
- Demonstrates that training on GooseReason data revives models saturated on existing RLVR data, achieving sustained gains under continuous RL and new state-of-the-art results for 1.5B and 4B-Instruct models across 15 benchmarks; a cybersecurity deployment using GooseReason-Cyber data trains Qwen3-4B-Instruct to surpass a 7B domain-specialized model that underwent extensive domain-specific pre-training and post-training.
Introduction
Reinforcement Learning with Verifiable Rewards (RLVR) has become a core method for teaching large language models complex reasoning, powering systems like DeepSeek-R1, OpenAI-o3, and Gemini-3. Scaling RLVR, however, is bottlenecked by the need for problems with ground-truth answers that can be automatically checked, such as math problems parsable by a verifier or coding tasks with executable unit tests. Prior work depends on human-authored problems, which are costly and narrow in scope, or on handcrafted procedural data generators, which are hard to scale beyond a few hundred environments. As a result, rich but unverifiable sources like open-ended textbook questions, theorem-proving passages, and coding problems without test cases are typically discarded.
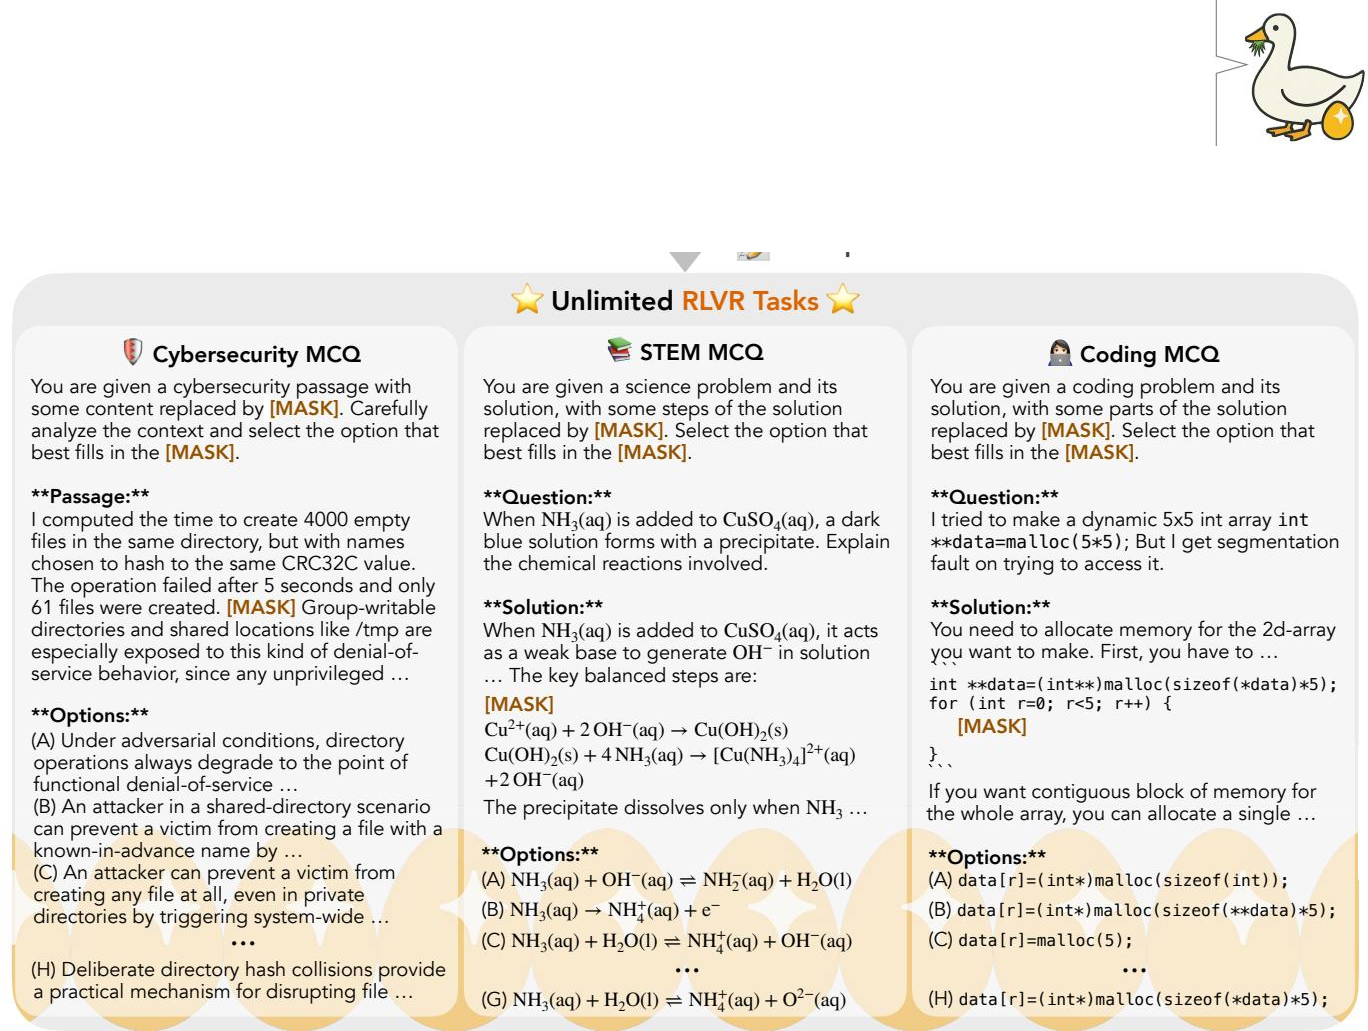
To address this, the authors introduce GooseReason, a simple pipeline that converts unverifiable internet text into verifiable RLVR tasks. The approach prompts an LLM to identify a contiguous span of crucial reasoning steps in a source passage, mask it, and generate plausible distractors, yielding a fill-in-the-middle multiple-choice task with a verifiable answer. This enables construction of GooseReason-0.7M, a dataset of over 700,000 RLVR tasks spanning mathematics, programming, and scientific domains. Empirically, the authors show that incorporating these tasks revives models whose RL training had saturated, producing continuous gains across 15 benchmarks, and even improves reasoning generalization on downstream tasks not explicitly covered by the data.
Dataset
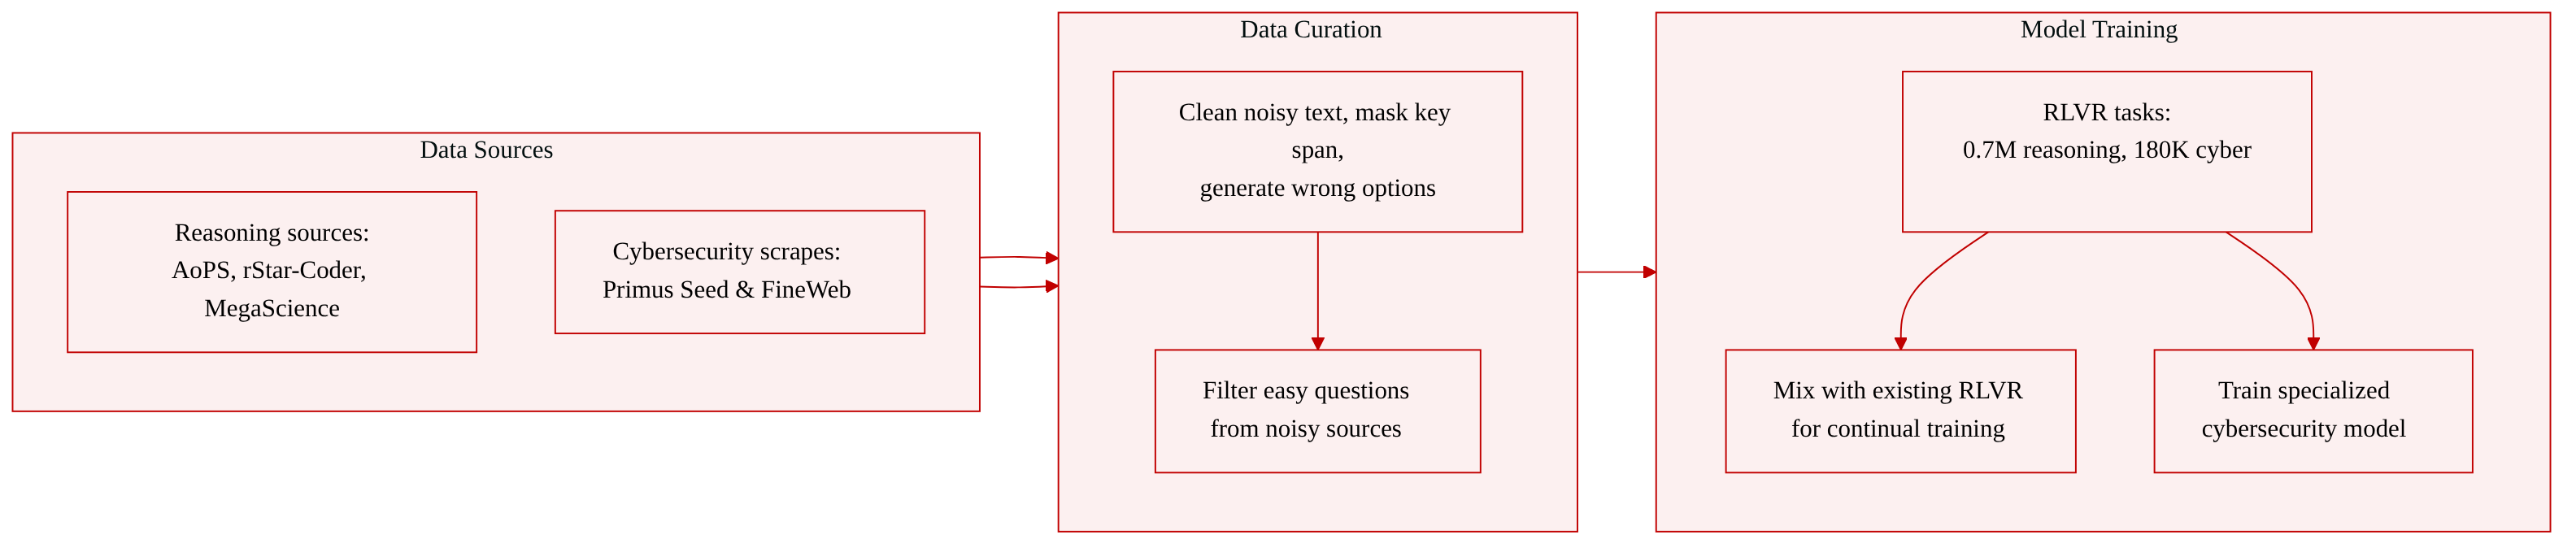
The authors build their dataset through a synthesis pipeline that turns raw text into verifiable multiple-choice reasoning questions. Here is a breakdown of its composition, sources, and usage.
Synthesis pipeline
- Given a source text, the authors prompt a large language model (GPT-5) to identify a contiguous span of important reasoning steps.
- They replace that span with a [MASK] token to create the masked context, treat the span as the ground-truth answer, and prompt the model to generate several plausible but incorrect distractors.
- The final question is a multiple-choice item consisting of the masked context plus the true answer and distractors in randomized order.
- For noisy source text, the model first extracts or summarizes it into a cleaner, educationally valuable version, then constructs the masked context and distractors from that version.
- If a source contains no suitable passage, the model returns an empty string and the text is skipped.
- To ensure quality, GPT-5 is used throughout the synthesis. For reasoning-dense sources, no post-processing is needed. For noisy sources, the authors add difficulty-based filtering, removing easy questions that the student model answers correctly across all 16 rollouts.
Reasoning domain (GooseReason-0.7M)
- Built from three corpora that were previously excluded from RLVR data curation:
- AoPS-Instruct: about 600K question-answer pairs from the Art of Problem Solving forum, mostly Olympiad-level math with community solutions. These are unstructured and sometimes incomplete, and many theorem-proving solutions are impossible to verify with a math verifier.
- rStar-Coder: 37.7K expert-written competitive programming problems (from IOI, Codeforces, etc.) with oracle solutions, plus synthesized problems. Only 380K of 1.656M synthesized questions got test cases; the authors use the synthetic SFT split (questions and teacher solutions without test cases) to generate verifiable coding questions.
- MegaScience: 650K question-answer pairs from about 12K university-level textbooks across physics, biology, chemistry, medicine, computer science, mathematics, and economics. Many answers contain specialized formulas or open-ended multi-paragraph discussions, which are hard to validate with a verifier.
- The pipeline yields over 0.7 million novel RLVR tasks.
- Effectiveness analysis against existing RLVR data (ProRL blend) shows that only about 25% of 136K samples in the ProRL mix provide meaningful learning signals, while GooseReason-0.7M retains around 70% effectiveness, substantially supplementing existing datasets for RL training.
Cybersecurity domain (about 180K tasks)
- This domain lacks open-source RLVR datasets, so the authors use Primus data as the raw source:
- Primus-Seed: crawled from reputable sources like MITRE, Wikipedia, and cybersecurity company websites, plus cyber threat intelligence manually collected by experts.
- Primus-FineWeb: cybersecurity-related text filtered from FineWeb, using Primus-Seed as positive samples.
- These sources are heavily web-scraped and noisy. The authors apply the synthesis pipeline directly, producing roughly 180K RLVR tasks from raw internet text.
Usage in the model
- The student model receives only the masked context and must select the correct option from the candidate set.
- Verification during RL simply checks whether the predicted option matches the ground-truth answer.
- The reasoning-domain tasks are mixed with existing RLVR data to scale continual RL training, while the cybersecurity tasks are used to train a specialized model in that domain.
Method
The authors propose a data synthesis pipeline to construct Reinforcement Learning with Verifiable Rewards (RLVR) tasks from reasoning-rich but unverifiable text. As illustrated in the framework diagram, the process begins with a source text S. An LLM is prompted to identify a contiguous span t containing crucial reasoning steps. This span is replaced with a special [MASK] token to form a masked context Smask. The original span t serves as the ground-truth answer. Simultaneously, the LLM generates a set of diverse distractors D={d1,d2,…,dk} that are plausible and stylistically similar to t but incorrect within the context of Smask. The final task is formulated as a multiple-choice question Q=(Smask,{t}∪D).
For noisy source texts, such as web scrapes, the pipeline includes a preprocessing step where the LLM first extracts or summarizes the text into a coherent, educationally valuable passage S′ before applying the masking and distractor generation steps. If the source text contains no suitable passage, the LLM returns an empty string. To ensure data quality, the system employs difficulty-based filtering, removing problems that are too easy for the student model to solve consistently across all rollouts. During the training phase, the student model is provided with Smask and tasked with selecting the option that best fills the [MASK] from the candidate set. Verification during RL simply checks if the prediction matches the ground-truth option.
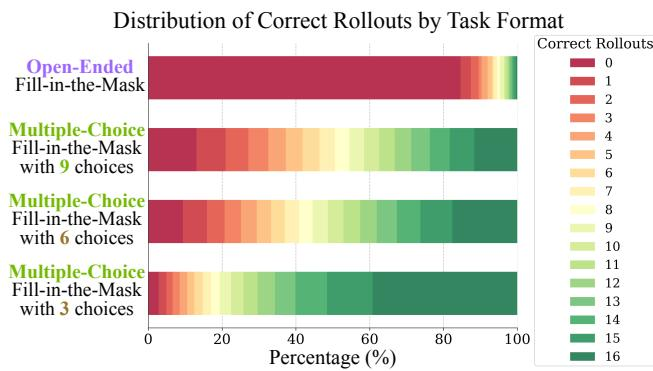
The design of the task format is critical for effective RL training. The authors compare open-ended fill-in-the-mask tasks against multiple-choice formulations. They observe that open-ended tasks often lead to poor instruction following, where models ignore the mask and solve the problem from scratch, yielding no usable reward signal. Regarding the number of distractors, the authors ablate the impact of option count. As shown in the chart below, using too few options (e.g., 3) makes tasks too easy, allowing models to rely on elimination strategies rather than reasoning. Conversely, increasing the number of distractors to 9 shifts the majority of problems into a medium-difficulty regime, characterized by a mix of successful and failed rollouts, which provides the most effective signal for reinforcement learning.
Experiment
The experiments evaluate the GooseReason dataset across scaling scenarios for RL training of LLMs. In a data saturation case, incorporating GooseReason revives a saturated model and yields robust gains across math, coding, and especially STEM, while also improving transfer to unrelated tasks, even for stronger models that plateau early. Under a fixed compute budget, joint training with GooseReason achieves higher performance at the same step count, showing more compute-efficient scaling. In a specialized domain, GooseReason-Cyber enables RLVR to deliver substantial improvements in cybersecurity reasoning with minimal training steps, surpassing prior domain-specific approaches.
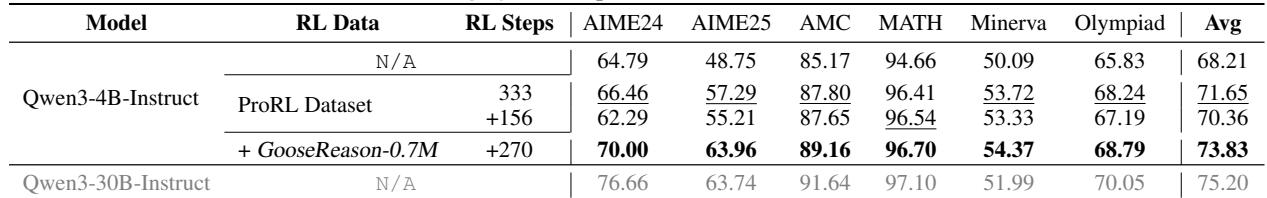
Continued RL training with the original ProRL data on a stronger model leads to performance saturation or degradation after about 300 steps, with losses in math and STEM. Adding GooseReason-0.7M revives the saturated model and yields consistent gains across all evaluated benchmarks, enabling further RL scaling and improving average performance. Extended RL with only ProRL data causes math and STEM performance to drop, with only a marginal coding gain. Incorporating GooseReason-0.7M after saturation improves results on all listed math benchmarks, lifting the average score from 70.36 to 73.83. The gains are broad, including tasks not directly covered by the training data, indicating transferable reasoning skills.
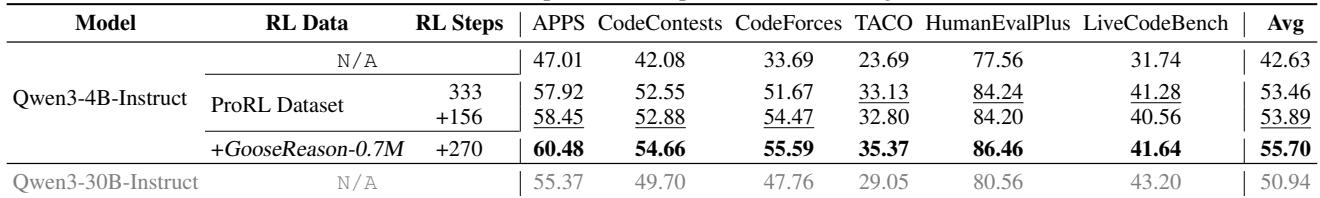
Adding GooseReason data to RL training improves coding benchmark performance for Qwen3-4B-Instruct, with further gains as RL steps increase. The 4B model with GooseReason surpasses the much larger Qwen3-30B-Instruct on average and on most individual benchmarks. Gains are consistent across APPS, CodeContests, CodeForces, TACO, HumanEvalPlus, and LiveCodeBench. Including GooseReason-0.7M raises the 4B model's average pass@1 from 42.63 to 55.70, surpassing the 30B model's 50.94. The 4B model with GooseReason outperforms the 30B model on all six coding benchmarks except LiveCodeBench, where it is slightly lower. Increasing RL steps from 333 to 270 with GooseReason yields additional gains on CodeForces and TACO, while maintaining high accuracy on other benchmarks.
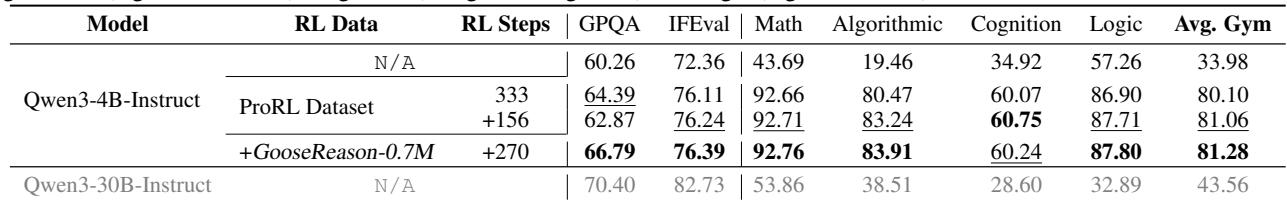
The table compares reinforcement learning recipes for Qwen3-4B-Instruct, showing that adding GooseReason data to ProRL training yields consistent gains across STEM reasoning, instruction following, and logic puzzles. The best configuration approaches or exceeds the performance of a 7.5 times larger model on several benchmarks, while the base model without RL performs notably worse on reasoning-heavy tasks. Adding GooseReason to ProRL improves scores on math, algorithmic, cognition, and logic tasks beyond ProRL alone, with the largest gains in math and algorithmic categories. The GooseReason-trained 4B model achieves comparable or better results than Qwen3-30B-Instruct on most reasoning benchmarks despite being much smaller. Instruction following and GPQA also improve with GooseReason, indicating transfer of reasoning skills beyond the training data domain.
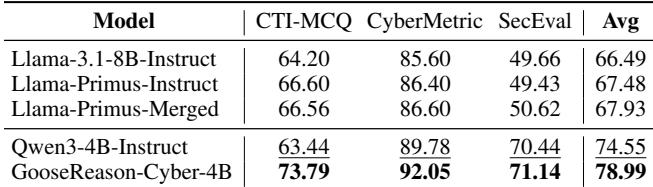
A 4B Qwen model trained with GooseReason-Cyber achieves state-of-the-art results on cybersecurity benchmarks, outperforming larger 8B domain-specialized models despite far less RL training. The method yields a substantial average performance gain, more than tripling the improvement seen by the previous best 8B approach. The GooseReason-Cyber-4B model improves average benchmark performance by 4.44% over its base Qwen3-4B, using only 100 RL steps. This 4B model surpasses all 8B baselines, including the prior state-of-the-art Llama-Primus-Instruct, which gained just 1.44% over its base. Gains appear across all three evaluated cybersecurity tasks, with the largest relative jump observed in threat-intelligence and vulnerability analysis.
The experiments show that adding GooseReason data to reinforcement learning prevents saturation and yields consistent gains across math, coding, reasoning, and instruction following benchmarks, even for models much smaller than their larger counterparts. This approach enables further RL scaling, improves transfer to tasks outside the training distribution, and similarly boosts cybersecurity performance, where a 4B model surpasses larger domain-specialized baselines with fewer training steps.