Command Palette
Search for a command to run...
مايند: حوارات اصطناعية مستنيرة بالرياضيات للتدريب المسبق لنماذج اللغة الكبيرة
مايند: حوارات اصطناعية مستنيرة بالرياضيات للتدريب المسبق لنماذج اللغة الكبيرة
Syeda Nahida Akter Shrimai Prabhumoye John Kamalu Sanjeev Satheesh Eric Nyberg Mostofa Patwary Mohammad Shoeybi Bryan Catanzaro
Nemotron-MIND: حوارات اصطناعية مستنيرة بالرياضيات
الملخص
لقد تم استكشاف فائدة البيانات الاصطناعية في تحسين جودة بيانات التدريب المسبق وبالتالي تحسين دقة المهام النهائية على نطاق واسع في نماذج اللغة الكبيرة الحديثة. ومع ذلك، فإن هذه الأساليب لا تكون كافية في المهام المعقدة والمتعددة الخطوات والتفكير الرياضي، حيث تفشل البيانات الاصطناعية عادة في إضافة معرفة تكميلية إلى المجموعة النصية الخام الموجودة. في هذا العمل، نقترح طريقة جديدة واسعة النطاق ومتنوعة لتوليد الحوارات الاصطناعية المستنيرة بالرياضيات (مايند) تعمل على تحسين القدرة على التفكير الرياضي لنماذج اللغة الكبيرة. على وجه التحديد، باستخدام مايند، نقوم بتوليد محادثات اصطناعية بناءً على OpenWebMath (OWM)، مما ينتج عنه مجموعة نصوص رياضية جديدة، مايند-OWM. تكشف تجاربنا مع إعدادات محادثة مختلفة أن دمج الفجوات المعرفية بين المشاركين في الحوار أمر ضروري لتوليد بيانات رياضية عالية الجودة. كما نحدد طريقة فعالة لتنسيق ودمج البيانات الاصطناعية والخام أثناء التدريب المسبق لتعظيم الاستفادة في التفكير الرياضي، مع التأكيد على الحاجة إلى إعادة هيكلة البيانات الخام بدلاً من استخدامها كما هي. بالمقارنة مع التدريب المسبق على البيانات الخام فقط، يُظهر نموذج تم تدريبه مسبقًا على مايند-OWM تحسنًا كبيرًا في التفكير الرياضي (GSM8K: +13.42%، MATH: +2.30%)، بما في ذلك أداء فائق في المعرفة المتخصصة (MMLU: +4.55%، MMLU-STEM: +4.28%) ومهام التفكير العامة (التفكير العام: +2.51%). نقوم بإصدار 138 مليار رمز من المحادثات الاصطناعية المولدة باستخدام مايند على https://huggingface.co/datasets/nvidia/Nemotron-MIND.
One-sentence Summary
Researchers from NVIDIA, Carnegie Mellon University, and Boston University propose MIND, a large-scale method that generates math-informed synthetic dialogues from OpenWeb-Math to enhance LLM mathematical reasoning, demonstrating that incorporating knowledge gaps between dialog participants and restructuring raw data during pretraining maximizes gains, yielding significant improvements on GSM8K (+13.42%), MATH (+2.30%), MMLU (+4.55%), and general reasoning (+2.51%), with a released 138B-token corpus.
Key Contributions
- The paper introduces MIND, a large-scale synthetic dialogue generation method that converts mathematical web content into structured conversations with embedded multi-step reasoning, and shows that encoding knowledge gaps between dialogue participants is a key factor in producing high-quality math training data.
- This work identifies an effective strategy for formatting and integrating synthetic and raw data during pretraining, demonstrating that restructuring raw data before mixing it with synthetic dialogues yields greater gains in mathematical reasoning than using raw data as-is.
- Results show that models pretrained on the resulting MIND-OWM corpus achieve significant improvements over raw-data baselines, including +13.42% on GSM8K, +2.30% on MATH, +4.55% on MMLU, +4.28% on MMLU-STEM, and +2.51% on general reasoning benchmarks, while outperforming models trained on 3.6× larger datasets; the paper also releases a 138B-token synthetic conversation corpus.
Introduction
Large language models (LLMs) have shown strong reasoning capabilities, particularly in complex mathematical tasks, but their performance heavily depends on the quality and structure of pretraining corpora. Effective math data must be formatted to encourage step-by-step problem decomposition, yet curating high-quality, structured mathematical datasets is costly and scarce. Prior synthetic data generation methods often lack the multi-step reasoning structure essential for complex math tasks, and many advanced models do not disclose their data strategies, leaving open-source efforts at a disadvantage.
To address these gaps, the authors introduce MIND, a scalable approach that converts raw web text into multi-turn, structured conversations using an off-the-shelf open-source LLM. MIND decomposes content into step-by-step dialogue trajectories, explores each step in depth, and supports diverse conversational styles to enrich data diversity. This method preserves web corpus diversity while embedding dynamic reasoning, enabling continuous synthetic data expansion. The authors demonstrate that pretraining a 7B model on MIND-generated conversations improves mathematical reasoning by up to 6.29% over raw data, outperforms models trained on 3.6× larger raw corpora, and extends gains to general tasks, offering a resource-efficient alternative for structured reasoning data.
Dataset
The authors generate a synthetic mathematical dialogue dataset called MIND (Math Informed Synthetic Dialogue) from unstructured mathematical web text.
Dataset Composition and Sources
- The seed corpus is OpenWebMath, containing 14.7B tokens of high quality mathematical web text.
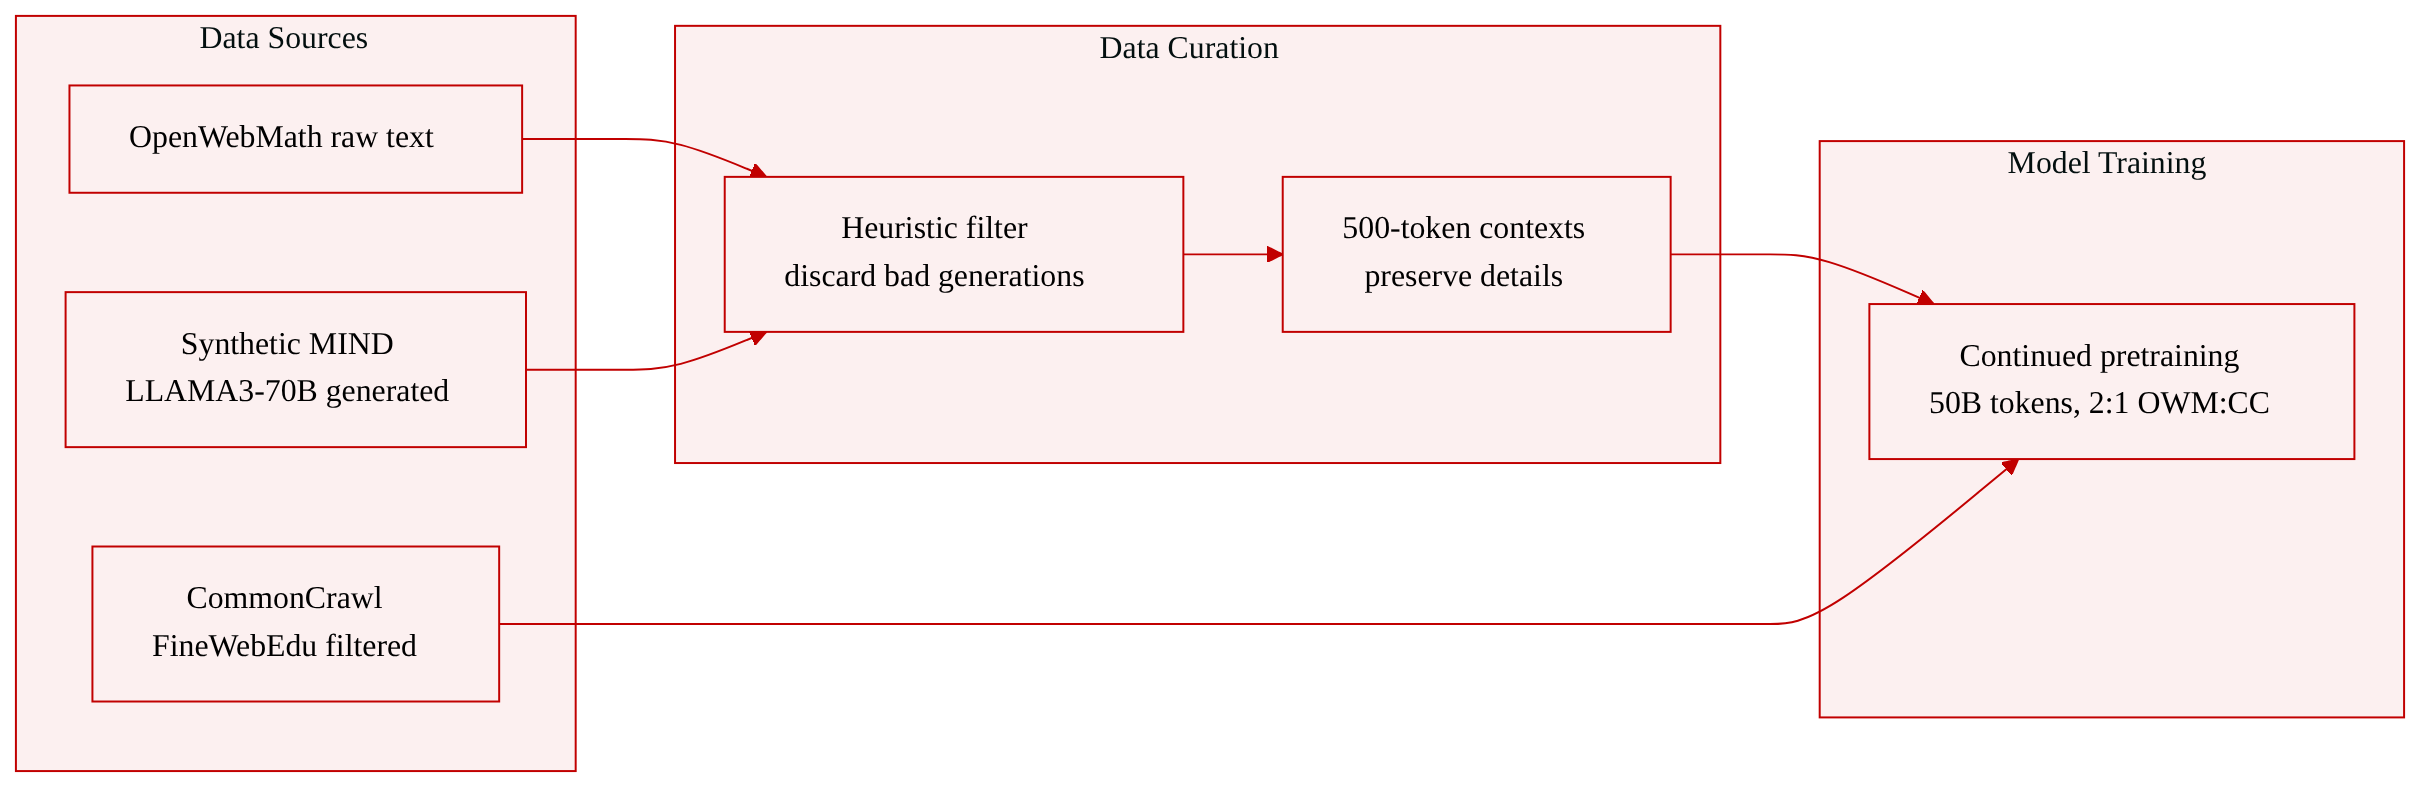
- The authors use LLAMA3-70B-INSTRUCT to convert raw text into multi-turn conversations using a set of prompts (e.g., two students, teacher_student, debate).
- For each generation, they iteratively take contexts of 500 tokens to preserve details from the original text.
Subset Versions
- OWM-4B: a smaller subset of OpenWebMath containing 4B tokens for quick evaluation of all seven prompts. Synthetic data from this subset is labeled MIND-OWM-4B.
- OWM-14B: the full 14.7B token OpenWebMath corpus. Synthetic data from this is called MIND-OWM-14B.
Filtering and Processing
- Heuristic filtering is used to discard bad generations. LLM-based scoring was tested but rejected because it rated all generations highly, making it unsuitable.
- No specific cropping strategy is mentioned beyond the 500-token context windows.
Use in Pretraining
- The base model is pretrained on a blend of 13 CommonCrawl snapshots (73.37%), books/patents (9%), papers (9%), code (5.12%), stack-exchange (2.66%), and Wikipedia (0.8%) for 700B tokens.
- Continued pretraining uses an additional 50B tokens with a new data blend (D) that maintains a 2:1 ratio of OpenWebMath (either raw R or synthetic S') to 13 snapshots of CommonCrawl (17B tokens, filtered by the FineWebEdu classifier).
- The CommonCrawl portion is fixed across experiments, while the OpenWebMath component varies between raw, synthetic, or a combination to assess their relative importance.
- The token distribution is kept constant across experiments, so every model sees the same number of tokens from each source regardless of the source size.
Method
The authors propose MIND, a conversational synthetic data generation framework designed to enhance the mathematical and complex multi-hop reasoning capabilities of Large Language Models (LLMs). Unlike standard rephrasing techniques that only modify surface forms, MIND introduces semantic variations and structured complexity by transforming raw text into multi-turn dialogues. This approach mimics human problem-solving by breaking down complex contexts into step-by-step sub-contexts through conversational interactions.
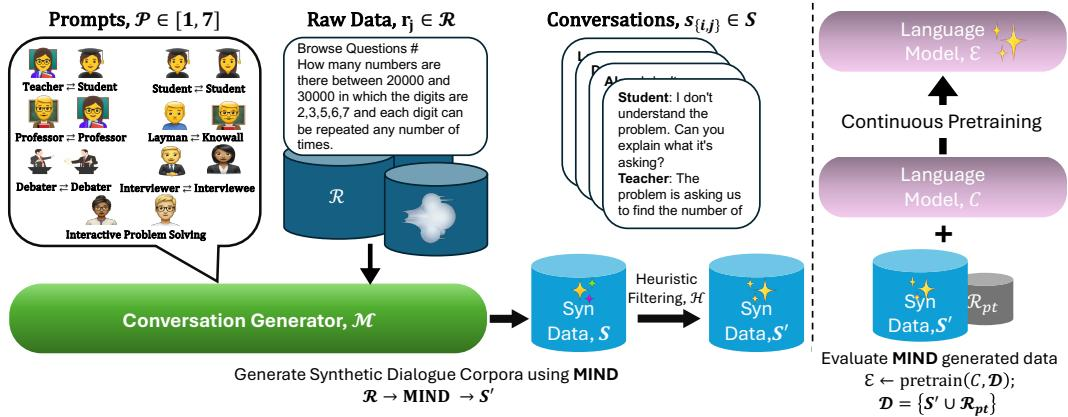
Refer to the framework diagram. The overall pipeline begins with a raw dataset R and a curated set of conversational prompts P. A pretrained LLM, denoted as M, serves as the conversation generator. The system employs seven distinct conversational settings to guide the generation process, including scenarios such as "Teacher ⇔ Student", "Student ⇔ Student", "Professor ⇔ Professor", "Debater ⇔ Debater", "Interviewer ⇔ Interviewee", "Layman ⇔ Knowall", and "Interactive Problem Solving". These prompts are specifically designed to instruct the LLM to preserve original information while encouraging detailed, step-by-step reasoning and explanations.
For each raw text example rj from the dataset and a selected prompt pi, the generator M produces a synthetic conversation si,j. This transformation is formalized as:
si,j=M(pi∣∣rj)where ∣∣ denotes the concatenation of the prompt and the raw text. The total synthetic data generated for a fixed prompt i is represented as S={si,j∣j∈[1,N]}. The authors utilize LLAMA3-70B-INSTRUCT as the generator M due to its robust performance in dialogue tasks. To ensure context fidelity and prevent detail loss, the generation is performed iteratively on chunks of 500 tokens.
Following generation, a heuristic filtering process H is applied to the synthetic dataset to remove low-quality or incorrect generations. The refined dataset is denoted as S′:
S′=H(S)This filtering step is crucial for maintaining the high quality of the synthetic dialogue corpus, which is specifically structured to improve reasoning abilities.
The resulting synthetic data S′ is utilized for continuous pretraining to evaluate its effectiveness. The authors start with a base LLM C and train it on a data blend D that combines the synthetic data S′ with a subset of high-quality pretraining data Rpt, derived from CommonCrawl snapshots. The continuous pretraining process is defined as:
E←pretrain(C,D);where D={S′∪Rpt}This yields an enhanced model E with improved mathematical reasoning capabilities. The training configuration maintains consistency with the initial pretraining setup, utilizing the AdamW optimizer and specific learning rate schedules to ensure stable convergence.
Experiment
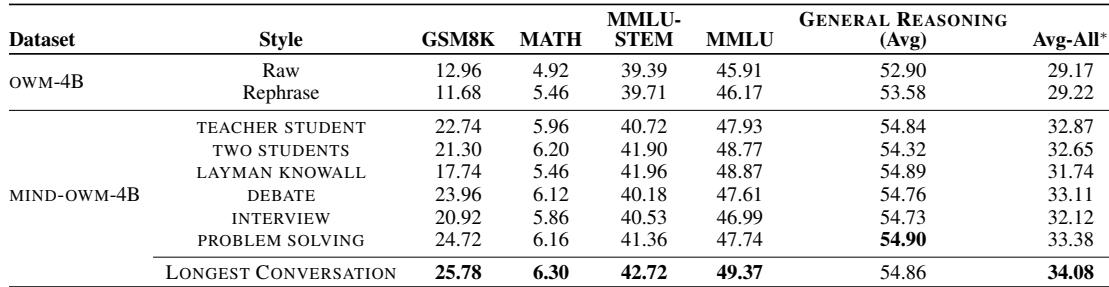
The experiments continuously pretrain a 7B model on synthetic conversational data generated by MIND, evaluating it against raw and rephrased data across math, general reasoning, and specialized knowledge benchmarks. MIND-generated conversations consistently outperform baselines, with the longest conversation format yielding the highest gains across all tasks. Ablations reveal that prompt style matters, as a clear knowledge gap between participants improves explanation depth, while a style like TWO PROFESSORS with no gap underperforms. The benefits extend to high-quality seed corpora like MATHPILE and persist even with a smaller generator model, indicating that conversational structure, rather than model scale, drives the improvements.
Continuous training on MIND-generated conversational data from diverse styles consistently improves performance across all reasoning tasks compared to raw or rephrased data. Selecting the longest conversation for each raw text yields the highest gains, especially in math and specialized knowledge benchmarks. All conversational styles outperform raw and rephrased baselines on GSM8K, MATH, MMLU-STEM, MMLU, and general reasoning. Longest-conversation selection delivers the largest improvements across tasks, highlighting the benefit of multi-perspective dialogues. Debate and teacher-student styles show the strongest math gains, while layman-knowall and two-students excel in specialized knowledge and general reasoning.
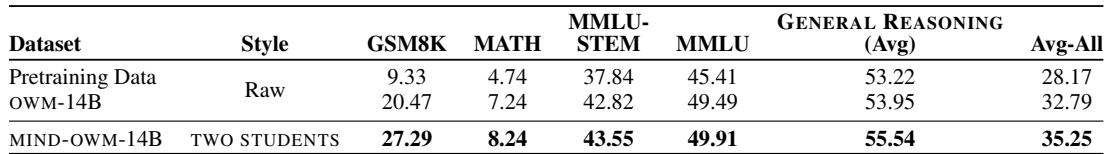
Training a 7B LLM on synthetic conversational data generated by MIND improves performance across math, specialized knowledge, and general reasoning benchmarks compared to using raw OpenWebMath or the original pretraining blend. The conversational approach, particularly with the TWO STUDENTS style, yields consistent gains across all evaluated tasks. MIND-generated synthetic conversations outperform raw data and the original pretraining mixture on every benchmark. The TWO STUDENTS conversation style produces the largest improvements, especially on math reasoning tasks. Continuous training with synthetic dialogues enhances both specialized knowledge and general reasoning abilities.
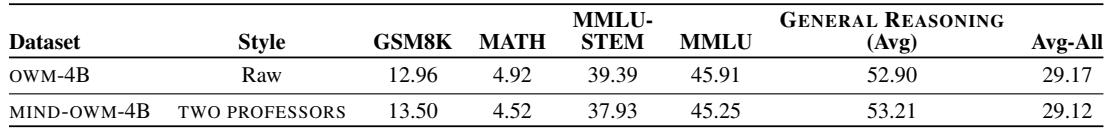
The TWO PROFESSORS conversational style performs comparably or worse than raw data during continuous pretraining, unlike other styles that improve reasoning. This underperformance is attributed to the zero-knowledge gap between expert participants, leading to surface-level discussions without deeper analysis or problem breakdowns. TWO PROFESSORS dialogues yield equivalent or worse performance relative to raw data across benchmarks. The style lacks a knowledge gap between participants, preventing detailed explanations and reasoning expansion. Other styles benefit either from explicit knowledge gaps (e.g., LAYMAN KNOWALL, TEACHER STUDENT) or collaborative non-expert problem solving (e.g., PROBLEM SOLVING, DEBATE).
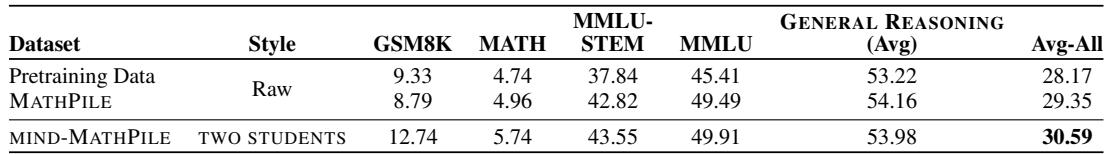
Synthetic conversations generated from high-quality raw data improve performance on math tasks, with the TWO STUDENTS style showing notable gains over raw data. The effectiveness of conversational styles depends on the presence of knowledge gaps, where clear gaps benefit general reasoning and collaborative problem-solving benefits math tasks. Conversational data from MATHPILE outperforms raw data on math benchmarks, with TWO STUDENTS style yielding further improvements. Styles with explicit or implicit knowledge gaps (e.g., TWO STUDENTS) lead to more detailed reasoning, which is key for math performance.
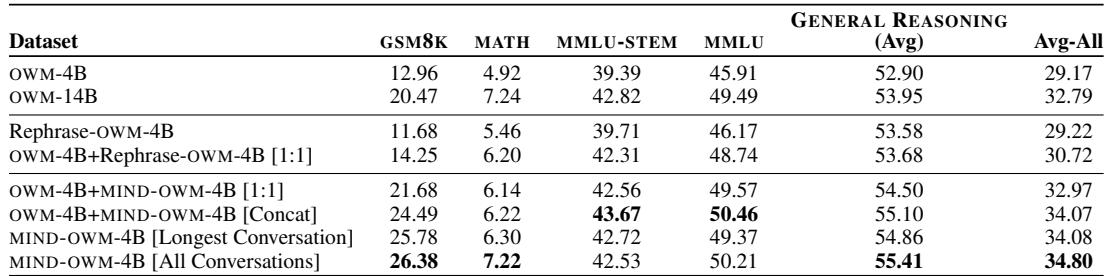
Synthetic conversational data consistently outperforms raw data across all training configurations. Combining all generated conversation styles from a smaller 4B model surpasses the performance of a larger 14B model trained on a 3.6x larger corpus, highlighting the efficiency and quality of synthetic conversations. While pure synthetic data yields the largest gains on math benchmarks, mixing raw and synthetic data benefits general reasoning tasks. Synthetic conversation data beats raw data in every combination tested. Conversations generated from a 4B model outperform a 14B model with 3.6x more data across all tasks. Pure synthetic data gives the biggest boost on math benchmarks, while blending raw and synthetic data improves general reasoning.
Across multiple benchmarks, training a 7B model on MIND-generated synthetic conversational data consistently outperforms raw data and the original pretraining blend in math, specialized knowledge, and general reasoning. Selecting the longest conversation per raw text yields the largest gains, and styles with knowledge gaps or collaborative problem solving, such as two students and debate, prove most effective, while two professors underperforms due to a lack of depth. Synthetic conversations also demonstrate efficiency, with a 4B teacher beating a larger 14B model trained on more raw data, and blending raw and synthetic data benefits general reasoning even as pure synthetic data maximizes math gains.