Command Palette
Search for a command to run...
과학 분야의 AI: 초기 통찰
과학 분야의 AI: 초기 통찰
초록
과학적 진보는 경제 성장과 번영의 핵심 동력이다. AI가 과학에 미칠 영향에 대해 큰 기대와 우려가 있지만, 지금까지 데이터는 거의 없다. 우리는 세 가지 데이터 소스, 즉 1,500만 건의 Gemini 상호작용 표본, 다양한 학문 분야에 걸친 2,600개 이상의 특화 AI 모델 목록, 그리고 600명 이상의 과학자를 대상으로 한 설문 조사를 통해 이에 대한 초기 통찰을 제공한다. 우리는 이러한 데이터를 과학적 작업의 새로운 분류 체계에 매핑하여 과학자들이 AI를 어떻게 사용하는지 연구한다. 네 가지 주요 발견이 도출된다. 첫째, 광범위한 채택과 적용 범위를 발견한다: 과학자들은 대부분의 다른 직업보다 AI를 더 많이 사용한다. 특화 AI 모델은 광범위한 학문 분야를 포괄하며 높은 인용도를 보인다. 설문에 응한 과학자의 거의 절반이 매일 어떤 형태로든 AI를 사용한다고 보고한다. 둘째, 우리는 LLM(Gemini 사용으로 대리 측정)과 특화 모델이 보완 관계로 작용한다는 증거를 문서화한다—LLM은 일반 분석, 코딩, 원고 작성에 사용되는 반면, 특화 모델은 도메인 특화 예측, 데이터 생성 및 분류를 제공한다. 셋째, 과학자들은 AI 사용으로 인한 큰 생산성 향상을 보고한다: 주당 약 7시간의 절약이며, 이 시간은 주로 더 많은 연구에 재투자된다. 마지막으로, AI가 이미 과학적 과정을 변화시키고 있음을 보여준다. 과학 연구의 일부 단계가 더 쉬워짐에 따라 병목 현상이 하류로 이동한다. 과학자들은 검증되지 않은 가설의 백로그 증가와 출력 검증에 대한 상당한 수요를 보고한다. 우리의 발견은 AI가 과학적 생산성을 높일 상당한 잠재력을 지니고 있음을 시사한다. 그러나 다른 분야와 마찬가지로, 그 궁극적인 영향은 복잡한 작업 간 상호 의존성과 새로운 병목 현상 제거를 위한 투자에 의해 좌우될 것이다.
One-sentence Summary
Researchers from Google, Google DeepMind, University of Chicago, CUNEF Universidad, MIT FutureTech, University of Oxford, Carnegie Mellon University, and University of Pennsylvania analyze 15×106 Gemini interactions, over 2600 specialized AI models, and surveys of 600 scientists, revealing broad AI adoption across disciplines, complementarity between LLMs and specialized models, nearly 7 hours of weekly productivity savings reinvested in research, and downstream bottlenecks such as untested hypotheses and output verification demands.
Key Contributions
- Introduces an early empirical analysis of AI adoption in science using three complementary data sources: 1.5 million Gemini interactions, an inventory of over 2,600 specialized AI models, and a survey of more than 600 scientists, all mapped to a new taxonomy of scientific tasks.
- Documents a complementary division of labor between general-purpose LLMs and specialized models, showing that LLMs handle general analysis, coding, and manuscript preparation while specialized models provide domain-specific predictions, data generation, and classification.
- Quantifies productivity gains and emerging bottlenecks: scientists report saving nearly 7 hours per week, reinvesting most of that time into research, yet nearly 90% of those users spend a meaningful share of saved time verifying AI outputs, and a growing backlog of untested hypotheses indicates downstream workflow constraints.
Introduction
Scientific progress has long been a driver of economic growth, but recent concerns about declining research productivity have sparked interest in whether AI can reverse this trend. While specialized models like AlphaFold have shown Nobel-caliber potential, the debate over AI's impact on science has relied mostly on lagging indicators like publications and patents, with little real-time evidence on how researchers actually use these tools.
The authors address this gap by combining three complementary data sources: 15 million Gemini interactions, bibliometrics from over 2,600 specialized AI models, and a survey of more than 600 scientists. They map all data to a new taxonomy of scientific tasks developed by MIT FutureTech, enabling task-level analysis across academic disciplines. Prior work lacked this granularity, as existing taxonomies like O*NET flatten the domain-specific activities that define research, and frontier AI lab telemetry had not been focused on scientific workflows.
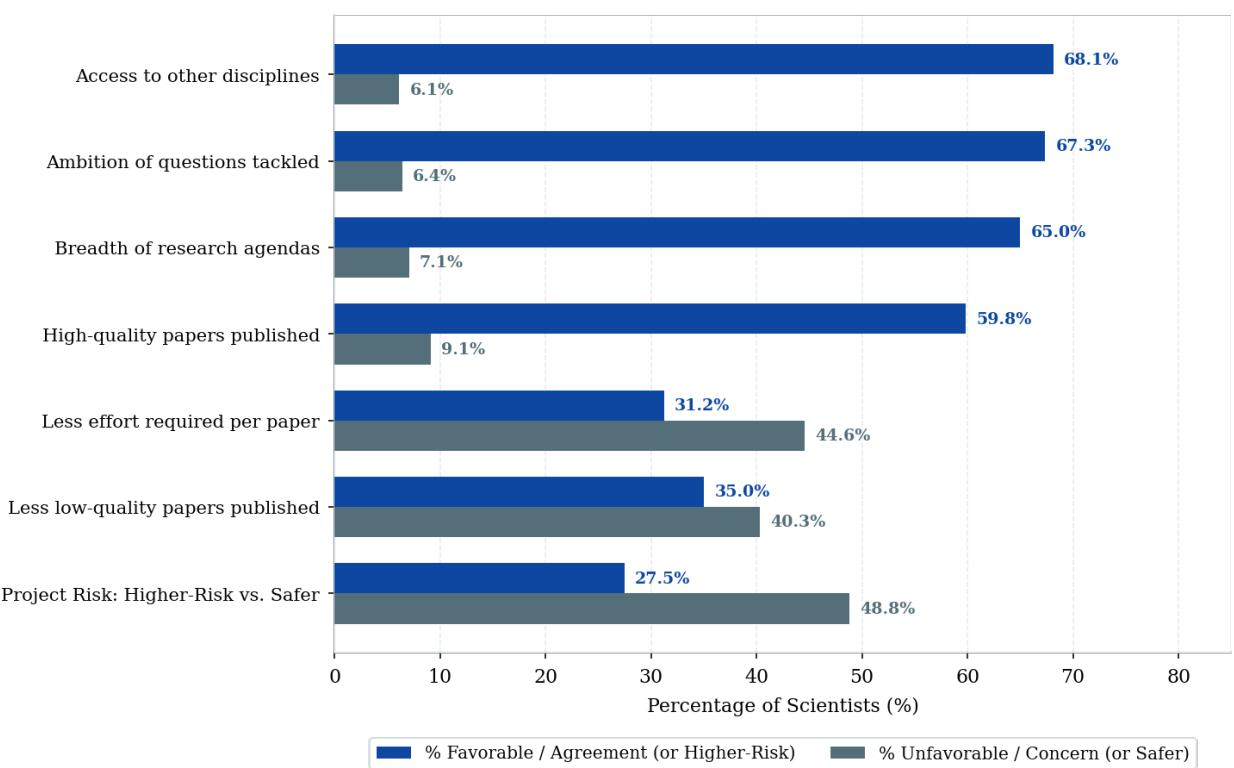
The main contribution is an empirical, multi-source snapshot of AI adoption in science. The analysis reveals that scientists lead other occupations in AI usage, that LLMs and specialized models act as complements with a clear division of labor, and that while researchers report substantial time savings, bottlenecks persist in physical experimentation and validation. The authors also document a concerning trend: nearly half of surveyed scientists say AI pushes them toward safer, incremental projects rather than high-risk discoveries, highlighting a potential "streetlight effect" where AI lowers the cost of incremental work without advancing the scientific frontier.
Dataset
Dataset Composition and Sources
The authors combine five complementary data sources to evaluate AI in science:
- Google ATLAS 1.0 corpus: approximately 15 million anonymized user interactions from the Gemini App, Google AI Mode, and API interfaces, sampled in early April 2026.
- Specialized AI for Science Model Inventory: a curated set of 2,690 notable AI models for science, assembled through agentic search across scientific repositories and literature, augmented by Epoch AI's Foundation Model database, and enriched with publication, citation, and institutional metadata from OpenAlex.
- Scientist Survey: a survey of 637 active scientists in the US and UK, run by a third-party provider through the More in Common online panel between 27 July and 11 August 2026.
- MIT FutureTech Scientific Task Taxonomy: built from approximately 3.8 million Lightcast (2026) scientific research job adverts posted after 2010.
- OpenAlex Publication Database: bibliometric records providing metadata on scientific works, including publication dates, author affiliations, funding sources, citations, and concept classifications.
Key Details for Each Subset
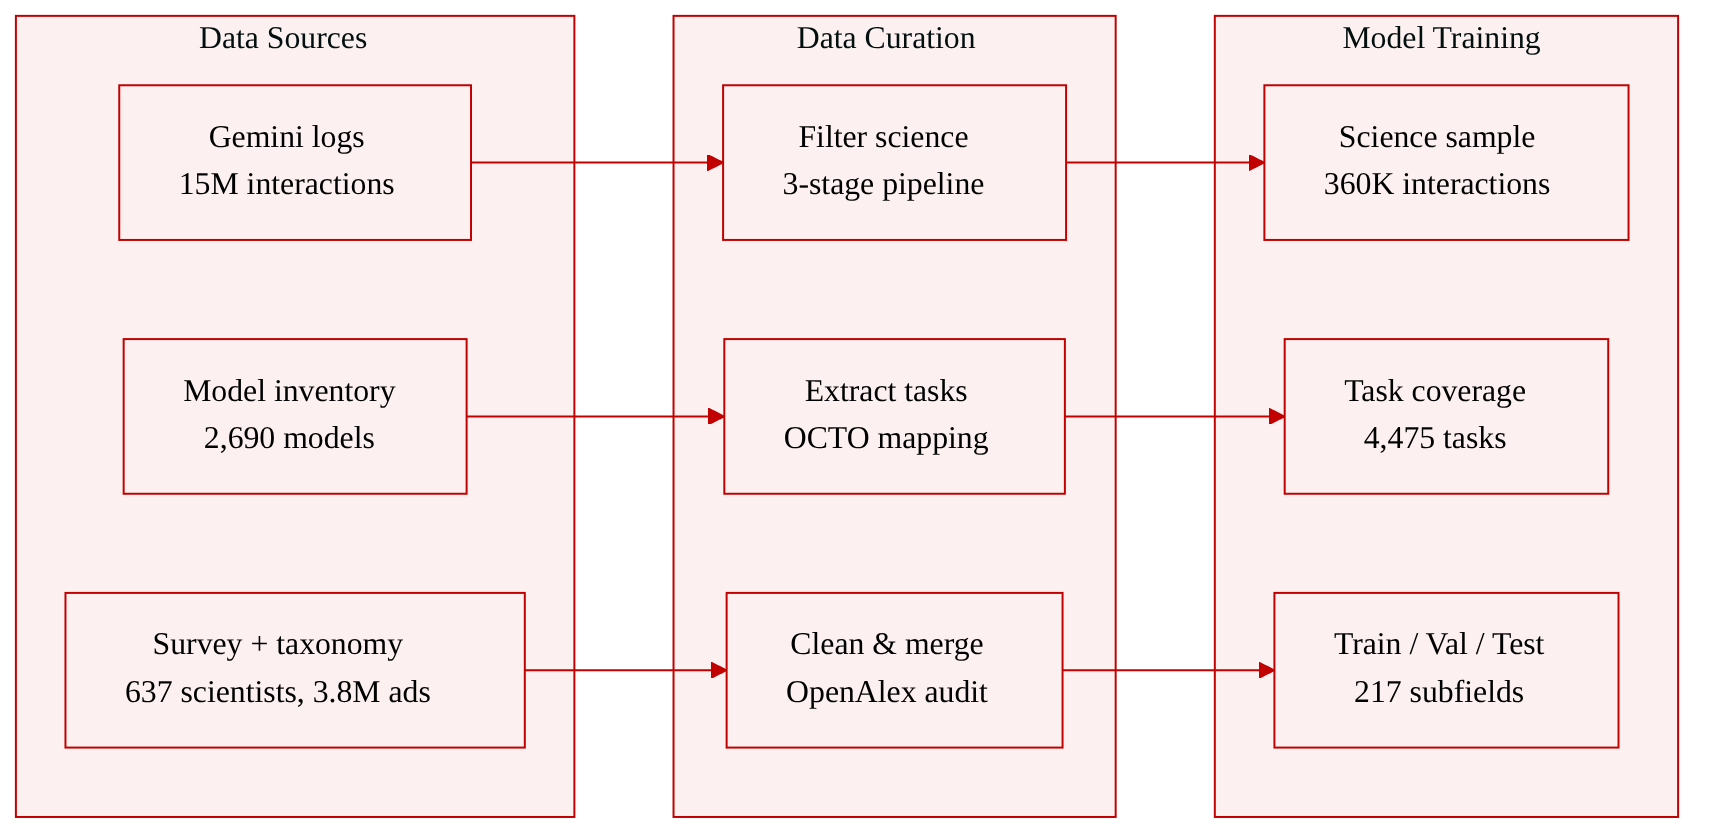
- Gemini Interaction Logs: The authors isolate scientific use cases through a three-stage filtering pipeline. First, they discard non-work interactions using ATLAS's work versus non-work classifier. Second, they apply ATLAS's occupation predictions, restricting the sample to six 2-digit Standard Occupational Classification (SOC) categories covering physical, life, social, computer, engineering, and health disciplines. Third, they apply a custom "science" classifier that operationalizes their definition of science. This yields about 360,000 science interactions from the initial 15 million.
- Specialized Model Inventory: The inventory includes domain-specific AI models (protein structure predictions, genomic models, neural climate models) and deep learning models (neural networks, diffusion models, vision transformers) that could help scientific discovery. The authors exclude general statistical ML (regularized regression, random forests) and general software or ML frameworks (PyTorch, TensorFlow). Models were published after 2012 and linked to a code repository. The inventory covers all 26 scientific fields in the OpenAlex taxonomy and 83% of the subfields.
- Scientist Survey: Participants were identified as scientists according to four criteria, including that their main job involves working directly in science and technology, clinical or health research, life sciences, or social science research. The survey collects information on demographics, fields of research, AI adoption intensity, time allocation across research tasks, expected time savings from AI, and perceived impacts on interdisciplinarity and bottlenecks.
- MIT FutureTech Scientific Task Taxonomy: The pipeline extracts over 64 million task instances from scientific job adverts, consolidates semantically equivalent instances into approximately 210,000 representative tasks, and organizes them under a global taxonomy of 12 Level-1 areas, 114 Level-2 areas, and 2,433 Level-3 groups. The hierarchy is built using hierarchical clustering of high-dimensional task embeddings and LLM analysis.
- OpenAlex: The authors audit and clean metadata to address known issues in OpenAlex classifications, such as its tendency to disproportionately assign computational and data-driven papers under Computer Science.
How the Paper Uses the Data
- Classification and Mapping: The authors use the OCTO pipeline, which integrates vector embeddings, clustering algorithms, and frontier Gemini LLMs, to map unstructured text into structured representations. OCTO classifies both Gemini interaction logs and publication abstracts against the MIT FutureTech Scientific Task Taxonomy and OpenAlex disciplinary hierarchy.
- Taxonomy Filtering: The authors focus analysis on 217 scientific subfields that have research activities across both commercial and non-commercial sectors, covering 92% of all OpenAlex works and 96.5% of citations. They exclude non-R&D subfields and aggregate others where domain boundaries were not sharp.
- Task Extraction: For specialized models, the authors use OCTO to extract 4,475 tasks from publication abstracts, formatted using the same verb / object / context structure as the MIT FutureTech Scientific Task Taxonomy. They map these tasks to the taxonomy to understand what tasks and fields could benefit from specialized model outputs.
- Survey Analysis: The survey data is used to assess broader economic and organizational impacts of AI, including bottlenecks in the research process, verification costs, and perceived impacts on research question ambition and quality.
Processing Details
- Science Definition: The authors adopt a broad definition of science, including academic, industry, non-profit, and government roles, and define science as any pursuit likely to generate new knowledge through investigation, computation, experimentation, or theoretical work.
- Occupational Over-Representation: The authors calculate an occupational over-representation ratio, comparing an occupational group's share of Gemini conversation volume to its baseline share of US employment. Research-intensive occupational families show about 1.8 times higher Gemini interaction volume than their labor force share.
- Science Interaction Characteristics: Compared to average work conversations, science interactions are about 7% more multimodal, 19% higher in token usage, 11% higher in number of turns, and measure 26% higher domain expertise score.
- Task Coverage: The authors find that 17.6% of Level-3 tasks in the taxonomy are covered by models in the inventory, rising to 24.3% when excluding operational and teaching tasks unlikely to be mentioned in publication abstracts.
Method
The authors leverage a comprehensive methodology to quantify scientific engagement with AI, utilizing two distinct data streams and a unified classification framework.
Gemini Interaction Logs Filtering Pipeline To isolate scientific use cases from the Google ATLAS 1.0 corpus, which contains approximately 15 million anonymized user interactions, the researchers implement a three-stage filtering pipeline. The first stage employs a work versus non-work classifier to discard interactions related to personal, leisure, or educational inquiries. In the second stage, the sample frame is restricted to six Standard Occupational Classification categories where research activities concentrate, including physical, life, social, computer, engineering, and health disciplines. The final stage applies a custom science classifier to the content and context of the interactions, identifying those likely to represent scientific workflows. This process yields a corpus of approximately 360,000 science-specific interactions.
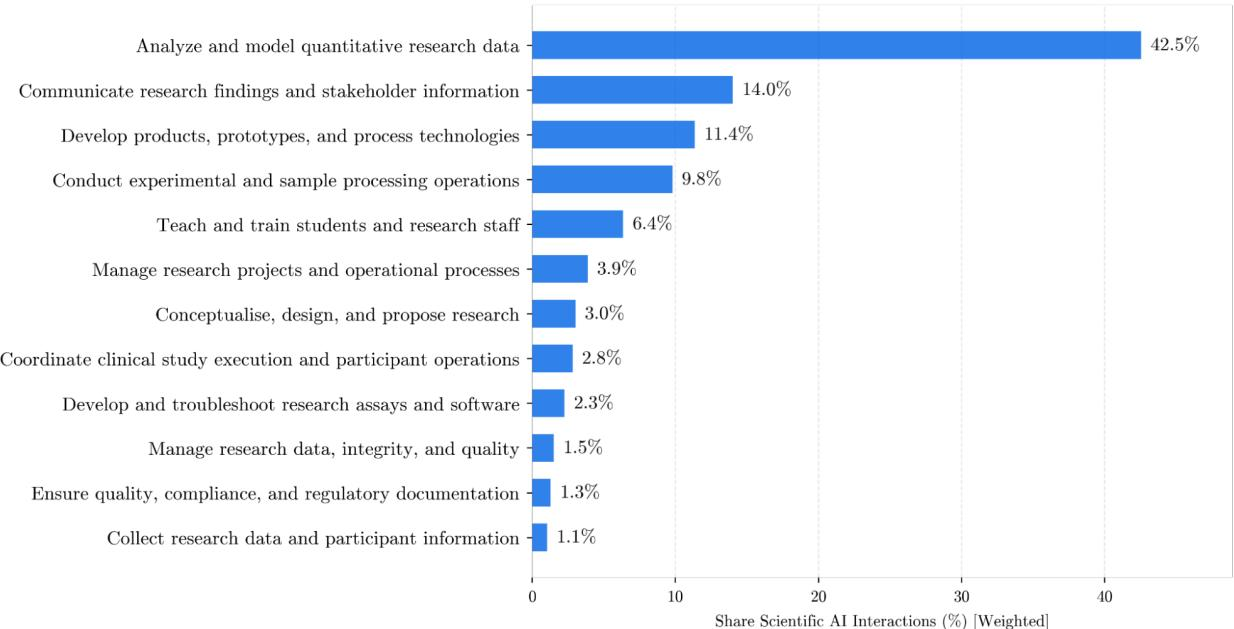
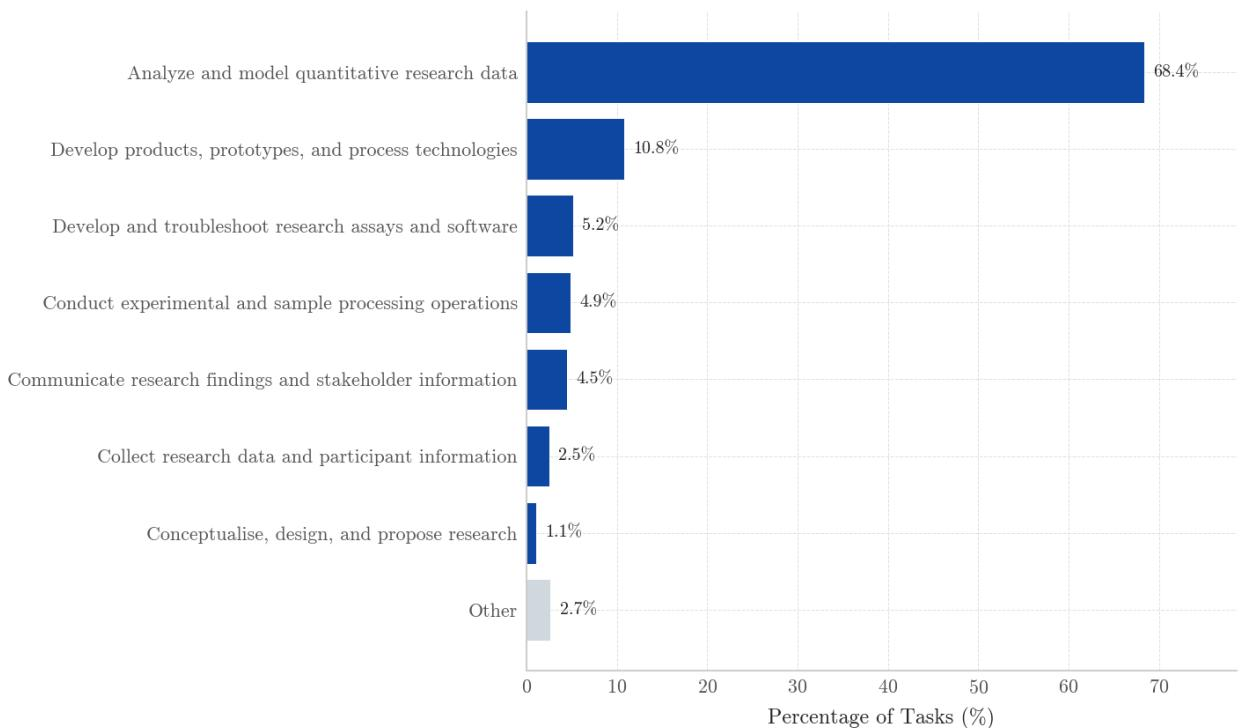
The authors then map this corpus using the OCTO classification framework across the OpenAlex disciplinary hierarchy and the MIT FutureTech Scientific Task Taxonomy. As shown in the figure below, the distribution of these interactions across high-level task categories indicates a heavy concentration in quantitative data analysis and modeling.
Specialized AI Model Inventory Construction Alongside general-purpose LLMs, the authors construct a curated inventory of 2,690 specialized AI models for science. This inventory is assembled through agentic search across scientific repositories and literature, augmented by the Epoch AI Foundation Model database, and enriched with publication and citation metadata from OpenAlex. The selection includes domain-specific models and deep learning architectures while excluding general statistical machine learning and software frameworks.
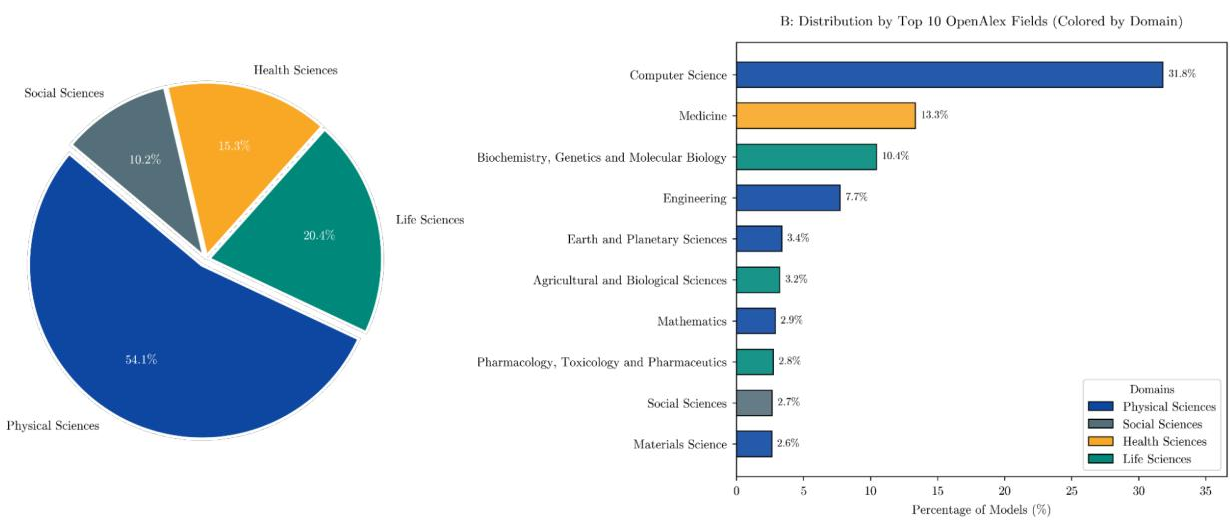
The distribution of these models across scientific domains is broad. As illustrated in the framework diagram, Physical Sciences and Computer Science dominate the inventory, though Life and Health Sciences also account for a significant portion of the models, particularly in fields like Biochemistry, Genetics, and Molecular Biology.
Task Extraction and Taxonomy Mapping To evaluate the downstream capabilities of the specialized models, the authors utilize the OCTO semantic classification tool to extract tasks from the abstracts of canonical publications. These tasks are formatted using a verb, object, and context structure and mapped to the MIT FutureTech Scientific Task Taxonomy. The extraction process identifies over 4,475 tasks associated with more than 200 unique actions.
The analysis of action verbs reveals distinct usage patterns across different scientific fields. Specialized models are primarily utilized for prediction, generation, and classification, though field heterogeneity reflects specific use cases, such as segmentation in Medicine or solving mathematical proofs in Mathematics.
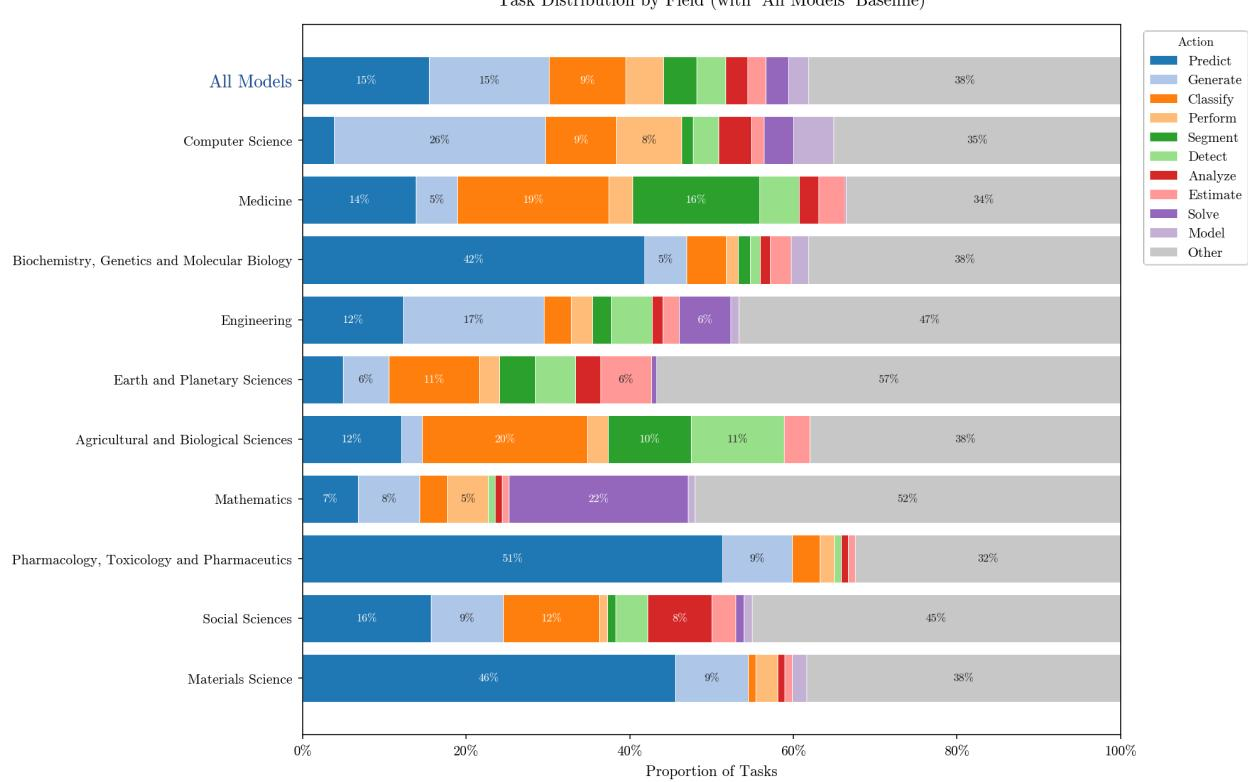
When mapping these extracted tasks to the MIT FutureTech Scientific Task Taxonomy, the authors find that nearly one in four substantive research tasks are covered by the capabilities in the inventory. The most common task category at the highest level of the taxonomy is the analysis and modeling of quantitative data, which aligns with the primary role of specialized models in predicting and simulating data for downstream analysis.
Experiment
The experiments analyze AI adoption in science by combining Gemini interaction logs, a specialized model inventory, and survey data. Results show LLM usage spans nearly all scientific subfields, led by physical and computer sciences, with usage scaling proportionally to researcher populations. Task analyses reveal that while both general LLMs and specialized models concentrate on data analysis, they operate as complements at granular levels, with specialized models handling domain-specific prediction and simulation. Survey data corroborate this picture, showing that most researchers use AI weekly and report net time savings reinvested into higher output, though verification of AI outputs and task bottlenecks temper productivity gains.
LLM adoption in science varies notably across disciplines, with each field showing distinct over- and under-represented task types relative to average researcher activity. Health and Life Sciences lean toward clinical and experimental tasks, while Computer Science and Physical Sciences favor software, data analysis, and prototyping tasks. Health Sciences shows nearly five times higher relative use for clinical study coordination, with compliance and regulatory documentation also overrepresented. Life Sciences has over three times higher relative use for experimental and sample processing tasks. Computer Science is overrepresented in software troubleshooting and quantitative data analysis, while Physical Sciences is overrepresented in prototype and process technologies. Social Sciences is overrepresented in data collection, teaching, and project management, but underrepresented in experimental and product development tasks. Clinical study coordination is consistently underrepresented in Computer Science, Physical Sciences, and Life Sciences, while experimental operations are underrepresented in Computer Science and Social Sciences.
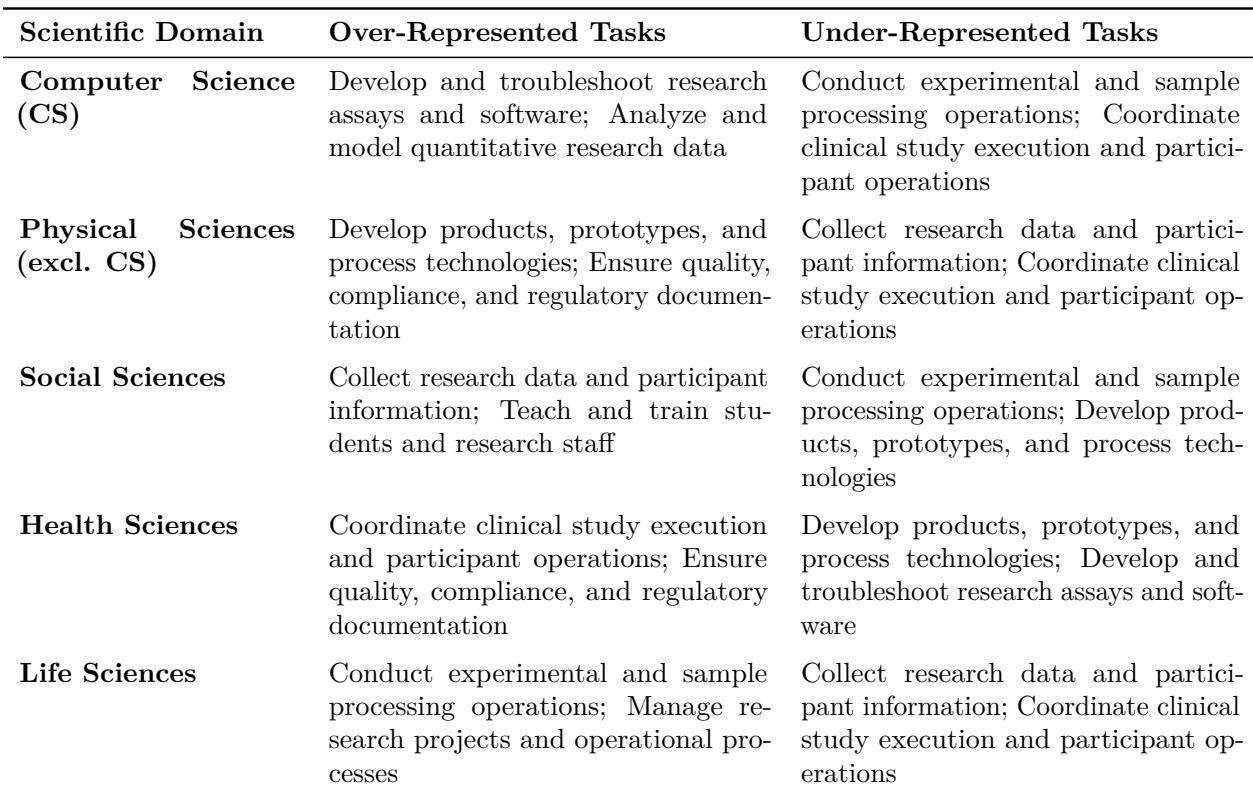
An analysis of LLM adoption across scientific disciplines reveals distinct task-level specialization patterns. Health and Life Sciences show strong overrepresentation in clinical, experimental, and compliance-related tasks, while Computer Science and Physical Sciences favor software, data analysis, and prototyping. Social Sciences are overrepresented in data collection, teaching, and project management but underrepresented in experimental work. Notably, clinical study coordination is consistently underrepresented in Computer Science, Physical Sciences, and Life Sciences, whereas experimental operations are underrepresented in Computer Science and Social Sciences.