Command Palette
Search for a command to run...
Game2Player: 환경-플레이어 공동 개발을 통한 시각 에이전트의 게임플레이 경험 확장
Game2Player: 환경-플레이어 공동 개발을 통한 시각 에이전트의 게임플레이 경험 확장
초록
게임은 지각, 장기 계획, 정밀한 제어를 요구하는 시각 에이전트의 풍부한 테스트베드이다. 그러나 인간 게임플레이 수집은 비용이 많이 들고, 게임플레이 비디오로부터 학습하려면 누락된 행동을 추론해야 한다. 기존 데이터셋은 또한 제한된 범위의 게임만을 다루며, 명시적 작업이나 검증 가능한 결과가 없는 경우가 많다. 이러한 격차를 해소하기 위해 우리는 게임 환경과 플레이어를 공동 개발하여 다양하고 검증 가능한 게임플레이 경험을 대규모로 수집하는 프레임워크인 Game2Player를 소개한다. Game2Player 루프에서 Builder 에이전트는 기존 웹 게임을 각색하고, 내부 상태를 노출하며, 상태 기반 진행 측정 및 성공 확인 기능을 갖춘 작업을 정의한다. Coding Player와 VLM Player는 이후 작업을 시도하고 문제점을 Builder에게 보고하여 수리하도록 함으로써, 플레이가 환경 검증과 훈련 데이터 수집의 역할을 동시에 수행하게 된다. Game2Player를 통해 우리는 3,436개의 작업이 포함된 568개의 검증된 웹 게임을 구축하고, 15.7K개의 궤적(307시간의 게임플레이)을 수집했으며, 50개의 게임을 벤치마크인 PlayerBench로 분리해 두었다. 수집된 경험을 훈련 데이터로 평가하기 위해, 작업 진행을 진전시키는 단계에 더 큰 가중치를 부여하는 진행 가중 SFT로 VLM 에이전트를 훈련한다. Game2Player-9B는 PlayerBench에서 진행률을 14.3%에서 31.2%로, 외부 GameWorld 벤치마크에서 30.0%에서 53.1%로 향상시킨다. 더 넓게 보면, 우리의 연구는 시각 에이전트가 기존 게임 세계를 구축하고, 검증하고, 학습함으로써 게임플레이 경험을 확장할 수 있는 경로를 제시한다.
One-sentence Summary
Researchers at UIUC and collaborators introduce Game2Player, a framework that co-develops game environments and players through a Builder agent, a Coding Player, and a VLM Player to collect 568 verified web games, 3,436 tasks, and 15.7K trajectories, and then trains Game2Player-9B with progress-weighted SFT, improving progress on PlayerBench from 14.3% to 31.2% and on GameWorld from 30.0% to 53.1%.
Key Contributions
- Game2Player is introduced as a framework that co-develops game environments and players: a Builder agent adapts existing web games, exposes internal state, and defines tasks with state-based progress measures and success checks, while Coding and VLM players attempt tasks and report problems for repair.
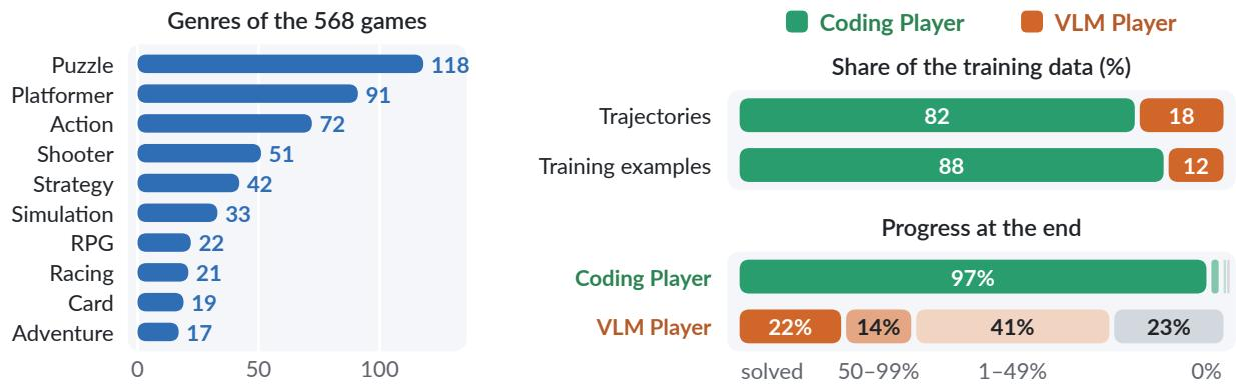
- The framework is used to build 568 verified web games with 3,436 tasks, collect 15.7K trajectories totaling 307 hours of gameplay, and hold out 50 games as the PlayerBench benchmark.
- Progress-weighted supervised fine-tuning assigns greater weight to steps that advance task progress; the resulting Game2Player-9B agent improves progress from 14.3% to 31.2% on PlayerBench and from 30.0% to 53.1% on the external GameWorld benchmark.
Introduction
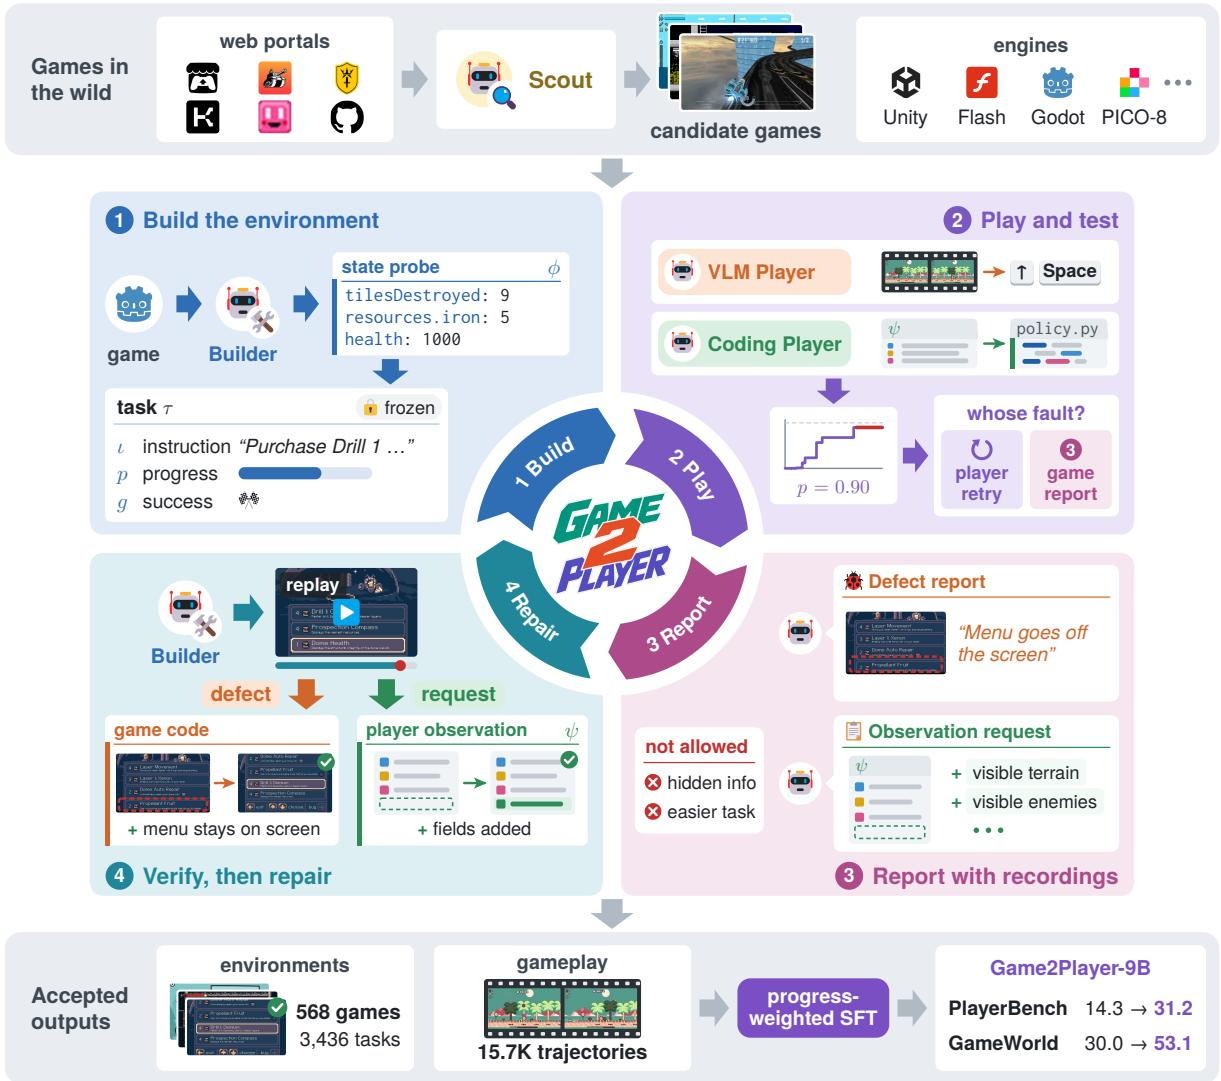
Visual agents powered by vision-language models have advanced on computer-use and embodied tasks, but video games raise a harder challenge because each game brings its own visuals, rules, and controls that an agent must infer while acting with precise timing. Collecting gameplay experience at scale has been limited by costly human recordings, online videos that lack actions and require inverse-dynamics or latent-action recovery, and game-specific engineering for interactive environments. Coding agents can help build environments, yet they may pass their own tests even when tasks are impossible, progress measures fail, or success checks trigger too early. The authors introduce Game2Player, a framework in which a Builder agent and two players, a VLM Player and a Coding Player, co-develop verifiable environments from in-the-wild web games through gameplay feedback, then use the complementary demonstrations for progress-weighted supervised fine-tuning and build PlayerBench for evaluation.
Dataset
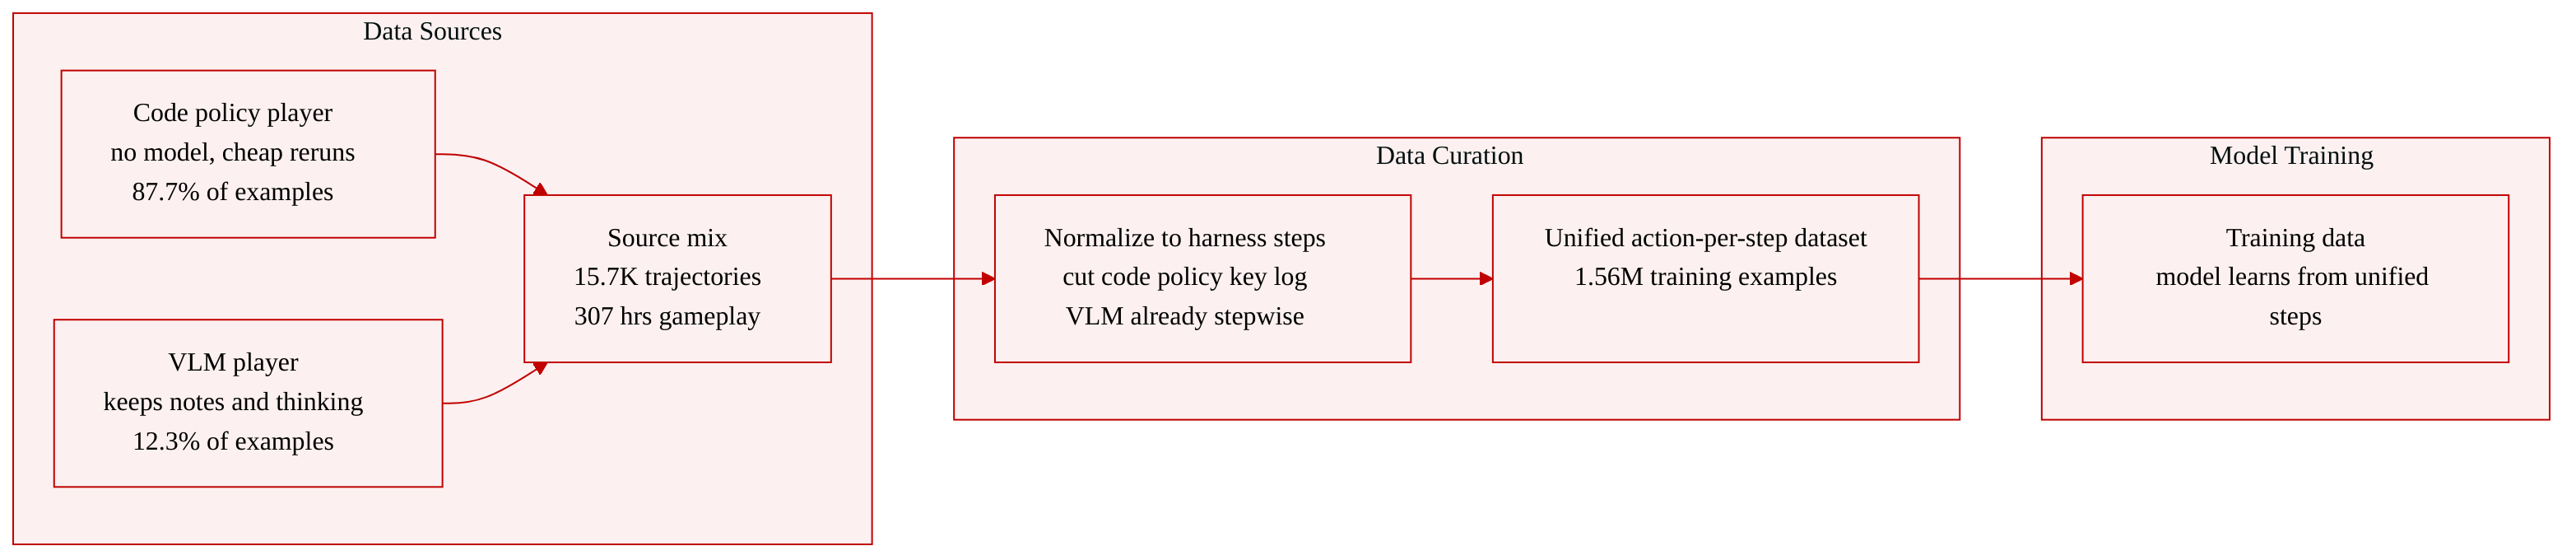
The authors collect training gameplay in the accepted environments from two complementary players and merge the data into one format.
Sources:
- Code policy player: plays without calling a model, so it can be rerun from new seeds at low cost. It supplies most of the examples.
- VLM Player: keeps model notes and thinking, and covers tasks that the code policy does not complete.
Scale and composition:
- Total recorded data: 15.7K trajectories and 307 hours of gameplay.
- Resulting training examples: 1.56M.
- Code policy data contributes 87.7% of training examples.
- VLM Player data contributes 12.3% of training examples.
Processing:
- VLM Player episodes already follow the harness format, with one action per step.
- Code policy actions are continuous, so the authors cut its recordings into harness steps.
- The recorder logs every key press and release with its timestamp, and this log is converted into harness actions.
Usage:
- The unified action-per-step dataset is used as training data for the model.
Method
The authors introduce Game2Player, a framework that transforms open-source web games into verifiable environments for training visual agents. The pipeline begins with a Scout module that identifies games playable offline in a browser. A Builder agent then converts each game into an environment, while a VLM Player and a Coding Player test and play every task within it.
To ensure the environments are robust, the authors employ an environment-player co-development loop. The Builder first proposes a task plan and packages the game for offline play, defining a state probe, control guide, and task-specific start routines, progress functions, and success predicates. The VLM Player interacts with the game using only screenshots and a control guide, pausing the game to reason about actions. The Coding Player writes a Python policy that reads player-visible state and executes actions in real time. Both players test the environment and report failures. If a player traces a failure to the environment, it files a defect report or an observation request. The Builder then verifies the claim by replaying the recorded episode. If the claim is valid, the Builder repairs the game code, state probe, or player observation. This cycle repeats until the environment is accepted. The resulting collection spans diverse genres and engines, with the Coding Player providing the majority of the training examples due to its high success rate.
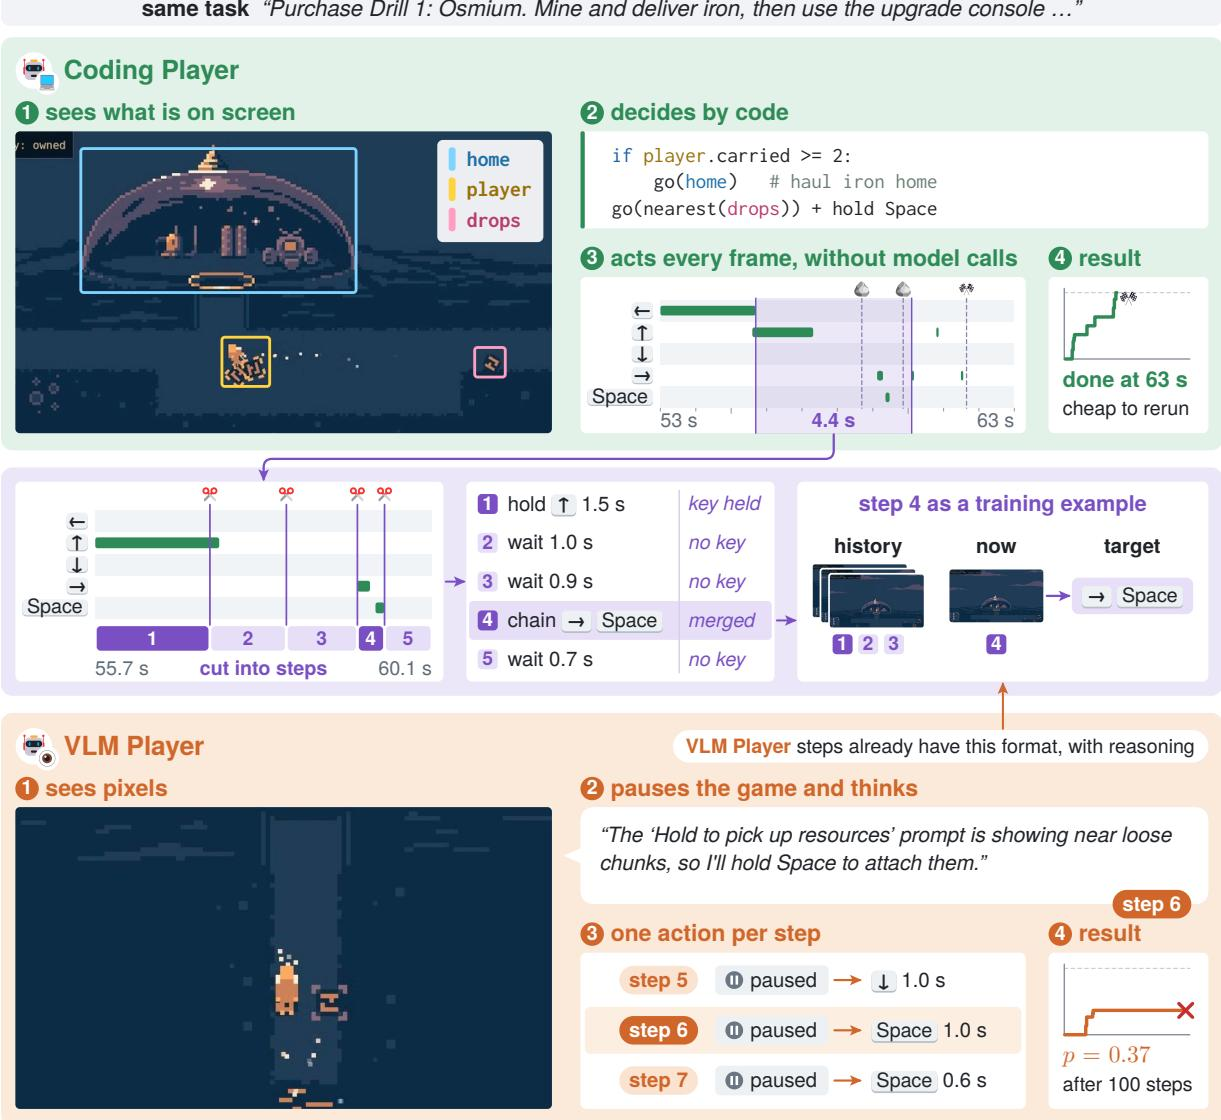
Once environments are accepted, both players record gameplay trajectories for training. The VLM Player episodes naturally follow a step-by-step harness format, recording screenshots, actions, and reasoning notes. The Coding Player, however, acts continuously. To unify the data, the authors segment the continuous key press and release logs from the Coding Player into discrete harness steps, matching the format of the VLM Player.
Finally, the authors train a visual agent using progress-weighted supervised fine-tuning (SFT). Since trajectories contain many passive actions, they use the recorded progress pt to weight training examples. Each example pairs a harness context xt with a target yt. The weight wt for each example is calculated as:
wt∝ρt⋅max(1,ct)where the credit ct increases the weight of actions immediately preceding a progress increase or success, and the penalty ρt reduces the weight of repeated actions or actions at the end of failed episodes. To prevent long games from dominating, weights are scaled down for games with many examples. Instead of directly weighting the loss, the authors stochastically round each weight to an integer multiplicity mt such that E[mt]=wt, and resample the examples to minimize:
L(θ)=−t∑mtlogπθ(yt∣xt)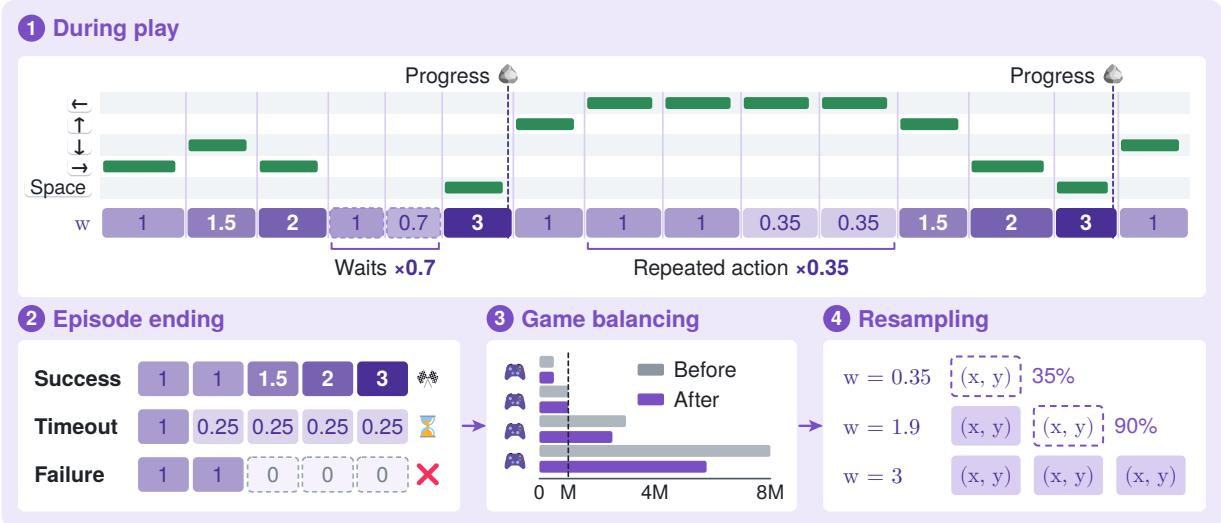
Experiment
The evaluation uses PlayerBench, a held-out split of 50 games and 287 tasks from the Game2Player collection, and GameWorld, an independently built benchmark of 34 browser games and 170 tasks, with models given a single 100-step attempt and scored on progress and success. A controlled co-development study shows that player reports to the builder reduce incorrect environments and increase solved tasks compared with a generic coding agent, while code-policy recording is far cheaper than VLM play. Main results find PlayerBench to be more challenging than GameWorld, with training roughly doubling PlayerBench progress and transferring to GameWorld, and with thinking becoming more useful after fine-tuning; ablations attribute gains to progress weighting, larger data volume, and complementarity between VLM and code-policy data, and case studies show learned precise timing control on held-out tasks.
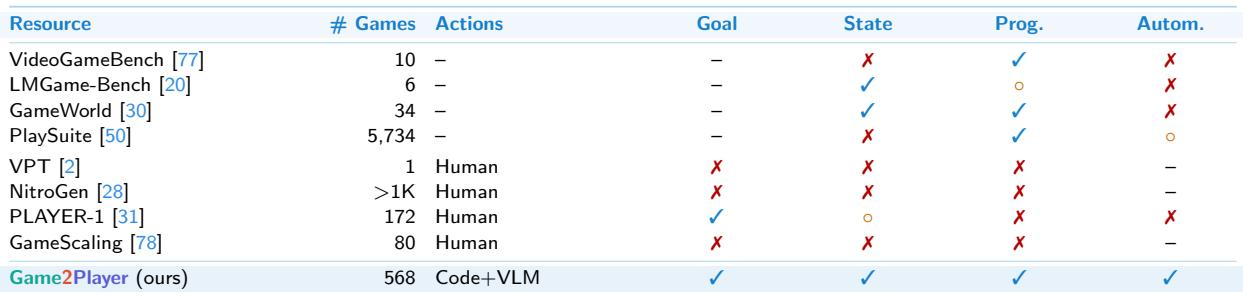
Existing resources separate into benchmarks without a listed action source and human gameplay datasets with explicit actions but limited scoring. Benchmarks commonly track intermediate progress and sometimes read internal state, while human datasets generally lack progress signals and only PLAYER-1 fully carries task instructions. Automation is mostly absent or partial, whereas Game2Player is described as automatically creating state-verified environments and collecting instruction-carrying, progress-scored trajectories. Game benchmarks and human gameplay datasets split clearly: the benchmarks do not list an action source, while the human datasets provide explicit human actions. Intermediate progress scoring is common among benchmarks but absent from all three human gameplay datasets in the comparison. GameWorld is the only benchmark with both internal state scoring and intermediate progress scoring. Automation is rare in the listed resources, with only PlaySuite partially automated, while Game2Player is described as automatically building state-verified environments.
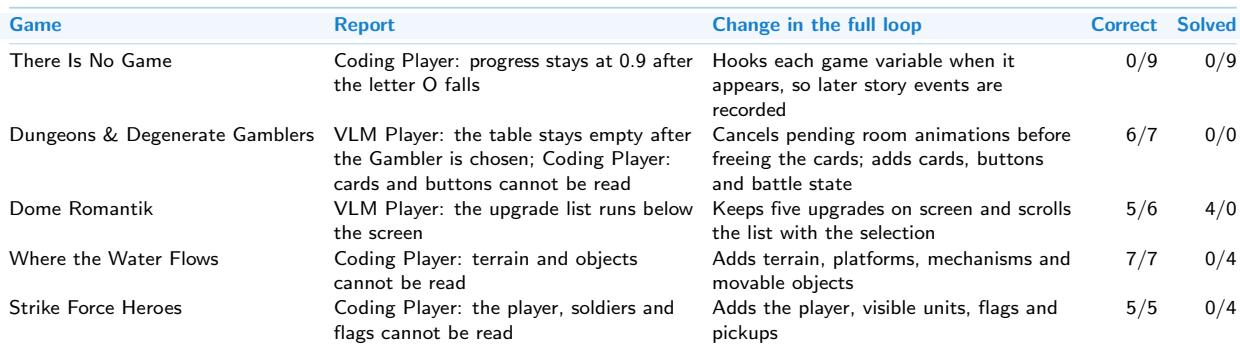
The full reporting and repair loop improves environments over the no-reports baseline, both by fixing incorrect tasks and by making previously blocked tasks solvable. Reports typically come from a Coding Player that cannot read game state or a VLM Player that sees missing or offscreen UI elements, and repairs add the needed state or interface access. Gains range from one additional correct environment to all tasks becoming correct and solved in a previously stuck game. In There Is No Game, a progress stall report leads to variable hooks, after which all nine tasks are correct and solved while the no-reports setting leaves them all wrong. In Where the Water Flows and Strike Force Heroes, reports about unreadable terrain, objects, players, and flags lead to added visible game state and raise solved tasks from zero to four. In Dungeons & Degenerate Gamblers, a report about an empty table and unreadable cards and buttons leads to cancelling pending animations and exposing card, button, and battle state, increasing correct environments.
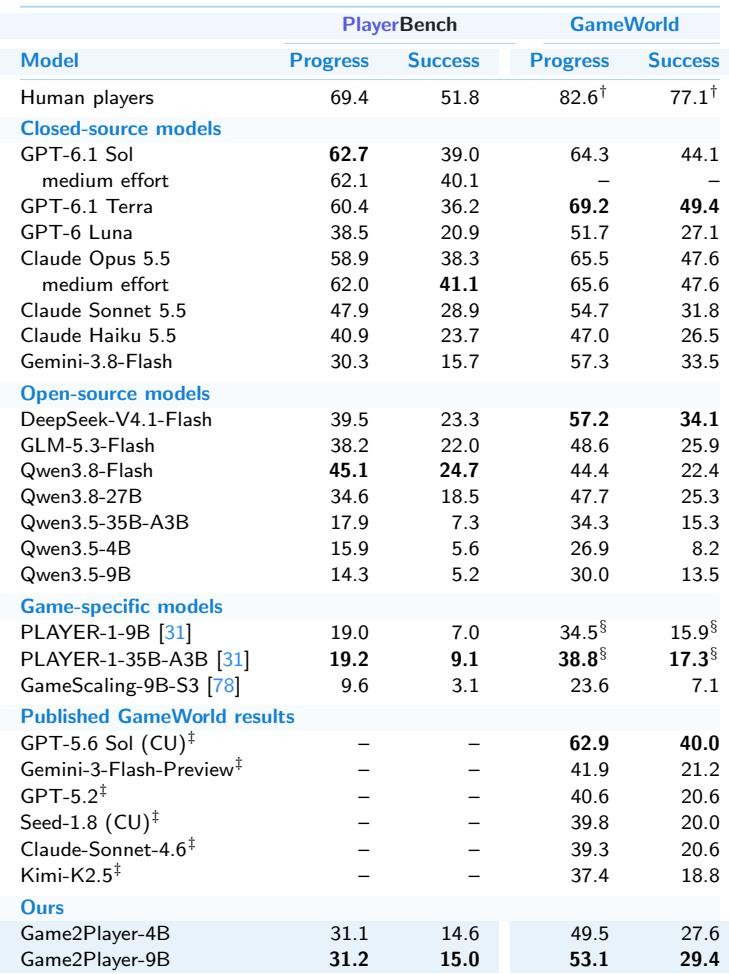
PlayerBench is consistently more challenging than GameWorld, with human players and most evaluated models earning lower progress and success on it. Human players achieve the highest scores on both benchmarks, outperforming the evaluated closed-source models. Among closed-source models, GPT-6.1 Sol tends to lead on PlayerBench while GPT-6.1 Terra leads on GameWorld, and GPT-6 Luna trails clearly. Human players outperform all evaluated closed-source models on both PlayerBench and GameWorld. GameWorld scores are generally higher than PlayerBench scores for humans and the listed models. GPT-6.1 Sol has the strongest PlayerBench progress among closed-source models, while GPT-6.1 Terra has the strongest GameWorld progress. GPT-6 Luna posts the lowest progress and success on both benchmarks among the closed-source models shown.
Data source and sampling strategy affect the two benchmarks differently. VLM player data is more sample efficient for PlayerBench, while code policy data alone gives the strongest GameWorld performance, and combining both sources helps the larger model on PlayerBench. Progress-weighted training outperforms uniform sampling across both model sizes and benchmarks, and additional data keeps improving PlayerBench while GameWorld progress plateaus after early training steps. VLM player data raises PlayerBench performance far more efficiently than a larger code policy dataset. Code policy data alone yields the best GameWorld progress for both the 4B and 9B models. Combining both data sources gives the strongest PlayerBench result for the 9B model, while the 4B combination sits between single-source results. Progress-weighted supervised fine-tuning outperforms uniform sampling on both benchmarks for both model sizes. More training data continues to improve PlayerBench, while GameWorld progress plateaus after early training steps.
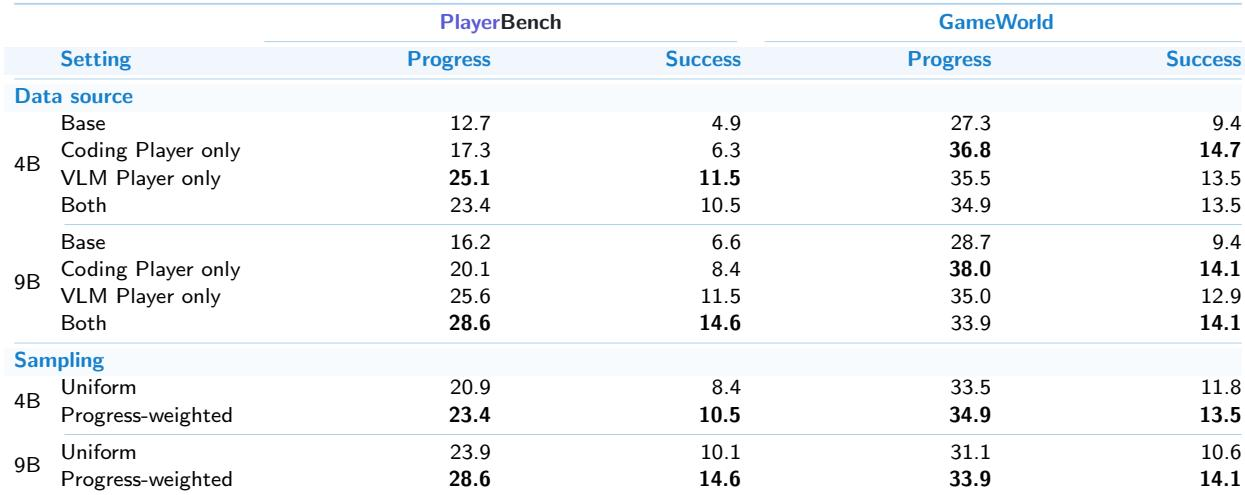
The paper first situates Game2Player among existing resources, noting that benchmarks typically lack explicit action sources while human datasets lack progress scoring, and automation is rare in prior work. A reporting and repair loop is then shown to improve environments over a no-reports baseline by fixing incorrect tasks and making previously blocked games solvable, often by exposing missing game state or interface access. Evaluations indicate that PlayerBench is consistently more challenging than GameWorld, with human players outperforming all closed-source models, while data source and sampling studies show VLM data is more sample efficient for PlayerBench, code policy data alone is best for GameWorld, combining sources helps the larger model only on PlayerBench, and progress-weighted training outperforms uniform sampling as GameWorld progress plateaus early.