Command Palette
Search for a command to run...
Gamer: 장기 지평 실시간 게임 에이전트를 위한 범용 비전-언어-행동 기반 모델
Gamer: 장기 지평 실시간 게임 에이전트를 위한 범용 비전-언어-행동 기반 모델
초록
본 논문은 복잡한 상호작용 환경에서 장기 지평 과제를 수행하도록 설계된 범용 에이전트 프레임워크인 Gamer를 소개한다. Gamer의 종단 간 아키텍처는 인지, 메모리 관리, 다단계 추론을 결합한다. 공유된 훈련 및 배포 파이프라인은 기존의 2D 그래픽 인터페이스와 복잡한 3D 시뮬레이션 세계 모두와의 상호작용을 지원한다. 먼저 수만 시간에 달하는 기기 수준의 키보드 및 마우스 상호작용 데이터로 구성된 데이터셋을 이용해 사전 훈련을 지속한다. 이 궤적들은 시뮬레이션 게임과 체화된 환경을 아우르며, 모델이 물리적 영역과 가상 영역 모두에서 환경 역학을 학습할 수 있게 한다. 희소 사고 명령 튜닝은 복잡한 의사결정에 필요한 추론 능력을 유지하면서 중복 계산을 크게 줄인다. 유한 컨텍스트 창, 누적된 롤아웃 오류, 희소 보상을 해결하는 안정적인 다중 턴 강화학습 방법으로 장기 지평 상호작용을 위한 정책을 훈련한다. 실시간 상호작용을 위해 클라우드-엣지 추론 엔진이 다수의 시뮬레이션 게임 환경을 동시에 서비스하고, 무한 컨텍스트 실행을 지원하며, 온라인 추론 지연 시간을 낮게 유지한다. 여러 도전적인 3D 오픈월드 게임에서 Gamer는 숙련된 플레이어에 필적하는 견고한 일반화와 운영 효율성을 입증한다. 또한 다양한 기존 2D 게임 벤치마크에서도 경쟁력 있는 결과를 달성한다. 이러한 결과는 반복적인 키보드 및 마우스 궤적만으로도 데이터와 학습 알고리즘의 확장을 통해 상당한 성능 향상을 이끌어낼 수 있음을 시사한다. 이러한 궤적을 활용한 훈련은 물리적 속성과 디지털 속성을 모두 지닌 환경에서 Gamer가 복잡한 기술을 더욱 안정적으로 학습하도록 돕는다. 이 접근법은 디지털 세계와 물리적 세계 전반에서 상호작용할 수 있는 범용 에이전트로 나아가는 경로를 제시한다.
One-sentence Summary
Researchers from miHoYo Honkai AI R&D Team, National University of Singapore, Tsinghua University, University of Chinese Academy of Sciences, University of Science and Technology of China, and Xi'an Jiaotong University introduce Gamer, a generalist vision-language-action foundation model for long-horizon real-time game agents that combines perception, memory management, and multi-step reasoning, trained by continued pretraining on tens of thousands of hours of device-level keyboard and mouse trajectories, sparsethinking instruction tuning, and stable multi-turn reinforcement learning, with a cloud-edge inference engine enabling real-time, low-latency interaction across challenging 3D open-world games and conventional 2D game benchmarks.
Key Contributions
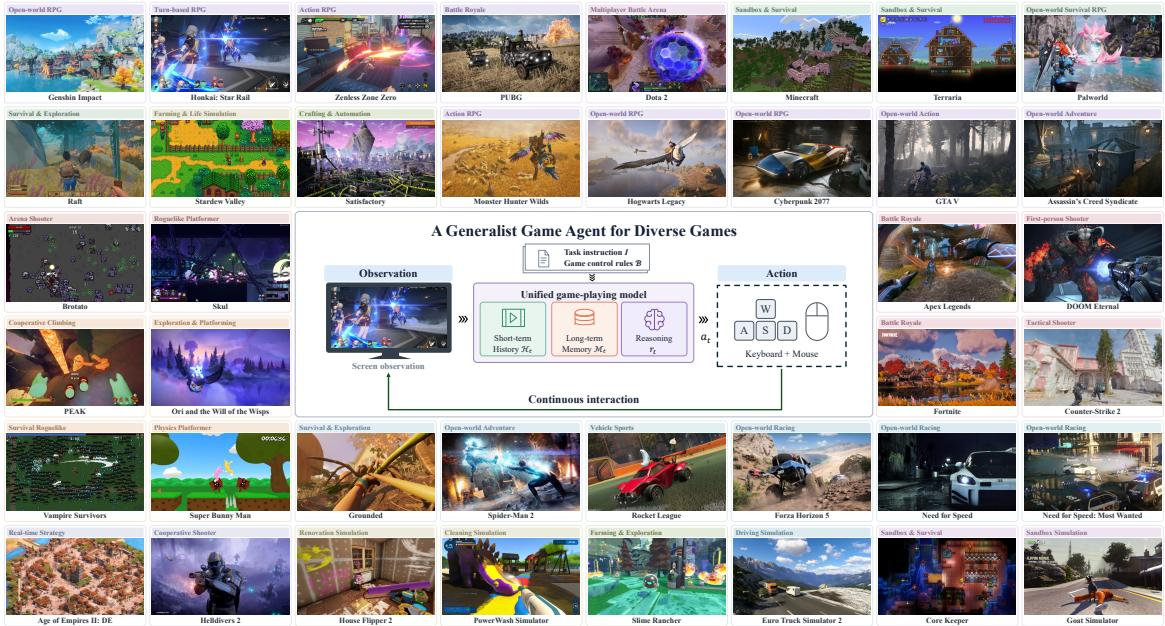
- Gamer is a generalist agent framework with an end-to-end architecture combining perception, memory management, and multi-step reasoning for long-horizon tasks. It uses screen observations and a unified keyboard and mouse action space across conventional 2D graphical interfaces and complex 3D simulated worlds.
- The training pipeline continues pre-training on tens of thousands of hours of device-level keyboard and mouse trajectories, then applies sparsethinking instruction tuning and Temporal-Aware Group Relative Policy Optimization (TA-GRPO). This reduces redundant computation and stabilizes long-horizon reinforcement learning under finite context windows, accumulated rollout errors, and sparse rewards.
- Streaming-vLLM serves as a cloud-edge inference engine supporting concurrent game instances, unbounded-context execution, and low-latency real-time interaction. Gamer achieves operational efficiency comparable to skilled players on challenging 3D open-world games and competitive performance on standard 2D game benchmarks.
Introduction
Multimodal large language models are evolving into interactive agents, and vision-language-action models offer a path toward embodied general intelligence, but evaluating real-world physical agents is hindered by high trial-and-error costs and limited environmental controllability. Modern large-scale games provide a controlled yet demanding benchmark, but existing game agents typically depend on privileged internal states, tailored action spaces, or dedicated APIs, and conventional inference latency can cause actions to lag behind changing game states, weakening both closed-loop control and online reinforcement learning. The authors present Gamer, a generalist agent framework that uses raw screen pixels as input and native keyboard-and-mouse actions as a unified interface, combining continued pre-training on multi-source gameplay, LLM-assisted long-horizon instruction data construction, sparse-thinking instruction tuning, Temporal-Aware Group Relative Policy Optimization, and a real-time Streaming-vLLM inference system.
Dataset
Sources and composition
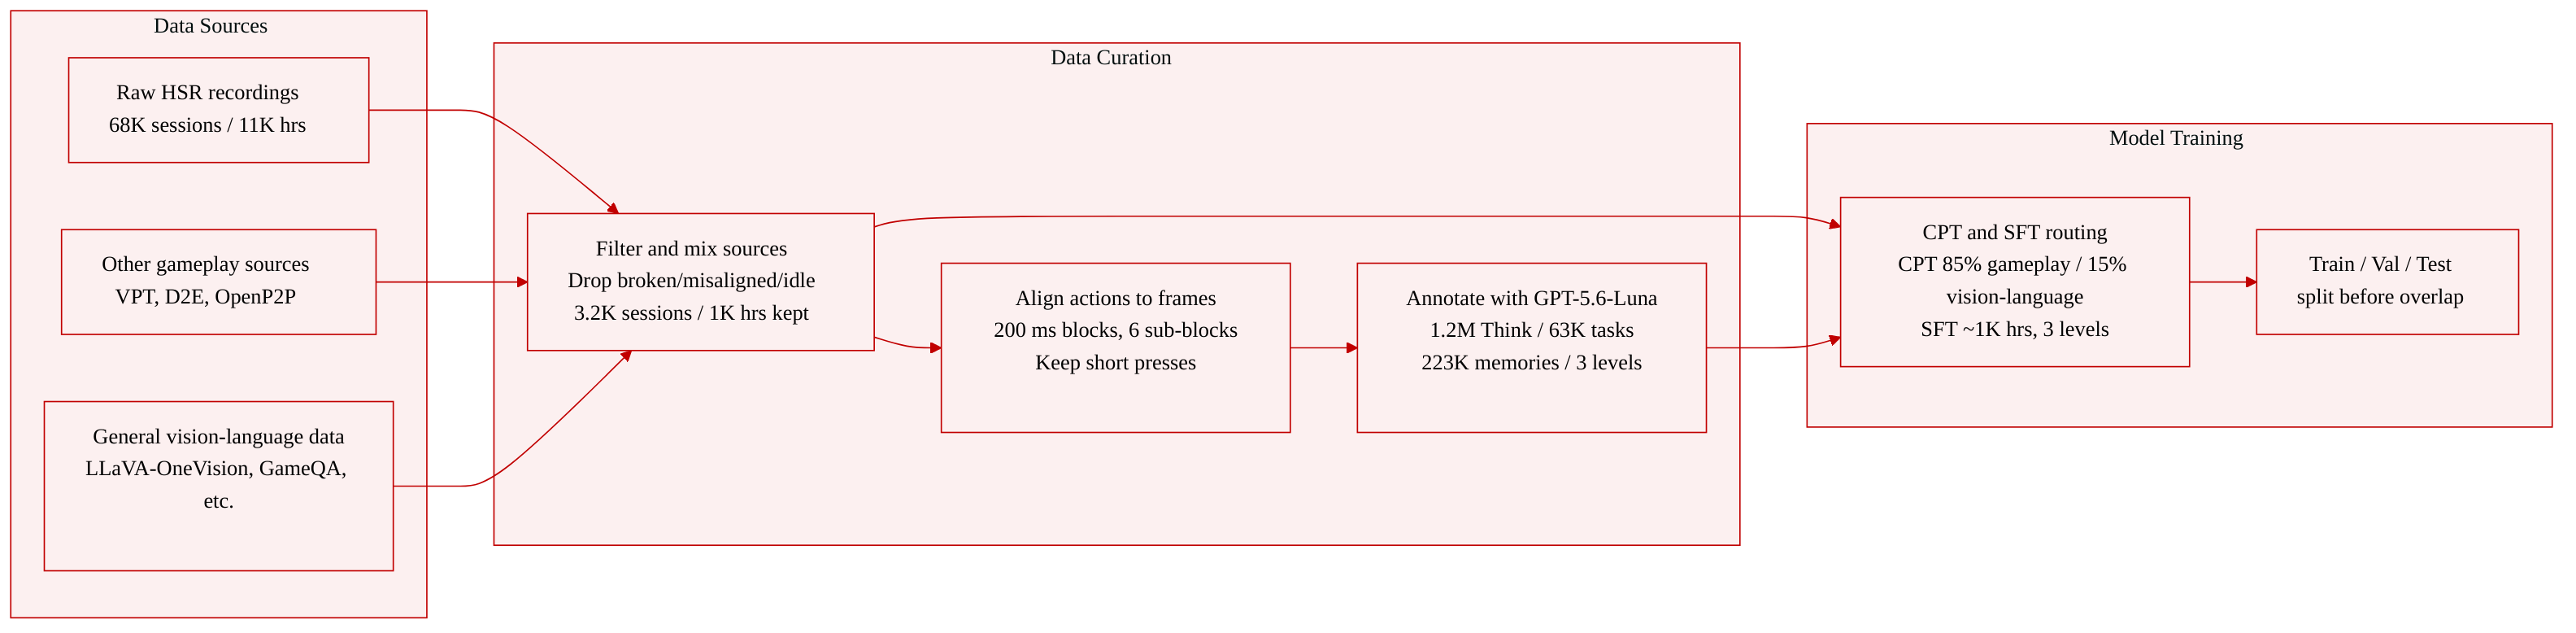
- The authors collect raw gameplay recordings with associated keyboard and mouse events from multiple sources.
- The HSR recording track contains roughly 68K sessions and 11K hours of video.
- After filtering and scenario balancing, approximately 3.2K sessions and 1K hours are retained for SFT annotation.
- In the HSR portion of the CPT corpus, filtering retains about 149K aligned clips, corresponding to around 332 hours of gameplay.
- Other gameplay sources used in CPT scaling include VPT, D2E, and OpenP2P.
- General vision-language sources include LLaVA-OneVision, Zebra-CoT, GameQA, Embodied-Reasoner, and Cambrian-S.
Filtering and coverage balancing
- The authors reject corrupted or duplicated sessions, missing or discontinuous frames, and trajectories whose video and action timestamps cannot be aligned consistently.
- Invalid action traces are removed, including mouse coordinates outside valid screen or control bounds, malformed action states, and events crossing recording or interaction boundaries.
- Long inactive periods and recordings without meaningful interaction are filtered out, while valid held inputs and task-related waiting periods are retained.
- The authors also downsample overrepresented streams and excessively idle intervals, balancing coverage by retaining less frequent interactions and longer task transitions.
Action-observation alignment
- The original ordering of keyboard and mouse events is preserved.
- Each action block is associated with its corresponding frame using corrected recording timestamps.
- Each device-level action interval spans approximately 200 ms and contains six finer control blocks.
- An action window is not allowed to cross frame gaps, discontinuous indices, or recording boundaries.
- Short button presses are kept as short pulses rather than being dropped by temporal aggregation.
Annotation outputs
- Sparse reasoning: The authors divide the action stream into windows of 50 device-level action intervals, roughly 10 seconds of interaction. Each window contains 25 ordered game observations and the associated 50 action intervals. GPT-5.6-Luna identifies sparse decision points and produces about 1.2M timestamp-aligned Think annotations.
- Visual task segmentation: Each session is divided into equal-length visual clips of at most 288 seconds. Frames are sampled at roughly one-second intervals and arranged into 3x2 timestamped mosaics, with at most 49 mosaics per clip. GPT-5.6-Luna identifies contiguous task segments and assigns each a task instruction, gameplay label, and short scene description. This yields about 63K task segments, with a median duration of about 40 seconds.
- The activity labels cover seven gameplay categories: navigation, NPC dialogue, combat, minigames, system menus, Currency Wars, and other activities.
- Memory annotations: A second conversational turn reuses the clip images and cleaned task segments. GPT-5.6-Luna returns summaries, typically one per 16-second window, describing cumulative accomplishments and outcomes in the first person. A final window shorter than 8 seconds is merged into the preceding window. This yields approximately 223K memory annotations, each associated with the active task instruction and the latest image frame at or before the window end.
Three-level instruction hierarchy
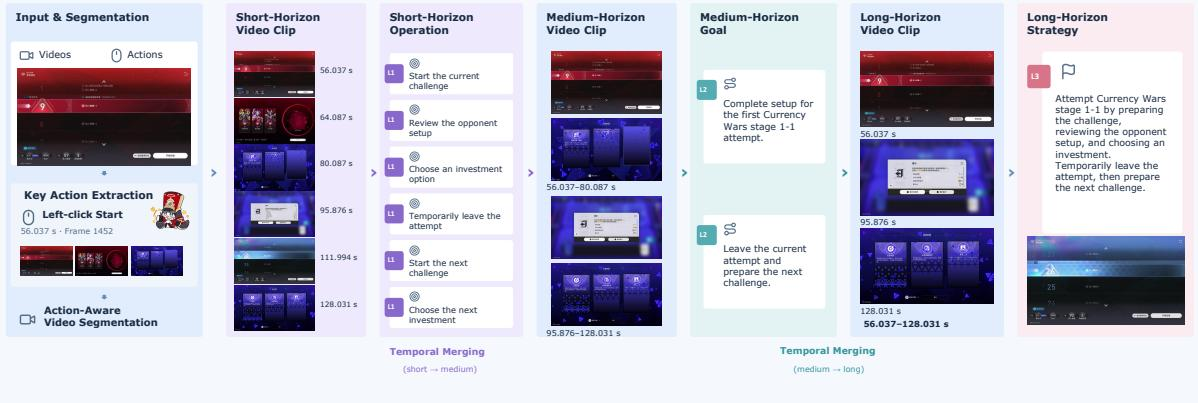
- Easy: local operations. These cover one or two annotated decisions, such as approaching an NPC, selecting a menu option, or collecting an item.
- Medium: intermediate subgoals. These combine related operations into a subgoal spanning three to five annotated decisions.
- Hard: extended task stages. These connect multiple subgoals into a task stage spanning six or more annotated decisions.
- The hierarchy is built bottom-up from task segments, Think annotations, and memory annotations. Human-annotated examples guide wording and scope. The same recorded interval can support instructions at multiple levels.
Training usage and sampling
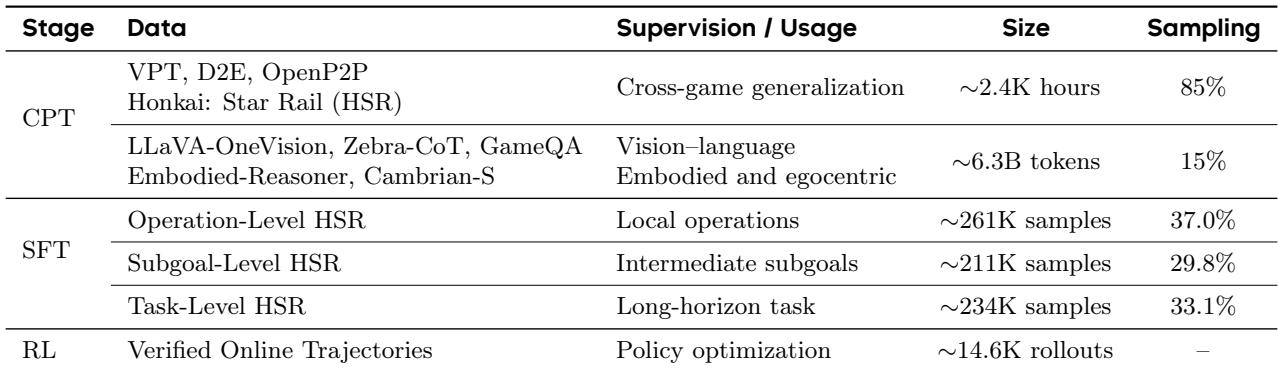
- The CPT stage uses a token ratio of 85% gameplay and 15% general vision-language data. Gamer CPT adds HSR gameplay trajectories to this mixture.
- The SFT stage uses the curated approximately 1K hours of HSR gameplay trajectories. Operation-level examples train local control and sparse reasoning, subgoal-level examples add intermediate objectives and longer memory, and task-level examples cover long-horizon tasks.
- Examples at different annotation levels may come from the same trajectory, and their derived samples and supervision tokens are counted separately.
- The RL stage also uses online policy experience, while cross-game interaction trajectories, general multimodal data, and multi-level task supervision are routed into CPT, SFT, and RL.
- Data splits are assigned at the recording or complete-task level before overlapping windows or multi-level examples are created, so derived samples from a source remain in the same split.
- Each supervision example is represented as xth=(B,Ih,Mth,Ht) and yt=[rt,at], where h is the instruction level. Every step includes action supervision, including steps without Think annotations.
Method
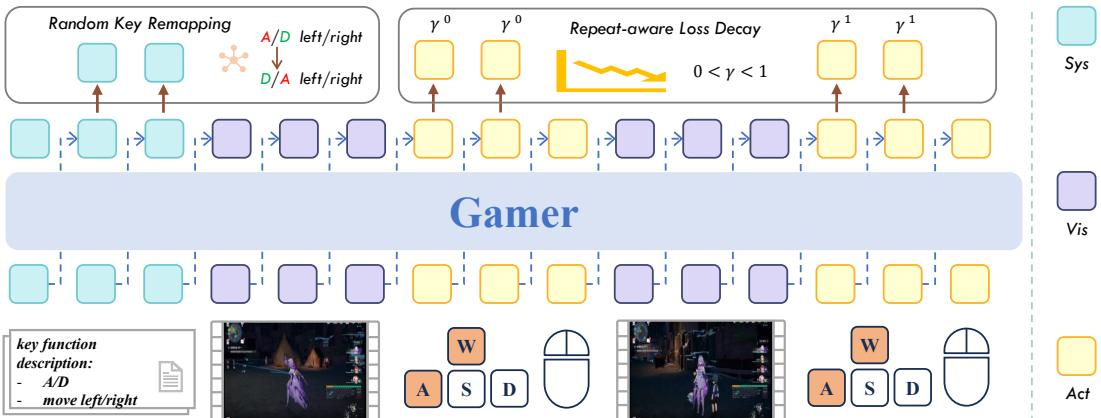
The authors adapt a pretrained multimodal model to a unified device-level interface using screen observations and native keyboard-mouse inputs. They represent gameplay trajectories as interleaved observations and actions, decoupling visual decision making from low-level action execution. Observations are sampled at 5 Hz, and each interval is divided into six keyboard-mouse action blocks, yielding a 30 Hz action rate. The action for interval t is defined as at=(ΔPt;Kt,1,…,Kt,6), where ΔPt is the accumulated mouse movement and Kt,j is the set of keys pressed in block j. To address biases from uneven key frequencies and repeated actions, the authors employ random key remapping and repeat-aware loss decay. Random key remapping samples a random bijection over rebindable keys to reduce reliance on key identity, while repeat-aware loss decay down-weights consecutive repeated actions using ωt=γnt−1 to emphasize behavior transitions.
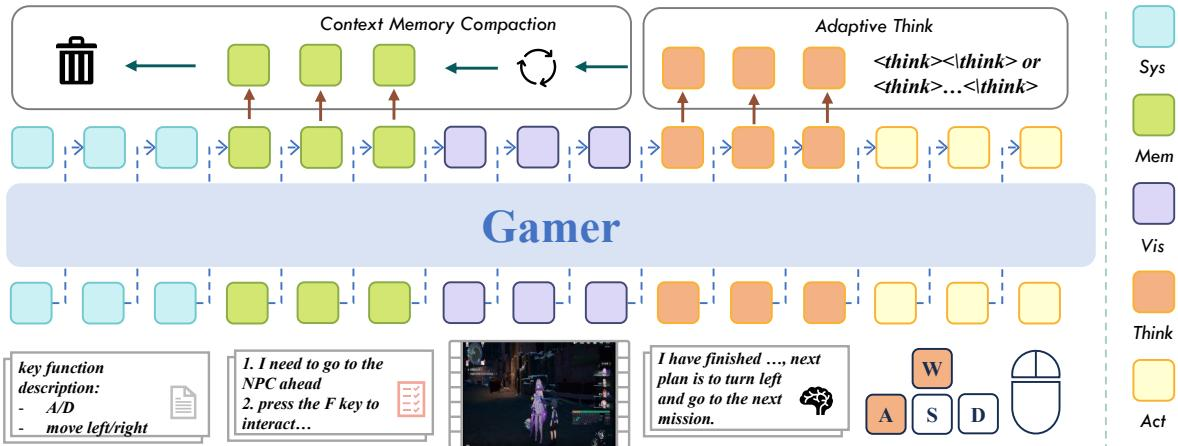
To teach the model to follow explicit task objectives, the authors use supervised fine-tuning with multi-level task conditioning. The policy is conditioned on a task instruction I and long-term memory Mt, alongside the control specification B and recent interaction history Ht. The instruction is instantiated at three difficulty levels: local operations, intermediate subgoals, and complete tasks. The model generates an optional reasoning sequence rt before producing the executable action at. Routine control steps bypass reasoning, while decision-critical steps generate explicit reasoning or memory summaries. Context memory compaction preserves task progress across long interactions by summarizing history before older interactions leave the active context.
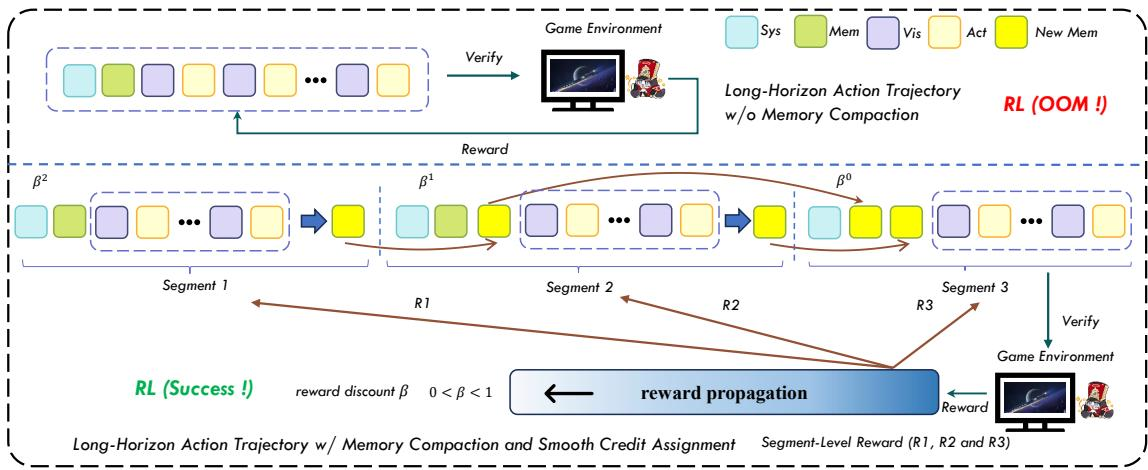
For long-horizon policy optimization, the authors introduce Temporal-Aware GRPO (TA-GRPO) to address the challenge of interactions exceeding the model's context window. TA-GRPO divides long rollouts into finite segments linked by the same memory compaction mechanism used during supervised fine-tuning. Segments from separate rollouts of the same task are scored using environment-verifiable outcomes. A temporal credit assignment mechanism distributes the segment-level advantage Ag,m across individual decisions, assigning larger weights to later steps that are temporally closer to the verified outcome using dg,m,t=Tg,m1∑u=0Tg,m−1βTg,m−1−uβTg,m−1−t.
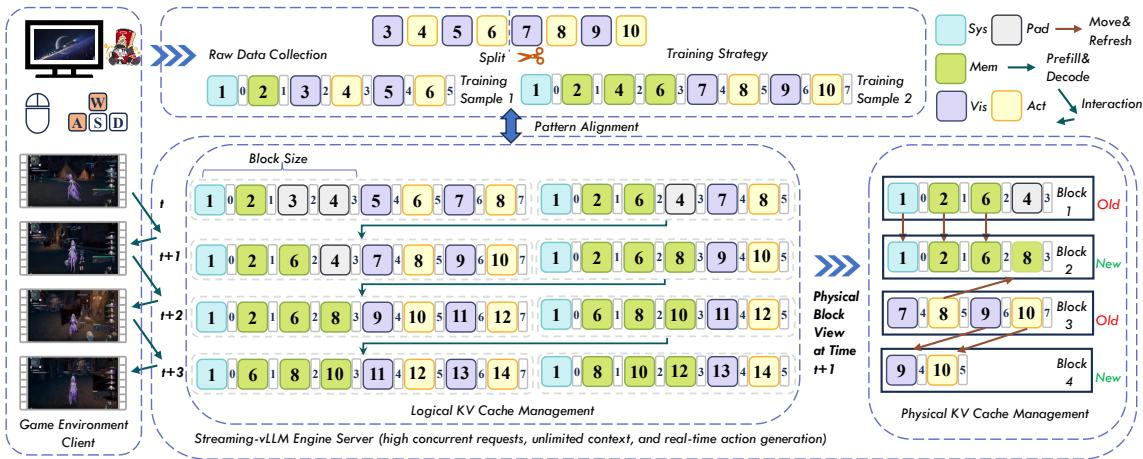
To handle the timing constraints of real-time gameplay, the authors develop Streaming-vLLM as a common execution backend. It preserves the KV states of retained context and computes new states only for newly appended tokens, following stateful streaming inference. A short-term queue holds recent complete interaction rounds, while a long-term queue stores generated memory summaries. At a compaction boundary, the policy summarizes history before eviction, and the rotary phase of the corresponding cached keys is updated using the positional shift without recomputing their projections.
The authors develop a scalable annotation pipeline to turn heterogeneous raw gameplay recordings into supervision for long-horizon task following. They filter invalid recordings and balance scenario coverage. Using a large language model, they generate sparse action reasoning, task segments with instructions, and task-state memories. These annotations are organized into a three-level instruction hierarchy: easy instructions cover local operations, medium instructions combine related operations into intermediate subgoals, and hard instructions connect multiple subgoals into extended task stages.
Experiment
The evaluations combine public game benchmarks, a controlled 120-configuration GameScaling study, and held-out Honkai: Star Rail side quests and minigames to validate cross-game control, long-horizon instruction following, and real-time online RL. GameScaling shows that continued pre-training first adapts models to the shared keyboard-mouse interface and that later gains depend on relevant game coverage, with distant unseen games plateauing or degrading after early adaptation. On Honkai: Star Rail, HSR-augmented CPT provides a control foundation, SFT substantially improves held-out task execution and minigame generalization, and online RL with game-native verification yields further gains. Real-time Streaming-vLLM preserves streaming visual understanding while reducing latency, and timely rollouts are essential for stable and effective online policy learning.
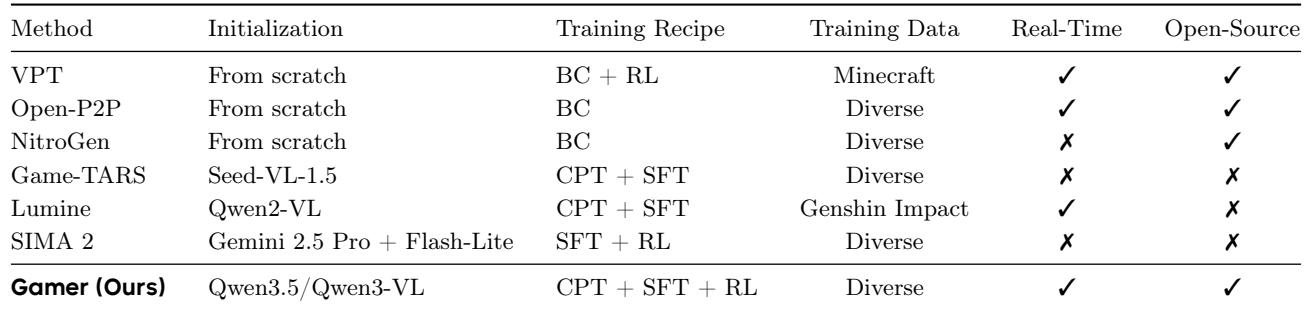
Gamer is initialized from Qwen3.5 or Qwen3-VL and trained with continued pre-training, supervised fine-tuning, and reinforcement learning on diverse data. Among the compared game agents, it is the only one that pairs real-time inference with open-source release while also using this multi-stage training recipe. Other open-source agents mainly rely on behavior cloning or behavior cloning plus reinforcement learning and are trained from scratch. Gamer is the only compared agent that combines real-time inference, open-source availability, and a CPT plus SFT plus RL training recipe. Among open-source agents, Gamer is the only one initialized from a pretrained vision-language model rather than trained from scratch. Agents using pretrained vision-language initialization often sacrifice open-source release or real-time inference, while Gamer retains both and uses diverse training data.
Gamer's training data combines cross-game gameplay, general multimodal sources, hierarchical task supervision, and online policy experience. The pretraining mixture is dominated by gameplay trajectories while retaining a smaller general vision-language component. Supervised fine-tuning distributes samples across operation, subgoal, and task levels without any single level dominating. The CPT stage mixes roughly 2.4K hours of cross-game gameplay with general multimodal sources at an 85:15 ratio. SFT supervision is split across operation-level, subgoal-level, and task-level examples, with operation-level samples forming the largest share at 37.0 percent. RL uses about 14.6K verified online trajectories for policy optimization.
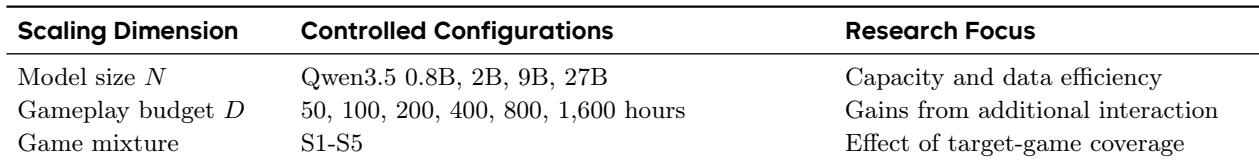
A controlled scaling study varies model size, gameplay budget, and game mixture across a large configuration grid. Gameplay trajectories account for most training tokens, with the remainder drawn from a fixed general multimodal pool. The game mixture shifts from Minecraft-only gameplay to no Minecraft, while remaining gameplay data come from a shared multi-game pool. Model size spans from under one billion to tens of billions of parameters, targeting capacity and data efficiency. Gameplay budget ranges from tens to over a thousand hours to study gains from additional interaction. Minecraft coverage decreases from all gameplay data to none, with the rest of the gameplay portion sampled from a multi-game pool.
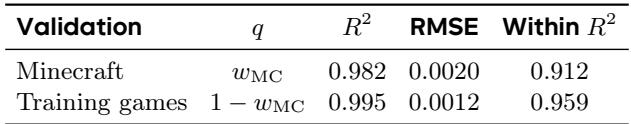
The composition-aware scaling relation fits validation loss closely for both Minecraft and the training-game distribution. Training-game validation shows the strongest overall fit and the lowest error, while Minecraft validation is slightly less accurate but still strong. Within-mixture explained variance is lower than overall fit, indicating that mean differences across mixtures contribute to the relation's explanatory power. Training-game validation achieves the highest fit accuracy and lowest RMSE among the reported conditions. Minecraft validation also shows high explained variance, though its within-mixture fit is weaker than the training-game within-mixture fit.
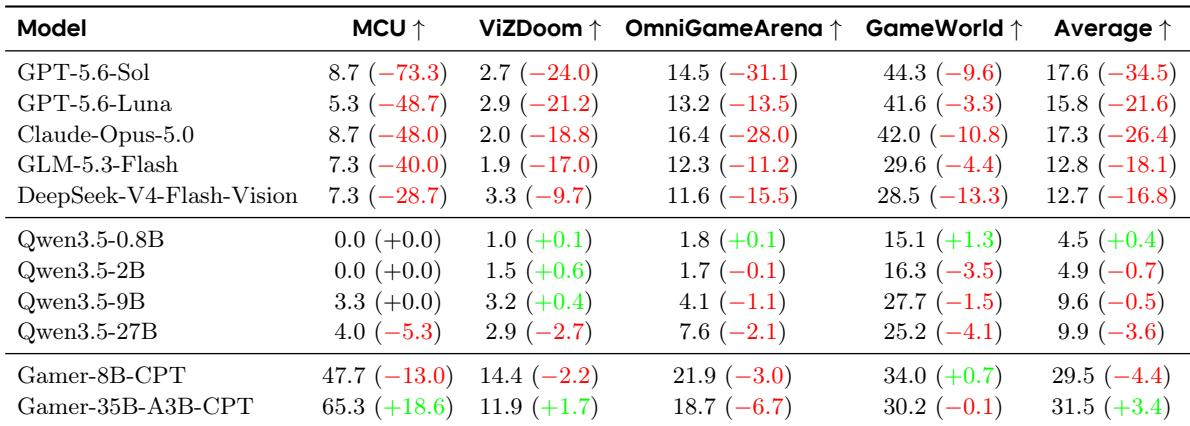
CPT-trained policies achieve higher average real-time scores than the listed general-purpose multimodal baselines across the four game benchmarks, for both Dense and MoE backbones. General-purpose models tend to show negative real-time versus time-paused differences, whereas the CPT policies are more robust and the MoE CPT policy even improves on average. The CPT checkpoints show complementary per-game strengths, with the MoE policy especially strong on MCU. CPT policies from both evaluated backbones exceed the strongest listed general-purpose baseline in average real-time score. Most general-purpose baselines lose performance under real-time interaction, while the Dense CPT policy shows only a modest decrease and the MoE CPT policy shows a positive average RT-TP difference. The clearest CPT advantage appears on MCU, and the two CPT backbones have complementary strengths across the four benchmarks.
Gamer is evaluated as an open-source agent initialized from a pretrained vision-language model and trained with continued pretraining, supervised fine-tuning, and reinforcement learning, unlike baselines that mostly rely on behavior cloning from scratch. Its data mixture combines large-scale cross-game gameplay with general multimodal sources, hierarchical supervision, and online policy experience, while a controlled scaling study varies model size, gameplay hours, and Minecraft coverage to examine scaling behavior. The composition-aware scaling relation tracks validation loss closely, especially on training-game data, and CPT-trained policies outperform general multimodal baselines in average real-time scores, with the MoE checkpoint showing complementary strengths and notable gains on MCU.