Command Palette
Search for a command to run...
미래를 내다보며: 자기회귀적 비디오 생성에서 미래 진화 모델링
미래를 내다보며: 자기회귀적 비디오 생성에서 미래 진화 모델링
Ruopeng Gao Yukun Huang Jiarui Hu Shuai Wang Wenbo Hu Ying Shan Limin Wang
초록
자기회귀적 비디오 확산 모델은 비디오를 청크 단위로 생성하지만, 그럴듯한 연속 장면을 만들어내는 것이 장면이 어떻게 진화하는지를 포착한다는 것을 보장하지는 않는다. 교사 강요 하에서는 강한 시간적 중복성 때문에 국소적인 시각적 연속성이 현재 청크의 디노이징을 위한 지름길로 작용할 수 있으며, 이는 시각적 진화를 모델링해야 할 압력을 낮춘다. 우리는 시간적으로 분리된 청크를 중간의 시각적 맥락에 접근하지 않고 예측하는 보조 목적함수인 Future Chunk Prediction(FCP)을 도입하며, 이를 교사 강요 기반 디노이징과 공동으로 최적화한다. FCP는 학습 비디오에서 직접 지도 신호를 얻으므로 추가적인 사전학습된 시각 인코더가 필요 없고, 자기회귀적 추론 과정도 그대로 유지된다. 제안 방법은 표준적인 교사 강요 자기회귀 학습보다 더 적은 전체 학습 계산 예산으로 우수한 물리적 개연성을 달성하며, 이는 시각적 진화 모델링을 위한 미래 청크 지도의 효과성과 효율성을 보여준다. 흥미롭게도 우리의 시각화 결과는 FCP가 더 구조화된 표현 공간을 조성함을 시사하며, 이는 자기회귀적 세계 모델을 구축하는 데 유용할 수 있다.
One-sentence Summary
Nanjing University et al. propose Future Chunk Prediction (FCP), an auxiliary objective jointly optimized with teacher-forced denoising for autoregressive video diffusion, which predicts temporally separated chunks without intervening visual context and improves physical plausibility at a lower training compute budget while leaving autoregressive inference unchanged and yielding more structured representations.
Key Contributions
- Future Chunk Prediction (FCP) is introduced as an auxiliary objective for autoregressive video diffusion that predicts temporally separated chunks without access to intervening visual context, jointly optimized with standard teacher-forced denoising.
- FCP draws supervision directly from training videos, requires no additional pretrained visual encoder, and leaves autoregressive inference unchanged by removing auxiliary predictors at inference.
- Controlled comparisons show improved physical plausibility over standard teacher-forced autoregressive training across model scales and conditioning settings with a lower overall training compute budget, and visualizations suggest FCP fosters a more structured representation space.
Introduction
Autoregressive video generation extends visual sequences through chunk-wise temporal rollout, conditioning each new chunk on preceding context, and is a promising route toward generative world modeling. However, standard teacher-forced training often creates a shortcut: because neighboring video chunks share strong appearance and motion similarity, models can rely on local visual continuity instead of learning how scenes actually evolve. Prior work addresses rollout quality mainly through causal few-step generators, self-generated histories, context management, or alignment with external pretrained encoders, which can introduce complexity or scaling limitations. The authors introduce Future Chunk Prediction (FCP), a training-only auxiliary objective that predicts a temporally separated future chunk from intermediate representations without exposing the model to intervening ground-truth context or requiring external pretrained features, and show it improves physical plausibility while inducing more structured spatiotemporal representations.
Dataset
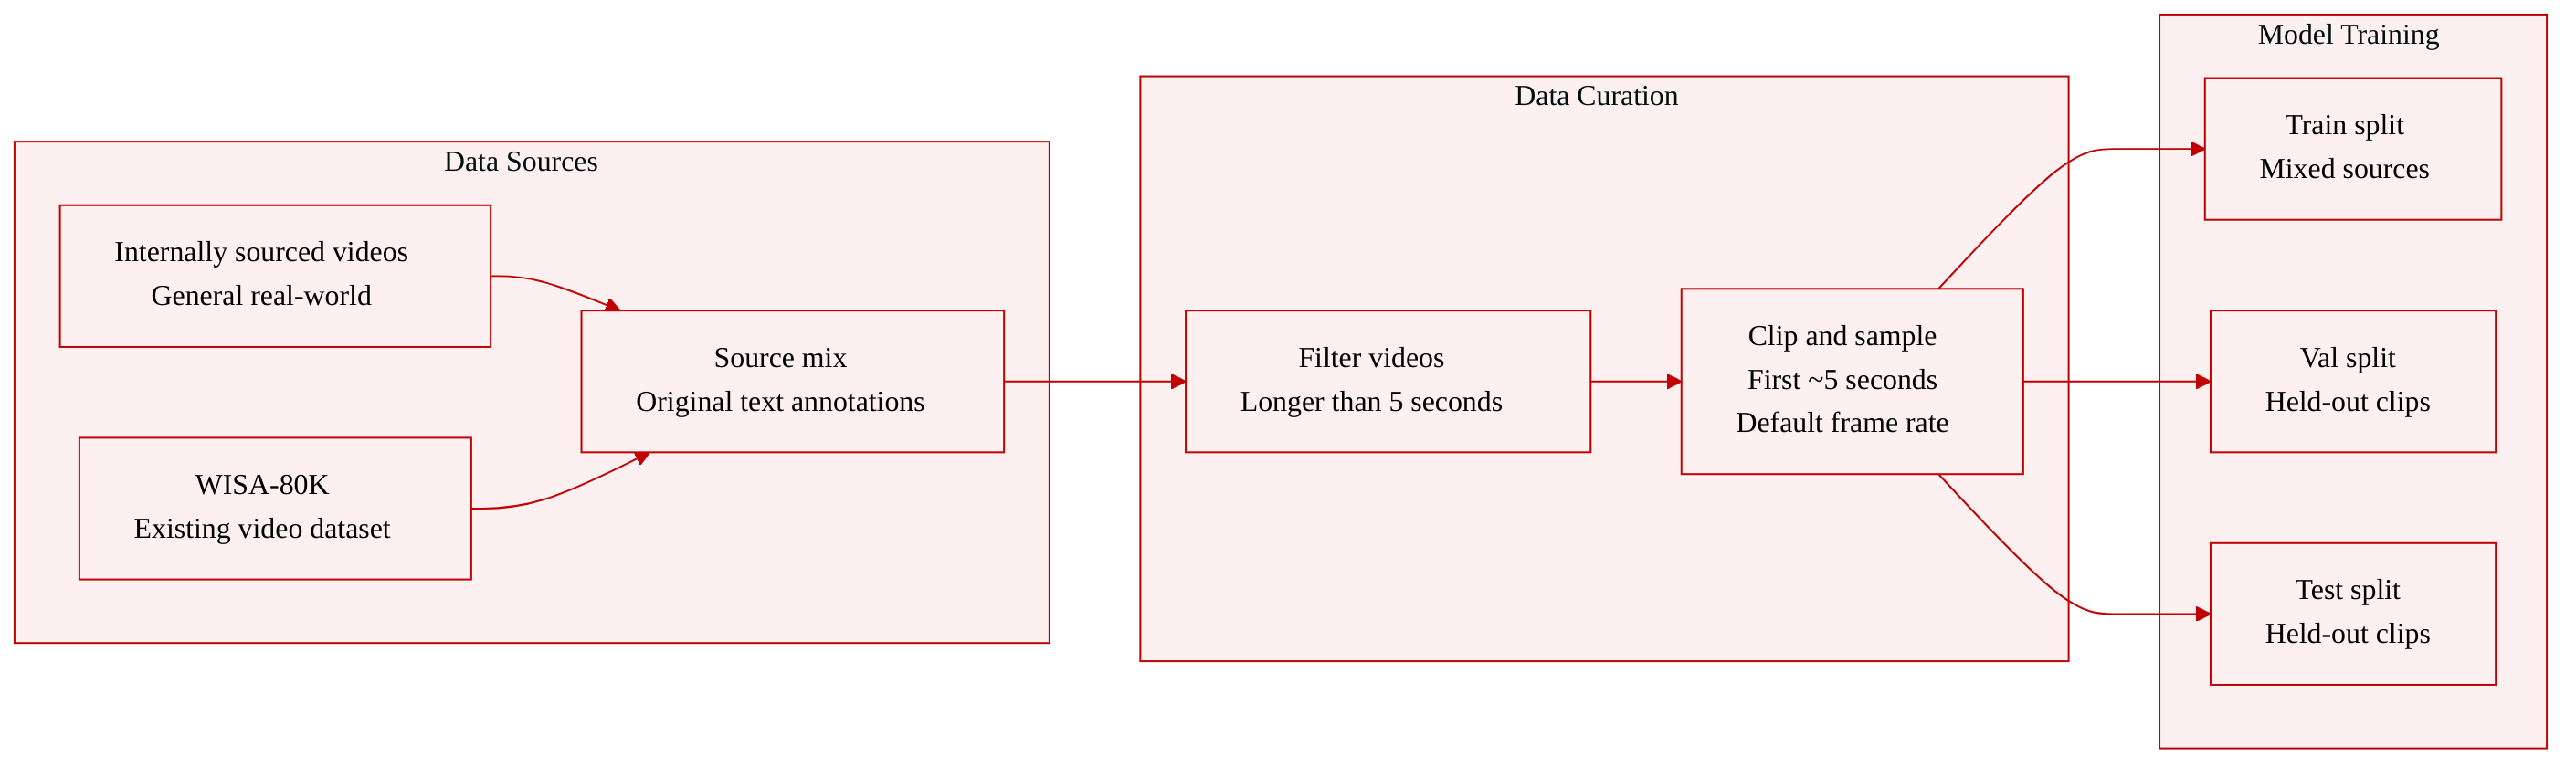
The authors use a training mixture from two sources:
- Internally sourced videos: general-purpose real-world videos, with no physics simulator data. The paper does not state the exact number of videos or total duration for this subset in this section.
- WISA-80K: an existing video dataset used with its original text annotations. The name suggests 80K examples, but the excerpt does not restate its exact size or collection details.
Filtering and processing:
- Only videos longer than five seconds are selected.
- Approximately the first five seconds of each selected video are used, so the temporal cropping is fixed to the opening segment.
- Videos are sampled at the default frame rate of the corresponding model.
- Original text annotations from each source are retained rather than rewritten or re-labeled.
Usage in training:
- The two sources are mixed together for training.
- The exact mixture ratio between internally sourced videos and WISA-80K is not specified in this section.
- Training does not include physics simulator videos, although the authors note that simulator data may improve physical plausibility in future work.
Method
The authors leverage a teacher-forced training paradigm for autoregressive video generation, where the historical context is taken directly from the ground-truth video. Under a flow-matching formulation, Gaussian noise and a flow time are sampled to perturb the target chunk along a linear probability path. The model predicts the corresponding velocity conditioned on the clean preceding chunks and text condition, optimizing the following objective:
LTF(θ)=Ex1:K,c,k,t,ϵk[∥vθ(xk,t,t,x<k,c)−(ϵk−xk)∥22]However, the strong temporal redundancy of video allows the immediately preceding correct context to provide substantial support for current-chunk denoising. This reduces the pressure to capture temporal progression and potentially hinders the learning of representations that capture visual evolution. To address this, the authors introduce Future Chunk Prediction (FCP), which supplements next-chunk denoising with an auxiliary task of predicting temporally more distant chunks from the same video. By excluding the intervening chunks from the visual context, this task discourages reliance on local temporal continuity.
Formally, FCP requires the available context to support the prediction of a farther target:
pFCP(xk+Δ∣hk),Δ≥1where Δ is an integer temporal offset measured in chunks. Rather than conditioning on the full history or explicit text, the auxiliary prediction conditions on the generator's intermediate hidden states hk corresponding to chunk k. This encourages a more compact encoding of predictive information.
The overall architecture of the Future Chunk Prediction framework is illustrated below.
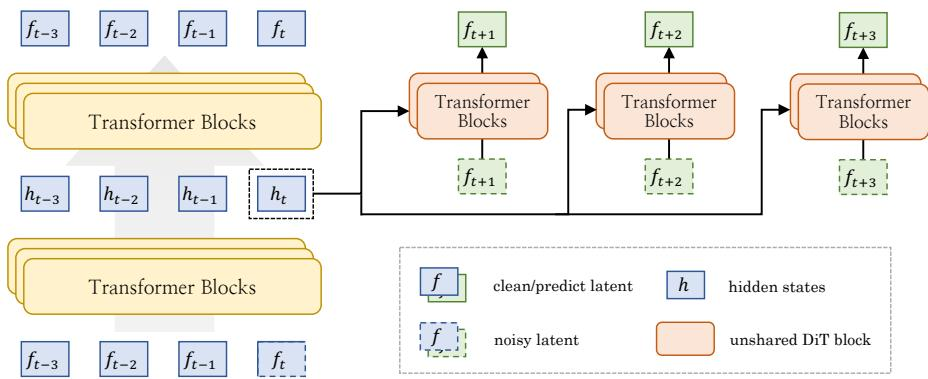
For the autoregressive generator, the authors employ a standard video diffusion model whose backbone consists of stacked diffusion transformer (DiT) blocks with chunk-causal attention. The auxiliary predictor adopts a lightweight counterpart of this DiT architecture with a separate set of parameters. The design incorporates several key components. First, regarding source representations, the system extracts intermediate features associated with chunk k in both clean and noise-perturbed states. Clean context provides historical information for subsequent chunk generation, while the noisy target is progressively denoised to produce the current chunk. Both types of representations are regularized through future-prediction supervision.
Second, the framework utilizes a parallel future prediction design. Each future offset has a separate predictor conditioned directly on the hidden states of the current chunk, rather than on hidden states from preceding predictors. This parallel structure removes inter-offset information flow, preventing shortcuts that could weaken the pressure on the source representation to encode future evolution.
Third, for feature conditioning, the model extracts features from multiple generator layers, concatenates them along the channel dimension at corresponding token positions, and fuses them with a multilayer perceptron. These fused features are injected into every auxiliary DiT block through token-wise Adaptive Layer Normalization modulation, preserving fine-grained conditioning across spatiotemporal positions. Finally, the architecture employs asymmetric text conditioning. Unlike the text-conditioned main generator, the auxiliary predictors omit text cross-attention from every DiT block. This asymmetry blocks a direct pathway through which text prompts could leak cues about future events, encouraging the predictors to rely strictly on the generator's source representations while also reducing computational cost.
During training, the authors jointly optimize the autoregressive generator and auxiliary predictors using flow matching. For each offset in a predefined set, a separate auxiliary predictor follows the flow-matching objective, conditioned on either clean or noisy source representations. Target noise and flow time are resampled for each auxiliary prediction. The resulting joint objective takes the form:
Ltotal=LTF+Δ∈D∑wΔ2LΔclean+LΔnoisywhere wΔ controls the contribution of each offset. The auxiliary losses backpropagate through the source representations into the generator. At inference, all FCP-specific modules are discarded, retaining the same autoregressive generator and rollout procedure as the teacher-forcing baseline without additional overhead.
Experiment
The experiments evaluate future-conditioned prediction for autoregressive video generators initialized from Wan checkpoints, using image-to-video training and physics plausibility benchmarks, primarily Physics-IQ Verified. FCP consistently improves physical plausibility over teacher forcing across model scales and conditioning settings, with qualitative gains in temporal dynamics such as domino toppling and rising water. Ablations attribute these benefits to regularizing clean-context and noisy-target representations, using parallel rather than chained future prediction, and withholding text from auxiliary predictors, while maintaining training efficiency comparable to teacher forcing. Representation analysis further shows that FCP yields more selective, temporally aligned features.
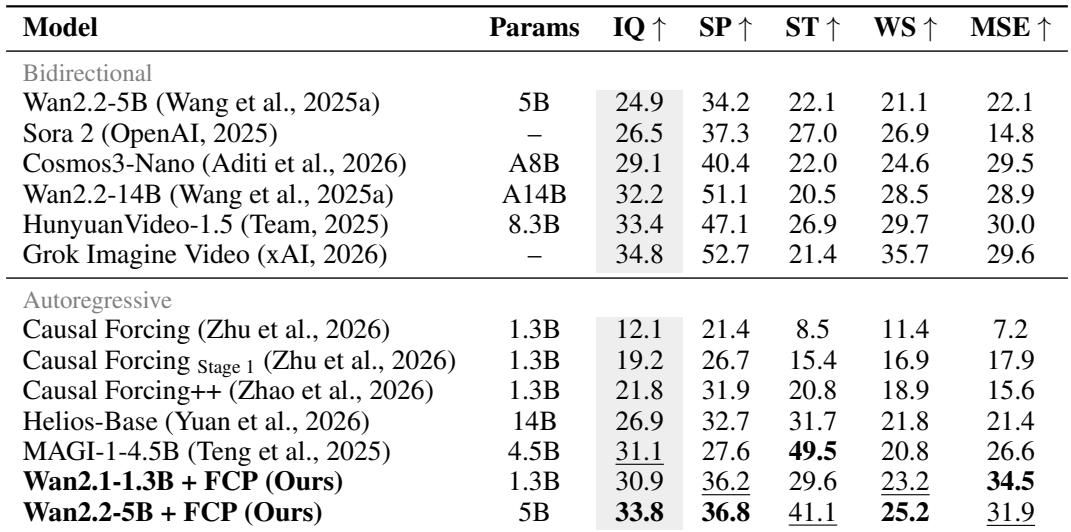
The Physics-IQ Verified comparison shows that the 5B model achieves stronger overall physical plausibility than several larger bidirectional video generators, including Wan2.2-14B, HunyuanVideo-1.5, and Cosmos3-Nano. Future-conditioned prediction consistently improves over teacher forcing across 1.3B and 5B scales, with gains in both image-to-video and video-to-video settings. Cross-model differences are interpreted cautiously because training data and experimental configurations differ. The 5B model outperforms larger bidirectional models such as Wan2.2-14B, HunyuanVideo-1.5, and Cosmos3-Nano on the overall Physics-IQ score. Future-conditioned prediction improves IQ over teacher forcing for both 1.3B and 5B models. Qualitative examples show future-conditioned prediction preserves physical dynamics like domino falling direction and water-level rise that teacher forcing misses.
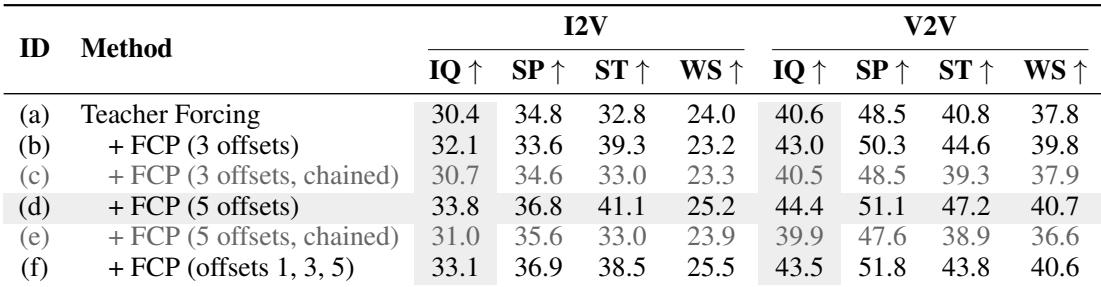
Controlled comparisons on Wan2.2-TI2V-5B show that adding future-conditioned prediction improves Physics-IQ over teacher forcing in both image-to-video and video-to-video settings, with the parallel five-offset configuration producing the largest gains. Chained future prediction gives only marginal image-to-video improvement and does not improve video-to-video performance, while nonconsecutive offsets also improve over teacher forcing. Overall, parallel future prediction appears to be the more effective formulation for physical plausibility. The five-offset FCP configuration achieves the highest I2V and V2V IQ scores among the compared variants, improving from 30.4 to 33.8 and from 40.6 to 44.4 over teacher forcing. Chained FCP variants show only marginal I2V gains over teacher forcing and slightly lower V2V IQ, failing to improve video-to-video performance.
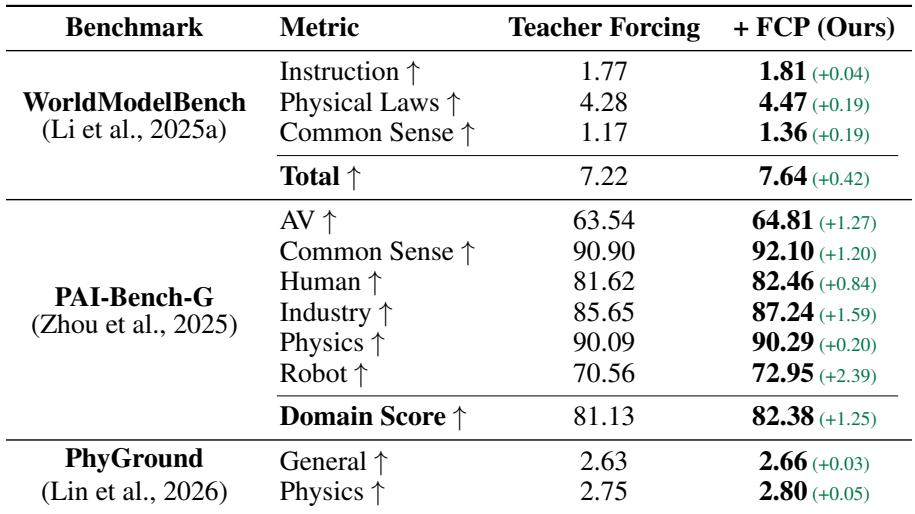
Across matched training settings, adding future-conditioning prediction to a Wan2.2-TI2V-5B teacher-forcing baseline yields consistent improvements on WorldModelBench and PAI-Bench-G. Gains are especially clear in physical laws and common sense, while instruction following improves more modestly. Controlled PhyGround comparisons similarly favor FCP for IQ, image-to-video, and video-to-video metrics. On WorldModelBench, FCP improves physical laws and common sense more clearly than instruction following relative to teacher forcing. On PAI-Bench-G, FCP raises the AV, common sense, and human metrics over the teacher-forcing baseline. In PhyGround-based comparisons, FCP improves IQ scores across model scales and boosts both image-to-video and video-to-video conditioning performance. The reported improvements arise under matched training settings, supporting future-prediction supervision as the key factor rather than differences in data or compute.
The ablation shows that combining clean-context and noisy-target components yields the largest improvement in physical plausibility over teacher forcing, while the default parallel future-prediction setup achieves the highest overall IQ and SP scores. Adding text conditioning to auxiliary predictors or using chained prediction reduces the IQ score relative to the default configuration. The results support visual-only, parallel future prediction as the most effective evaluated design. Combining clean-context and noisy-target components improves IQ over teacher forcing more than either component alone. Adding explicit text conditioning to auxiliary predictors lowers IQ relative to the default setup. Parallel future prediction yields a higher IQ score than the chained alternative. The default configuration records the highest SP score among the compared variants.
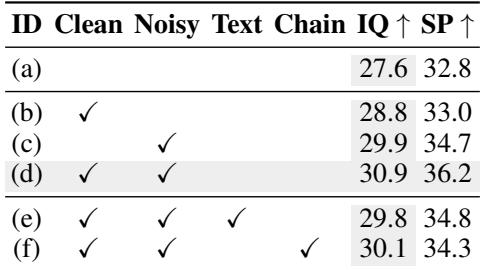
The experiments evaluate future-conditioned prediction against teacher forcing across image-to-video and video-to-video settings, using Physics-IQ and other physical plausibility benchmarks. A 5B model outperforms several larger bidirectional video generators on Physics-IQ, and future-conditioned prediction consistently improves physical plausibility over teacher forcing at both 1.3B and 5B scales. Controlled and matched training comparisons show gains on Physics-IQ, WorldModelBench, PAI-Bench-G, and PhyGround metrics, especially in physical laws and common sense. Ablations indicate that parallel visual-only future prediction with clean-context and noisy-target components is the most effective configuration, while chained prediction and added text conditioning reduce performance.